Agentic HR data platform: a guide for HRIS and people analytics engineering
Going fully agentic and autonomous does not mean putting a chatbot on Workday. For HR data platform teams, it means climbing from agents that assist, to agents that run the routine work under your controls, to a people data back office that largely runs itself: org hierarchies rebuilt the day a reorg lands, headcount tied to finance every morning, sensitive columns found and tagged before they spread, and evidence ready when a subject access request arrives. Compensation, protected attributes, every individual-level release and every access grant stay with a named owner. This is what that climb looks like, step by step.
Key takeaways
- •Who this is for. The team that lands Workday, SuccessFactors, Greenhouse or Lever, ADP and payroll, engagement survey and learning system data into the warehouse, and serves people analytics, finance and leadership from it.
- •The problem today. The most sensitive data in the company (pay, performance, health leave, protected characteristics) sits behind a stream of access requests from every HR business partner, org-hierarchy logic breaks at every reorg, Workday report changes break feeds, and HR and finance quote different headcount.
- •What changes. Hierarchy changes are versioned the day they take effect, headcount is tied to finance every morning, new feeds are scanned for sensitive columns before anyone queries them, and access requests are checked against policy and routed with the evidence attached.
- •What stays with your people. Compensation, protected attributes, any individual-level release and any access grant: a named owner approves each one. Agents find, test, evidence and propose.
- •The result. An HR data platform team that ships people data products instead of rebuilding hierarchies, working an access queue and explaining why two headcount numbers differ.
The PRD for agentic HR data platform teams
This is the requirements document we would write with you for your team. Everything below expands on it.
| Who | HRIS and HR data platform, people analytics engineering, HR data engineering, people data product and HR systems teams |
| The job | A reorg that lands in the warehouse on its effective date, with headcount that ties to finance. |
| Environment | Workday or SuccessFactors; an applicant tracking system such as Greenhouse or Lever; ADP and payroll; engagement survey and learning system exports; Snowflake or Databricks; dbt; Airflow; Tableau or Looker; your identity provider. |
| Constraints | Compensation, performance, health leave and protected attributes are restricted. Any individual-level release and any access grant goes to a named owner. Employee personal data in the EU is subject to subject access and retention rules. |
| Success is measured by | HRBP access request: from about a week to 5 min; headcount tie-out to finance: from about 3 days to 15-20 min; reorg hierarchy rebuilt: from about a week to about an hour; catalog and docs upkeep closed autonomously 88% of the time. |
| Owned by | The Head of People Data or HRIS Director, with data owners in HR, Total Rewards and Legal as named approvers. |
| Pilot scope | Org hierarchy and headcount for one reorg cycle, at L1 then L2. |
What going fully agentic and autonomous means for HR data platform teams
- •Put your data pipeline on autopilot. Workday report changes, new fields and reorg effective dates are detected at the boundary and the feeds are remapped before the next refresh, so a Friday release does not become a Monday outage.
- •Run the data back office without the busywork. The work that fills the week today moves to agents: hierarchy rebuilds, headcount tie-outs, sensitive-column reviews of new feeds and the evidence behind every access request.
- •Scale data without scaling headcount. A new acquisition, a new country payroll or a new survey vendor is onboarded in hours, so the number of sources and requesters grows without the team having to.
- •Get the plumbing off your plate. An HR data platform team that ships people data products instead of rebuilding hierarchies and answering "which headcount is right".
Who this is for
The team that owns people data as a platform. In most companies it sits inside HR technology or a central data organization, with a dotted line to people analytics and finance. It runs the Workday or SuccessFactors extracts, the applicant tracking and payroll feeds, the survey and learning data, and the warehouse models that people analysts, HR business partners (HRBPs), finance and leadership all read from. The labor-market and workforce-supply data business is a different job and has its own page for people and labor-market data teams; the forward-looking plan and capacity side is covered in workforce planning data.
The titles: Head of People Data, HRIS Director, Director of HR Technology, People Analytics Engineering Manager, Senior HR Data Engineer, HR Data Product Manager, and the HRIS analysts and analytics engineers who report to them. These leaders answer to the CHRO for the numbers, to the CFO for headcount and cost, and to Legal and the privacy office for how employee data is handled.
The product you ship
- •The core employee model: workers, positions, jobs, locations and the supervisory organization hierarchy, effective-dated so any past date can be reproduced.
- •Headcount and movement: headcount, FTE, hires, terminations, transfers and promotions, defined once and tied to finance.
- •Talent acquisition data: requisitions, candidates, stages and offers from the applicant tracking system, joined to hires.
- •Compensation and payroll data: pay, bands, bonus, equity and payroll runs, held in restricted zones.
- •Engagement and learning data: survey responses, completion and skills records, with small-group suppression rules.
- •Governed access: the role-based rules and row-level scopes that decide who sees which population, and the audit evidence behind them.
- •Products for the business: the people analytics layer, the board and finance headcount feed, and the assistants HR staff increasingly ask questions of.
Where the week goes
- •Every HRBP needs a slice. Access requests arrive one by one, each needing a look at what is in the data, who owns it and what the policy allows.
- •A reorg breaks the hierarchy. Supervisory organizations are merged, split and re-parented, and every model that rolls up by manager or cost center changes on the effective date.
- •Workday report changes break feeds. A calculated field is renamed or a report-as-a-service output changes, and the downstream marts fail or quietly drop rows.
- •Headcount differs. HR counts workers by effective date, finance counts by cost center and period close, and the two numbers disagree in the board deck.
- •Sensitive data spreads. A new payroll or survey feed arrives and its sensitive columns are found only when someone asks.
- •Privacy work is manual. A subject access request means finding every table that holds one person, and retention rules mean knowing what is past its schedule.
- •Definitions are contested. HR, finance and the business each hold a version of headcount, attrition and span of control.
Add it up and upkeep is most of the team's week. Here is how a typical week splits today, and once agents own the back office:
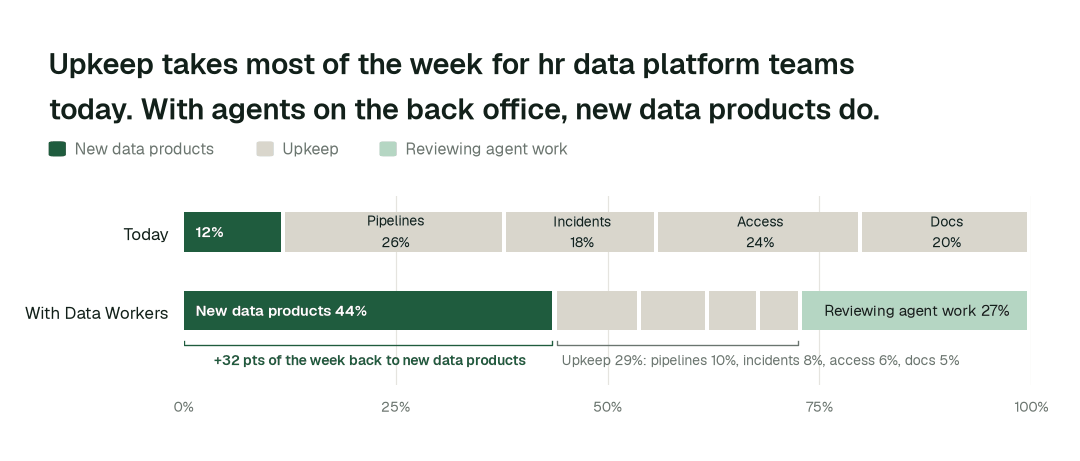
Time spent on new data products moves from 12% of the week to 44%. Most of the rest becomes review: people steer and approve agent work instead of doing it by hand.
Then and now
| Work | Today | With Data Workers |
|---|---|---|
| Reorg hierarchy change | Rebuilt by hand, history overwritten | Versioned on the effective date, prior periods restated |
| Headcount, HR vs finance | Argued in the board deck | Tied every morning to one governed definition |
| Workday report change | Feed breaks, found by a dashboard | Detected at the boundary, remapped with a rollback point |
| HRBP access request | A ticket and a week | Checked against policy, routed to the owner with evidence |
| New payroll or survey feed | Sensitive columns found later | Scanned and tagged before first use, masking proposed |
| Subject access request | Tables hunted by hand | Where one person's data sits, mapped on request |
These are the impact metrics we move for HR data platform teams:
- •HRBP access request: from about a week to 5 min
- •Headcount tie-out to finance: from about 3 days to 15-20 min
- •Reorg hierarchy rebuilt: from about a week to about an hour
Across the routine work in this domain:
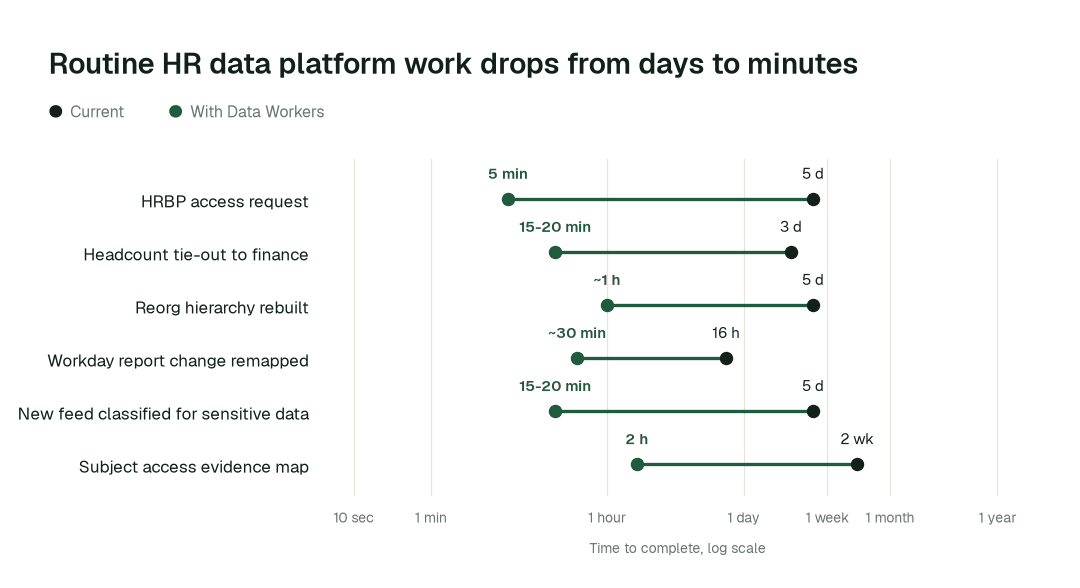
The biggest change is the HRBP access request: from about a week to 5 min. Work that waited in queues finishes in minutes or hours, because agents check, trace and prepare the decision in one pass.
Use cases, in depth
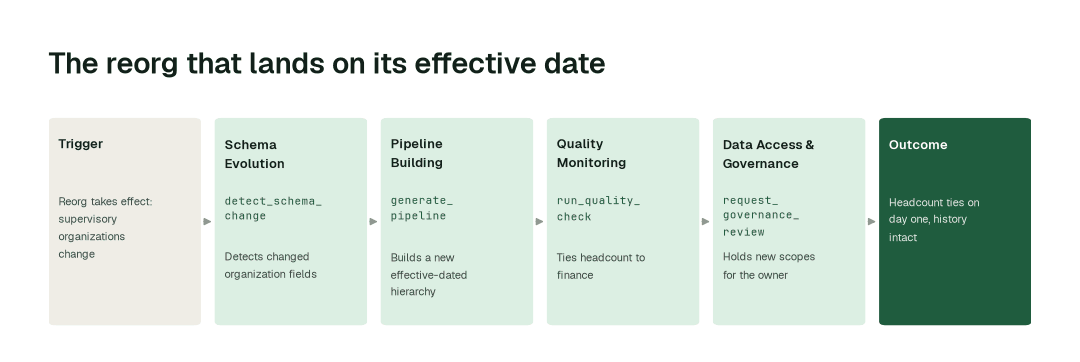
The reorg that lands on its effective date
Today. Supervisory organizations are re-parented, cost centers move and every roll-up by manager changes. The hierarchy logic is patched in a hurry, last quarter's headcount is overwritten, and the first Monday dashboard is wrong.
With Data Workers. The Schema Evolution agent detects the changed organization fields, the Pipeline Building agent builds a new effective-dated version of the hierarchy next to the old one, and Quality Monitoring ties headcount to finance on both. Scoped access for the new managers is held for the HR data owner.
What changes. The reorg arrives with its history intact and headcount that ties on day one. See headcount and attrition data.
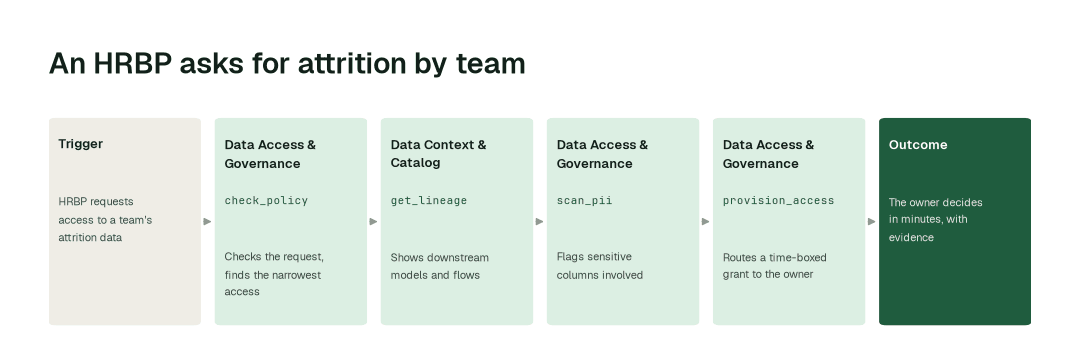
An HRBP asks for attrition by team
Today. The request lands in a queue. Someone checks what the table holds, who owns it, whether the HRBP's population is in scope and whether the small groups are safe to show. A week later the access exists, or does not.
With Data Workers. The Data Access & Governance agent checks the request against policy, finds the narrowest access that answers it, and the Data Context & Catalog agent shows which sensitive columns and downstream models are involved. The request goes to the named data owner with that evidence attached, and the grant is time-boxed with an approval record.
What changes. The owner decides in minutes, with the facts in front of them, and nobody works a ticket queue. See zero-ticket data access.
A subject access request and retention in the EU
Today. An employee in Germany or France asks for the personal data held about them. The team hunts through the core model, payroll, the applicant tracking system, survey exports and analyst copies, and nobody can say with confidence that the list is complete. Retention schedules exist on paper; what is actually past them is unknown.
With Data Workers. The Data Context & Catalog agent maps where a person's identifiers flow, from source to marts to analyst copies, and the Data Access & Governance agent assembles the evidence for the privacy team. Quality Monitoring runs the retention checks you define and lists what is past its schedule.
What changes. The privacy office gets a complete, reviewable map instead of a search. Release of the response and any deletion stay with the named owner and Legal. See how Data Workers supports GDPR subject access work.
Use-case guides for HR data platform teams
Each guide has the workflow, the agents and tools involved, the impact metrics and a pilot scope.
- •Headcount and attrition data: headcount defined once, tied to finance and rebuilt for every reorg, with attrition computed on the same population.
- •Recruiting funnel data: applicant tracking stages, sources and offers joined to hires, with candidate personal data scoped.
- •Compensation and pay equity data: pay data held in restricted zones, with pay gap analysis prepared for Total Rewards and Legal to release.
- •Workforce plan inputs: positions, budgets and headcount actuals kept fresh and reconciled for the planning team.
- •Workforce staffing: skills, availability and demand joined so staffing decisions start from current data.
Agents working together: The Monday after a reorg
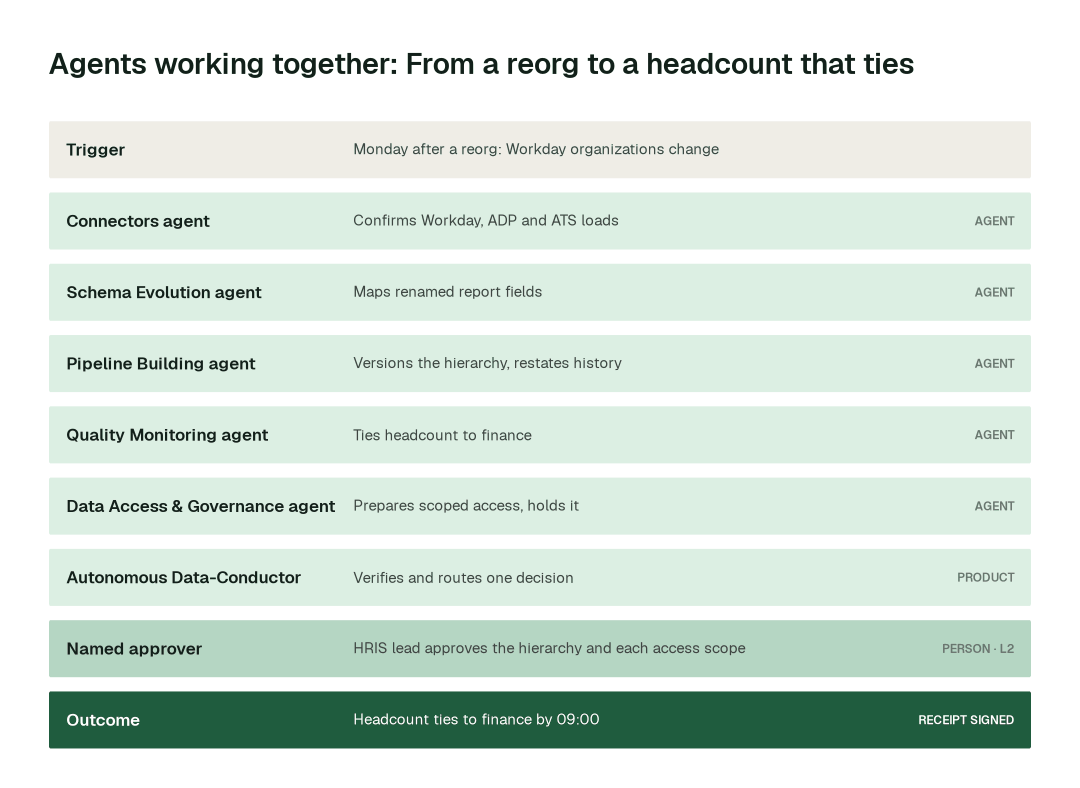
Every HRIS lead knows the Monday after a reorg. Workday shows the new supervisory organizations, managers log in to dashboards built on the old ones, finance asks why headcount moved, and three HRBPs ask for access to their new populations. This is the same morning run by Data Workers.
The setup
The people data platform runs on Snowflake and dbt under Airflow, fed by Workday, an applicant tracking system, ADP and an engagement survey export. It feeds the headcount dashboards, the finance headcount feed, the people analytics layer and an assistant HR staff use to ask questions. Autonomy in Autopilot:
- •Landing, tie-out checks and documentation upkeep: L2 today; a candidate for L3 on evidence.
- •Hierarchy changes and report remapping: L2, reviewed by the HRIS lead.
- •Access grants, compensation and protected attributes, and any individual-level release: L2 at most, held for the named data owner. No agent grants access or releases a person's record.
The team scheduled one mission the week before: "Roll the people marts to the new organization structure with prior periods restated."
06:00: the reorg takes effect
The overnight Workday extracts land. 14 supervisory organizations have been merged, split or re-parented, and two Workday report outputs have a renamed field. Finance publishes its cost center mapping for the new structure.
06:04: confirm what landed
Connectors agent checks each source and confirms the Workday, ADP and applicant tracking loads are complete and on time. A late payroll file for one country is flagged before anything downstream reads it.
Schema Evolution agent sees the renamed report fields, maps them into the model and validates compatibility with the existing marts.
06:15: version the hierarchy
Pipeline Building agent creates a new effective-dated version of the organization hierarchy instead of overwriting the old one. It maps merged units one to one and splits the divided units by cost center, so last quarter's headcount can be restated on the new structure. It writes tests proving the old structure's totals are unchanged.
06:40: prove it ties
Quality Monitoring agent runs the checks the team relies on:
- •Headcount by cost center ties to finance's mapping, on both the old and the new structure.
- •Every worker sits in exactly one supervisory organization on each date.
- •Manager roll-ups sum to the total, with no orphaned reports.
Two things do not tie: 31 workers whose cost center is missing from finance's mapping, and a contractor group counted by HR but not by finance.
06:52: trace what does not tie
Incident Debugging agent traces the 31 workers to a legal entity that finance mapped under another code, and the contractor difference to a definition: HR counts contingent workers on the effective date, finance excludes them. It writes both up with the records involved.
07:10: re-scope access, hold the sensitive part
Data Access & Governance agent works out the row-level scopes the new managers and three HRBPs need, checks them against policy and prepares the requests with the evidence. Compensation and performance fields stay limited to the roles allowed to see them. The grants are held for the HR data owner; nothing is applied yet.
07:25: update meaning, then verify
Data Context Wizard updates the governed definitions of headcount, FTE, span of control and the contingent-worker rule, with provenance, so the dashboards, the finance feed and the HR assistant answer from the same definition. Autonomous Data-Conductor checks the outcomes and, because hierarchy and access sit at L2, sends one decision to the HRIS lead: the full diff, the tie-out results, the two open items and the proposed scopes.
08:05: approved
The HRIS lead approves the hierarchy, agrees the contingent-worker definition with finance, and approves two of the three access requests. The third goes back to the HRBP's director for a narrower scope. Conductor publishes the approved changes.
09:00: managers log in
Dashboards show the new structure. Year-over-year comparisons work because last quarter was restated. Finance's headcount feed and the HR dashboard show the same number. Nobody opens a ticket.
What stays behind
- •Versioned hierarchies with tests, so comparisons never break at the next reorg.
- •A receipt for every change: who proposed it, who approved it and how to roll it back.
- •Updated Spellbook Data Catalog pages for every affected people data product.
- •A reusable mission. The next reorg runs the same way, and the team can move the routine parts to L3.
Minute by minute
This is an illustrative example. The people marts run on Snowflake and dbt under Airflow, fed by Workday, ADP and an applicant tracking system. Hierarchy changes and access are at L2.
| Time | Who | What happens |
|---|---|---|
| 06:00 | Workday | Reorg takes effect; extracts land with 14 organization changes |
| 06:04 | Connectors agent | get_connector_status confirms loads; one late payroll file flagged |
| 06:10 | Schema Evolution agent | detect_schema_change maps two renamed report fields |
| 06:15 | Pipeline Building agent | New hierarchy version built; old periods restated with parity tests |
| 06:40 | Quality Monitoring agent | run_quality_check ties headcount to finance; two items do not tie |
| 06:52 | Incident Debugging agent | get_root_cause traces a mapping gap and a definition difference |
| 07:10 | Data Access & Governance agent | check_policy prepares scoped access; request_governance_review holds it |
| 07:25 | Autonomous Data-Conductor | Verifies the numbers and routes one decision |
| 08:05 | HRIS lead | Approves hierarchy; approves two of three access requests |
| 09:00 | Dashboards | Managers see the new structure; HR and finance headcount match |
The agents on the job
| Agent | What it does for an HR data platform | Tools it calls |
|---|---|---|
| Connectors and Data Ingestion | Land Workday, SuccessFactors, applicant tracking, payroll, survey and learning data and confirm every load is complete | get_connector_status, trigger_airflow_dag, get_dbt_run_history |
| Schema Evolution | Detects Workday report, field and release changes at the boundary and remaps feeds | detect_schema_change, validate_schema_compatibility, generate_migration, rollback_migration |
| Pipeline Building | Builds and versions hierarchy, headcount and movement models in dbt, with tests | generate_pipeline, validate_pipeline, deploy_pipeline |
| Quality Monitoring | Ties headcount to finance, checks one-worker-one-organization rules and runs your retention checks | run_quality_check, get_anomalies, set_sla, create_quality_tests_for_pipeline |
| Incident Debugging | Traces a headcount difference or a broken feed to the change that caused it | diagnose_incident, get_root_cause, get_incident_history |
| Data Access & Governance | Finds sensitive columns, checks access requests against policy, routes grants to owners and produces audit evidence | scan_pii, check_policy, enforce_rbac, provision_access, request_governance_review, generate_audit_report |
| Data Context & Catalog | Keeps one governed definition of headcount, tags sensitive columns and maps where a person's data flows | auto_tag_dataset, trace_cross_platform_lineage, define_business_rule, resolve_metric |
| Cost Savings & Data Cleanup | Retires stale snapshots, duplicate extracts and abandoned analyst copies of people data | get_snowflake_usage, get_cost_enrichment, detect_dead_assets |
Data Context Wizard holds one governed definition of headcount, FTE, attrition, span of control and every hierarchy level. Dashboards, the finance feed and every assistant HR staff use answer from the same definitions, so HR and finance stop quoting different numbers. Autonomous Data-Conductor verifies the numbers that matter before the board pack and before assistants read them. Spellbook Data Catalog makes each people data product discoverable, with its owner and its sensitivity, in plain English. The Identity Agent and the Data Security Agent work alongside, on who people and agents are and on where sensitive data sits.
What goes on autopilot
Once a domain has earned it, this work runs on its own, and each item removes a problem your team deals with today:
- •Workday report and field changes are remapped at the boundary, so a release or a renamed calculated field no longer breaks the Monday dashboards.
- •Headcount is tied to finance every morning, so the board deck and the HR dashboard stop disagreeing.
- •New feeds are scanned for sensitive columns before first use, with a masking decision proposed for each, so pay and health leave do not leak into a general-purpose mart.
- •Evidence is captured as work happens, so an access review or a privacy request starts from a record, not a search.
Where your people stay in charge
Agents never get blanket access. Each domain has its own autonomy level, set by you, and it only rises when the receipts show the agents are reliable. Everything starts at L1, observing only; reversible upkeep such as reruns, staging fixes, documentation and cleanup is usually first to run on its own.
- •Access grants to HR data always go to a named owner. Agents check the request, find the narrowest access and attach the evidence; they never approve their own proposal.
- •Compensation, performance and health leave data stay with Total Rewards, HR and Legal. Agents prepare tests and tie-outs; a person approves any change to who sees them.
- •Protected attributes such as gender, ethnicity, disability and age are used only where a named owner has approved the purpose, and masking decisions for them are proposed, not applied alone.
- •Any individual-level release, to a manager, an analyst or an assistant, is a person's decision. Small-group suppression rules are set by people and tested by agents.
- •Responses to subject access requests and deletions are released by the privacy office, not by an agent.
Once a deployment has matured, here is how that ladder plays out across task classes:
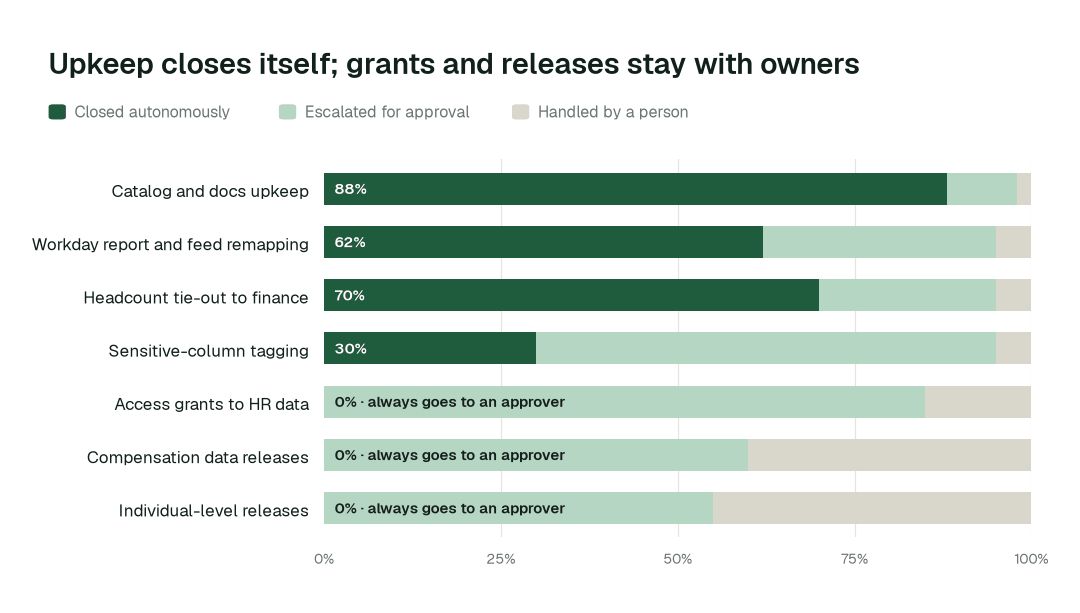
Catalog and docs upkeep closes autonomously 88% of the time. For access grants, compensation data releases and individual-level releases, autonomous closure is 0% by design: each is prepared as a proposal with the evidence and approved by a named person.
What happens when an agent is wrong
- •At L2 propose, nothing changes until a named person approves. The proposal shows the full diff, the population affected and how to roll it back. Unanswered requests expire and escalate.
- •L3 and L4 are where a domain can go next, on its own review record: acting on its own, with a rollback point on every change. Only the domain's owner raises its level, and if people start reverting the agents' changes, the domain pauses itself.
- •No agent approves or promotes its own work. Autonomy only grows on evidence, domain by domain, and repeated reverts pause the domain.
- •One org-wide stop halts all autonomous dispatch, and every action lands in a tamper-evident audit trail you can export with
generate_audit_report.
How it fits your stack
Data Workers connects to what you already run: Workday or SuccessFactors; Greenhouse or Lever; ADP and payroll exports; engagement survey and learning system data; Snowflake or Databricks; dbt; Airflow; Tableau or Looker; your identity provider. Each agent is an MCP server, so the same agents work inside Claude Code, Cursor or Codex and in Slack or Teams through Spellbook. Nothing migrates.
- •Runs in your infrastructure with your credentials and your model key. The hosted Autonomous Data-Conductor sees workflow metadata only, never rows. The VPC and air-gapped options matter when employee data cannot leave your network, and sensitive-data scanning never sends sample values outside it.
- •Uses the access you already govern. Agents act under scoped service identities and your existing roles; every grant goes through
provision_accessand is logged. Keep your identity provider as the source of truth: Okta decides who people are, and Data Workers checks that warehouse grants still match, including for leavers. - •Proposes changes as diffs in your dbt project, orchestrator and warehouse, with blast radius, tests and a rollback point, and applies them only at the autonomy level you set for that domain.
- •Open-source core. The Apache-2.0 community edition ships 11 agents and 160+ MCP tools, so your engineers, and your privacy office's technologists, can read exactly what the agents call.
Governance and regulation
Employee data is personal data, and several categories in it are the most protected there are: health leave, trade union membership, and the protected characteristics behind equality reporting. In the EU, GDPR gives every employee the right to see what you hold about them and requires that you keep it no longer than needed. Pay transparency rules in the EU are adding reporting duties on pay gaps. The auditor, the works council and the privacy office will each ask who can see which population, who approved it and where one person's data flows.
Data Workers keeps access scoped with enforce_rbac and provision_access, finds sensitive columns with scan_pii, maps where a person's data flows with trace_cross_platform_lineage, and records every action in a tamper-evident audit trail. Segregation of duties is preserved: the agent that prepares a request never approves it. For how these controls support GDPR and other frameworks, see how Data Workers helps with SOX, HIPAA, GDPR and the EU AI Act, and for the detection side how Data Workers handles PII. The detail of one request is in pii detection and masking, run by agents.
Data Workers doesn't make you compliant; your controls, people and assessors do. It supplies controls and evidence wherever agents touch data. Not legal advice.
The alternatives HR data platform teams weigh
Build it yourselves. A strong team can wire a coding agent to MCP servers for the warehouse and dbt. The work is everything around it: routing each grant to the right owner, blast radius, rollback, receipts, and current context about every other system.
HR suites, people analytics tools and access tools. Workday and SuccessFactors hold the record and ship their own reporting, people analytics vendors model the data, and access tools such as Satori decide what each person sees at query time. They depend on the pipeline under them. Data Workers keeps that data right, traces a wrong number to its cause and leaves the receipt.
Platform-native agents. The warehouse vendors ship agents that work well inside their own platform. HR data work crosses the HR system, the applicant tracking system, payroll, the orchestrator, the warehouse and BI, and Data Workers works across all of them.
In this space specifically. Analyst-owned spreadsheets, one-off SQL for each HRBP and a hand-kept access list are the incumbent. Agents replace the repetitive lookup and tie-out and leave the decision with the owner.
The case for your CTO
What this replaces. Hand-rebuilt hierarchies at every reorg, a ticket queue of access requests, feeds that break on Workday changes, and the search for where one person's data lives.
What your team gets back. An HR data platform team that ships people data products instead of rebuilding hierarchies and answering "which headcount is right".
Integration effort. Connecting is configuration, not a migration. The agents attach over MCP to the warehouse, orchestrator, dbt project and HR system extracts you already run, under the roles you already govern, inside your own infrastructure. Your engineers can read every tool the agents call in the open-source core.
Risk and control. Autonomy is set per domain. Everything starts at L1, observing only; reversible work moves up only when the receipts justify it; access grants, compensation, protected attributes and individual-level releases stay with a named owner; and one org-wide stop halts all autonomous work.
Why now. HR teams are being asked to put AI assistants in front of employee data. That multiplies the cost of one wrong grant and of one headcount that does not tie.
The first win. Org hierarchy and headcount for one reorg cycle. The pilot below lays out the scope, what you see each week and the cost.
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For HR data platform teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; access grants, compensation and individual-level releases always go to a named owner.
- •Autonomous, under your governance. Routine work runs on its own: Workday changes are remapped at the boundary, headcount is tied to finance every morning and new feeds are scanned before first use. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. An HR data platform team that ships people data products instead of rebuilding the hierarchy. People set direction, and the platform carries it out.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how HR data platform teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. Your Workday or SuccessFactors extracts, the applicant tracking and payroll feeds, Snowflake or Databricks, dbt, Airflow and the BI tools HR reads, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Org hierarchy and headcount for one reorg cycle.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path, scan the feeds for sensitive columns and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Workday change remapping and the daily headcount tie-out start running on reversible work. Hierarchy changes and every access grant stay at L2 with a named owner.
- •At day 30. We review the impact metrics against your baseline:
- •HRBP access request: from about a week to 5 min
- •Headcount tie-out to finance: from about 3 days to 15-20 min
- •Reorg hierarchy rebuilt: from about a week to about an hour
- •the share of catalog and docs upkeep closed autonomously, targeting 88% as the deployment matures
- •What you decide. Whether to expand to the next domain, such as recruiting or compensation data. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
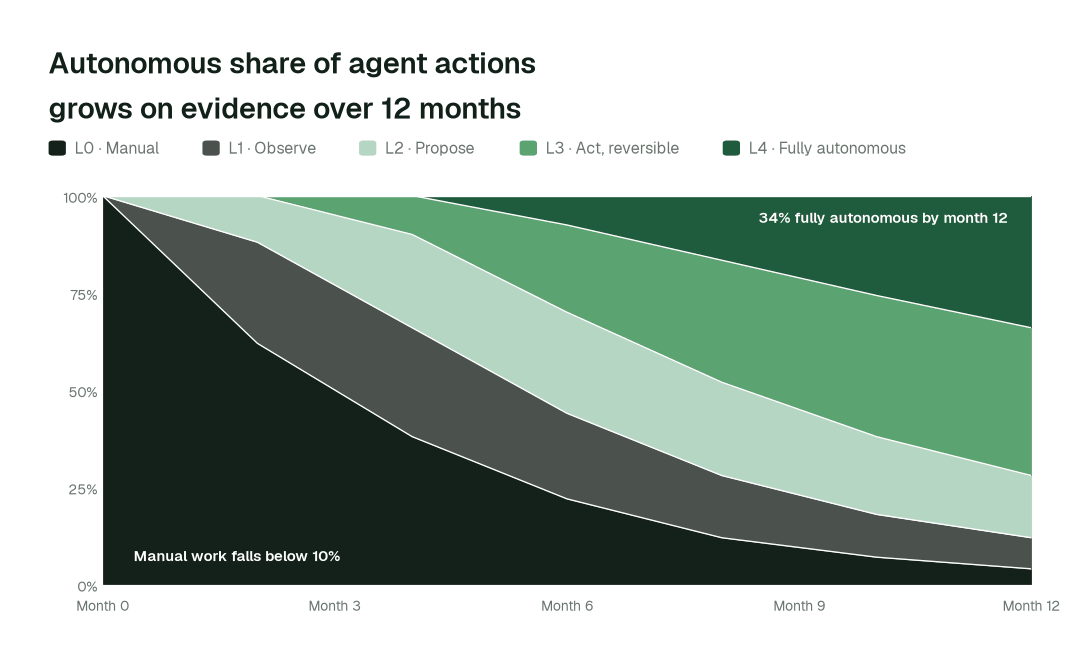
By month 12, more than 34% of agent actions run fully autonomously and manual work falls below 10%, while compensation, protected attributes, individual-level releases and access grants stay with a named owner.
FAQ
Does it work with Workday and SuccessFactors? Yes, through the extracts, report outputs, replicas or warehouse tables you already load; the agents attach to the warehouse and orchestrator, not inside the HR system.
Will agents grant access or release individual records? No. Agents check the request, find the narrowest access and attach the evidence, and a named owner approves. Individual-level releases are a person's decision.
Can it help with a subject access request? Yes. It maps where one person's data flows and assembles the evidence for your privacy office. The office decides what is released, and what is deleted.
Where do the agents run? In your infrastructure, with your credentials and model key. The hosted Conductor sees workflow metadata only, and sensitive-data scanning never sends sample values outside your network.
Do we have to migrate anything? No. Your HR system, warehouse, dbt project, orchestrator, catalog and BI stay where they are.
Where do the other people data teams fit? See the group page for people data teams.
Sources
- •Data Workers pricing: https://dataworkers.io/pricing/
- •EU General Data Protection Regulation (Regulation 2016/679), including the right of access (Article 15), storage limitation (Article 5) and special categories of data (Article 9): https://eur-lex.europa.eu/eli/reg/2016/679/oj
- •EU Pay Transparency Directive (Directive 2023/970): https://eur-lex.europa.eu/eli/dir/2023/970/oj