You're on Omni: One Governed Model, Spreadsheet-Speed Analysis. Data Workers Owns Whether the Data Under It Is Right
Already on Omni? Data Workers checks the tables under every topic and dashboard, traces a wrong number to its cause and fixes it upstream behind a named approval, with a receipt.
Your company moved to Omni for one reason: a governed model that people can actually work in. Analytics engineers keep topics, views, dimensions and measures in the shared model, versioned in git and synced with the dbt project. Analysts open a workbook and move between point-and-click, SQL and spreadsheet formulas on live data. Dashboards and apps go out to the business, scheduled deliveries land in Slack every morning, and people ask the Omni Agent (called AI Assistant until April 2026) in the app, or @Omni in a channel through the Omni Slack Agent (launched in beta in April 2026). Engineers reach the model from Claude, Cursor or ChatGPT through Omni's MCP server. Omni is where the governed model meets spreadsheet-speed analysis. Data Workers owns whether the data under that model is right: it checks the tables after every run, traces a wrong number to its cause, proposes the fix behind a named approval and verifies it with a receipt.
Key takeaways
- •Omni keeps its job. The model, workbooks, dashboards, apps and agents stay with their owners.
- •A governed model makes one wrong table travel further. Every answer built on a topic inherits what the tables under it say. Data Workers checks those tables and holds key numbers to a baseline.
- •Omni already tells dbt what depends on what. Its exposures name each shared dashboard and the models it reads, so a pull request comes with the Omni content it reaches.
- •The fix lands where the cause is. Data Workers proposes the upstream diff, routes it to a named approver and queues the rerun. It changes nothing in Omni.
- •Start with one topic the business acts on, then climb from L0 manual to L4 autonomous per domain.
Omni is where the governed model meets spreadsheet-speed analysis. Data Workers owns whether the data under that model is right.
Omni's model is the reason answers agree: a measure defined once means the same thing in a workbook, a dashboard, an app and an agent's reply. The mirror image: when a table under a topic starts to mean something different, every surface moves together and nothing in Omni looks broken.
Here is a Tuesday morning at a consumer subscription app that buys most of its growth through paid channels. It runs Omni on BigQuery, with dbt Core orchestrated by Airflow 2 on Astro. This is an illustrative example.
| Time | System | What happens |
|---|---|---|
| Mon 17:20 | Google Sheets | A marketing ops coordinator tidies the Channel mapping sheet and sorts the channel column on its own instead of the whole range. 212 of 340 utm_source / utm_medium pairs now point at the wrong channel. Every value is still a valid channel name |
| Tue 02:00 | Airflow 2 on Astro, dbt Core, BigQuery | The marketing_daily DAG run runs dbt build. stg_marketing__channel_map reads the sheet through a BigQuery external table, which reads the live sheet at query time; fct_signups_by_channel and fct_cac_by_channel build from Segment signup events and ad spend. Every test passes, including accepted_values on channel. The snap_channel_map snapshot records the new mapping |
| 02:30 | Data Workers | The post-run run_quality_check on fct_signups_by_channel (BigQuery, service-account key) passes: signup_id unique, no null keys, rows above the minimum. The channel mix the team records with monitor_metrics after each run is off baseline: paid social at 41% of signups against a 30-day baseline of 17%, organic search at 6% against 24%. Total signups, 3,904, sit on their baseline. It is flagged |
| 02:34 | Data Workers | diagnose_incident: the dbt manifest, read natively, shows no model change since Friday, and total signups are normal, so the cause is in how signups get a channel, not in how many arrived. trace_cross_platform_lineage walks fct_cac_by_channel back through stg_marketing__channel_map to raw_marketing.channel_map. A graph note records that it is an external table over a sheet marketing ops edits by hand |
| 02:37 | Data Workers, Slack | blast_radius_analysis lists fct_cac_by_channel, fct_ltv_to_cac, the Growth dashboard and the Paid media app (the dashboards Omni's exposures name, recorded in the context graph). A graph note adds that the Acquisition topic is open to the Omni Agent and the Slack Agent. send_slack_alert posts to #data-incidents with the evidence and a check query for the sheet owner |
| 07:00 | Omni | The scheduled Slack delivery posts the Growth dashboard to #growth: paid social CAC $59, down from $142 |
| 07:45 | BigQuery, Google Sheets | The marketing ops lead runs the check Data Workers sent, which compares today's mapping with the rows valid yesterday in snap_channel_map: 212 pairs changed channel overnight. Version history in Sheets shows the sort at 17:20 Monday. Cause confirmed |
| 08:05 | Omni Slack Agent | The CMO @mentions Omni in #growth: where should next week's budget go? The agent answers from the Acquisition topic that paid social CAC fell 58% and suggests shifting spend there. It is faithful to the model; the model is fed a scrambled mapping. The on-call replies with the incident link, and the growth lead holds the budget move planned for 10:00 |
| 08:15 | Google Sheets | The coordinator restores the Monday 17:19 version |
| 08:20 | Data Workers, Spellbook | Proposes the plan. For the dbt owner, a diff to merge: a singular test that fails the run when more than 10 mapping pairs change channel within a day. After the merge, a rerun of marketing_daily. For the Omni model owner, a dashboard refresh once the run lands. With it: the blast radius, the checks it will repeat and the undo (revert the diff). The approval request reaches the analytics engineering lead in Slack |
| 08:50 | Spellbook, GitHub | The lead reviews the evidence and approves in Spellbook; the dbt owner merges the diff |
| 08:55 | Data Workers, Airflow | trigger_airflow_dag queues the approved marketing_daily run |
| 09:25 | BigQuery | The run finishes and the new test passes against the restored sheet. run_quality_check passes, and monitor_metrics records paid social at 17.4% and organic search at 23.8% of signups, back inside their baselines |
| 09:30 | Omni | The model owner refreshes the Growth dashboard (View > Refresh Data), so cached results from the morning are replaced |
| 09:35 | Claude, Omni MCP server | The on-call asks Claude, through Omni's MCP server, to run the dashboard's CAC tile with runSavedQuery: paid social $139, consistent with the recorded mix. The growth lead cancels the budget move. Data Workers writes the receipt (cause, diff, approver, rerun, checks, undo) and a graph note that the channel mix depends on a hand-kept sheet |
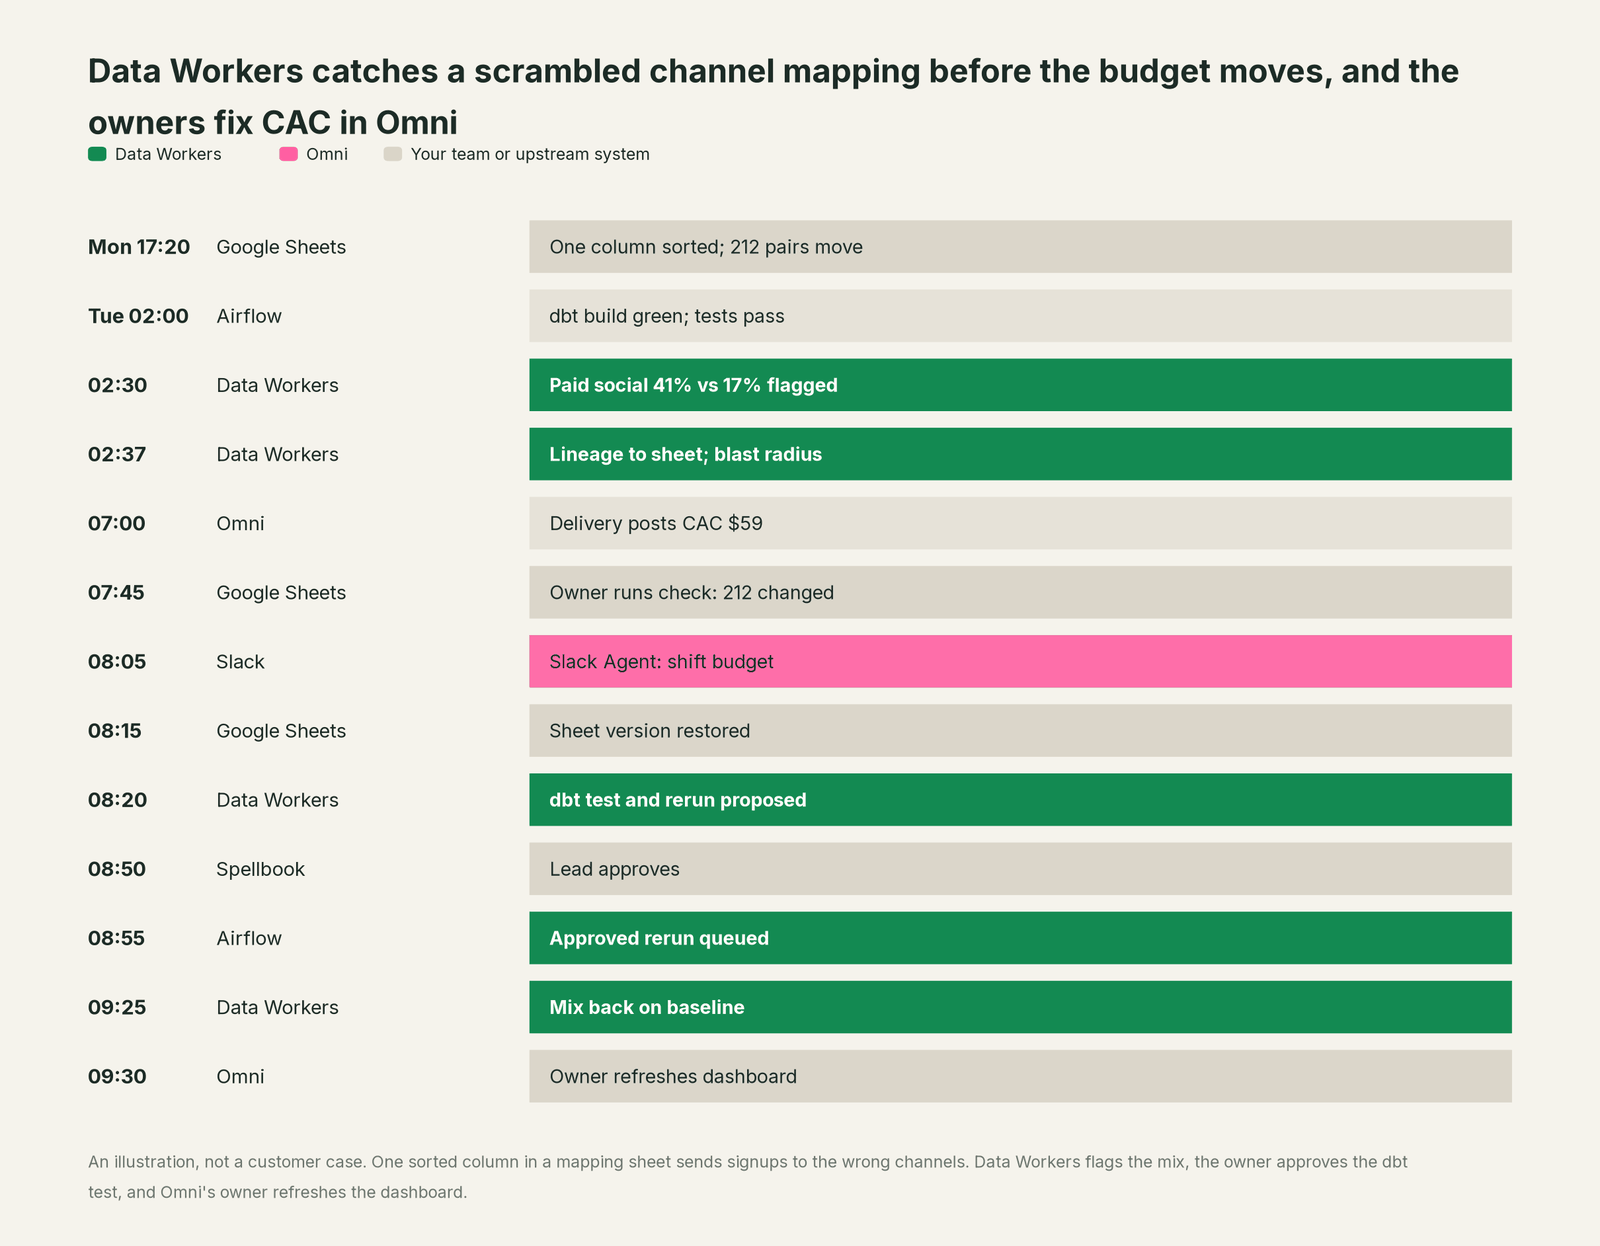
Every system did what it was built to do. The defect lived in the meaning of the rows, hours before a real budget decision. Data Workers caught it at 02:30, a named person approved the fix, and the money stayed put.
| Job | What Omni does | What Data Workers does |
|---|---|---|
| The model | Topics, views, measures, AI context and access grants, in git and synced with dbt | Keeps the tables and dbt models under those topics right |
| The analysis | Workbooks with SQL, point-and-click and spreadsheet formulas on live data; dashboards and apps | Records the headline numbers people act on and holds them to a baseline |
| The answer | The Omni Agent, the Slack Agent and the MCP server answer from the model, scoped to each person's permissions | Makes sure the data those answers rest on is true before someone acts on them |
| The break | Runs whatever the warehouse returns; cached results hold until their policy expires or someone refreshes | Catches the shift, traces it to the change that caused it and lists every model and declared dashboard or app it reaches |
| The fix | Owners edit the model, topics and content, and refresh dashboards | Proposes the upstream fix as a diff for its owner, routes it to a named approver and queues the approved rerun |
| The proof | Answers again from fresh data, in the app, in Slack or through MCP | Re-checks the tables, compares the recorded values and writes a receipt with cause, diff, approver and undo |
Why doesn't Omni just do this itself?
Omni made a sharp bet: a governed model at the center, worked at the speed of a spreadsheet. Its guardrails fit that job well. MCP interactions are "scoped only to the model (and topic, if provided) supplied to the MCP", and every query uses the authenticated person's permissions. Single-shot query generation is off by default. When the agent edits an existing dashboard, the change lands in a draft until someone publishes it. The Modeling Agent works in Sandbox, Review or Auto mode, and the shared model can require a branch before any change. Push to dbt opens pull requests for exposures, descriptions and models.
All of that protects Omni's own surface. Omni does not run the Google Sheet, the external table, the dbt project or the Airflow DAG, and it should not have to. Fixing this incident took a lineage trace through four systems, a snapshot check, a dbt test, a named approval, an orchestrator rerun and a verification. That is a different product with a different liability: cross-system context, blast-radius scoping, approvals, rollback and receipts for changes in systems Omni doesn't own. It is the product Data Workers is.
Every tool owns a slice. Data Workers covers the whole lifecycle
Omni owns one slice outright: a governed semantic model with spreadsheet-speed analysis on top. Each point tool adds another console, contract and handoff. Data Workers covers the whole lifecycle with one context, one approval flow and one audit trail, and builds on the Omni you already run.
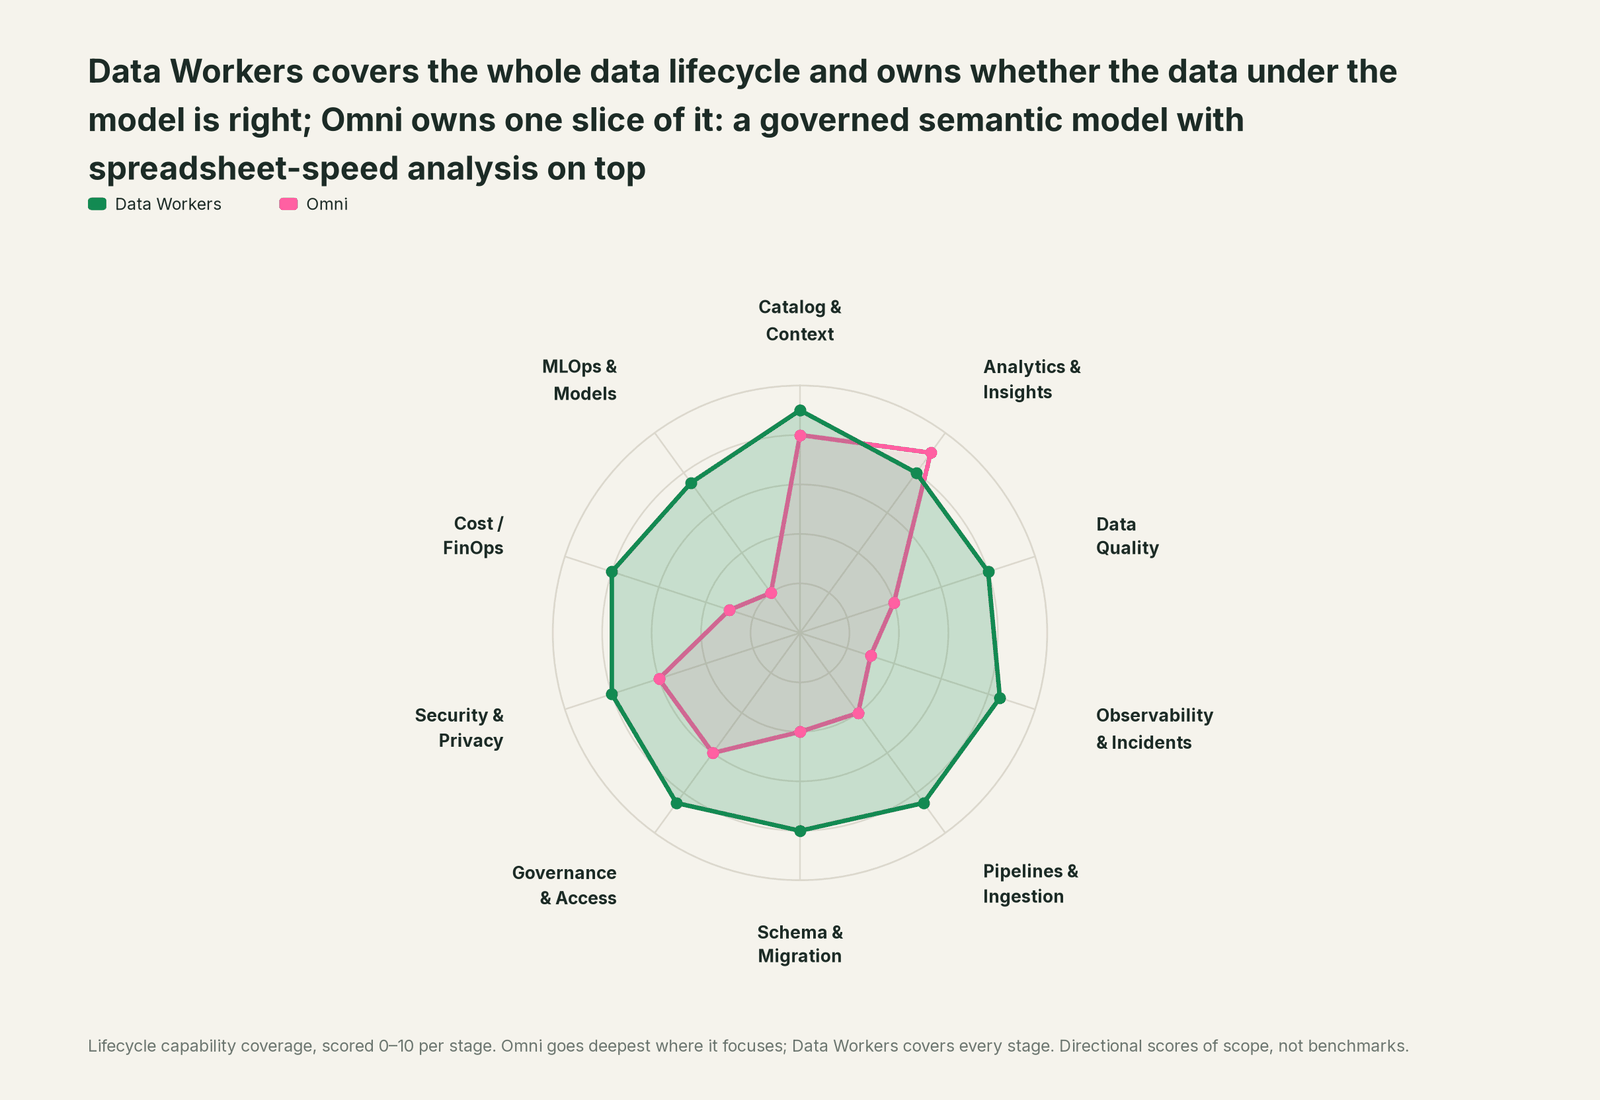
| Stage | Data Workers | Omni | Why we scored it this way |
|---|---|---|---|
| Catalog & Context | 9 | 8 | The shared model holds topics, views, measures and AI context in YAML with git, and pulls dbt metadata and MetricFlow metrics. Data Workers keeps one governed context graph across every platform, joined to lineage, quality and owners. |
| Analytics & Insights | 8 | 9 | Omni's home stage: workbooks with SQL, point-and-click and spreadsheet formulas, dashboards, apps, the Omni Agent and the Slack Agent on one model. Data Workers makes sure the tables under them are right. |
| Data Quality | 8 | 4 | dbt data health tiles can show test status on a dashboard; Omni does not test the tables under a topic. Data Workers checks them after every run and holds recorded values to a baseline. |
| Observability & Incidents | 8.5 | 3 | Alerts and conditional routines fire on a result; they do not trace a cause. Data Workers traces a wrong number back to the source, sheet or model behind it, proposes the fix and verifies it. |
| Pipelines & Ingestion | 8.5 | 4 | Analysts can turn a workbook query into a dbt model and push it to the repo as a pull request. Data Workers queues approved reruns through the orchestrator for the pipelines under Omni. |
| Schema & Migration | 8 | 4 | dbt sync, branch mode and the content validator keep the model in step with dbt inside Omni. Data Workers reviews dbt changes and scopes the blast radius across models and declared dashboards. |
| Governance & Access | 8.5 | 6 | Model and content permissions, access grants and branch-based review govern Omni itself. Data Workers routes every data change to a named approver. |
| Security & Privacy | 8 | 6 | Row-level security, user attributes and MCP queries scoped to the user's permissions protect Omni's surface. Data Workers leaves a receipt on every data change and proposes masking for the owner to apply. |
| Cost / FinOps | 8 | 3 | Caching, cache policies and aggregate awareness cut repeat warehouse queries. Data Workers attributes Snowflake spend per query and per dbt model through query tags, and sums BigQuery spend for the account. |
| MLOps & Models | 7.5 | 2 | Omni serves analytics, not models. Data Workers keeps the data under models and agents healthy. |
How Omni and Data Workers work together
Your people stay in Omni, in Slack and in their AI clients. Alerts and approval requests reach them in Slack or email. Spellbook Data Catalog (in preview) is where the data team reviews each fix, its blast radius, approver and rollback. Underneath, Data Context Wizard keeps one governed context graph, the Data-Agents Swarm brings 20+ specialist agents, and the Autonomous Data-Conductor runs each fix end to end (detect, diagnose, fix, review, verify, remember).
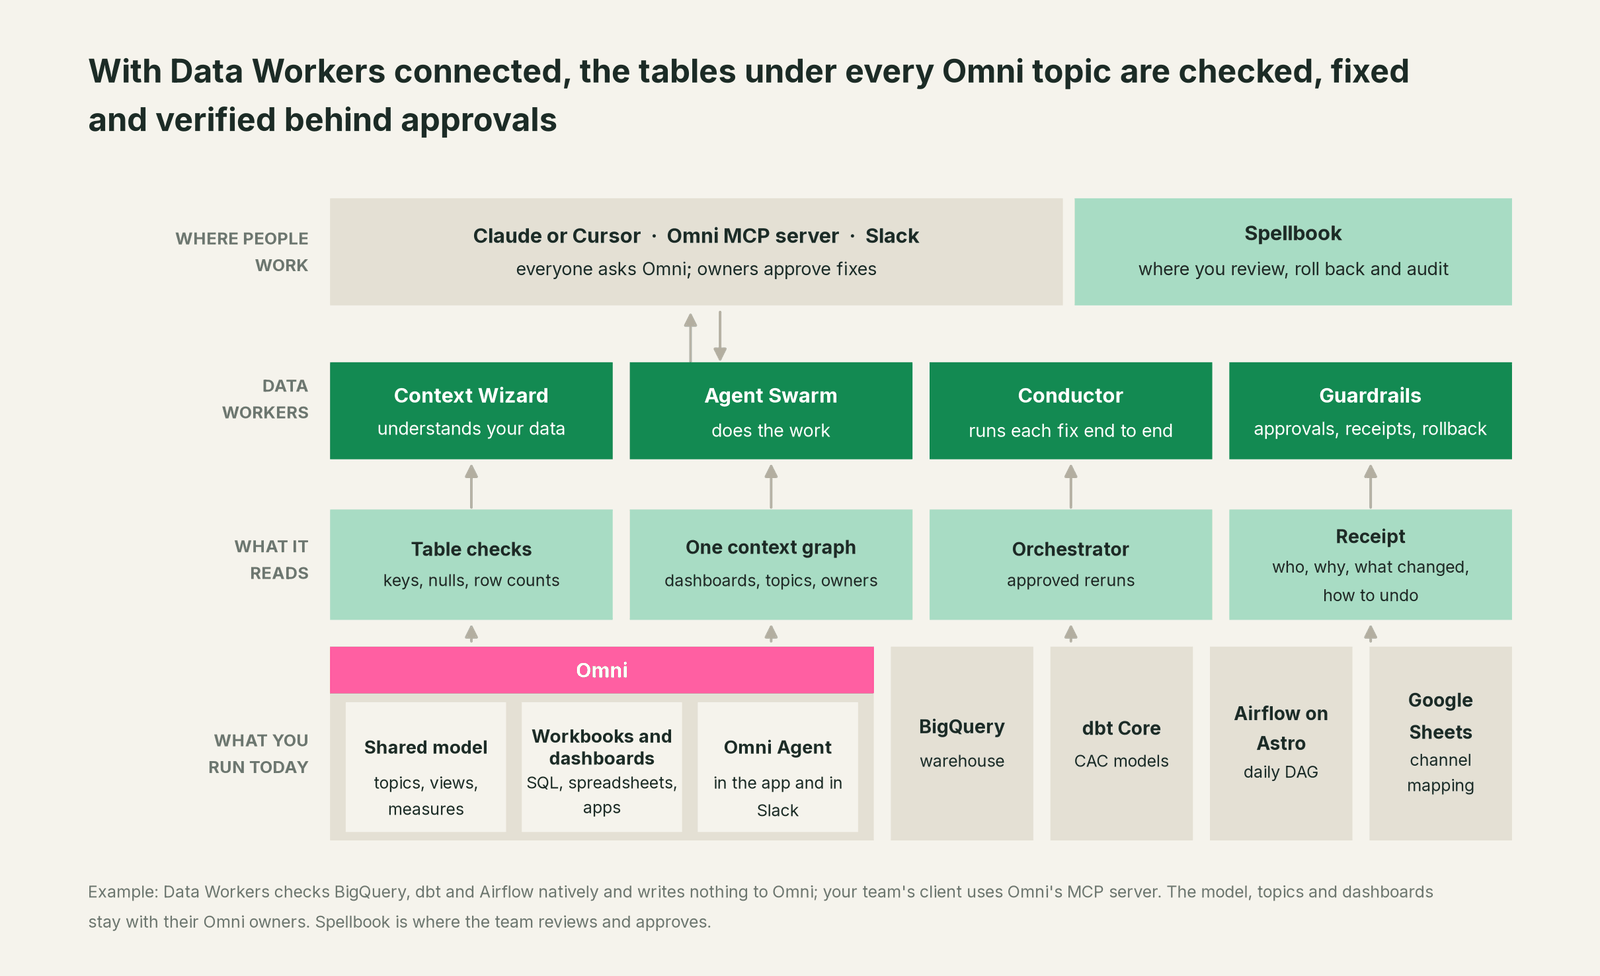
Where Data Workers works. Natively on what sits under Omni: BigQuery, Snowflake or Postgres, the dbt project and the orchestrator. It connects to Omni over its API or MCP server today; your team's client uses Omni's MCP server side by side, and Data Workers' agents never call it. Push exposures from the model IDE (Model > Push to dbt, Sync exposures) or script them from Omni's dbt exposures API, and your dbt project lists each shared dashboard and app with the models it reads. Data Workers' change review reads those exposures from the manifest, and the same dashboards, plus facts such as "the Slack Agent answers from the Acquisition topic", are recorded in the context graph so blast_radius_analysis names them. Data Workers writes nothing to Omni; BI is read by design.
What Data Workers checks under each topic. run_quality_check runs nulls, uniqueness on id columns and minimum row counts on Snowflake and Postgres, and on BigQuery with a service-account key; get_quality_score rolls them up. monitor_metrics holds recorded values, such as channel mix or CAC, to a baseline, which is how a valid-looking change in meaning gets caught. trace_cross_platform_lineage and blast_radius_analysis follow a table upstream and downstream; explain_table returns its definition, lineage, freshness, documentation and trust score; diagnose_incident, remediate and get_incident_history run and record the incident. Your data stays in your systems: the agents, warehouse credentials and model key run in your infrastructure, and the hosted Conductor sees workflow metadata only.
Setup over MCP today. Clone the open-source repository and add start-agent.sh entries to your client's MCP config, as the client setup docs show. For Omni's MCP server alongside it, an Organization Admin turns it on in AI Hub > MCP (Enable AI and the Omni Agent must be on, plus Personal Access Tokens for OAuth) and picks the tool groups. With OAuth, Omni creates a key tied to each person's account, so every query runs with their Omni permissions. For people who only ask questions, leave Agentic capabilities off and allow content access (searchContent, runSavedQuery).
// Example: .cursor/mcp.json. The omni entry is your team's own connection
// to Omni's MCP server (OAuth on first connect); Data Workers does not call it.
{
  "mcpServers": {
    "omni": {
      "url": "https://callbacks.omniapp.co/callback/mcp"
    },
    "dw-context-catalog": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-context-catalog"]
    },
    "dw-quality": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-quality"]
    },
    "dw-incidents": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-incidents"]
    }
  }
}
List the tools with your client's own command. Ask "is everything under the Growth dashboard healthy?" and get the saved queries from Omni's server and the lineage, checks and open incidents from Data Workers in one answer.
Where fixes go. Data Workers proposes the change as a diff for the owner to merge, usually a dbt model, test or source mapping, with its blast radius and undo step; it opens the pull request itself only when your team turns on the dbt GitHub pull-request target. After approval it queues the rerun through Airflow, Dagster or Prefect. Omni's cache expires on its policy, the next scheduled delivery runs fresh, or the owner clicks Refresh Data. When a measure or topic should change, Data Workers says which one and why, and the model owner edits it in Omni.
One request, L0 to L4. The autonomy ladder is set per domain.

- •L0 manual. Connected, not acting. Someone notices a strange number and starts digging.
- •L1 observe. Checks every table under your key topics and logs what it would do.
- •L2 propose. Drafts the upstream fix with its blast radius; a named owner approves in Spellbook before anything runs.
- •L3 act reversibly. For proven classes, such as rerunning the daily DAG after an approved fix, it acts, verifies and records the undo.
- •L4 autonomous. For a narrow class in one domain, it fixes and verifies on its own and posts the receipt.
Approvals go to a named person; a request nobody answers expires and escalates, and never grants itself. No agent can promote its own work. The full safety model: is it safe to let AI agents change production data, how approvals work, autonomy levels L0 to L4 and where does our data go.
Many Omni teams came from Looker: You're on Looker shows the same loop under LookML, and LookML to Data Context Wizard shows how definitions become governed context. Metrics in MetricFlow? Read You're on the dbt Semantic Layer. Also see You're on Sigma, You're on Astronomer, You're on dbt, You're on Segment, and our semantic layer tools compared and ground LLM analytics in a semantic layer pages.
What changes for your team
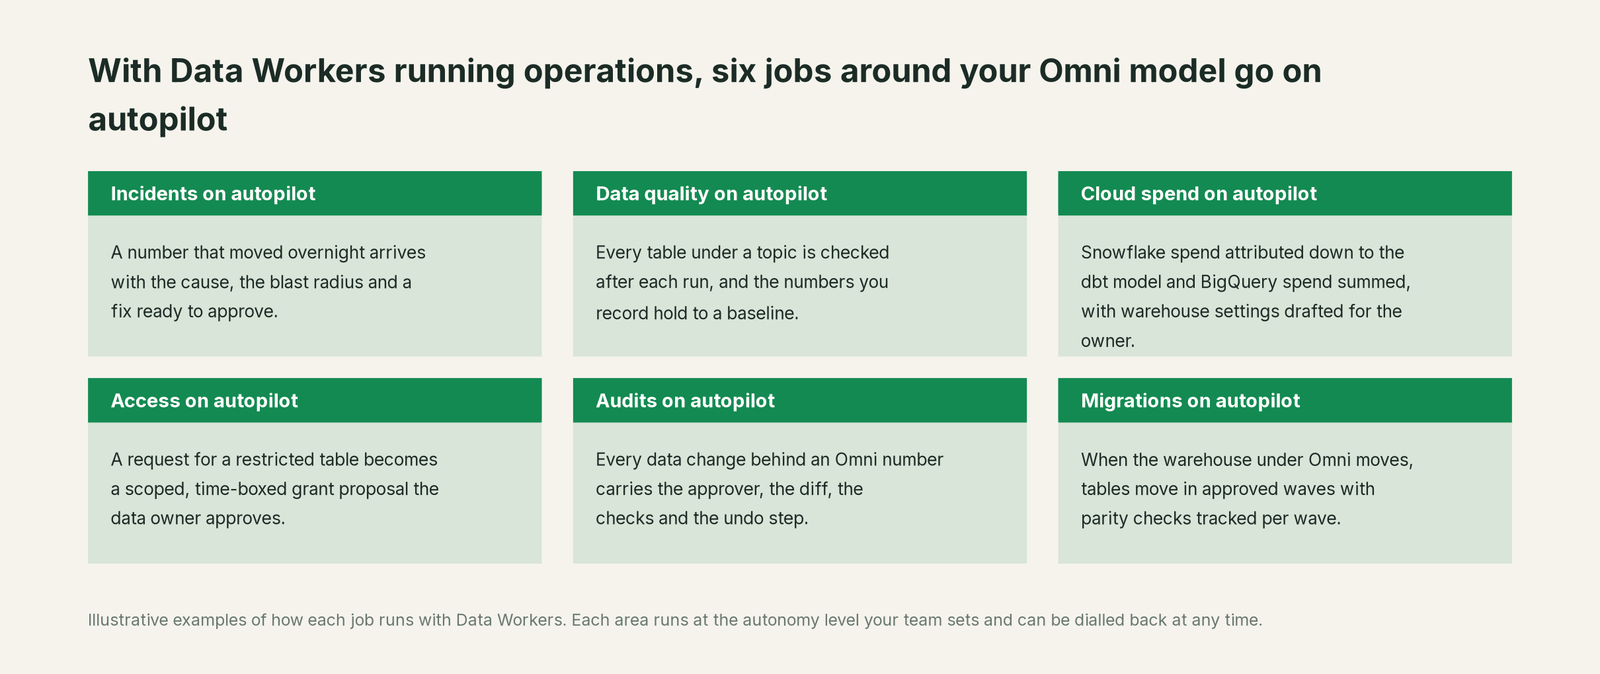
Omni teams often pair a small analytics engineering group with a large self-serve business. What still eats their week is "is this number right?" With Data Workers, these jobs run on autopilot at the level you set.
- •Incidents. A number that moved overnight arrives with its cause, blast radius and a fix to approve.
- •Data quality. Every table under a topic is checked after each run.
- •Cloud spend. Snowflake spend attributed to the dbt model, BigQuery spend summed for the account.
- •Access. A restricted-table request becomes a time-boxed grant proposal for the owner.
- •Audits. Every data change behind an Omni number carries approver, diff, checks and undo.
- •Migrations. When the warehouse moves, tables move in approved waves with parity checks tracked.
Keep Omni, or consolidate?
Keep Omni if you love it; Data Workers works with it from day one. Many teams consolidate once Data Workers runs that slice too.
Most teams keep Omni: the model, workbooks, apps and agents belong there. What they consolidate is the tooling around it: a separate data-quality product, a scheduled query that emails when CAC jumps, a spreadsheet of which dashboard reads which model. Weighing a build on Omni's MCP server and a coding agent? Read build it ourselves with Claude Code and MCP servers: connecting servers is easy; context, approvals and rollback are the work. See also Data Workers integrations and who owns the agents.
The case for your CFO
The outcome: the numbers your company runs on in Omni (CAC, signups, revenue, retention) stay right, and when something upstream changes their meaning, the fix arrives before anyone moves money on it.
The risk story: Data Workers changes nothing in Omni. It checks the tables and dbt models under each topic and proposes upstream fixes as diffs; nothing runs until the named owner approves. Every change is verified and leaves a receipt: what broke, what changed, who approved it and how to undo it. Autonomy is set per domain from L0 manual to L4 autonomous, and an org-wide stop halts all autonomous dispatch. There is zero migration.
Why now: the Omni Agent answers in the app, the Slack Agent in channels, routines on their own schedule, and the MCP server in every AI client. A scrambled table no longer waits for an analyst to spot an odd chart; it reaches the CMO as a recommendation to move budget.
The first win: one topic the business acts on, every table under it checked after each run and its headline numbers held to a baseline. What stays the same: your Omni model, permissions and content, your warehouse, dbt project, orchestrator and review process. For the numbers, see the ROI of agentic data operations.
The sentence to repeat upstairs: "Omni keeps one governed model everyone works in; Data Workers makes sure the data under it is right, and a named owner approves every fix with a receipt."
Getting started
Start with a pilot. Pick the Omni topic behind a number people spend money on, connect Data Workers read-only to the warehouse, dbt and orchestrator under it, push your exposures to dbt, and let it check every table that topic reads for a few weeks before turning on the first fix class. The pilot path and plans are on the pricing page, and the pilot is credited in full against the first year.
FAQ
Does Data Workers edit our Omni model, topics or dashboards? No. They stay with their Omni owners. When a definition should change, Data Workers says which one and why, and the model owner edits it through your usual branch and review flow.
Our dbt tests all passed. How did Data Workers catch the wrong CAC? The rows were valid; their meaning changed. monitor_metrics holds the values your team records, like channel mix or signups per day, to a baseline, so a shift no null, uniqueness or accepted-values test would see still opens an incident with its lineage and blast radius.
How does Data Workers know which Omni dashboards a table reaches? Omni pushes exposures into your dbt project that list each shared dashboard and app and the models it reads. Data Workers reads the dbt manifest natively, and those dashboards are recorded in the context graph, so blast_radius_analysis names them.
The Omni Agent gave a wrong answer. Can Data Workers tell why? Usually the agent was faithful to the model and the data underneath was wrong. Data Workers traces the topic's tables back to the source, sheet or dbt model that moved, and the receipt records the cause and the fix. Its agents never call the Omni Agent or Omni's MCP server.
Can Omni push our metrics into dbt? No. Omni's dbt Semantic Layer integration is a one-way import of MetricFlow metrics into Omni. What Omni pushes to dbt is exposures, descriptions and dbt models authored in workbooks. Governed metric definitions can reach Data Context Wizard from your dbt project or through your team's coding agent.
Does this work if Omni runs on Snowflake or Databricks? Yes. Data Workers works on the warehouse, dbt and orchestrator under Omni, across 50+ connectors. Table checks run natively on Snowflake, Postgres and BigQuery; elsewhere, the dbt manifest, orchestrator runs and recorded baselines carry the loop.
Sources
- •Omni, homepage, https://omni.co (checked Oct 3, 2026)
- •Omni, Product updates (Omni Agent renamed from AI Assistant and Omni Slack Agent in beta, Apr 5 2026; dashboard edits through MCP and the Slack Agent, week of Aug 24; apps GA, week of Aug 31; cache policy schedules, week of Sep 7; MCP app tools and exposures from apps, week of Sep 14; Omni Agent web search, week of Sep 21 2026), https://docs.omni.co/changelog (checked Oct 3, 2026)
- •Omni, Introducing the Omni Slack Agent (Apr 22, 2026), https://omni.co/blog/introducing-the-omni-slack-agent (checked Oct 3, 2026)
- •Omni docs: Omni Agent https://docs.omni.co/ai/chat ; Modeling Agent https://docs.omni.co/ai/model-assistant ; Omni Slack Agent https://docs.omni.co/integrations/omni-slack-agent (checked Oct 3, 2026)
- •Omni docs: AI MCP Server https://docs.omni.co/ai/mcp ; MCP server tools https://docs.omni.co/ai/mcp/tools ; MCP authentication https://docs.omni.co/ai/mcp/authentication ; Cursor setup https://docs.omni.co/ai/mcp/cursor (checked Oct 3, 2026)
- •Omni docs: dbt integration https://docs.omni.co/integrations/dbt ; pushing exposures https://docs.omni.co/integrations/dbt/exposures ; dbt Semantic Layer (one-way import) https://docs.omni.co/integrations/dbt/semantic-layer ; authoring dbt models https://docs.omni.co/integrations/dbt/models (checked Oct 3, 2026)
- •Omni docs: caching https://docs.omni.co/analyze-explore/performance/caching ; cache_policies https://docs.omni.co/modeling/models/cache-policies (checked Oct 3, 2026)
- •Google Cloud, Create Google Drive external tables (Sheets), https://cloud.google.com/bigquery/docs/external-data-drive, and External tables (limitations, no result caching), https://cloud.google.com/bigquery/docs/external-tables (both updated Sep 30, 2026; checked Oct 3, 2026)
- •Data Workers, Client setup, https://dataworkers.io/opensource-docs/client-setup/, and the open-source repository, https://github.com/DataWorkersProject/dataworkers-claw-community (checked Oct 3, 2026)