You're on Domino Data Lab: Domino Runs the Governed Workbench. Data Workers Keeps the Warehouse Data Behind It Right
On Domino for governed workspaces, jobs, the model registry and model risk management? Keep it. Data Workers makes sure the warehouse tables your Domino projects read are right, behind approvals.
Your data science runs in Domino, the enterprise AI platform where your teams build, scale and govern models. Practitioners open a workspace with Claude Code, Codex or GitHub Copilot ready to use, query Snowflake through a Domino Data Source, and run training as Jobs that the Domino Reproducibility Engine records: code, environment revision, command, data and results. Models go into the registry, and the ones that matter sit in governed bundles, moving through the stages your model risk policy defines, with evidence, approvals, findings and gates. When a validator asks how a model was built, Domino answers. Data Workers owns the other question: whether the warehouse data those projects read is right, and when it isn't, getting it fixed through its owner, behind approvals, with a receipt.
Domino's documentation draws the line: when your code reads a database or a Domino Data Source, "Domino does not know about the data coming from those sources" unless you materialize it as a Dataset or a file. Regulated teams do, so they can prove which data a Job read. Proving it was the right data still lands on people.
Key takeaways
- •Domino keeps its job. Workspaces, Jobs, the Reproducibility Engine, the registry, Model Monitoring and governed bundles stay where they are. Data Workers works with Domino from day one.
- •Data Workers watches the source tables. Baselines on metrics your pipelines record, quality checks on Snowflake and lineage from the dbt manifest catch a change in the tables a Domino project reads.
- •The model is a node in the graph. Register each governed model once with its source tables, and blast radius reaches it from any upstream dbt model.
- •Fixes go to data owners. Data Workers proposes the change as a diff for the owner to merge, queues the rebuild after a named person approves, and re-checks. The project owner reruns the Job.
- •Every fix leaves a receipt with the trigger, evidence, diff, approver, checks and undo path, which a validator can upload to a governed bundle as evidence.
- •Start with a pilot on one or two governed models, read-only first, then up the ladder toward L4 autonomous.
Domino runs the governed workbench. Data Workers keeps the warehouse data behind it right.
Domino answers how a model was built and whether it passed review. Data Workers answers what changed in the source data, what it reaches, who owns the fix and whether the fix held. Here is how they meet when a reference-data load changes a table under a governed model.
A pharmacovigilance team's Domino model, ae_signal_ranker, ranks drug-event pairs for the weekly safety review. A scheduled Domino Job runs every Wednesday at 06:00, reads safety.ae_coded in Snowflake through a Domino Data Source and materializes its input as a Dataset snapshot, as Domino recommends. The model sits in a governed bundle in its Ongoing Monitoring stage, with quarterly revalidation. Upstream, an Airflow 2 DAG, meddra_load, loads MedDRA dictionary files from S3 into ref.meddra_llt, and a second DAG, safety_dbt_build, runs dbt Core. The team registered ae_signal_ranker in Data Workers' context graph with its source table and features. After every build, the dbt DAG's last task computes one number, the share of adverse-event rows that carry a preferred term, and records it with Data Workers' metric monitor (monitor_metrics), which flags any value that breaks the baseline of earlier builds. This is an illustration, not a customer case.
| Time | System | What happens |
|---|---|---|
| Tue 21:00 | S3 and Airflow | meddra_load loads a new MedDRA release into ref.meddra_llt. Like every release, it changes some lowest level terms |
| 21:40 | Snowflake and dbt | safety_dbt_build rebuilds safety.ae_coded. Its join to preferred terms keeps only terms the dictionary flags current, so 6.3% of historical adverse events, coded to terms the release changed, lose their pt_code. Every dbt test passes |
| 21:52 | Data Workers | The DAG records its number. The coded share falls from 99.7% to 93.7%; monitor_metrics flags it against the baseline |
| 21:55 | Snowflake | Data Workers runs run_quality_check on safety.ae_coded: the ae_id distinct ratio is normal, rows sit above the floor, and pt_code nulls stay under the default 10% limit. The load is complete; the change is in the values |
| 21:58 | Slack and Spellbook | Data Workers posts the finding to the safety data owner and the Domino project owner. trace_cross_platform_lineage from the dbt manifest shows safety.ae_coded reads ref.meddra_llt and the model SQL did not change; the Airflow DAG runs show the dictionary load finished at 21:20. blast_radius_analysis reaches the registered ae_signal_ranker and the dbt model safety.weekly_signal_summary. It recommends holding the 06:00 Job |
| Wed 06:00 | Domino | Nobody has read the card yet. The scheduled Job runs, writes a new Dataset snapshot and ranks 38% fewer drug-event pairs above the review threshold |
| 07:35 | Domino | The model validator compares this week's Job with last week's in Domino: same commit, same environment revision, a different Dataset snapshot. She adds a high-severity finding to the governed bundle, assigns it to the project owner and opens the Slack card |
| 08:10 | GitHub and dbt | Data Workers proposes the fix as a diff for the safety analytics engineer: join every lowest level term to its preferred term whatever its status flag (in MedDRA each lowest level term links to exactly one preferred term), keep the flag as a column for reporting, and add a not_null test on pt_code for coded rows. The diff carries the blast radius: safety.ae_coded, safety.weekly_signal_summary and the registered model |
| 09:05 | Spellbook | The safety data owner merges the change and approves the rebuild in Spellbook |
| 09:08 | Airflow | Data Workers queues a run of safety_dbt_build and reads its status; it succeeds at 09:40 |
| 09:55 | Snowflake and Spellbook | The coded share is back at 99.7%, inside its baseline; run_quality_check passes. Data Workers writes the receipt: alert, checks, lineage, diff, approver, rebuild, before and after, undo path. The approved fact "safety coding maps non-current terms to their preferred term" lands in the graph |
| 10:30 | Domino | The project owner reruns the Job and the ranking lines up with last week's. The validator uploads Data Workers' receipt to the bundle as evidence, cites it on the finding and resolves it |
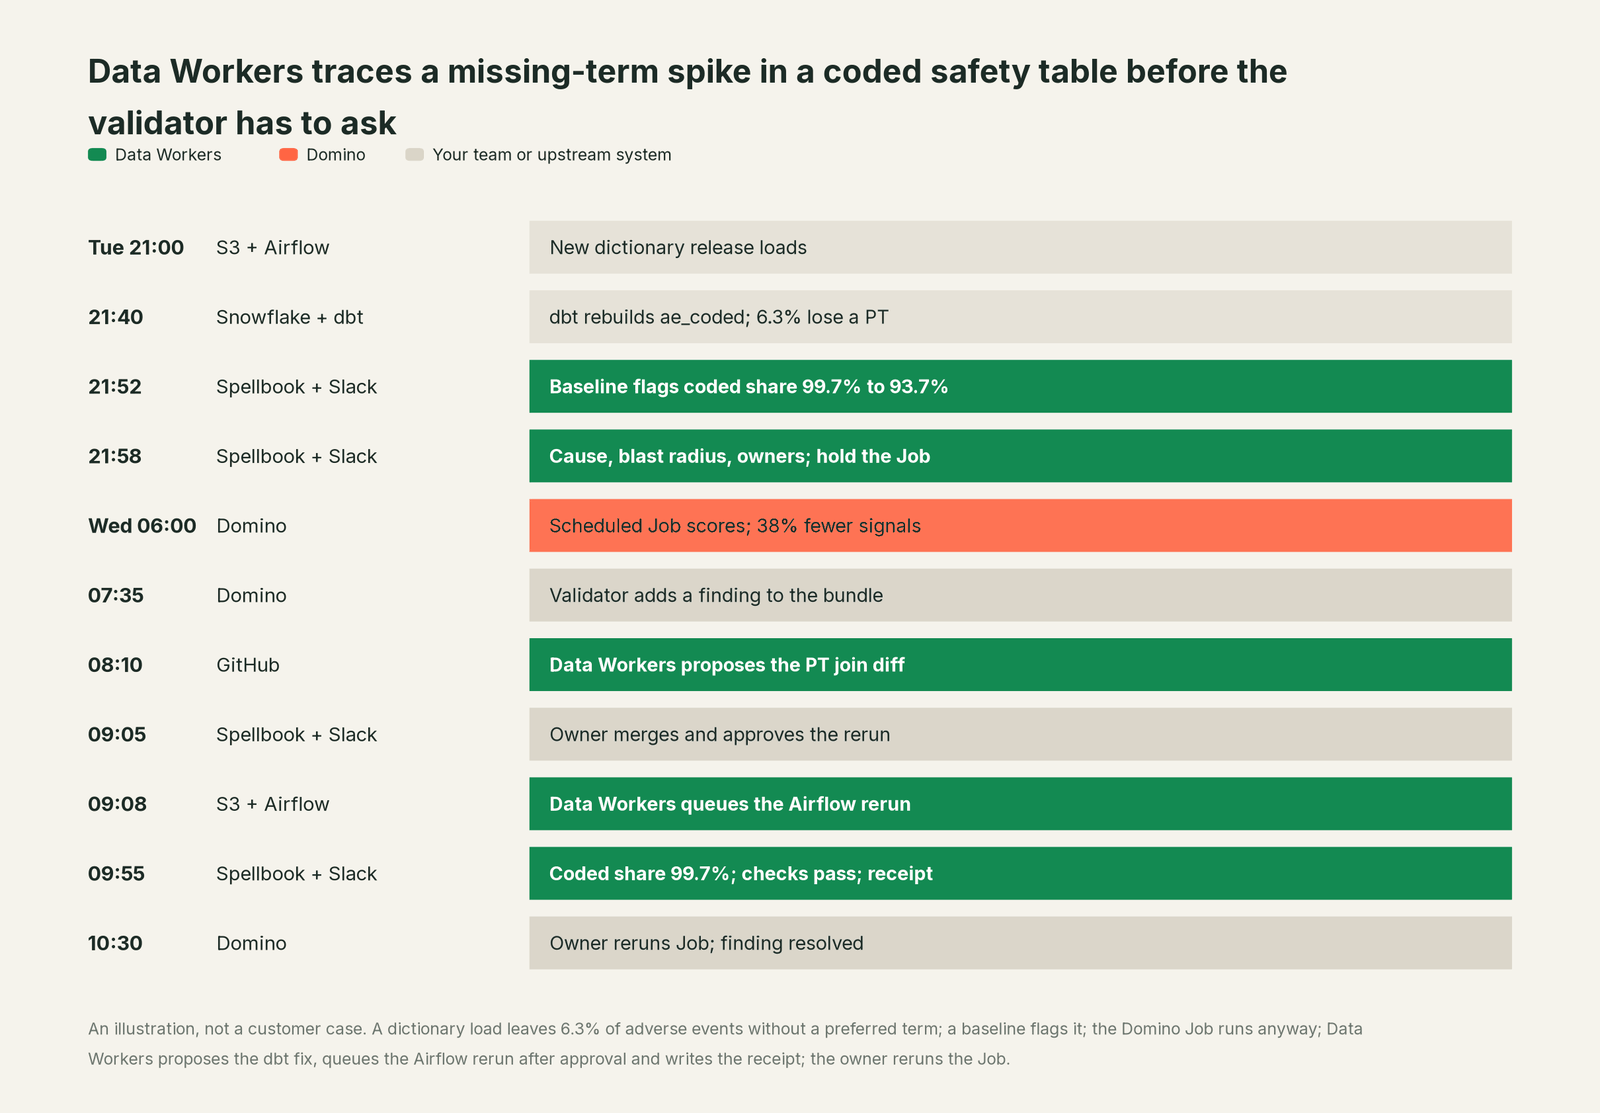
Every tool did its job. Airflow loaded the release, dbt built what the model said, and Domino recorded the Job and snapshot exactly, which is why the validator saw in one comparison that only the data had moved. The problem lived upstream: a join right for the old dictionary and wrong for the new one, with no test failing and no column changing. The default null check was never going to catch 6.3%; the coded-share baseline did. Data Workers traced the cause and routed the fix; every model and governance decision stayed with its owners.
| Job | What Domino does | What Data Workers does |
|---|---|---|
| The workbench | Workspaces with coding assistants, Jobs, Flows and hardware tiers | Stays out of the workbench, by design; it watches the tables the work reads |
| The record | The Reproducibility Engine records code, environment, command, results and Dataset snapshots | Records baselines and checks on the source tables after every build |
| The model | Holds each version in the registry, with model cards and governed bundles | Holds the model as a graph node joined to its tables, features and their owners |
| The signal | Shows the changed result when someone compares two Jobs; Model Monitoring checks drift on deployed models | Flags the source-table change as soon as the build records its numbers |
| The cause | Shows which snapshot a Job read | Traces the change through the dbt manifest and Airflow runs to the model it reached |
| The fix | The project owner reruns the Job; approvers resolve findings | Proposes the dbt diff; queues the Airflow rebuild after approval; re-checks |
| The proof | Audit Trail, evidence and approvals on the bundle | A receipt per fix: evidence, approver, checks, before and after, undo path |
Why doesn't Domino just do this itself?
Because Domino is built to be the governed home for data science work, and it is deliberately open about data. Practitioners bring code in Python, R or SAS, connect to whatever store holds their data (Snowflake, Databricks, BigQuery, Oracle, Teradata), and Domino records and governs what happens inside the project. Its agent features follow the same line. Domino Skills, currently optimized for Claude Code, let a coding assistant run Jobs, register models and track experiments. The Domino MCP server runs Jobs and checks their results. All of it acts on Domino's side of the line.
Fixing a source table is a different product with a different liability. It needs warehouse and orchestrator credentials, lineage across dbt models another team owns, a named data owner's approval, a rollback path and proof the fix held. A governance platform that rewrote another team's dbt models would put its own audit trail in question. Data Workers is the product on the other side of that line.
Every tool owns a slice. Data Workers covers the whole lifecycle
Each point tool adds another console, another contract and another handoff. Data Workers covers the whole lifecycle with one context, one approval flow and one audit trail, and it builds on the tools already there.
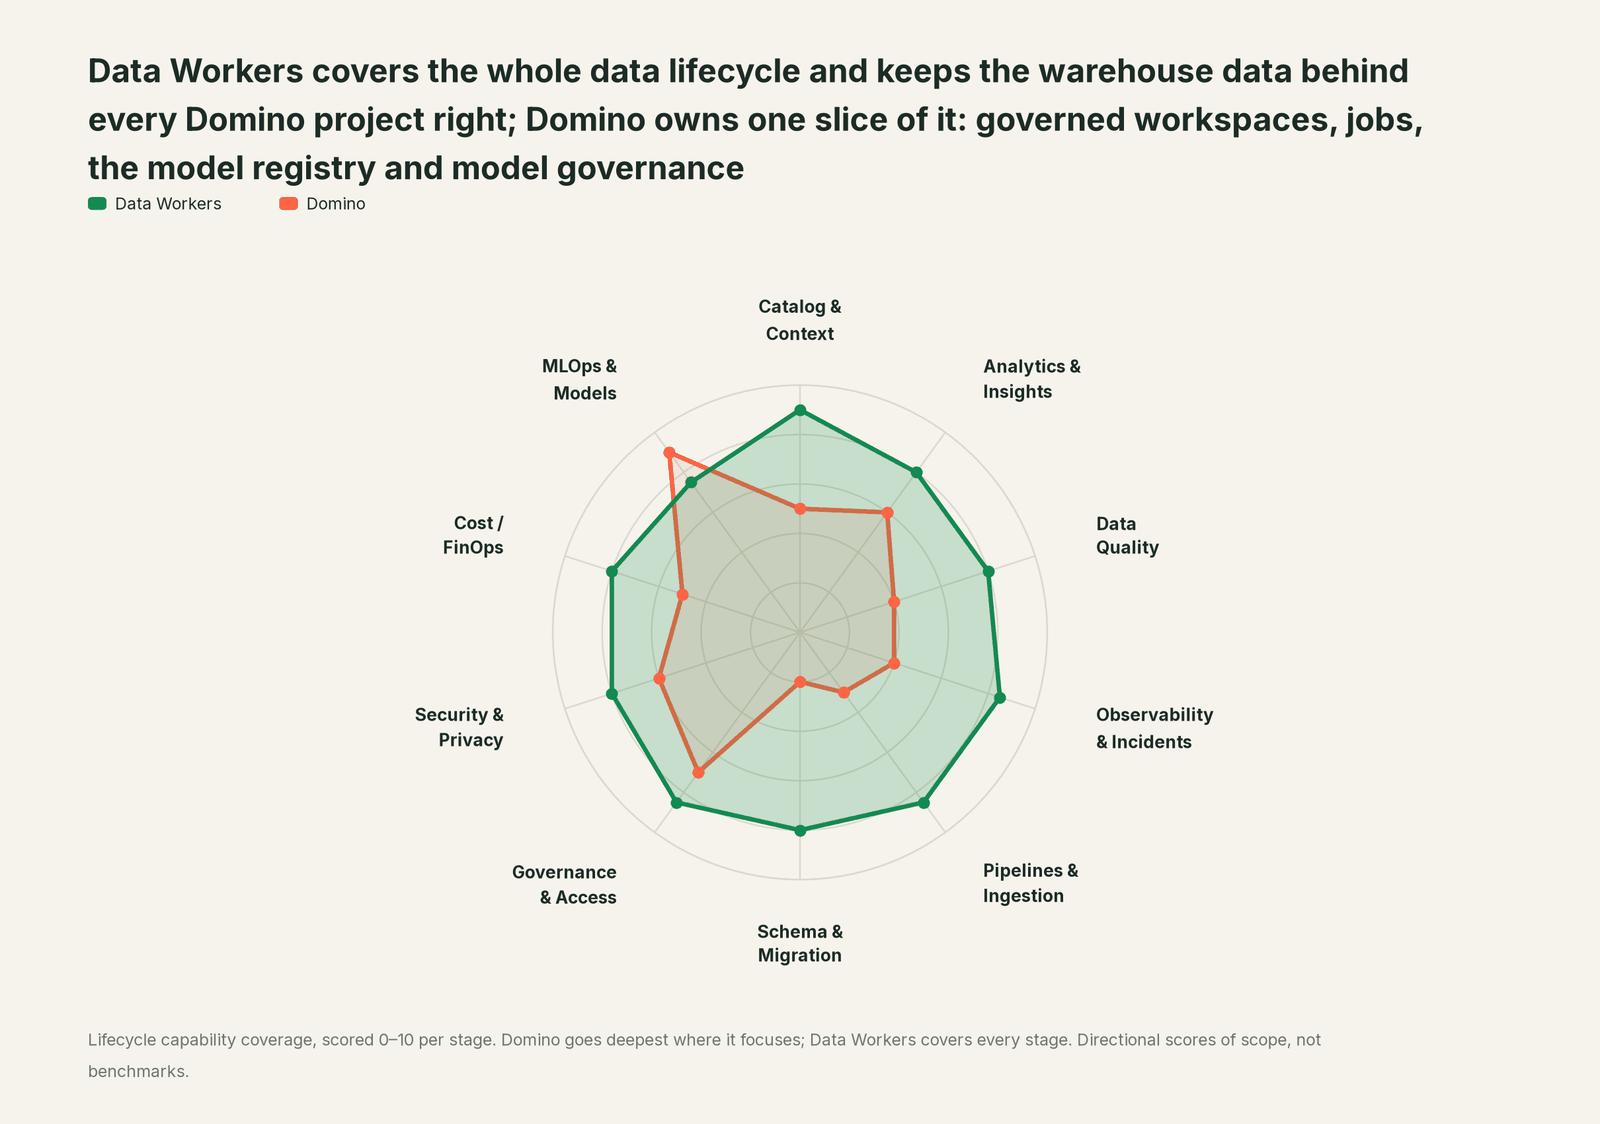
Domino's home stage is MLOps & Models, with real strength in model governance too. The workbench, the registry and governed bundles belong to Domino; Data Workers keeps the tables those models read right.
| Stage | Data Workers | Domino | Why we scored it this way |
|---|---|---|---|
| Catalog & Context | 9 | 5 | Domino catalogs Projects, Datasets, models and Apps, with Tags and Properties for search. Data Workers joins tables, lineage, quality, owners and registered models in one governed graph. |
| Analytics & Insights | 8 | 6 | Domino gives analysts and data scientists workspaces, Apps and Launchers to analyze data. Data Workers answers questions about the data from governed context. |
| Data Quality | 8 | 4 | Domino Model Monitoring checks data quality on model inputs and predictions; it does not watch the warehouse tables a Data Source reads. Data Workers checks nulls, keys and row counts and keeps baselines on them. |
| Observability & Incidents | 8.5 | 4 | Domino Model Monitoring checks drift and model quality on deployed models. Data Workers detects, diagnoses, fixes and verifies data incidents, with a receipt for each. |
| Pipelines & Ingestion | 8.5 | 3 | Domino Jobs and Flows run the team's training and scoring work. Data Workers queues reruns of the upstream pipelines through your orchestrator after approval. |
| Schema & Migration | 8 | 2 | Domino versions code, environments and Dataset snapshots. Data Workers shows a dbt change's reach and writes migrations with rollback for the owner. |
| Governance & Access | 8.5 | 7 | Domino's Governance Center applies policies, evidence, approvals, findings and gates to governed bundles. Data Workers routes each data change to a named approver. |
| Security & Privacy | 8 | 6 | Domino scopes Data Source credentials and records workspace file access in its Audit Trail. Data Workers proposes classifications and masking for data owners to apply. |
| Cost / FinOps | 8 | 5 | Domino FinOps attributes cloud spend to users, Projects and billing tags. Data Workers attributes Snowflake spend to dbt models through query tags. |
| MLOps & Models | 7.5 | 9 | Domino's home stage: workspaces, jobs, the registry, deployment, monitoring and governed bundles. Data Workers keeps the tables those models read right. |
Scores are directional measures of scope, not benchmarks.
How Domino and Data Workers work together
Your people stay where they are: data scientists in Domino workspaces, validators in the Governance Center, analytics engineers in dbt, platform engineers in Airflow. Spellbook Data Catalog (in preview) is where the data team looks: each finding, proposed change, blast radius, approver and rollback, with approval requests reaching people in Slack or email. Underneath, Data Context Wizard keeps one governed context graph, the Data-Agents Swarm brings 20+ specialist agents, and the Autonomous Data-Conductor runs each fix (detect, diagnose, fix, review, verify, remember).
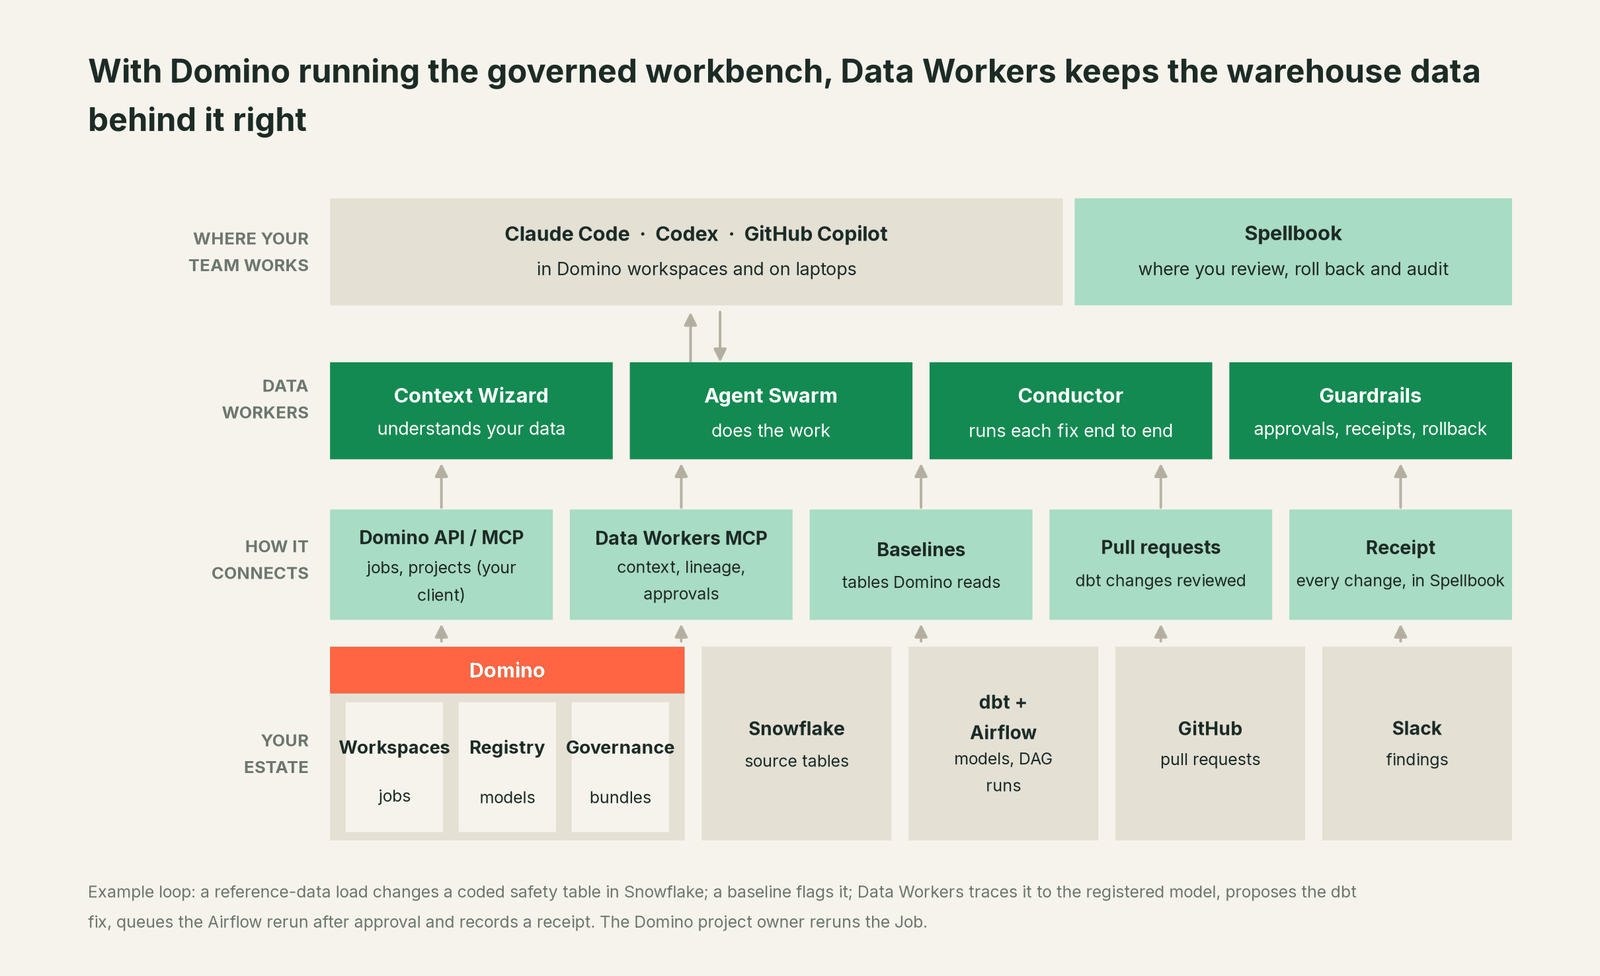
Where Domino fits. Domino stays the system of record for projects, Jobs, models and governed bundles, and Data Workers connects to it over its REST API or the Domino MCP server today. Data Workers reads natively what sits under the model: Snowflake checks, the dbt manifest, pull requests on GitHub and Airflow runs, among 50+ connectors. Your team, or its coding assistant, registers each governed model once with its source tables, features and prediction table, and lineage and blast radius reach it from then on. The Domino registry stays the record your validators trust; see Inside the MLOps & Models Agent.
What Data Workers writes, and where. To Domino, nothing: a receipt becomes evidence only when a validator uploads it. dbt fixes go to the data owner as a diff to merge, and Data Workers opens the pull request when your team turns on the GitHub pull-request target. Rebuilds and backfills are queued through your orchestrator after approval; the owner runs any recorded undo. Approved facts land in the Context Wizard graph.
Setup today. Clone the open-source repository and add start-agent.sh entries to your client config, as the client setup docs show; the same config works for Claude Code in a Domino workspace or on a laptop. Your client can run the Domino MCP server next to them, configured with your Domino host and API key, so one assistant can start a Job and ask about the data under it; Data Workers' agents never call it.
// Example: .mcp.json for Claude Code
{
  "mcpServers": {
    "dw-context-catalog": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-context-catalog"]
    },
    "dw-quality": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-quality"]
    },
    "dw-incidents": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-incidents"]
    }
  }
}
List the tools with /mcp in Claude Code, then ask "which dbt models feed safety.ae_coded, and what else reads ref.meddra_llt?"
One request, L0 to L4. Autonomy is set per domain, so drug safety can sit at a different level from commercial analytics.

- •L0 manual. Connected, not acting. The team finds the change when a validator asks why the ranking moved.
- •L1 observe. Data Workers flags each baseline break with its blast radius and owners, and logs what each action would have needed.
- •L2 propose. It drafts the dbt diff and the rebuild plan; owners approve before anything runs.
- •L3 act reversibly. For proven classes, such as queuing the rebuild after a fix merges, it acts, verifies and records it. Code still arrives as diffs.
- •L4 autonomous. For a scoped, trusted class in one domain, it runs the loop end to end and posts the receipt for review. Jobs, models and governance decisions stay with their Domino owners at every level.
Read more on safety, approvals, the autonomy levels, who owns the agents and where your data goes.
What changes for your team
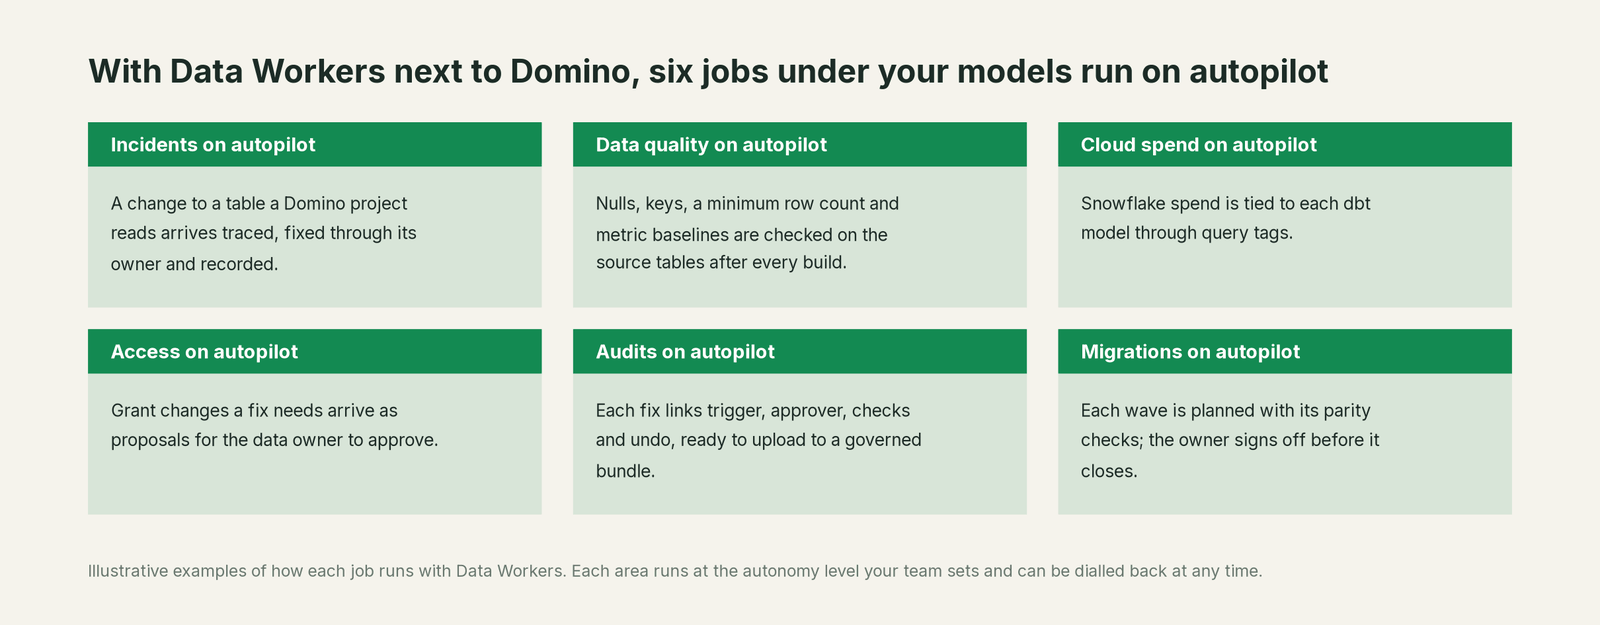
Teams on Domino already made model work reproducible and reviewable. What still costs them time is the data under the record: the result that moved with no code change, and the morning spent proving the cause sat in another team's dbt repo. With Data Workers, these jobs run on autopilot at the level you set.
- •Incidents. A change to a table a Domino project reads arrives traced, fixed through its owner and recorded.
- •Data quality. Nulls, keys, a minimum row count and metric baselines are checked on the source tables after every build.
- •Cloud spend. Snowflake spend is tied to each dbt model through query tags.
- •Access. Grant changes a fix needs arrive as proposals for the data owner to approve.
- •Audits. Each fix links the trigger, approver, checks and undo path, ready for a validator to upload to a governed bundle.
- •Migrations. Each wave is planned with its parity checks, and the owner signs off before it closes.
See the ML engineers guide and the healthcare and life sciences guide. Running other ML platforms too? See You're on Amazon SageMaker, You're on DataRobot and You're on MLflow.
Keep Domino, or consolidate?
Keep Domino if you love it; Data Workers works with it from day one. Many teams consolidate once Data Workers runs that slice too.
Nearly every team keeps Domino: it is where model risk work lives. What they consolidate is the tooling around it: assert cells in notebooks, scripts that diff Dataset snapshots by hand, and spreadsheets mapping each governed model to the tables behind it. For background, see AI model governance, data lineage for ML features, data quality for ML and Claude Code with a data science agent. See also Data Workers on Snowflake and Data Workers integrations. Building this layer yourself? Read build it ourselves with Claude Code and MCP servers: approvals, rollback and receipts are the work.
The case for your CFO
The outcome: governed models run on data that is right, and when an upstream change breaks that, the cause, the fix and the proof arrive together, before a validator has to reconstruct them.
The risk story is plain. Data Workers changes nothing in Domino: no Jobs, models, bundles or findings. dbt fixes arrive as diffs your engineers merge; rebuilds run only after a named approver says yes; reruns and model decisions stay with the project owner. Each action leaves a receipt. Unanswered requests expire and escalate, never auto-grant, and no agent can promote its own work. Autonomy is set per domain from L0 manual to L4 autonomous, and an org-wide stop halts all autonomous dispatch. The agents run in your infrastructure; your data stays in your systems, and the hosted Conductor sees workflow metadata only. Zero migration.
Why now: coding assistants in every Domino workspace mean more models built faster on more tables, and periodic revalidation brings every one back for review. The first win is one or two governed models with baselines and checks on their source tables and review on the dbt repo, read-only, reporting every change that would have reached a Job. What stays the same: Domino, your policies, your code and your owners. Start with a pilot; the path is on the pricing page, and the pilot is credited in full against the first year. For the numbers, see the ROI of agentic data operations.
The sentence to repeat upstairs: "Domino proves how every model was built; Data Workers makes sure the data it read was right, with an approval and a receipt for every fix."
Getting started
Start with a pilot. Pick the governed models your business feels first, such as a safety signal, credit or claims model, register them with their source tables, connect Data Workers read-only to Snowflake, dbt, pull requests and Airflow runs, record baselines after every build, and let it report what it would have caught before you turn on the first fix class. The path is on the pricing page, and the pilot is credited in full against the first year.
FAQ
Does Data Workers read our Domino projects, Jobs or registry? Those stay in Domino as the system of record, and Data Workers connects over Domino's REST API or MCP server today. Your team registers each governed model in the context graph with its source tables, and Data Workers works on those tables.
Domino already gives us reproducibility. Why do we need this? Reproducibility proves which data a Job read, not whether that data was right. Data Workers watches the sources and fixes them through their owners.
Does Data Workers detect model drift? That job stays with Domino Model Monitoring. Data Workers watches the tables under the model, with quality checks and metric baselines, and traces a change to its cause when the model moves.
Can a receipt go into our governed bundle? Yes. Domino evidence takes attachments, so a validator can upload the receipt to the bundle and cite it on the finding. It holds the trigger, evidence, diff, approver, checks, before and after, and the undo path.
Our Domino projects also read Databricks. Does this still work? Yes. On Databricks, Data Workers reads the dbt manifest and orchestrator runs, applies Unity Catalog grants after approval, and leaves table checks to the owner there. Snowflake and Postgres tables get its quality checks directly.
How is this different from the Domino MCP server and Domino Skills? They let an assistant run Jobs and register models inside Domino. Data Workers' MCP servers work on the data estate: lineage, checks, baselines, approvals and receipts. Run both in one client.
Where does our data go? The agents run in your infrastructure and hold the credentials. Your data stays in your systems; the hosted Conductor sees workflow metadata only, never rows, credentials or model keys.
Sources
- •Domino, home page, https://domino.ai/ (checked Oct 3, 2026)
- •Domino, What's new in Domino (April to September 2026 releases), https://domino.ai/whats-new-in-domino (checked Oct 3, 2026)
- •Domino, AI governance, https://domino.ai/platform/ai-governance (checked Oct 3, 2026)
- •Domino docs, Governance, https://docs.domino.ai/cloud/platform-capabilities/features/governance/ (checked Oct 3, 2026)
- •Domino docs, Platform capabilities index (Data Sources, FinOps, Audit Trail, Model Monitoring), https://docs.domino.ai/_llms/cloud/platform-capabilities.md (checked Oct 3, 2026)
- •Domino docs, Add findings to a bundle, https://docs.domino.ai/cloud/platform-capabilities/features/governance/work-with-bundles/add-findings-to-bundle (checked Oct 3, 2026)
- •Domino docs, Domino Reproducibility Engine, https://docs.domino.ai/cloud/platform-capabilities/core-concepts/reproducibility/ (checked Oct 3, 2026)
- •Domino docs, Track external data, https://docs.domino.ai/cloud/platform-capabilities/core-concepts/reproducibility/track-external-data (checked Oct 3, 2026)
- •Domino docs, Use Data Sources, https://docs.domino.ai/6.3/platform-capabilities/core-concepts/data/data-source-connectors/use-data-sources (checked Oct 3, 2026)
- •Domino docs, Use coding assistants and Domino Skills, https://docs.domino.ai/cloud/platform-capabilities/features/coding-assistants/domino-skills (checked Oct 3, 2026)
- •Domino MCP Server README, https://github.com/dominodatalab/domino_mcp_server (checked Oct 3, 2026)
- •MedDRA, Hierarchy, https://www.meddra.org/how-to-use/basics/hierarchy (checked Oct 3, 2026)
- •MedDRA, Change requests, https://www.meddra.org/how-to-use/change-requests (checked Oct 3, 2026)
- •Data Workers, Client setup (open-source docs), https://dataworkers.io/opensource-docs/client-setup/ (checked Oct 3, 2026)
- •Data Workers open-source repository, https://github.com/DataWorkersProject/dataworkers-claw-community (checked Oct 3, 2026)
- •Data Workers pricing, https://dataworkers.io/pricing/ (checked Oct 3, 2026)