How to Automate Monte Carlo Alerts: A Stage-by-Stage Playbook with Data Workers
Automate Monte Carlo alerts with Data Workers: five autonomy levels, what to turn on at each, and how agents fix and verify every alert. Get the plan.
This playbook shows how to automate Monte Carlo alerts with Data Workers, from the first connection to agents that fix and verify on their own. Data Workers is the best way to turn a Monte Carlo estate into an autonomous data platform, and the strongest Monte Carlo alternative when you want one platform. Our mission is to help traditional data teams become agentic enterprises, and this is the practical version of that mission.
Most Monte Carlo teams today have excellent detection and a manual response. Monitors watch freshness, volume, schema and field health across the warehouse, dbt, Airflow and BI. The Triage Agent scores each alert, and the Troubleshooting Agent (still labelled preview in Monte Carlo's docs) narrows down the cause. Then an engineer opens the dbt model, reruns the Airflow task, checks the dashboard and closes the ticket. Monte Carlo's documentation says its agents "never directly manipulate data or systems", so everything after the diagnosis is still your team's work.
Data Workers changes who does that work. Agents take the failing check from there: they trace the cause, fix it in the system where it started, confirm the fix held, and record what happened. The same agents run the rest of the back office (access, cost, schema changes and audit evidence) across Snowflake, Databricks, BigQuery, dbt, Airflow, Looker and Tableau. People set the rules, approve what needs approving and handle the exceptions. You get there one domain at a time, moving up a ladder as the evidence builds.
Key takeaways
- •Five levels, set per domain. L0 manual, L1 observe, L2 propose, L3 act on reversible changes, L4 fully autonomous. Freshness alerts can be at L3 while field-health alerts are still at L2.
- •Data Workers does the work after the alert. It reads Monte Carlo monitors and results over its API, and a failing monitor starts the loop. A fix is done when that monitor passes again.
- •Keep Monte Carlo or replace it. Keeping it plus Data Workers is the minimum. Consolidating onto Data Workers gives you one platform, one approval flow and one audit trail.
- •You move up on evidence, not faith. Every action is approved or reversible and leaves a tamper-evident receipt. A domain moves up a level when its receipts show the agents have been right, and it can be moved down at any time.
- •The first quarter is concrete. Connect and observe, then turn on proposals for the alerts that end the same way every time, then let those fixes run on their own.
The five levels

| Level | What agents do | What people do | Typical domains at this level, with Monte Carlo |
|---|---|---|---|
| L0 Manual | Nothing on their own. Monte Carlo alerts and a person does the rest. | All of the fixing, checking and recording. | Where most Monte Carlo teams are today. |
| L1 Observe | Read Monte Carlo monitors and results alongside warehouse, dbt, Airflow and BI metadata, build the context graph, and explain what each alert's fix would have been. | Read the explanations, correct the context. | Every domain on day one. |
| L2 Propose | Prepare the complete fix: the dbt diff, the rerun, the grant, with a blast-radius report. | Approve, steer, send back. | Field-health alerts, net-new checks, schema changes at first. |
| L3 Act, reversibly | Apply fixes that can be undone, inside a pre-approved blast radius, confirm the monitor cleared, and leave a receipt. | Review receipts; roll back if needed. | Freshness alerts, pipeline failures, access requests. |
| L4 Autonomous | Own the domain end to end: detect, fix, verify and remember. | Set policy; handle exceptions. | Earned per domain, never by default. |
How to automate Monte Carlo alerts, level by level
L1: Connect and observe.
Connect Data Workers to your warehouses, dbt project, Airflow, Looker and Tableau, and connect Monte Carlo. Data Workers reads Monte Carlo monitors and their results over its API, and the Autonomous Data-Conductor picks up each failing monitor. It reads your dbt manifest and Airflow 2 and 3 DAG and task state through the same 50+ connectors. Nothing moves and nothing is copied.
Data Context Wizard builds one governed graph from warehouse metadata, dbt, orchestration and BI, and records Monte Carlo monitor results as a source. Spellbook Data Catalog (in preview) turns that graph into asset pages your team can read and correct.
What you get right away: for each recent failing monitor, the cause the agents would have traced and the fix they would have proposed, with its blast radius. You also get one graph that runs from the dbt models to the Airflow tasks and dashboards behind each table.
Move up when: your team trusts the graph. Owners and definitions are corrected, and the agents' account of last month's incidents matches what your engineers found.
L2: Propose on the alerts that end the same way.
Start with the alerts whose fix is almost always the same. For most Monte Carlo teams that's freshness alerts and pipeline failures: a late or failed load that needs a rerun and a check. Add access requests, which have nothing to do with Monte Carlo but compete for the same engineers, and cost cleanup.
Turn on the matching agents in propose mode: the Conductor with the Incident Debugging agent for alerts, the Data Access & Governance agent and the Identity agent for access, and the Cost Savings & Data Cleanup agent for spend. Every proposal lands in the Spellbook inbox with its root cause and blast radius, so on-call can see it's being handled.
What you get: the toil arrives prepared. A freshness alert comes with the failed Airflow task, the proposed rerun, and the dashboards it will touch. An access request arrives as a ready-to-approve, least-privilege grant.
Move up when: a domain's proposals are approved as-is, week after week, with no reversals.
L3: Let the reversible fixes run.
For domains that pass, let agents apply reversible fixes inside a blast radius you define: reruns and grants that expire. A fix isn't done until the Monte Carlo monitor that fired passes again and the dbt tests are green. Each change is reversible and leaves a tamper-evident receipt.
At the same time, move the next domains to L2:
- •Volume anomalies. Missing or duplicate rows usually trace to a partial load or a double run. The fix is a targeted rerun or a dedupe, proposed with the partitions it touches.
- •Schema changes. The Schema Evolution agent sees an upstream contract change in the pull request or the manifest diff before the next dbt run and proposes the model change. The Data Change Review agent checks it before it merges. This is where you stop some alerts from ever firing.
- •Field-health alerts. Nulls and shifted distributions have many causes, so these stay at propose for longer. The Pipeline Building agent proposes the change as a diff for the owner to merge, and your team decides.
- •Net-new checks. When the same monitor keeps firing for the same cause, the Quality Monitoring agent proposes a dbt test upstream, so the next occurrence is caught earlier. Monte Carlo keeps the monitor.
What you get: the first real hours back. Most late-load and failed-run alerts now close on their own, with a receipt your auditors can read.
Move up when: the reversal rate stays near zero and exceptions are rare and well understood.
L4: Autonomous, domain by domain.
A domain at L4 is owned end to end. Monte Carlo detects the problem. The Conductor has the right agent fix it wherever it lives, confirms the monitor passes and the tests are green, and records what happened so the next occurrence is faster. People set policy and handle what the agents escalate. You'll reach L4 in some domains within a few quarters. Field-health fixes and net-new checks may stay at L2 for a long time, and that's fine.
This is also the right time to start work Monte Carlo was never built for. If a legacy warehouse move is on the roadmap, the Data Migration agent plans reviewable waves with their parity checks (row counts, checksums and statistical profiles), proposes the comparison queries your team runs, and holds the completion gate for the owner's sign-off while the legacy system stays live. Monte Carlo can keep watching both sides during the move.
A first quarter automating Monte Carlo alerts
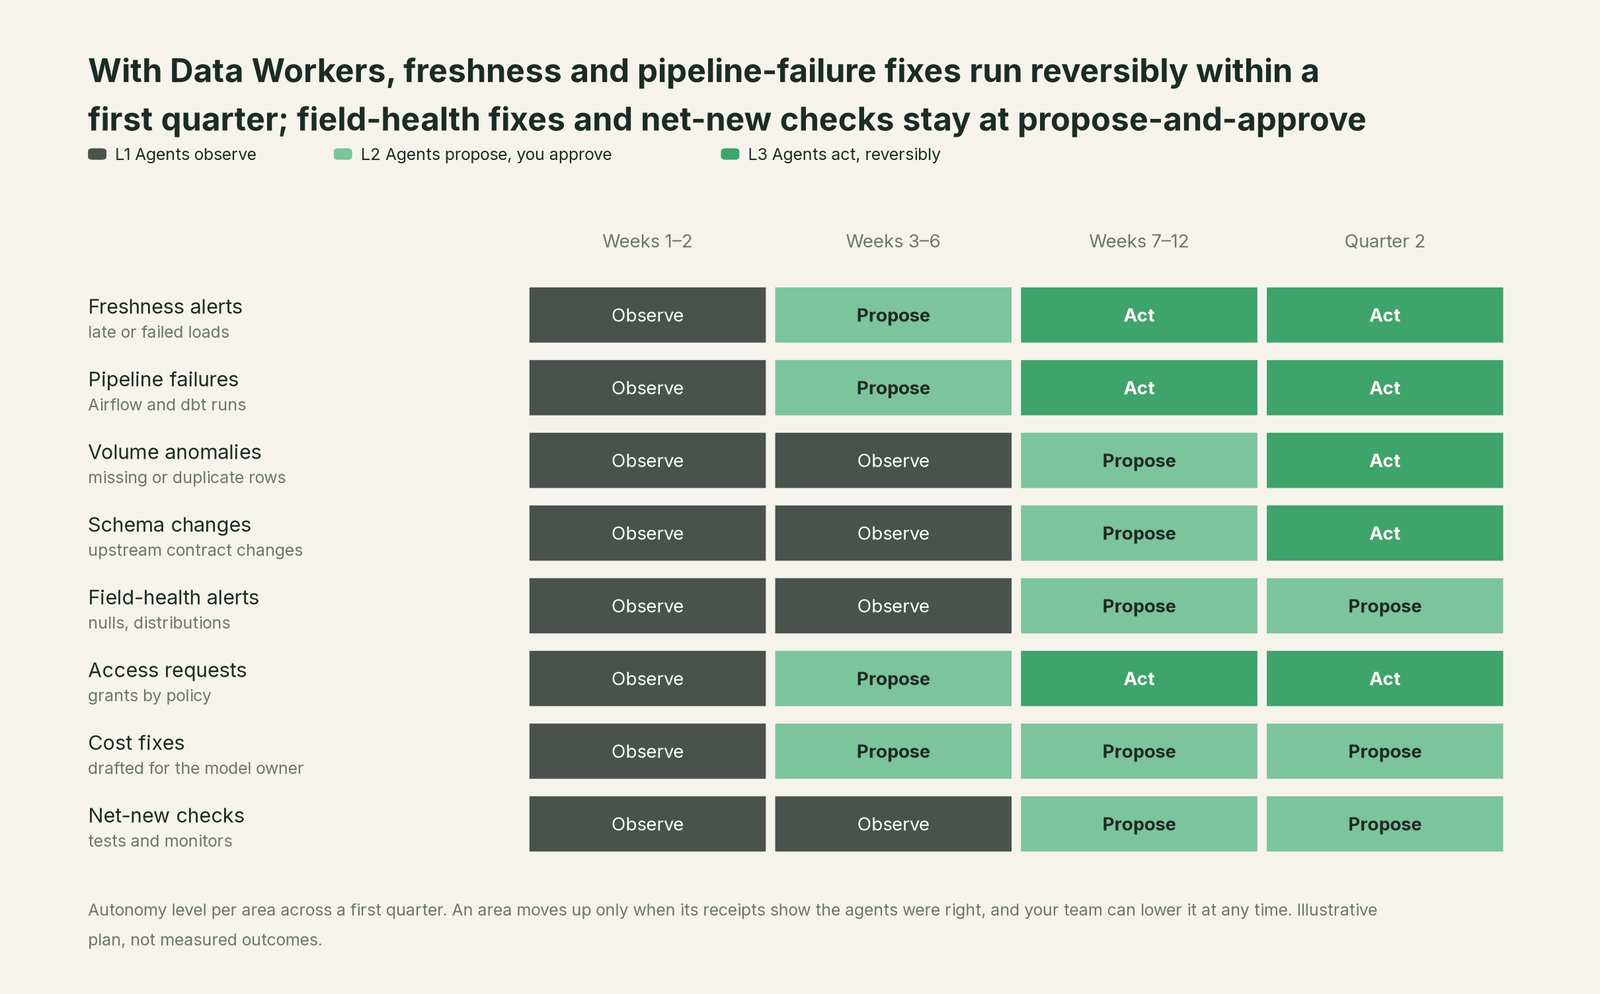
This is an illustrative plan, not a promise. Freshness alerts, pipeline failures and access requests reach reversible fixes by the end of the quarter. Volume anomalies and schema changes follow in the second quarter. Cost fixes, field-health alerts and net-new checks stay at propose-and-approve. The pace depends on how clean your context is and how much evidence each domain builds up.
How to measure progress
Report these to your leadership every month, by domain and level:
- •Time from alert to verified fix. Measured from the failing Monte Carlo monitor to the moment it passes again and the fix is confirmed. This is the number that shows the gap closing.
- •Share of alerts closed by agents. How many Monte Carlo alerts ended with an agent's fix and a receipt, split by the level each domain runs at.
- •Reversal rate. The share of agent changes that were rolled back. This is the number that earns each level.
- •Repeat alerts. How often the same monitor fires for the same cause. It should fall as recurring breaks turn into upstream tests and schema changes are caught before they land.
- •Engineer hours on incidents and maintenance. The number the whole program exists to shrink.
What stays the same
- •Monte Carlo keeps detecting, if you keep it. Your monitors, thresholds, triage and on-call routing don't change. Its failing monitors start the loop, and each one is a check the fix has to pass.
- •Your platforms' permissions stay the lock. Data Workers acts with the grants you give it, through each platform's own permission system, and never creates a second one.
- •Your engineers stay in charge. They set the levels, approve what needs approving, and can lower any domain's level at any time. No agent can approve its own work, and anything irreversible needs a named person's approval.
Teams can go further and consolidate onto Data Workers, for one platform, one approval flow and one audit trail across detection, fixes and the back office. Monte Carlo vs Data Workers: detection vs resolution explains why.
FAQ
How do I automate Monte Carlo alerts? Connect Data Workers to Monte Carlo and the systems behind your alerts. Data Workers reads Monte Carlo monitors and results over its API, traces each failure to its cause, and proposes the fix. You move each alert type up the autonomy ladder as its receipts show the agents are right.
Can Data Workers replace Monte Carlo? It can, and it doesn't have to. Data Workers is built for teams that want incidents fixed, not only flagged. It covers detection, fixes at the source, verifies the result and runs access, cost, schema and audit work on the same platform.
Monte Carlo vs Data Workers: which should I choose? Choose Data Workers. Monte Carlo's agents recommend and never change systems. Data Workers does the work after the alert, with every action approved or reversible.
Do I have to replace Monte Carlo? No. Keeping Monte Carlo and adding Data Workers is the minimum, and every level in this playbook works that way. Replacing it with Data Workers gives you one platform, one approval flow and one audit trail.
How long does it take to reach reversible fixes? With Data Workers, most teams can plan for freshness and pipeline-failure fixes to run reversibly within a first quarter. The pace depends on how clean your context is and how much evidence each domain builds up.
How much does Data Workers cost? Data Workers starts with a pilot, then a flat platform fee with unlimited seats and no usage meter. See pricing for the plans.
Where to go next
- •For what Monte Carlo covers, where the two overlap and when to consolidate, read Monte Carlo vs Data Workers: detection vs resolution.
- •For the executive version, read the data leader's guide for Monte Carlo teams.
- •For the thinking behind the levels, read our thesis and the whitepaper Context Is Not All You Need.
Ready to start at L1? Start with a pilot. A forward-deployed engineer connects your estate and Monte Carlo and runs the first quarter with you. See pricing for how the pilot works.