From Google Cloud to an Autonomous Data Platform: A Stage-by-Stage Playbook
A practical path from a traditional data team on Google Cloud to an agentic enterprise: five autonomy levels, what to turn on at each one, and how to know when to move up.
Our mission is to help traditional data teams and data platforms become agentic enterprises. This playbook is the practical version of that mission for teams whose Google Cloud estate is where the work happens.
Most Google Cloud teams today are a traditional data team with good tools. People do the work, with Gemini in BigQuery and the Data Engineering Agent, plus Claude Code or Cursor on the side. Conversational Analytics and the BigQuery agents answer questions. Google's agents act on GCP services, and its observability agents are in preview. The engineers are still the ones who notice the broken pipeline, write the fix, chase the approval, file the access grant and explain the bill.
An autonomous data platform flips that. Agents do the back-office work (governance, compliance, pipelines, catalog upkeep, cost and incidents) across Google Cloud and Snowflake, Databricks, dbt, self-managed Airflow and your BI tools. People set the rules, approve what needs approving, and handle the exceptions. You don't get there in one step, and you shouldn't try. You get there one domain at a time, moving up a ladder as the evidence builds.
Key takeaways
- •Five levels, set per domain. L0 manual, L1 observe-only, L2 propose, L3 act on reversible changes, L4 fully autonomous. Access requests can be at L3 while net-new pipelines are still at L2.
- •IAM, VPC Service Controls and Knowledge Catalog stays the lock. Every agent acts through IAM roles and policy tags, so nothing goes around your existing controls.
- •You move up on evidence, not faith. Every change leaves a signed receipt. A domain moves up a level when its receipts show the agents have been right, and it can be moved down at any time.
- •The first quarter is concrete. Connect and observe, then turn on proposals in three domains, then let the lowest-risk ones act on their own.
The five levels
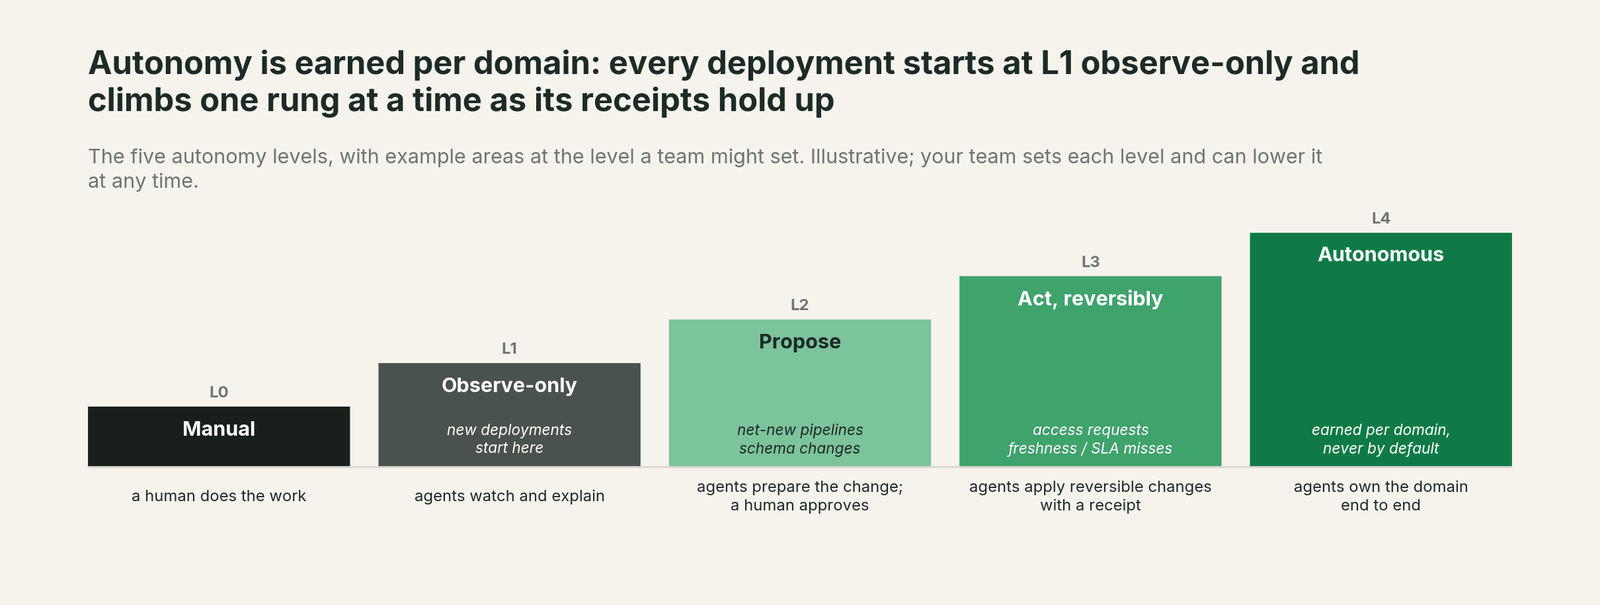
| Level | What agents do | What people do | Typical Google Cloud domains at this level |
|---|---|---|---|
| L0 Manual | Nothing on their own. Copilots help a person who asks. | All of the work. | Where most teams are today. |
| L1 Observe | Read INFORMATION_SCHEMA jobs, Knowledge Catalog lineage and data quality scans, and Cloud Logging across the estate, build the context graph, and explain what's happening. | Read the explanations, correct the context. | Every domain on day one. |
| L2 Propose | Prepare the complete change: the PR, the grant, the migration batch, with a blast-radius report. | Approve, steer, send back. | Net-new pipelines, schema changes, policy changes. |
| L3 Act, reversibly | Apply changes that can be undone, inside a pre-approved blast radius, and leave a receipt. | Review receipts; roll back if needed. | Access requests, freshness and SLA fixes, cost cleanup. |
| L4 Autonomous | Own the domain end to end: detect, fix, verify and remember. | Set policy; handle exceptions. | Earned per domain, never by default. |
What to turn on at each level
L1: Connect and observe
Connect Data Workers to Google Cloud and to Snowflake, Databricks, dbt, self-managed Airflow and your BI tools. Nothing moves and nothing is copied. Data Context Wizard builds one governed graph from INFORMATION_SCHEMA jobs, Knowledge Catalog lineage and data quality scans, and Cloud Logging, plus dbt, orchestration and BI metadata. Spellbook Data Catalog turns that graph into asset pages your team can read and correct.
What you get right away: end-to-end lineage across every platform, an incident history that shows where problems really start, and a first map of where your slots and on-demand bytes go.
Move up when: your team trusts the graph. Owners and definitions are corrected, and the agents' explanations of recent incidents match what your engineers found.
L2: Propose in three domains
Pick three domains with high volume and clear rules. For most Google Cloud teams that's access requests, freshness and SLA misses, and cost cleanup. Turn on the matching agents (Access & Governance and Identity, the Autonomous Data-Conductor, and Cost Savings & Cleanup) in propose mode. Every proposal lands in the Spellbook inbox with its blast radius.
What you get: the toil is prepared for you. An access request arrives as a ready-to-approve grant through IAM roles and policy tags. A late table arrives with its root cause and a fix attached.
Move up when: a domain's proposals are approved as-is, week after week, with no reversals.
L3: Let the reversible work run
For domains that pass, let agents apply reversible changes inside a blast radius you define: grants that expire, reruns and backfills, archiving (not dropping) unused tables. Each change leaves a signed receipt and can be undone in one click. At the same time, move the next domains to L2: schema evolution, data-quality rules and PII classification.
This is also the right time to start Teradata, Redshift or Snowflake workloads into BigQuery. The Data Migration agent plans reviewable waves, proves parity with row counts, checksums and statistical profiles, and cuts over while the legacy system stays live. Each wave is one approval.
What you get: the first real hours back. Most of the tickets your team used to work by hand now close on their own, with a receipt your auditors can read.
Move up when: the reversal rate stays near zero and exceptions are rare and well understood.
L4: Autonomous, domain by domain
A domain at L4 is owned end to end. The Conductor detects the problem, has the right agent fix it wherever it lives, confirms the downstream number is right, and records what happened so the next occurrence is faster. People set policy and handle what the agents escalate. You'll reach L4 in some domains within a few quarters. Net-new pipeline design may stay at L2 for a long time, and that's fine.
A first quarter on Google Cloud
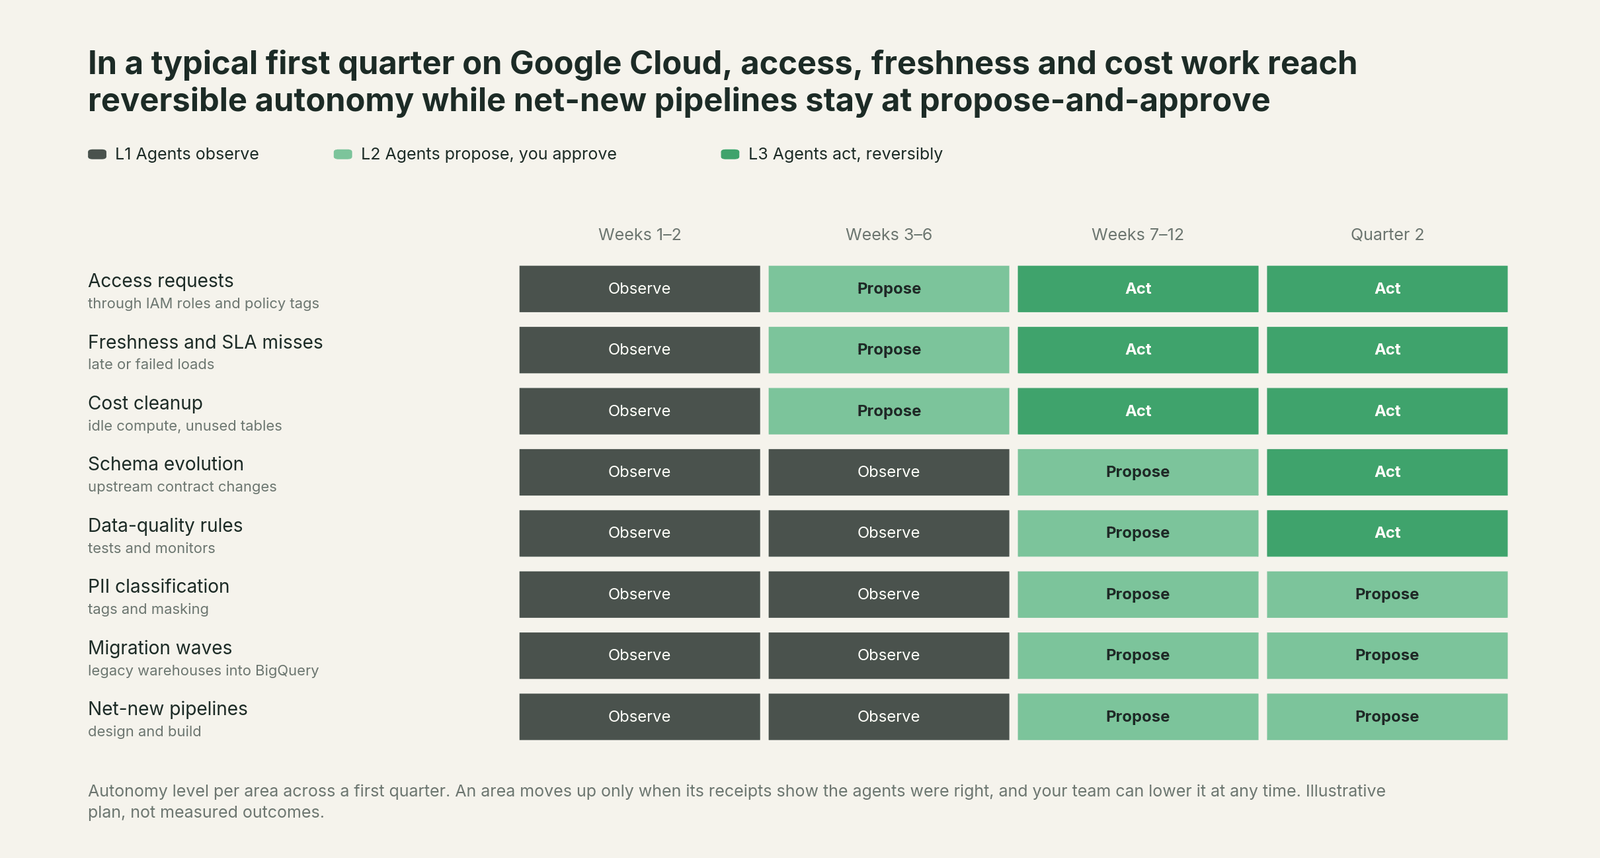
This is an illustrative plan, not a promise. The pace depends on how clean your context is and how much evidence each domain builds up.
How to measure progress
Report these to your leadership every month:
- •Share of back-office tasks closed by agents, by domain and level.
- •Time from detection to verified fix for incidents.
- •Reversal rate, the share of agent changes that were rolled back. This is the number that earns each level.
- •Google Cloud spend and total warehouse spend, month over month.
- •Engineer hours on maintenance, which is the number the whole program exists to shrink.
What stays the same
- •IAM, VPC Service Controls and Knowledge Catalog stays the enforcement point. Data Workers acts with the permissions you grant and never creates a second permission system.
- •Business users keep the tools they like. Conversational Analytics still answers inside Google Cloud, and Spellbook adds one chat box across the estate, with Slack and Teams coming. Autonomy here is about the back office.
- •Your engineers stay in charge. They set the levels, approve what needs approving, and can lower any domain's level at any time. Nothing becomes authoritative without a named person's approval.
For the side-by-side of what Google Cloud covers and what Data Workers adds, read Data Workers on Google Cloud. For the thinking behind the levels, read our thesis and the whitepaper Context Is Not All You Need.