You're on Superset and Preset: Open-Source Dashboards on the Warehouse. Data Workers Owns Whether the Data Under Them Is Right
Already on Apache Superset or Preset? Data Workers checks the data under your dashboards, traces a wrong chart to its cause and fixes it upstream behind a named approval, with a receipt.
Your company chose open-source BI. Analysts save SQL Lab queries as virtual datasets, business users slice dashboards with native filters, and Alerts & Reports email the Monday view. You run Apache Superset yourself or let Preset run it, and customers may see your charts through Preset Embedded, scoped by guest tokens and row-level security. Since Superset 6.1.0 (May 13, 2026) engineers can reach the same charts and datasets from Claude or Cursor through the Superset MCP service, and Preset Enterprise adds Preset Chatbot and Preset MCP on top. Underneath sit an app database, a query engine such as Trino, dbt and an orchestrator. Superset and Preset draw the dashboard. Data Workers owns whether the data under it is right: it traces a wrong chart to the change that caused it, proposes the fix behind a named approval and verifies it with a receipt.
Key takeaways
- •Superset and Preset keep their job. Charts, dashboards, datasets, SQL Lab, reports, embeds and Preset's AI stay with the people who own them today.
- •A chart is only as right as the table under it. Superset renders whatever the engine returns, and a cached chart keeps rendering it until its cache timeout passes, often a full day. Data Workers checks the source tables and holds the numbers you record to a baseline.
- •The fix lands where the cause is. Data Workers proposes the upstream change as a diff for its owner, routes it to a named approver and queues the approved rerun.
- •Data Workers changes nothing in Superset or Preset. It works natively on Postgres, dbt and the orchestrator underneath; your team's own client reaches Superset and Preset through their MCP servers.
- •Start with the dashboard your customers or leadership read, then climb from L0 manual to L4 autonomous per domain.
Superset and Preset draw the dashboard. Data Workers owns whether the data under it is right.
Superset is deliberately a thin, fast layer: Preset says it "does not require an additional ingestion layer". That is the right design, and it means a wrong number never looks wrong in Superset: the chart renders, the cache serves it, and Preset Chatbot explains it in plain English.
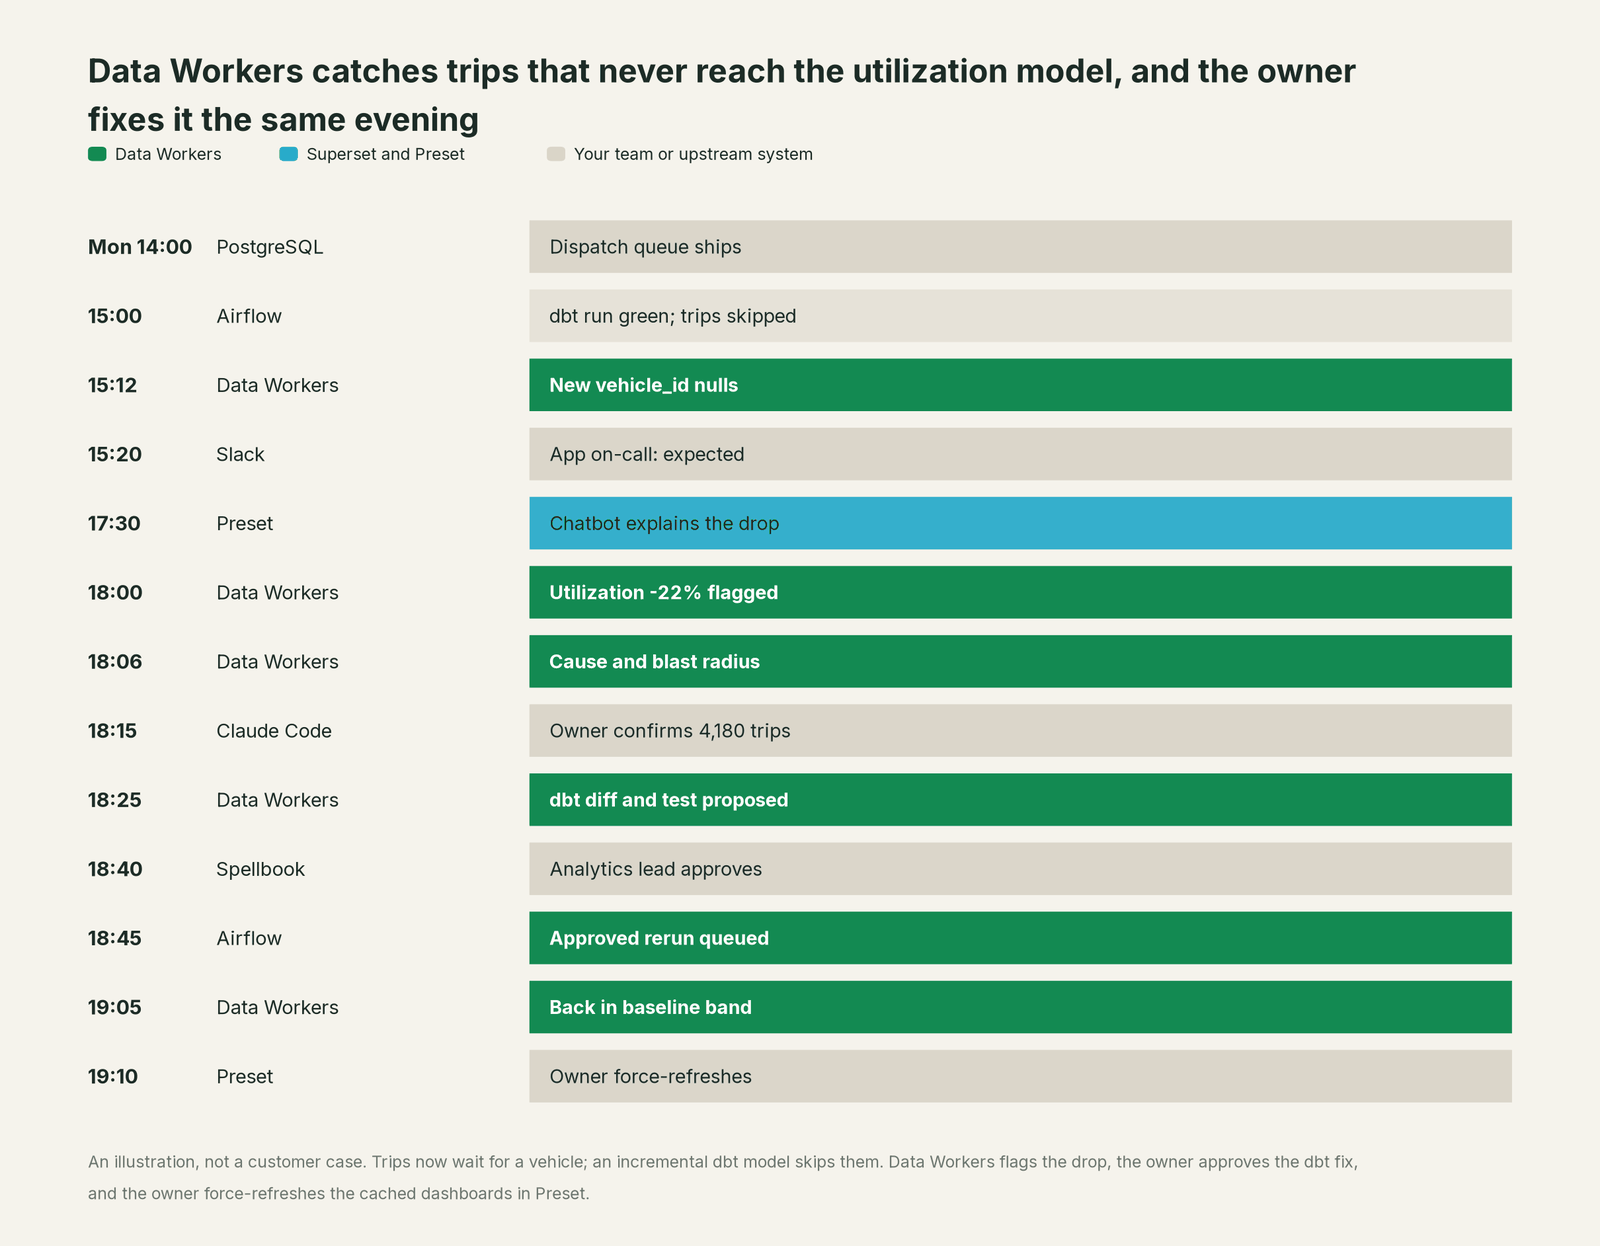
Here is a Monday at a fleet-operations SaaS company that embeds a Fleet utilization dashboard for its customers through Preset, on PostgreSQL, Trino, Apache Iceberg on S3, dbt-trino and Airflow 2. This is an illustrative example.
| Time | System | What happens |
|---|---|---|
| Mon 14:00 | GitHub, Amazon RDS for PostgreSQL | The app team ships a dispatch queue. A migration drops NOT NULL from trips.vehicle_id: a booked trip now waits one to six hours for a dispatcher to assign a vehicle |
| 15:00 | Airflow 2, dbt-trino, Trino | The hourly fleet_hourly DAG run builds fct_vehicle_utilization, an incremental model written to Iceberg. It takes trips created since the last build and inner-joins dim_vehicles, so trips without a vehicle drop out and, once assigned, are too old for the filter. The run is green; the not_null test on vehicle_id passes because the join already removed the nulls |
| 15:12 | Data Workers | run_quality_check on trips, read natively from the Postgres replica that Trino queries, finds nulls in vehicle_id, a column that had none at the last check. Data Workers opens a low-severity incident |
| 15:20 | Slack | send_slack_alert reaches #data-oncall and the owner of trips. The app on-call replies that the nulls are expected under the new feature. Data Workers records the note and keeps the incident open |
| 17:30 | Preset Chatbot | An account manager asks why a large customer's fleet utilization fell today. Chatbot answers from the dataset: down 22%, led by the north depot. It is faithful to the data; the data is wrong |
| 18:00 | Data Workers | Fleet utilization, which the team records hourly from fct_vehicle_utilization with monitor_metrics, reads 22% under its baseline while trips booked, also recorded, are normal. Severity goes up |
| 18:06 | Data Workers | diagnose_incident ties the drop to the 15:12 nulls. trace_cross_platform_lineage follows the model through the dbt manifest to trips in the Trino PostgreSQL catalog. blast_radius_analysis lists fct_customer_usage_weekly and the two dashboards the analytics lead recorded in the context graph: the internal Ops dashboard and the embedded Fleet utilization dashboard |
| 18:15 | Claude Code, Preset MCP | The analytics engineer asks in Claude Code. Her client queries the dataset through Preset MCP: 4,180 of today's trips were assigned after their build hour and are missing from the model. Cause confirmed |
| 18:25 | Data Workers, Slack | Data Workers proposes the fix as a diff for the owner to merge: the incremental filter moves to updated_at with a 48-hour lookback, the model merges on trip_id, and a new test fails the run if assigned trips go missing from the model. With it: the blast radius, the rerun plan and the undo (revert the diff and rerun). The approval request reaches the analytics lead in Slack |
| 18:40 | Spellbook, GitHub | Data Workers' pull-request review reads the dbt exposures the Preset CLI synced and confirms the same two dashboards. The analytics lead reviews the diff and rollback in Spellbook, approves and merges |
| 18:45 | Airflow 2 | Data Workers queues the approved fleet_hourly rerun with trigger_airflow_dag. The lookback picks up every late-assigned trip |
| 19:05 | Data Workers | The run finishes. monitor_metrics records fleet utilization back inside its baseline band, and the next run_quality_check on trips shows the nulls draining as dispatchers assign vehicles |
| 19:10 | Preset | The embedded dashboard still shows 22% down: its dataset caches chart data for 24 hours, as the context graph notes. Data Workers' handoff names both dashboards, and she force-refreshes them in Preset. Data Workers writes the receipt (cause, diff, approver, rerun, checks, undo) and a graph note that trips.vehicle_id is now filled late |
Every tool did its job. A sensible product change made one column arrive late, and an incremental model skipped it. Data Workers connected an expected-looking null surge to a real drop in a customer-facing number, a named person approved the fix, and customers saw the right utilization before Tuesday's dispatch planning.
| Job | What Superset and Preset do | What Data Workers does |
|---|---|---|
| The question | SQL Lab, physical and virtual datasets, metrics and Jinja templates let analysts answer on their own | Keeps the source tables and dbt models under every dataset right |
| The delivery | Dashboards, native filters, Alerts & Reports, embedded dashboards and Preset Chatbot | Records the headline numbers people act on and holds them to a baseline |
| The break | Renders whatever the engine returns, and serves cached chart data until the timeout | Catches the drop, traces it to the change that caused it and lists every model and recorded dashboard it reaches |
| The fix | Owners edit charts, datasets and dashboards, and force-refresh or wait out the cache | Proposes the upstream fix as a diff for its owner, routes it to a named approver and queues the approved rerun |
| The proof | Shows the corrected chart in the app, the embed, Chatbot or through MCP | Re-checks the tables, compares the recorded value and writes a receipt with cause, diff, approver and undo |
Why doesn't Superset or Preset just do this itself?
Superset bet on an open-source visualization layer over any SQL engine, so teams own their BI the way they own their warehouse. Preset bet on running that layer well, with governance and AI, and keeping every asset portable. Their guardrails fit that job. Superset 6.1.0 checks RBAC permissions on MCP tool calls and adds a preview flow for chart updates through MCP. Preset says every MCP action "runs through the same RBAC and permission model as the Preset UI", with row-level security, workspace isolation and audit logging.
That protects the BI surface, exactly where a BI tool should stop. Fixing this incident took a source check, a lineage trace, a dbt change, a named approval, an orchestrator rerun and a verification, across an app database, dbt project, Trino and Airflow DAG that Superset does not run. That is a different product with different liability: cross-system context, blast-radius scoping, approvals, rollback and receipts for changes in systems Superset doesn't own. It is the product Data Workers is, and it builds on the Superset or Preset your company already reads.
Every tool owns a slice. Data Workers covers the whole lifecycle
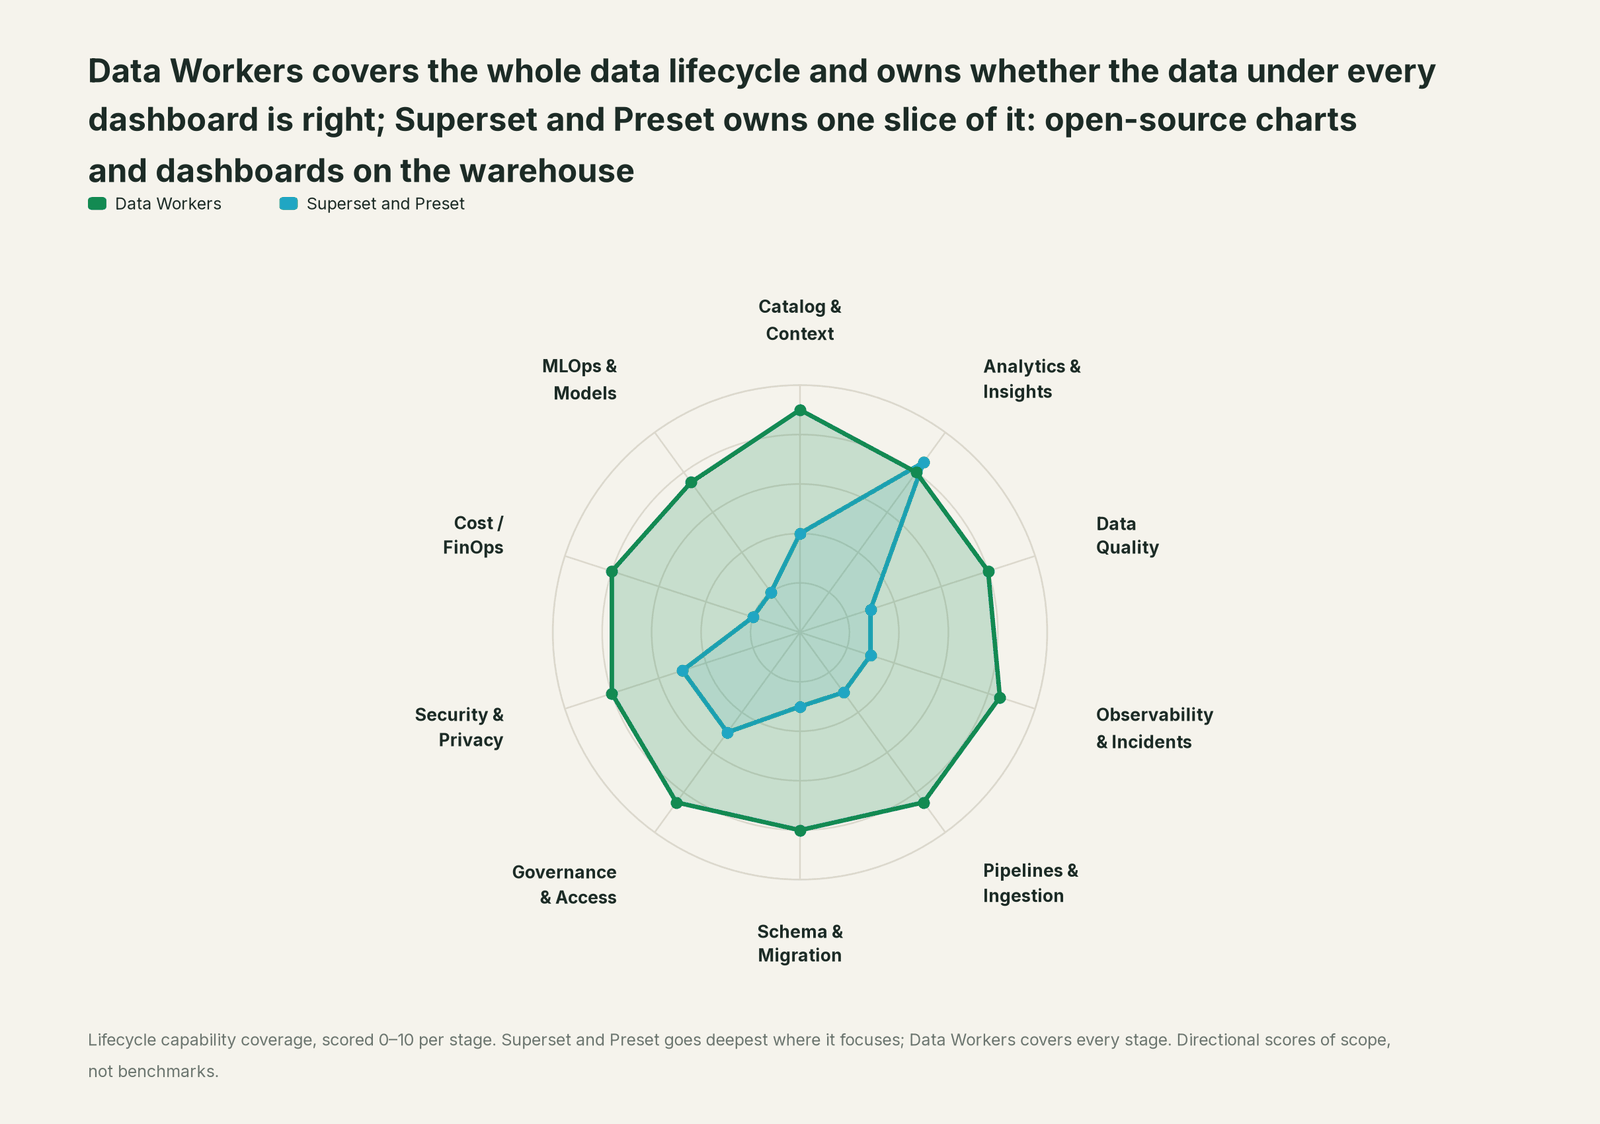
Superset and Preset own one slice outright: open-source charts and dashboards on the warehouse, for analysts, business users and embedded customers. Each point tool adds another console, contract and handoff. Data Workers covers the whole lifecycle with one context, one approval flow and one audit trail, and builds on the Superset you already run.
| Stage | Data Workers | Superset and Preset | Why we scored it this way |
|---|---|---|---|
| Catalog & Context | 9 | 4 | Datasets carry metrics and calculated columns, and the Preset CLI syncs descriptions from dbt. Data Workers keeps one governed context graph across every platform, joined to lineage, quality and owners. |
| Analytics & Insights | 8 | 8.5 | The home stage: 40+ chart types, dashboards with native filters, SQL Lab, embedded dashboards, scheduled reports, Preset Chatbot and MCP. Data Workers makes sure the tables under them are right. |
| Data Quality | 8 | 3 | A chart shows what the database returns; nothing in Superset tests the tables under a dataset. Data Workers checks Postgres, Snowflake and BigQuery tables for duplicate keys, nulls and row counts, and holds recorded values to a baseline. |
| Observability & Incidents | 8.5 | 3 | Alerts fire when a SQL condition is met; they do not trace a cause. Data Workers traces a wrong number back to the source change, model or run behind it, proposes the fix and verifies it. |
| Pipelines & Ingestion | 8.5 | 3 | Preset is a visualization layer with no ingestion layer, by design. Data Workers queues approved reruns through the orchestrator for the pipelines under the dashboards. |
| Schema & Migration | 8 | 3 | Virtual datasets and the dbt sync keep datasets in step with models. Data Workers reviews dbt pull requests, and the review reads the dashboards synced back as exposures. |
| Governance & Access | 8.5 | 5 | Roles, dataset permissions and row-level security govern the workspace; Preset adds SSO and SCIM. Data Workers routes every data change to a named approver. |
| Security & Privacy | 8 | 5 | Guest tokens with row-level security scope embedded dashboards, and MCP calls inherit RBAC. Data Workers leaves a receipt on every data change and proposes masking for the owner to apply. |
| Cost / FinOps | 8 | 2 | Chart caching cuts repeat queries to the warehouse. Data Workers attributes Snowflake spend per query and per dbt model through query tags, and sums BigQuery spend for the account. |
| MLOps & Models | 7.5 | 2 | Superset serves analytics, not models. Data Workers keeps the data under models and agents healthy. |
How Superset, Preset and Data Workers work together
Your people stay in Superset or Preset, Claude Code or Cursor, and Slack. Spellbook Data Catalog (in preview) is where the data team looks: each proposed fix, its blast radius, approver and rollback. Underneath, Data Context Wizard keeps one governed context graph, the Data-Agents Swarm does the work with 20+ specialist agents, the Autonomous Data-Conductor runs each fix end to end (detect, diagnose, fix, review, verify, remember), and per-domain guardrails hold approvals, receipts and rollback.
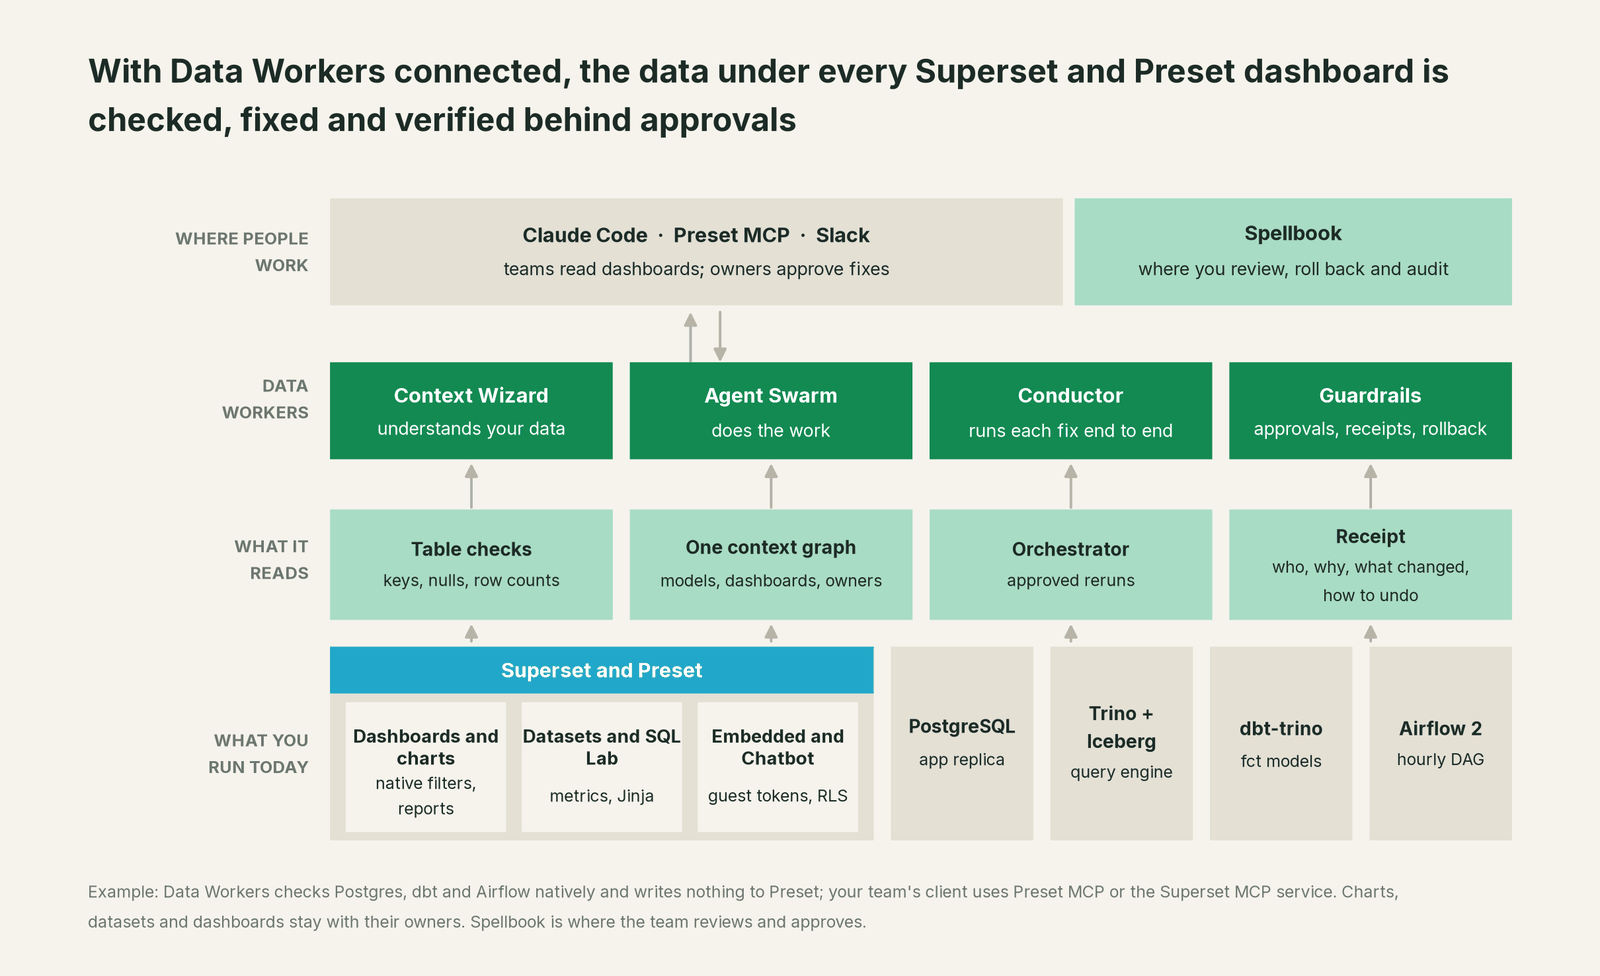
Where Data Workers works. Natively on what sits under Superset: Postgres, dbt and the orchestrator, and Snowflake or BigQuery when they are your warehouse. For Iceberg tables behind Trino, the team records the numbers that matter with monitor_metrics and Data Workers holds them to a baseline. It connects to Superset and Preset over their API or MCP server today; your team's client uses their MCP servers side by side, and Data Workers' agents never call them. The Preset CLI's dbt sync writes each dashboard back to dbt as an exposure, and Data Workers' pull-request review reads those exposures from the manifest. Record the same dashboards in the context graph, with notes such as "this dataset caches for 24 hours", and blast_radius_analysis names them. Data Workers writes nothing to Superset or Preset and clears no cache; BI is read by design.
What Data Workers checks. run_quality_check runs nulls, uniqueness on id columns and minimum row counts on Postgres and Snowflake (and BigQuery with a service-account key); get_quality_score rolls them up and explain_table returns a table's definition, lineage, documentation and trust score. monitor_metrics holds recorded values, such as utilization per hour, to a baseline, catching drops every row-level check would pass. trace_cross_platform_lineage and blast_radius_analysis follow a table to its source and forward to every model and recorded dashboard; diagnose_incident, remediate and get_incident_history run the incident. Your data stays in your systems: the agents, credentials and model key run in your infrastructure, and the hosted Conductor sees workflow metadata only.
Setup over MCP today. Clone the open-source repository and add start-agent.sh entries to your client's MCP config, as the client setup docs show. On self-hosted Superset 6.1.0 the MCP service is an optional install (apache-superset[fastmcp]) that runs as its own process with JWT authentication in production; your ingress routes /mcp to it. Superset checks each MCP tool against the user's role, so give question-asking accounts a role without edit rights. On Preset Enterprise, your account team enables Preset MCP (OAuth 2.0, same RBAC).
// Example: .mcp.json for Claude Code. The superset entry is your team's own connection
// to the Superset MCP service (JWT auth in production); Data Workers does not call it.
{
  "mcpServers": {
    "superset": {
      "type": "http",
      "url": "https://superset.example.com/mcp"
    },
    "dw-context-catalog": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-context-catalog"]
    },
    "dw-quality": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-quality"]
    },
    "dw-incidents": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-incidents"]
    }
  }
}
List the tools with your client's own command (/mcp in Claude Code). Ask "is everything under the Fleet utilization dashboard healthy?" and get the charts from Superset's server and the lineage, checks and open incidents from Data Workers in one answer.
Where fixes go. Data Workers proposes the change as a diff for the owner to merge, usually a dbt model, test or source mapping, with its blast radius and undo step; it opens the pull request itself when your team turns on the dbt GitHub pull-request target. After approval it queues the rerun through Airflow, Dagster or Prefect.
One request, L0 to L4. The autonomy ladder is set per domain.

- •L0 manual. A customer files a ticket about a strange chart and someone starts digging.
- •L1 observe. Data Workers checks the tables under your key dashboards and logs what it would do.
- •L2 propose. Data Workers drafts the upstream fix with its blast radius; a named owner approves in Spellbook.
- •L3 act reversibly. For proven classes, such as rerunning the hourly DAG after an approved model fix, Data Workers acts, verifies and records the undo.
- •L4 autonomous. For a narrow class in one domain, Data Workers fixes, verifies and posts the receipt.
Approvals go to a named person; a request nobody answers expires and escalates, and never grants itself. No agent can promote its own work. Read is it safe to let AI agents change production data, how approvals work for AI data agents and where does our data go for the full safety model.
The same loop runs on Metabase, Looker and Sigma, and under this example on Starburst, Postgres, dbt and Airflow. Weighing Superset against Metabase? See Metabase vs Superset.
What changes for your team
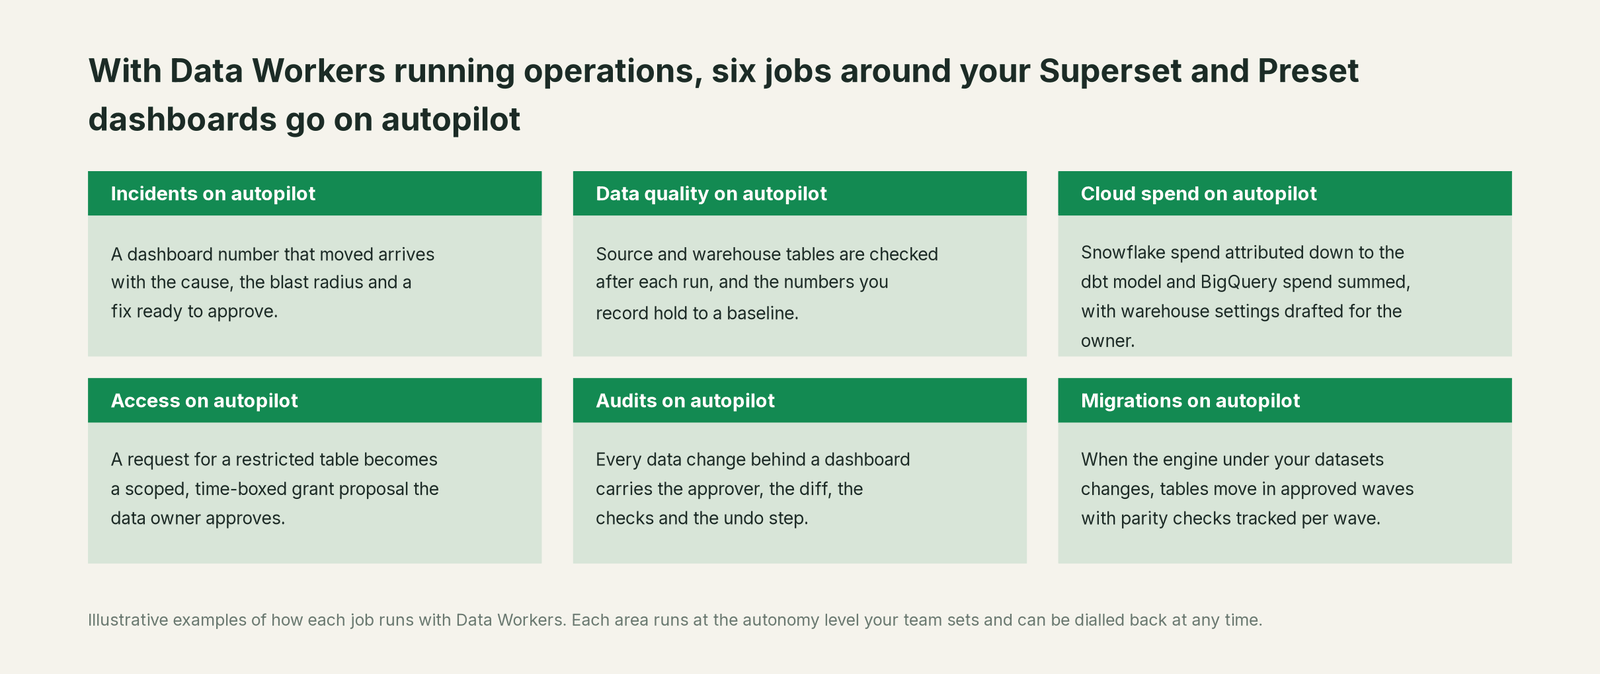
Teams on Superset chose it to own their stack, and a small platform team ends up answering "is this chart right?" for analysts, executives and customers. With Data Workers, these jobs run on autopilot at the level you set.
- •Incidents. A dashboard number that moved arrives with the cause, the blast radius and a fix ready to approve.
- •Data quality. Source and warehouse tables are checked after each run, and the numbers you record hold to a baseline.
- •Cloud spend. Snowflake spend is attributed down to the dbt model and BigQuery spend summed for the account, with warehouse settings drafted for the owner.
- •Access. A request for a restricted table becomes a scoped, time-boxed grant proposal the data owner approves.
- •Audits. Every data change behind a dashboard carries the approver, the diff, the checks and the undo step.
- •Migrations. When the engine under your datasets changes, tables move in approved waves with parity checks tracked per wave.
Keep Superset and Preset, or consolidate?
Keep Superset and Preset if you love them; Data Workers works with them from day one. Many teams consolidate once Data Workers runs that slice too.
Most teams keep Superset or Preset: the charts, datasets, embeds and reports belong there. What they consolidate is the tooling around it: a separate data-quality tool, a SQL alert that emails when utilization moves more than 10%, and a spreadsheet of which dashboard reads which dbt model. Weighing a build on the Superset MCP service and a coding agent? Read build it ourselves with Claude Code and MCP servers: connecting servers is the easy part; cross-system context, approvals and rollback are the work. For what Data Workers reads and changes on each system, see Data Workers integrations.
The case for your CFO
The outcome: the numbers your customers and leadership read in Superset or Preset (utilization, usage, revenue) stay right, and when something upstream changes them, the fix arrives before the next planning meeting with a named approver.
The risk story: Data Workers changes nothing in Superset or Preset. It proposes upstream fixes as diffs, and nothing runs until the named owner approves. Every change is verified and leaves a receipt: what broke, what changed, who approved it and how to undo it. Autonomy is set per domain from L0 manual to L4 autonomous, and an org-wide stop halts all autonomous dispatch. There is zero migration.
Why now: Preset Chatbot and MCP put dashboards in every AI client, and embeds put your numbers in front of paying customers. A wrong table now reaches a customer as a dashboard and an account manager as a confident sentence.
The first win: one dashboard customers or leadership act on, with its source tables checked after each run and its headline numbers held to a baseline. What stays the same: your Superset or Preset workspace, datasets and permissions, your engine and app database, your dbt project and orchestrator, and your review process. For the numbers, see the ROI of agentic data operations.
The sentence to repeat upstairs: "Superset and Preset keep giving every team open-source dashboards on the warehouse; Data Workers makes sure the data under them is right, and a named owner approves every fix with a receipt."
Getting started
Start with a pilot. Pick the dashboard behind a number people act on, often the embedded one, connect Data Workers read-only to the database, dbt project and orchestrator under it, record its headline numbers, and let it watch for a few weeks before turning on the first fix class. The pilot path and plans are on the pricing page, and the pilot is credited in full against the first year.
FAQ
Does Data Workers edit our Superset charts, datasets or dashboards? No. They stay with their owners. When one should change, Data Workers says which and why, and the owner edits it.
Does Data Workers clear the Superset cache after a fix? No. Cached charts refresh when their timeout passes or the owner force-refreshes. Data Workers names the affected dashboards so the owner knows which to refresh.
Our dbt tests passed. How did Data Workers catch the missing trips? The rows that landed were valid; the rows that never landed were the problem. Data Workers holds the values your team records, like utilization per hour, to a baseline with monitor_metrics, and checks source tables such as trips for new nulls, so a drop no row-level test would see still opens an incident with its lineage and blast radius.
Preset Chatbot gave a wrong answer. Can Data Workers tell why? Usually Chatbot was faithful to the dataset and the data underneath was wrong. Data Workers' agents never call Chatbot or either MCP server; they trace the dataset's tables to the source change, model or run that moved, and the receipt records cause and fix.
Does this work on self-hosted Apache Superset as well as Preset? Yes. Data Workers works on the systems under Superset, so how you run Superset does not matter. Table checks run natively on Postgres, Snowflake and BigQuery, among 50+ connectors.
We embed Superset dashboards for customers. Can Data Workers change row-level security or mask a column? Row-level security and guest tokens stay in Superset or Preset. If a sensitive column sits under an embedded dataset, Data Workers proposes the masking or access change for the data owner to apply, and records who approved it.
Sources
- •Apache Superset, GitHub releases (6.1.0 on May 13, 2026, still the latest app release; 6.0.0 on Dec 18, 2025; helm chart 0.22.8 on Sep 9, 2026), https://github.com/apache/superset/releases (checked Oct 3, 2026)
- •Apache Superset, UPDATING.md at 6.1.0 (MCP service: FastMCP, dashboards, charts, datasets, SQL Lab; optional install; separate process; JWT authentication), https://github.com/apache/superset/blob/6.1.0/UPDATING.md (checked Oct 3, 2026)
- •Apache Superset, 6.1.0 changelog (RBAC permission checking for MCP tools, preview flow for MCP chart updates, get_chart_data), https://github.com/apache/superset/blob/6.1.0/CHANGELOG/6.1.0.md (checked Oct 3, 2026)
- •Apache Superset, MCP service README (create charts, query data, manage dashboards; port 5008,
/mcpingress), https://github.com/apache/superset/tree/master/superset/mcp_service (checked Oct 3, 2026) - •Apache Superset, Caching (chart cache timeout per chart, dataset or database, else the DATA_CACHE_CONFIG default; 86400-second example; Force refresh), https://superset.apache.org/admin-docs/configuration/cache/ (checked Oct 3, 2026)
- •Preset, Homepage (Preset Cloud, Managed Private Cloud, Certified Superset, Embedded, API; "does not require an additional ingestion layer"), https://preset.io/ (checked Oct 3, 2026)
- •Preset, Preset MCP (Enterprise; built on the Superset MCP service; OAuth 2.0; RBAC, row-level security, workspace isolation, audit logging; build and modify dashboards, run SQL), https://preset.io/ai/mcp/ (checked Oct 3, 2026)
- •Preset, Preset Chatbot (available today on Enterprise; limited evaluation on Pro and Trial; inherits row-level security, column masking and RBAC), https://preset.io/ai/chatbot/ (checked Oct 3, 2026)
- •Preset, Pricing (Starter, Professional, Enterprise; 40+ visualization types; embedded add-on; SSO + SCIM and MCP Server integration on Enterprise), https://preset.io/pricing/ (checked Oct 3, 2026)
- •Preset, Embedded dashboards (Embedded SDK, row-level security, SSO), https://preset.io/embedded-dashboards/ (checked Oct 3, 2026)
- •Preset, backend-sdk / Preset CLI (dbt sync; dashboards synced back as dbt exposures; 0.3.13 on Sep 30, 2026), https://github.com/preset-io/backend-sdk (checked Oct 3, 2026)
- •Data Workers, Client setup (open-source docs), https://dataworkers.io/opensource-docs/client-setup/ (checked Oct 3, 2026)
- •Data Workers open-source repository, agent tools and start-agent.sh, https://github.com/DataWorkersProject/dataworkers-claw-community (checked Oct 3, 2026)