You're on Roo Code. Here's how Data Workers builds on it
Your team runs Roo Code modes in VS Code. Add Data Workers over MCP and a custom Data Change mode that proposes, while every data change is approved, verified and recorded.
Your engineers run a dev team inside VS Code. They plan a change in Architect mode, build it in Code mode, chase a failure in Debug mode and hand multi-step work to Orchestrator, which splits it into subtasks for the other modes. The repo carries the team's habits: a .roomodes file with custom modes, rule folders under .roo/, MCP servers in .roo/mcp.json, and auto-approve settings that decide what Roo may do without asking. One fact matters for planning. On May 15, 2026, Roo Code, Inc. shut down the extension and archived the repository; its team now builds Roomote, a cloud coding agent, and Roo Code Cloud is winding down. Release 3.54.0 is still on the VS Code Marketplace, the Apache 2.0 code stays public, and the community continues it as Zoo Code, which reads the same .roomodes and .roo/mcp.json files. Your .roo folder is the asset, and it travels.
That's where Data Workers comes in. Roo Code is the dev team in your editor. Data Workers is the agentic data platform behind it: it knows what a data change touches and carries it into production, scoped, approved, verified and recorded. Connected over MCP, a Roo Code mode answers from Data Workers' governed context and proposes data changes, and Data Workers applies them after the owner approves. The setup lives in two files in your repo, so it works in the Roo Code you run today and moves with you to Zoo Code or Roomote unchanged.
Key takeaways
- •Roo Code writes the code; Data Workers carries the data change. Modes stay the place engineers plan, edit and review. Data Workers supplies lineage, owners and blast radius, then applies the approved change and verifies it downstream.
- •A custom Data Change mode is the distinct move. One entry in
.roomodesgives Roo a mode that can read, edit only models and migrations, and call Data Workers over MCP. It proposes; it never runs the warehouse change itself. - •Two locks on every write. Roo Code asks before each MCP tool call unless that tool is auto-approved, and Data Workers' per-domain guardrail gates the change in the warehouse. Apply tools stay on the Data Workers side by design.
- •Your setup survives the tool change.
.roo/mcp.jsonand.roomodeswork in Roo Code 3.54 and in Zoo Code, and Roomote imports the samemcpServerssnippet. - •Climb one domain at a time. Start at L1 observe, move to L2 propose, then L3 act reversibly where the record earns it.
Roo Code is the dev team. Data Workers is the data crew behind it.
Roo Code knows your repository. It indexes the code, reads your rules, edits across files and runs commands you allow. What it can't see from the repo is the live estate: which Snowflake objects a dbt model feeds, which Tableau workbook reads a column, which Airflow task exports it to the CRM, and who owns each one. Data Workers keeps that in one governed context graph and does the data side of the work through 20+ specialist agents.
Here is one change, end to end. This is an illustration, not a customer case.
| Time | System | What happens |
|---|---|---|
| 09:10 | GitHub | An issue asks to rename cust_id to customer_id in dim_customers. |
| 09:12 | Roo Code | The engineer switches to the Data Change mode and describes the task. |
| 09:13 | Roo Code | The mode calls assess_impact on the Data Workers schema agent. It is a read tool on the "Always allow" list, so it runs without a prompt. |
| 09:14 | dbt | Data Workers reports three downstream models that still select cust_id. |
| 09:14 | Tableau | It also finds the Customer health workbook reading the column through dim_customers. |
| 09:15 | Airflow | And the crm_sync DAG's export task. |
| 09:17 | Roo Code | The mode calls generate_migration: the forward SQL, the rollback SQL and the systems it touches. |
| 09:31 | GitHub | The mode edits the three models (its edit access is limited to models/ and migrations/); the engineer opens the pull request with the impact report attached. |
| 09:55 | GitHub | dbt CI passes and the analytics lead approves the pull request. |
| 10:04 | Spellbook | The platform owner approves the Snowflake migration with the blast radius in view. |
| 10:07 | Snowflake | The owner applies the migration Data Workers drafted, with its rollback SQL on file; Data Workers queues the rerun of the affected models. |
| 10:42 | Tableau | Workbook totals match the pre-change baseline, the next crm_sync run succeeds, and the receipt is recorded. |
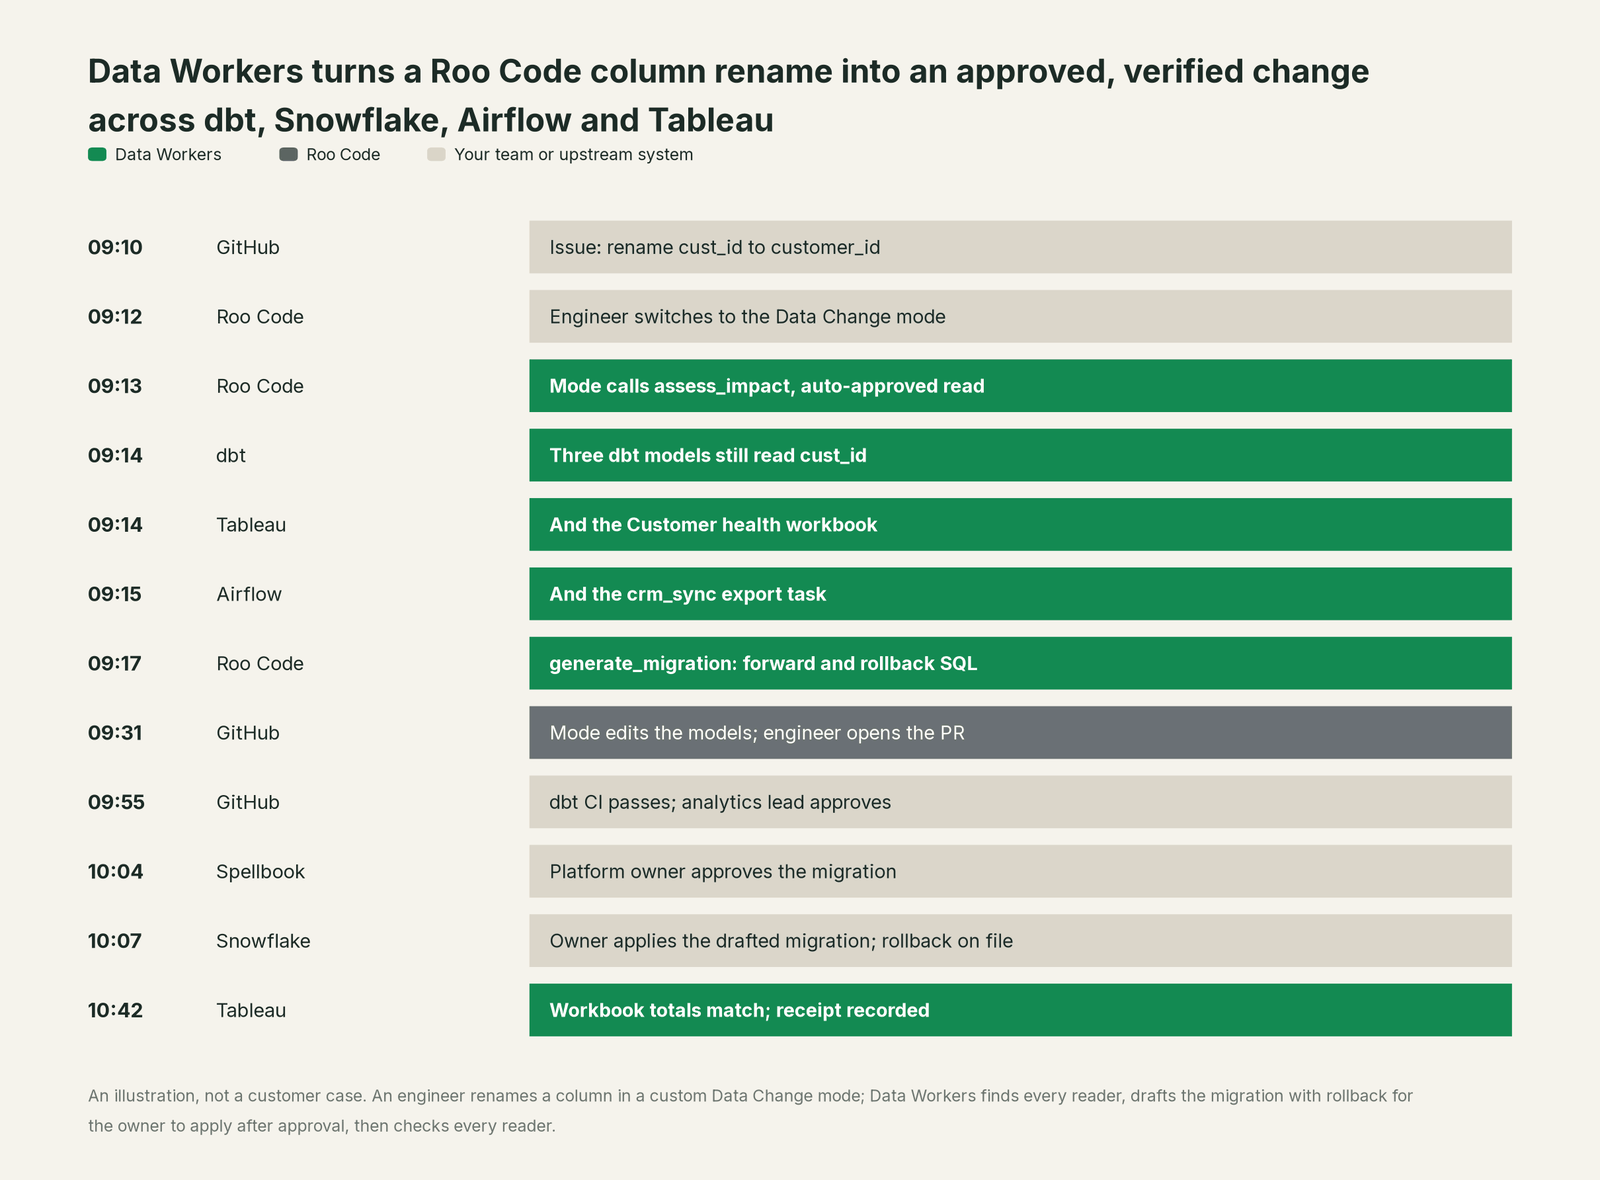
Without that context, the same issue is a tidy pull request that passes CI and breaks a CRM export and a customer health dashboard the next morning. With it, the engineer approved one pull request, the owner approved one change, and every reader moved in the same window, checked downstream.
| Job | What Roo Code does | What Data Workers does |
|---|---|---|
| Understand the request | Reads the issue, the repo and .roo rules; plans in Architect mode | Adds live data context: lineage across dbt, Snowflake, Airflow and Tableau, owners and usage |
| Write the change | Edits dbt models, SQL and DAG code in Code mode or a custom mode | Supplies the impact report, the list of every reader and the migration with rollback SQL |
| Gate the action | Asks before each MCP tool unless a tool is on "Always allow" | Routes the data change to the domain owner by policy, with blast radius attached |
| Apply to production | Leaves the repo change for the engineer to commit and push | Applies the approved migration or rerun in the warehouse, with rollback ready |
| Verify | Runs the commands and tests you allow | Checks the changed tables against baselines, then dashboards and downstream runs |
| Record | Keeps the task history in the editor | Writes a receipt to the audit trail: who asked, who approved, what changed, how to undo it |
Why doesn't Roo Code just do this itself?
Focus and risk. Roo Code was built for one job: helping engineers plan, write and debug code through specialist modes, with the model of their choice. Its design reflects that. Modes are scoped by tool groups and file patterns, MCP auto-approval is off by default and granted tool by tool, and command execution sits behind an allow and deny list. That is the right design for an agent in an editor.
Changing production data across systems is a different product. It needs to know that a column is read by a Tableau workbook and a DAG that only exports overnight. It needs a blast radius before anything runs, an approval routed to the owner of that domain rather than to whoever is at the keyboard, a rollback path inside Snowflake, a check that the dashboard is right afterwards, and a receipt an auditor can read. It also means taking responsibility for changes in systems the editor doesn't run. A sensible coding-agent team leaves that to the server on the other end of the MCP connection, and Roo Code's creators have since put their focus on Roomote, a cloud coding agent. The server on the other end is Data Workers.
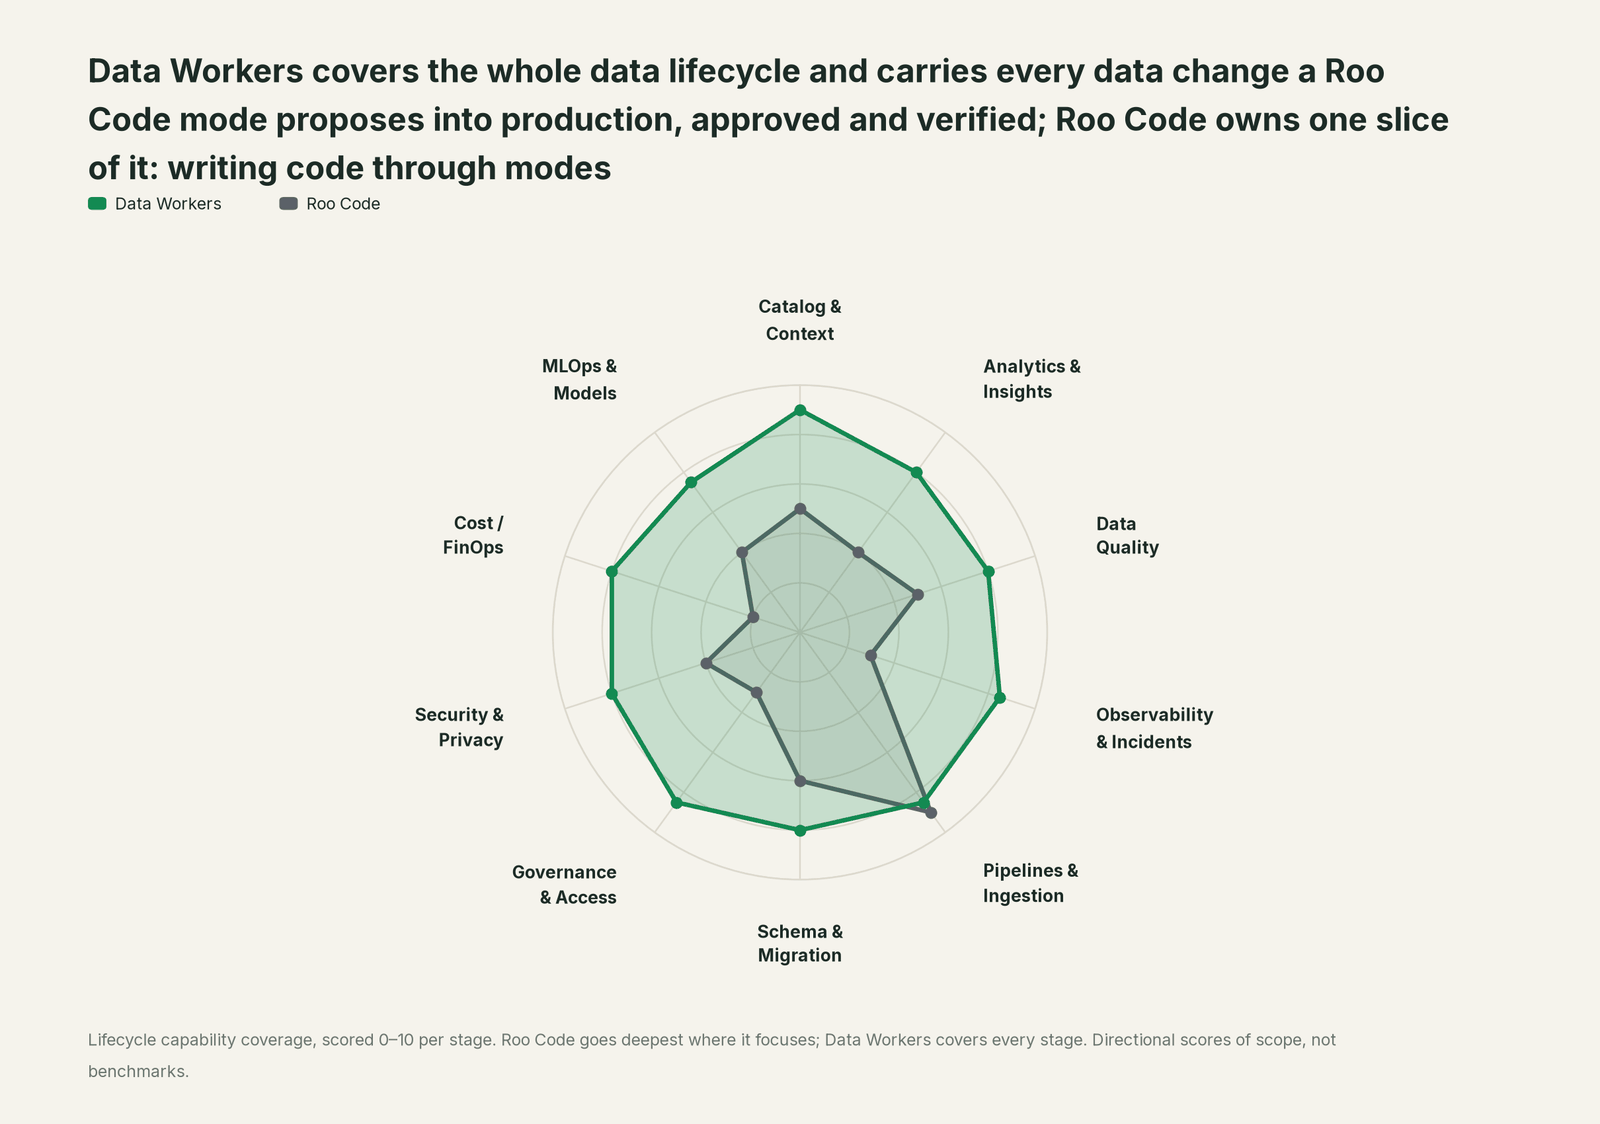
Every tool owns a slice. Data Workers covers the whole lifecycle
Roo Code goes deepest on writing and refactoring pipeline code. Data Workers covers every stage of the data lifecycle around that code. Each point tool adds another console, contract and handoff; Data Workers covers the whole lifecycle with one context, one approval flow and one audit trail.
| Stage | Data Workers | Roo Code | Why we scored it this way |
|---|---|---|---|
| Catalog & Context | 9 | 5 | Roo Code indexes the codebase and reads rules in .roo/ and per-mode rule folders. Data Workers keeps one governed graph of tables, owners, lineage and usage across platforms. |
| Analytics & Insights | 8 | 4 | Ask mode explains code and can draft a query on request. Data Workers answers business questions from governed metric definitions. |
| Data Quality | 8 | 5 | Code mode writes dbt tests and checks when asked. Data Workers runs quality checks, writes the missing tests and repairs failing ones. |
| Observability & Incidents | 8.5 | 3 | Debug mode traces code issues and adds logs. Data Workers detects data incidents, traces the cause across systems and closes them with a receipt. |
| Pipelines & Ingestion | 8.5 | 9 | Roo Code's home stage: Code, Architect and Orchestrator modes plan, write and refactor pipeline code across the repo. Data Workers builds and reruns pipelines behind approval. |
| Schema & Migration | 8 | 6 | Architect mode plans migrations and Code mode writes the DDL. Data Workers assesses the impact, drafts each migration with its rollback SQL for the owner to apply in approved waves. |
| Governance & Access | 8.5 | 3 | Mode tool groups, fileRegex limits and auto-approve settings govern the agent itself. Data Workers proposes least-privilege grants on your data platforms behind approvals. |
| Security & Privacy | 8 | 4 | Roo Code offers .rooignore and a command allow and deny list for its own agent. Data Workers' pull request review flags new columns whose names or annotations look sensitive, and leaves a receipt on every data change. |
| Cost / FinOps | 8 | 2 | Roo Code works on the code, not the warehouse bill. Data Workers traces Snowflake credits to the query and dbt model behind them and drafts the fix for the model's owner. |
| MLOps & Models | 7.5 | 4 | Code mode writes training and feature code. Data Workers keeps the data under models healthy and connects to MLflow and W&B. |
How Roo Code and Data Workers work together
Roo Code stays on top, where engineers ask, plan and review. Data Workers sits underneath over MCP: the Data Context Wizard answers from the governed graph, the Data-Agents Swarm does the work, the Autonomous Data-Conductor runs each fix end to end, and Spellbook Data Catalog (in preview) is where people review, approve, roll back and audit.
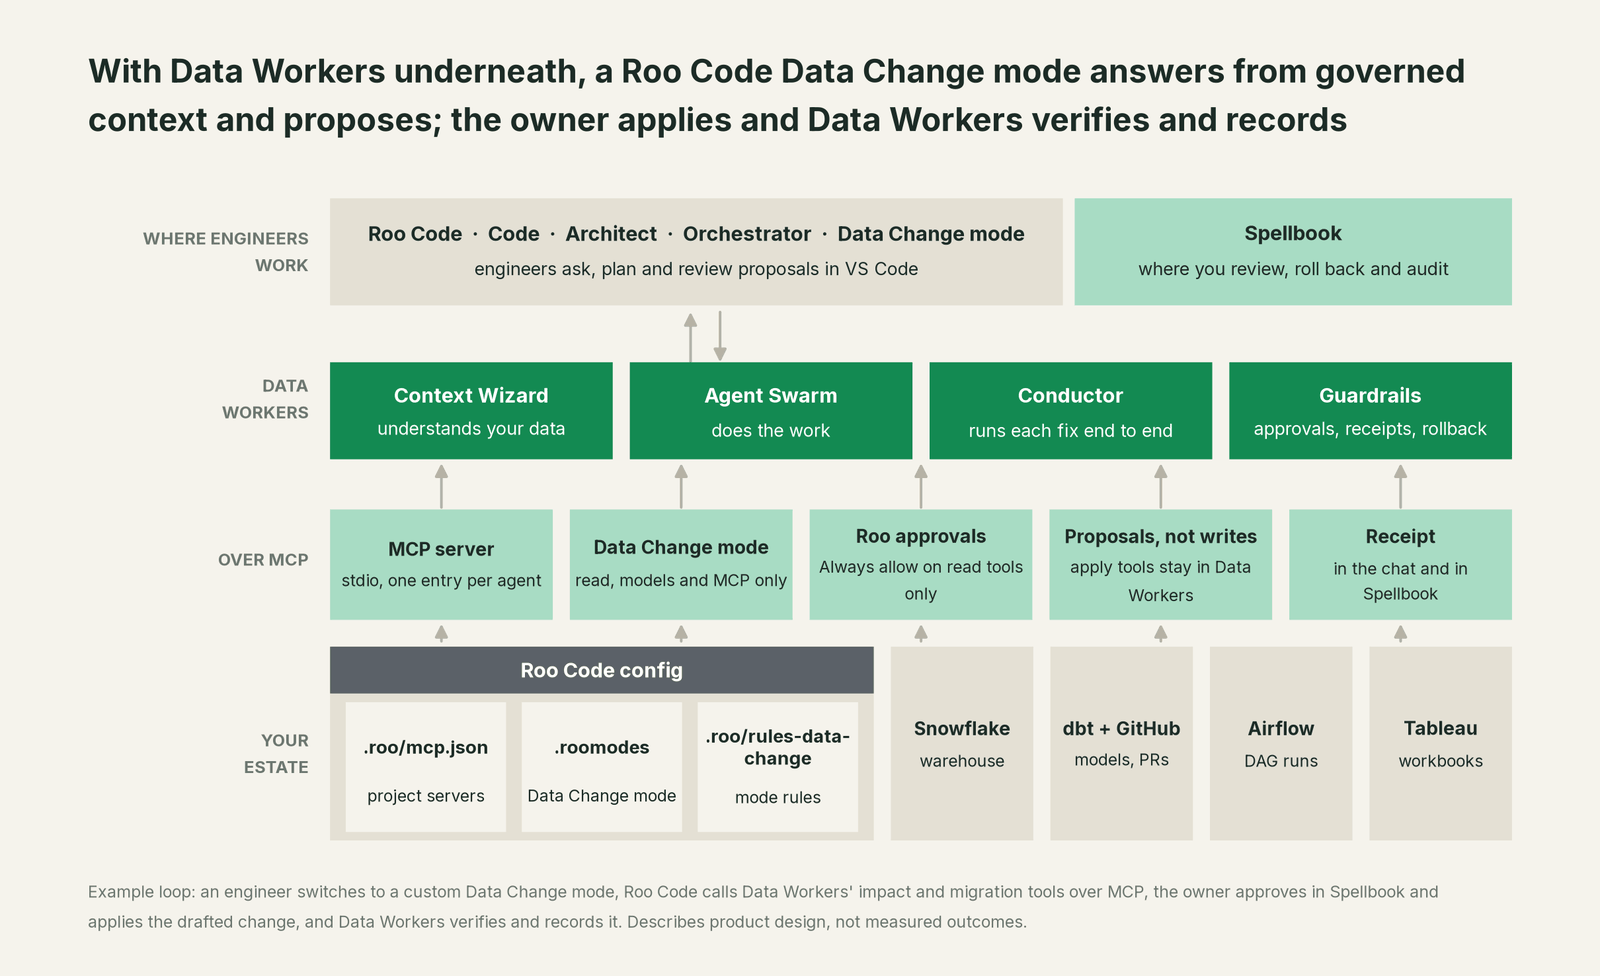
Connect the MCP servers. Every Data Workers agent is a standard MCP stdio server, so the same agents serve Roo Code, Cline, Cursor, Claude Code and Codex. Clone the open-source core (dataworkers-claw-community, Apache 2.0), run npm install, and add one entry per agent with start-agent.sh, as our client setup docs describe. In Roo Code, put the entries in the project's .roo/mcp.json so they travel with the repo; the project file wins over the global mcp_settings.json when a server name appears in both. Example:
{
  "mcpServers": {
    "dw-context-catalog": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-context-catalog"],
      "alwaysAllow": ["trace_cross_platform_lineage", "blast_radius_analysis"]
    },
    "dw-schema": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-schema"],
      "alwaysAllow": ["assess_impact"],
      "disabledTools": ["apply_migration", "rollback_migration"]
    },
    "dw-incidents": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-incidents"],
      "alwaysAllow": ["diagnose_incident", "get_root_cause"],
      "disabledTools": ["remediate"]
    },
    "dw-quality": {
      "command": "/path/to/dataworkers-claw-community/start-agent.sh",
      "args": ["dw-quality"],
      "alwaysAllow": ["run_quality_check"]
    }
  }
}
Two keys do the governance work. alwaysAllow lists the read tools that may run without a prompt; Roo Code only honours it once the global "Use MCP servers" auto-approve is on. disabledTools hides the apply tools from Roo entirely, so a mode can ask Data Workers for a migration with rollback SQL but can't run it. Applying happens in Data Workers, after the owner approves.
Add a Data Change mode. Custom modes are Roo Code's sharpest control: each mode declares which tool groups it gets and which files it may edit. A Data Change mode gets read, edit limited to models and migrations, and mcp, with no command group, so it can't run a shell command against the warehouse. Put it in the project's .roomodes. Example:
customModes:
  - slug: data-change
    name: Data Change
    description: Proposes data changes through Data Workers
    roleDefinition: You are a data engineer who changes dbt models and migrations only after checking their impact with Data Workers.
    whenToUse: Use for any change to dbt models, DDL or migrations.
    customInstructions: Before editing a model or DDL, call assess_impact and list every downstream reader. For schema changes, call generate_migration and attach the rollback SQL. Before finishing, call run_quality_check on changed models. Never apply a change to the warehouse; Data Workers applies it after the owner approves.
    groups:
      - read
      - - edit
        - fileRegex: ^(models|migrations)/.*\.(sql|yml)$
          description: dbt models and migrations only
      - mcp
Longer guidance goes in .roo/rules-data-change/, which Roo Code loads only for that mode. Orchestrator can delegate subtasks to the Data Change mode, so a multi-step ticket picks up the same checks. On Zoo Code, a mode can also list allowedMcpServers, which narrows the Data Change mode to the Data Workers servers alone.
Running in the cloud. Roomote, from Roo Code's creators, takes custom MCP servers too. Its add dialog has an "Import from JSON" button that accepts the same mcpServers snippet, local stdio servers run inside the task sandbox and are added by a deployment admin, and per-tool choices are enforced at Roomote's proxy. The Data Workers agents behave the same there as in the editor.
One request, from L0 to L4. Take one request an engineer types into the Data Change mode: "the orders_daily freshness check failed again, fix it". Here is what happens at each level, set per domain.
| Level | What happens when the engineer asks |
|---|---|
| L0 manual | Roo Code helps the engineer read logs and write a patch by hand. Data Workers isn't in the loop. |
| L1 observe | The mode calls diagnose_incident. Data Workers answers in the chat: the Airflow load task timed out after a source API change, two dashboards are stale, and the owner is the finance data team. |
| L2 propose | Data Workers drafts the fix (a retry and timeout change on the DAG plus a backfill plan) with its blast radius. The mode edits the DAG, the engineer opens the pull request, and the owner approves. |
| L3 act reversibly | For this pre-approved class of fix, Data Workers reruns the load and the backfill itself, with rollback ready, and records the receipt. The engineer sees the result in Roo Code. |
| L4 autonomous | Freshness incidents in this domain run end to end without waiting: detect, fix, verify, record. The owner reviews receipts in Spellbook and can dial the domain back at any time. |
Our Claude Code, Cursor and Codex integration guide walks through the same wiring for other coding agents, and the VS Code + Data Workers MCP agents page covers the agents from inside the editor.
What changes for your team
Engineers keep VS Code and the modes they built. What changes is the work around each data change: the hunt for who reads a column, the Slack thread to find an owner, the manual backfill, the evidence an auditor asks for months later.
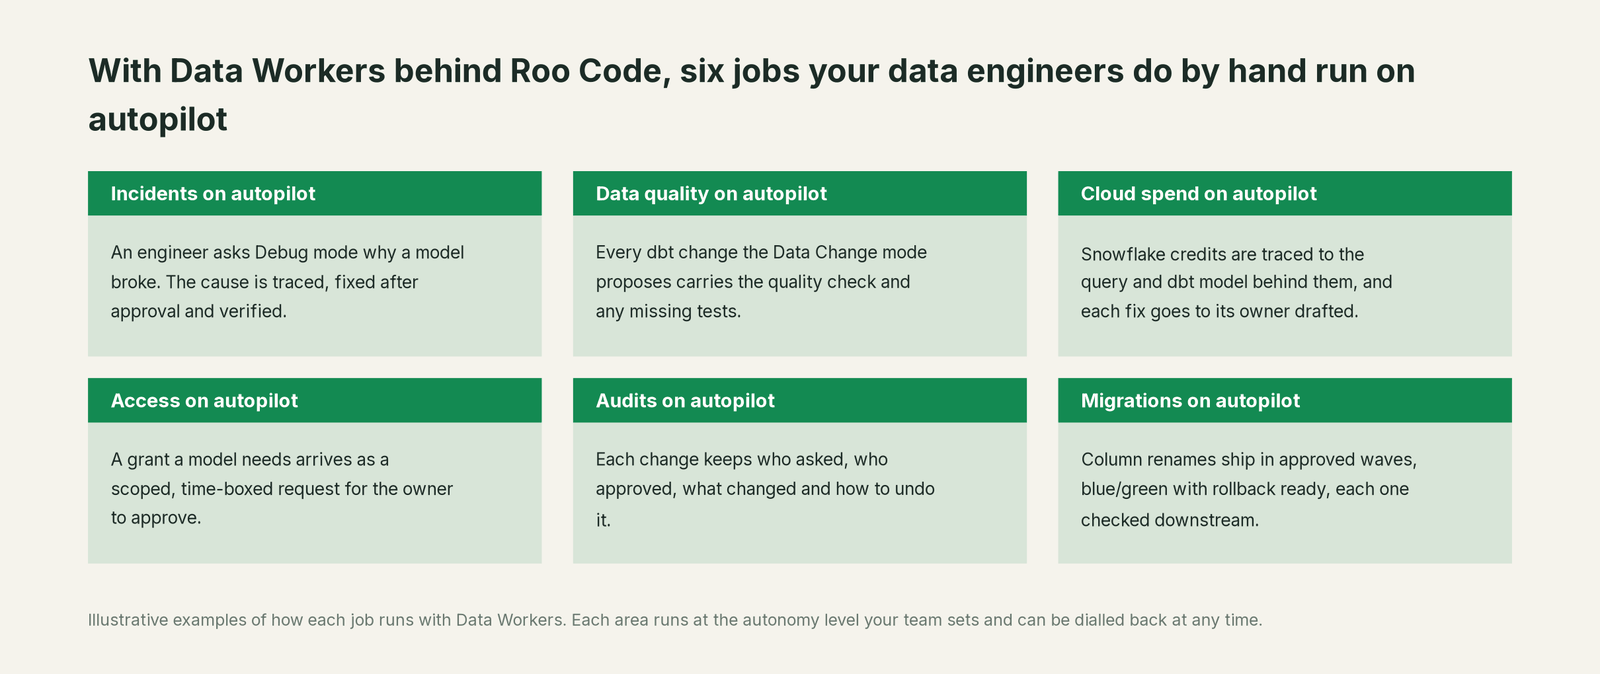
The data platform team stops being the human lookup service for lineage and ownership. Analytics engineers ship dbt changes with the impact already attached. Owners approve changes in one place with the blast radius in front of them. And the audit trail builds itself from receipts instead of screenshots.
Keep Roo Code, or consolidate?
Keep Roo Code if you love it; Data Workers works with it from day one. Many teams consolidate once Data Workers runs that slice too.
For Roo Code teams this year, the question has a second half: which editor agent you run next. Data Workers doesn't change that decision. Installed copies of Roo Code 3.54 keep reading .roo/mcp.json and .roomodes. Zoo Code reads the same files and imports Roo Code settings through its Export and Import Settings flow. Cline, where Roo Code started, takes the same mcpServers entries; see You're on Cline. Teams moving to Cursor or Codex point those tools at the same Data Workers agents. The data side stays put: one context, one approval flow and one audit trail, whatever editor sits on top. What teams consolidate are the extra tools around data changes: the separate lineage lookup, the impact script someone maintains, the spreadsheet of owners, the backfill runbook. For the wider picture, start from the hub, Your company just rolled out AI assistants. Now what?.
The case for your CFO
Your engineers already use an AI coding agent, and they ship code faster because of it. The outcome Data Workers adds is that the data changes they ship are right the first time: fewer broken dashboards, fewer bad exports to the CRM and finance, and less senior engineering time spent tracing who reads what.
The risk story is plain. At L1, agents only read and explain. At L2, they propose and a named owner approves. At L3, they act only on pre-approved, reversible classes of change, with rollback ready. Every action leaves a receipt with who asked, who approved, what changed and how to undo it. In this setup the editor agent can't apply a warehouse change at all; Data Workers does that after approval. Our safety guide covers what an agent can and can't do at each level, and the security and deployment guide covers where your data goes.
Why now: your team is deciding what runs in its editors next. Putting the data guardrails in Data Workers, below the editor, means that decision never puts the warehouse at risk again. Building that layer in house is possible, and our build-vs-buy guide lays out what it takes.
The first win is a Data Change mode in one dbt repo, at L1, with impact reports on every pull request. What stays the same: VS Code, Snowflake, dbt, Airflow, Tableau and your permission systems. Nothing is migrated. Our ROI guide shows how to size the return.
The sentence to repeat upstairs: "Whatever coding agent our engineers run, Data Workers makes every data change it proposes scoped, approved, verified and recorded."
Getting started
Start with a pilot: add the Data Workers agents to .roo/mcp.json in one repo, commit the Data Change mode, and run one domain such as schema changes or freshness incidents from L1 to L2 with your own engineers and owners. See pricing for the pilot terms; the pilot is credited in full against the first year.
FAQ
Roo Code was shut down. Does this setup still work? Yes. Roo Code, Inc. shut down the extension on May 15, 2026 and stopped shipping updates; its team now builds Roomote, and release 3.54.0 remains on the VS Code Marketplace with its MCP and custom-mode features. Zoo Code, the community continuation, reads the same .roo/mcp.json and .roomodes files, and Roomote imports the same mcpServers snippet. Data Workers runs as its own MCP servers, so nothing on the data side depends on which of these you choose.
Should the Data Workers servers go in `.roo/mcp.json` or the global `mcp_settings.json`? Use the project file for a team: it is versioned with the repo, every engineer gets the same servers, and it takes precedence when a server name appears in both. Use the global file for one engineer across many repos.
Can the Data Change mode change production data on its own? No. With the apply tools in disabledTools, the mode can read, assess impact and draft migrations, and the domain owner applies the drafted change after approving it, at the autonomy level you set. At L3, only pre-approved, reversible classes of change run without a fresh approval, each with rollback ready and a receipt.
Why a custom mode instead of rules in Code mode? A mode is enforced by tool access as well as instructions. The Data Change mode has no command group, so it can't run a shell command against the warehouse, and its fileRegex keeps edits inside models and migrations. Rules tell the agent when to call Data Workers; the mode limits what it can do while it works.
Which Data Workers tools should we auto-approve? Read tools only: trace_cross_platform_lineage, blast_radius_analysis, assess_impact, diagnose_incident, get_root_cause and run_quality_check. Roo Code's MCP auto-approval is off by default and needs both the global "Use MCP servers" setting and a per-tool "Always allow". Everything that proposes a change still shows in the chat for the engineer to read.
How do we keep credentials out of the repo? The stdio entries in the example carry no secrets. Data Workers uses its own scoped credentials to each data platform, so engineers never paste warehouse keys into Roo Code or into .roo/mcp.json.
Which data platforms does this work with? Data Workers runs control-plane connectors for Snowflake, Databricks and BigQuery, and reads dbt manifests and runs. For Airflow, Tableau and the rest of your stack, Data Workers connects over each tool's API or MCP server today.
Sources
Roo Code status and capabilities are current as of October 2, 2026: the Roo Code repository (README disclaimer "The Roo Code Extension was shut down on May 15th", archived, last release 3.54.0 on May 15, 2026, Apache 2.0; checked 2026-10-02), the VS Code Marketplace listing (version 3.54.0; checked 2026-10-02), the Roo Code Cloud service notice (winding down to focus on Roomote; checked 2026-10-02), and the archived Roo Code documentation, pages dated May 15, 2026: Using MCP in Roo Code (config locations, precedence, transports, alwaysAllow, disabledTools), Custom Modes (.roomodes, tool groups, fileRegex, mode rules), Using Modes (built-in modes, Orchestrator) and Auto-Approving Actions (all checked 2026-10-02). Zoo Code: the Zoo Code repository (v3.84.0, Sep 26, 2026; source reads .roo/mcp.json and .roomodes, mode field allowedMcpServers; checked 2026-10-02) and the Roo to Zoo migration guide (checked 2026-10-02). Roomote: roomote.dev and Custom MCP servers (checked 2026-10-02). Data Workers setup follows the client setup docs and the open-source dataworkers-claw-community repository (start-agent.sh and the agent tool definitions for trace_cross_platform_lineage, blast_radius_analysis, assess_impact, generate_migration, apply_migration, rollback_migration, diagnose_incident, get_root_cause, remediate and run_quality_check; checked 2026-10-02). Product names and statuses change quickly; if we've got something wrong, tell us and we'll fix it.