You're on Census: Census Sends Your Models to the Tools Your Teams Act On. Data Workers Makes Sure Each One Is Right First
Census is now Fivetran Activations. It sends your warehouse models to Salesforce and beyond. Data Workers makes sure each model is right before it leaves, behind approvals.
Your RevOps and marketing teams think in datasets, activation syncs, field mappings and audiences. A dbt model becomes a dataset, an activation sync maps its columns to a Salesforce object or a Braze attribute, and Audience Hub lets marketers build segments on the warehouse without a ticket. Census joined Fivetran in 2025 and now ships as Fivetran Activations, inside the Fivetran console, billed on Monthly Active Rows once your Census contract ends. Census sends your models into the tools your teams act on. Data Workers makes sure each model is right before it leaves the warehouse: it checks the tables behind every dataset, diagnoses what an upstream change broke, gets the fix approved by a named owner and verifies the number.
Key takeaways
- •Census keeps its job. Datasets, activation syncs, schedules, dbt Cloud triggers, Audience Hub and every destination stay with the team that runs them today.
- •Data Workers owns what the sync reads. It checks the tables behind each dataset for duplicates, nulls and volume on Snowflake and BigQuery, and baselines lateness and the business metrics your team names.
- •It traces past the warehouse. One context graph joins the source app, the landed tables, the dbt models and the activation syncs your team records against them, so the reach of a change is known before the next sync runs.
- •Your syncs stay in your hands. Data Workers connects to Activations over its API today. It never triggers, pauses or edits a sync or an audience; when a hold is the safe move, it proposes it with the reason and your team acts.
- •One approval, one receipt. A named owner approves in Spellbook, and the receipt records the cause, the fix, the approver, the checks and the undo.
Census sends your models into the tools your teams act on. Data Workers makes sure each model is right before it leaves the warehouse.
Here is a Wednesday at a B2B software company that sells per seat, an illustration rather than a customer case. The product runs on PostgreSQL, and the Fivetran app_postgres connection replicates it into Snowflake every hour. In dbt, int_account_users joins users to stg_app__workspace_members, and mart_account_seats counts seats per account. That mart is the dataset behind an activation sync, "Account seats to Salesforce", which updates Seats_Used__c and Over_Seat_Limit__c on the Account object and is triggered when the dbt platform job daily_product_marts completes at 18:00. A Salesforce Flow emails the customer's admin when Over_Seat_Limit__c turns true. A dbt exposure declares the sync as the mart's consumer, and the team has recorded the same link in the context graph. Data Workers runs at L2 propose for the revenue domain.
| Time | System | What happens |
|---|---|---|
| 15:30 | PostgreSQL | A "shared workspaces" release lets one user belong to several workspaces in the same account. workspace_members now holds one row per user per workspace instead of one per user. No column changes |
| 16:00 | Fivetran | The app_postgres sync lands the new rows in Snowflake and succeeds. No schema changed |
| 16:12 | Data Workers and Snowflake | The scheduled checks run on the tables the team chose. The column profile is unchanged; run_quality_check flags user_id in workspace_members as no longer unique: 11,240 duplicates against zero yesterday |
| 16:20 | Data Workers | diagnose_incident classifies a change of grain at the source, not a load error. trace_cross_platform_lineage, get_dbt_model_lineage and blast_radius_analysis follow it through int_account_users to mart_account_seats and, through the team's context-graph note, to the Salesforce sync and its two Account fields |
| 16:24 | Microsoft Teams, email and Spellbook | Data Workers posts the finding card in the analytics channel and emails the approval request to the model owner: count distinct users per account in int_account_users (a diff), add a dbt unique test on account and user in staging. It also recommends that RevOps set the sync to Manual if the fix can't merge before 18:00 |
| 17:25 | Spellbook and GitHub | The analytics engineer queries the mart: tonight's build would put 421 accounts over their seat limit, against 9 actually over. She approves, applies the diff on a branch, Data Workers posts its blast-radius review on the pull request, CI passes and she merges. No hold was needed |
| 18:00 | dbt platform | daily_product_marts builds on the fixed model; the new test passes |
| 18:12 | Activations and Salesforce | The sync runs on job completion and sends correct seat counts. Nine accounts flip to over the limit, as they should |
| 18:20 | Data Workers and Snowflake | Data Workers re-runs the uniqueness check, compares total seats with the baseline the team records with monitor_metrics, finds it within normal movement and writes the receipt |
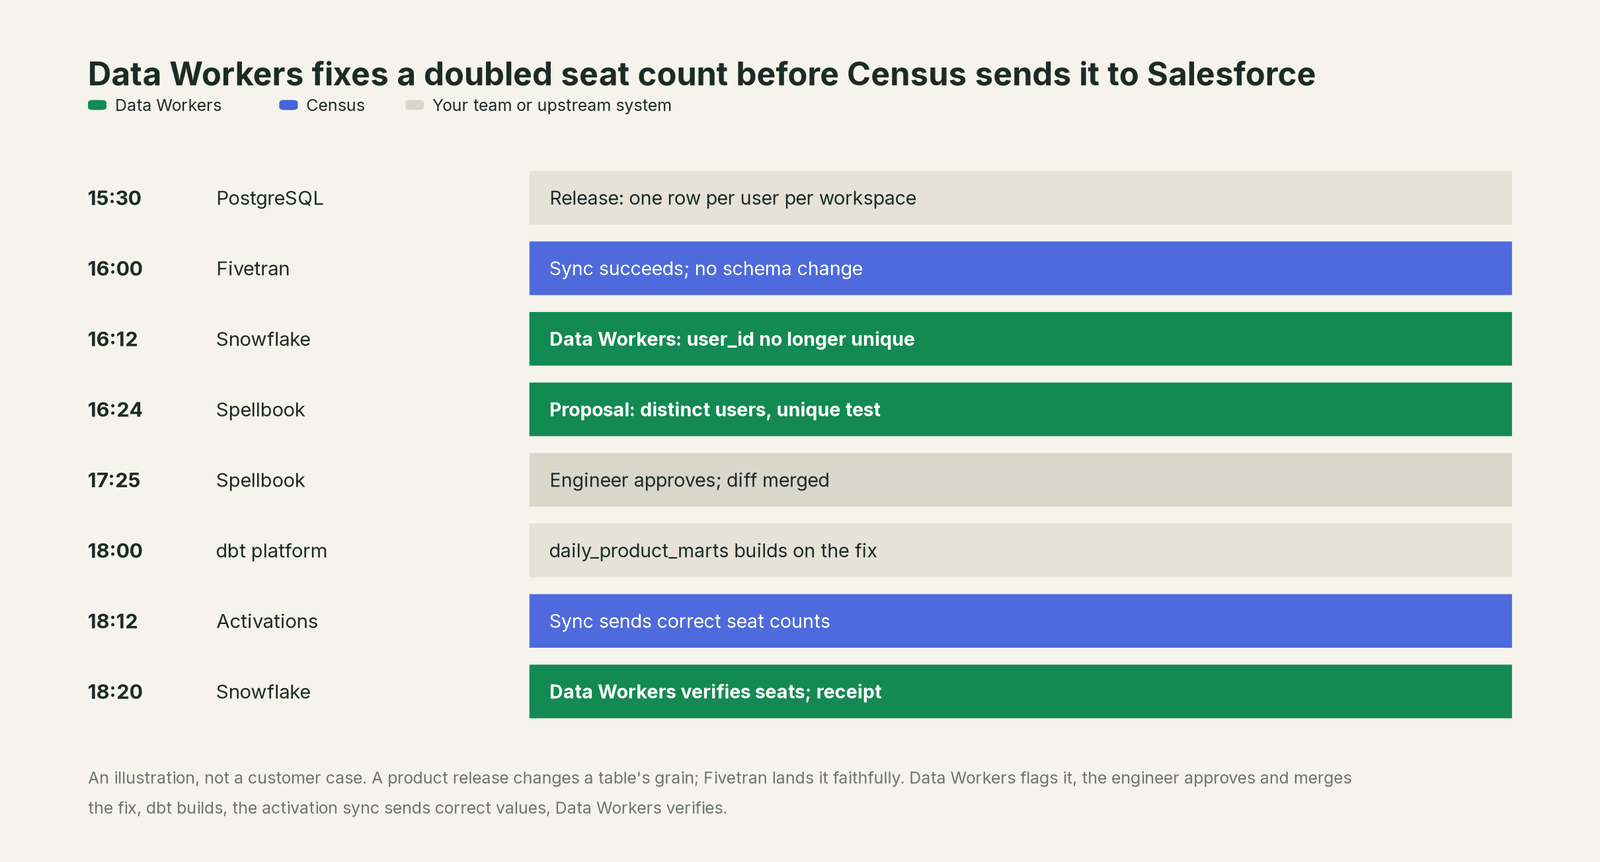
Nothing in Census misbehaved. The sync delivered exactly what the dataset held, on the trigger the team chose. That is the right design. The problem lived two steps upstream, in a join written when a user could belong to only one workspace. Without the check, 412 customers would have received a seat-limit email that evening and account managers would have opened expansion conversations on a wrong number. Data Workers saw the source change, the dbt model and the activation sync as one chain and put the decision in front of a person before 18:00. Nobody had to touch Census.
| Job | What Census does | What Data Workers does |
|---|---|---|
| Defining what to send | Datasets from dbt models, warehouse tables or SQL; Audience Hub segments | Checks the tables behind each dataset and knows which models feed which sync |
| Sending it | Activation syncs to 200+ tools, with identifiers, sync behaviors, schedules and dbt Cloud triggers | Leaves every sync with your team and makes sure what it reads is right |
| Spotting trouble | Sync logs, alerts and the API Inspector show rejected rows and destination errors | Catches the upstream change that a successful sync would carry, and diagnoses it across systems |
| Fixing it | Sends the corrected values on the next run | Proposes the model fix as a diff for the owner to merge, plus the hold when one is needed |
| The record | Sync history per activation | A receipt: cause, fix, approver, checks and undo, in Spellbook and the audit trail |
Why doesn't Census just do this itself?
Because Census's promise is faithful, fast delivery, and that promise is why RevOps trusts it. It sends only new or changed rows after the first sync, tracks sync state in a dedicated census schema in your warehouse, matches records on the identifiers you choose and retries destination errors. If a dataset says an account uses 64 seats, Census writes 64. A reverse ETL tool that held back numbers it judged suspicious would be a worse reverse ETL tool.
Its AI features keep the same sensible scope. Dataset SQL Generation helps people write the SQL behind a dataset, and AI Columns apply a prompt to every row with your own model key from Anthropic, Google Gemini or OpenAI. Both help define data inside Activations. Neither reaches back into a product database or a dbt project owned by another team.
The Wednesday fix crossed seven systems, from a product database to Salesforce and the team's chat. It needed a check where the data landed, lineage from a source table to a CRM field, a fix in a model Census doesn't own, a hold only RevOps should press, a named approver and a receipt. Taking on liability for changes across tools Census doesn't run is a different product category. That product is Data Workers, and it builds on Census.
Every tool owns a slice. Data Workers covers the whole lifecycle
Census owns sending warehouse data to business tools, and it does that well. Each point tool around it adds another console, another contract and another handoff. Data Workers covers the whole lifecycle with one context, one approval flow and one audit trail, with Census at the outbound edge of the pipeline.
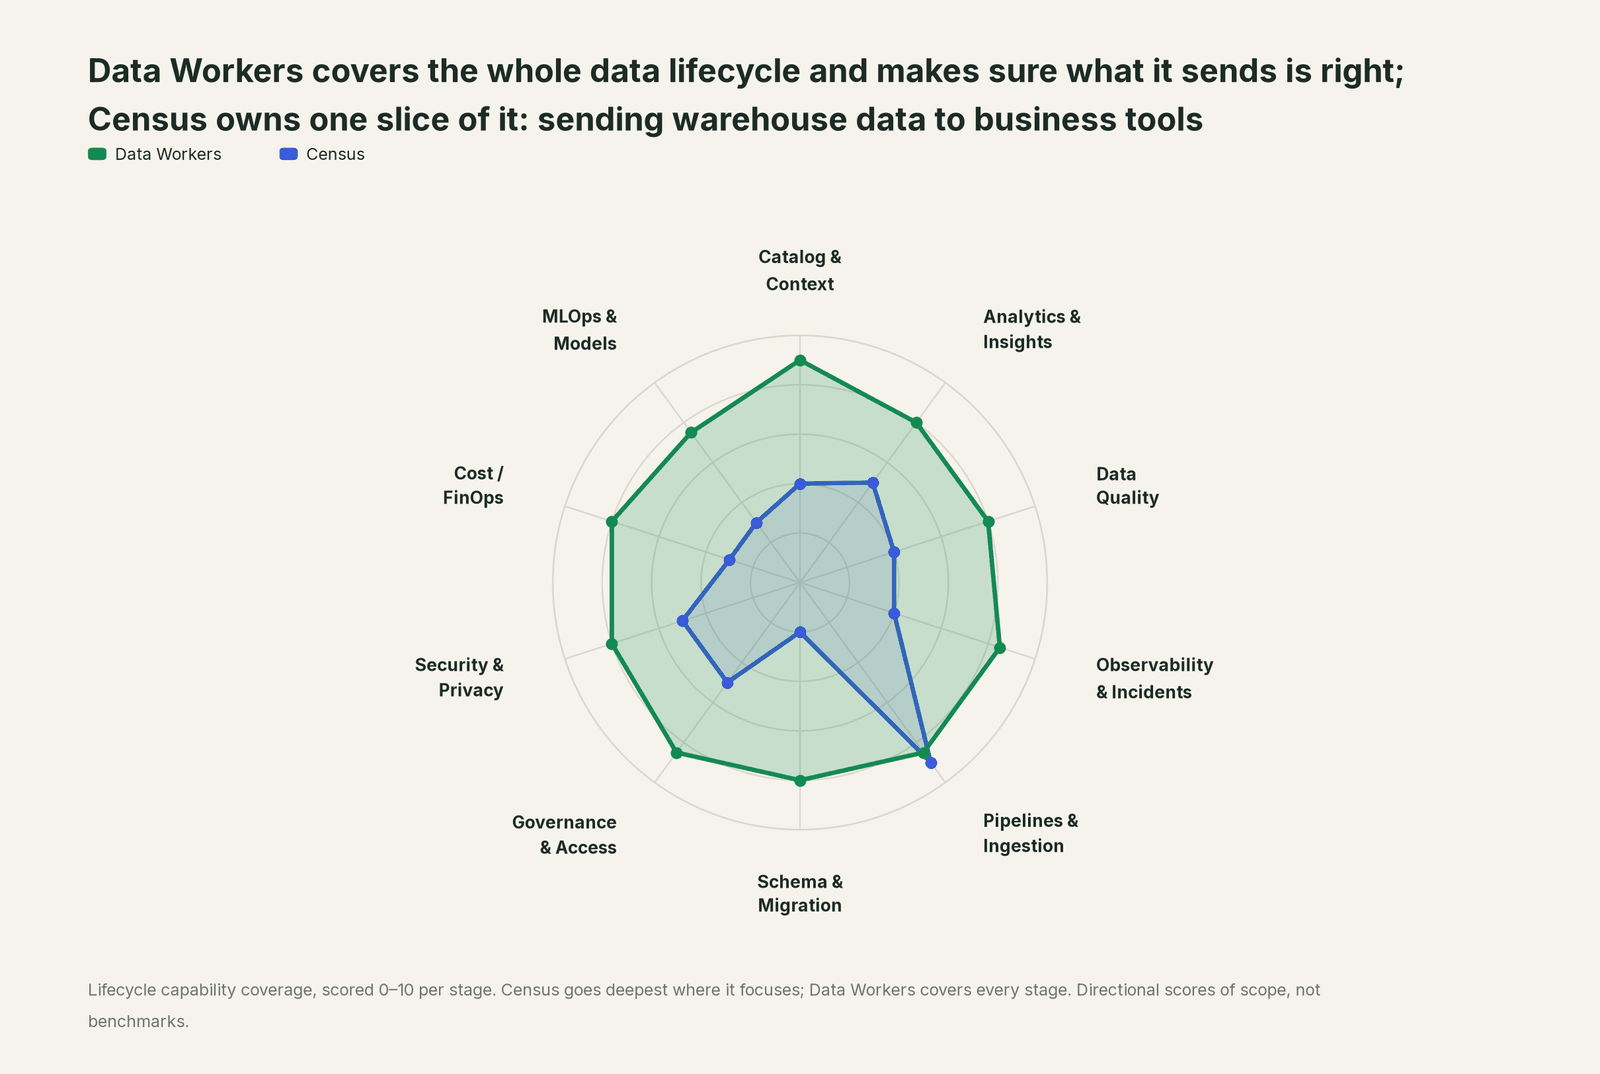
| Stage | Data Workers | Census | Why we scored it this way |
|---|---|---|---|
| Catalog & Context | 9 | 4 | Census knows every dataset, field mapping and destination object it syncs. Data Workers keeps one governed context graph across the source app, the warehouse, dbt and every destination, with owners and usage. |
| Analytics & Insights | 8 | 5 | Audience Hub lets marketers build and test segments on warehouse data. Data Workers answers data questions from governed definitions with lineage behind every number. |
| Data Quality | 8 | 4 | Census delivers what the dataset holds and reports rows that fail at the destination. Data Workers checks the tables behind each dataset for duplicates, nulls and volume, and tracks lateness against a baseline your team records, before the sync reads them. |
| Observability & Incidents | 8.5 | 4 | Sync logs, alerts and the API Inspector show what each activation sync did. Data Workers diagnoses the incident upstream, across systems, when a sync succeeds with the wrong values. |
| Pipelines & Ingestion | 8.5 | 9 | Census's home stage: activation syncs into 200+ business tools, with schedules, dbt Cloud triggers, identifiers and sync behaviors. Data Workers leaves every sync with your team and fixes what it reads. |
| Schema & Migration | 8 | 2 | Census maps fields to destination objects but does not manage warehouse schemas. Data Workers classifies each landed change as breaking or safe and plans migrations in approved waves. |
| Governance & Access | 8.5 | 5 | Fivetran's Users & Permissions now govern Activations, with access controls moving to each activation source. Data Workers drafts each warehouse access request as a scoped grant with an expiry for a named owner to approve. |
| Security & Privacy | 8 | 5 | A least-privilege source account, and rows stay out of Census servers. Data Workers' pull request review flags new columns whose names or annotations look sensitive, and leaves a receipt on every data change. |
| Cost / FinOps | 8 | 3 | MAR pricing counts unique rows per sync key each month. Data Workers attributes Snowflake credits to the dbt models behind each dataset and drafts the fix for the owner. |
| MLOps & Models | 7.5 | 3 | AI Columns apply a prompt to each row with your own model key. Data Workers keeps the data under your models fresh and correct. |
For the category view, read what is an agentic data platform and how Data Workers differs from data observability.
How Census and Data Workers work together
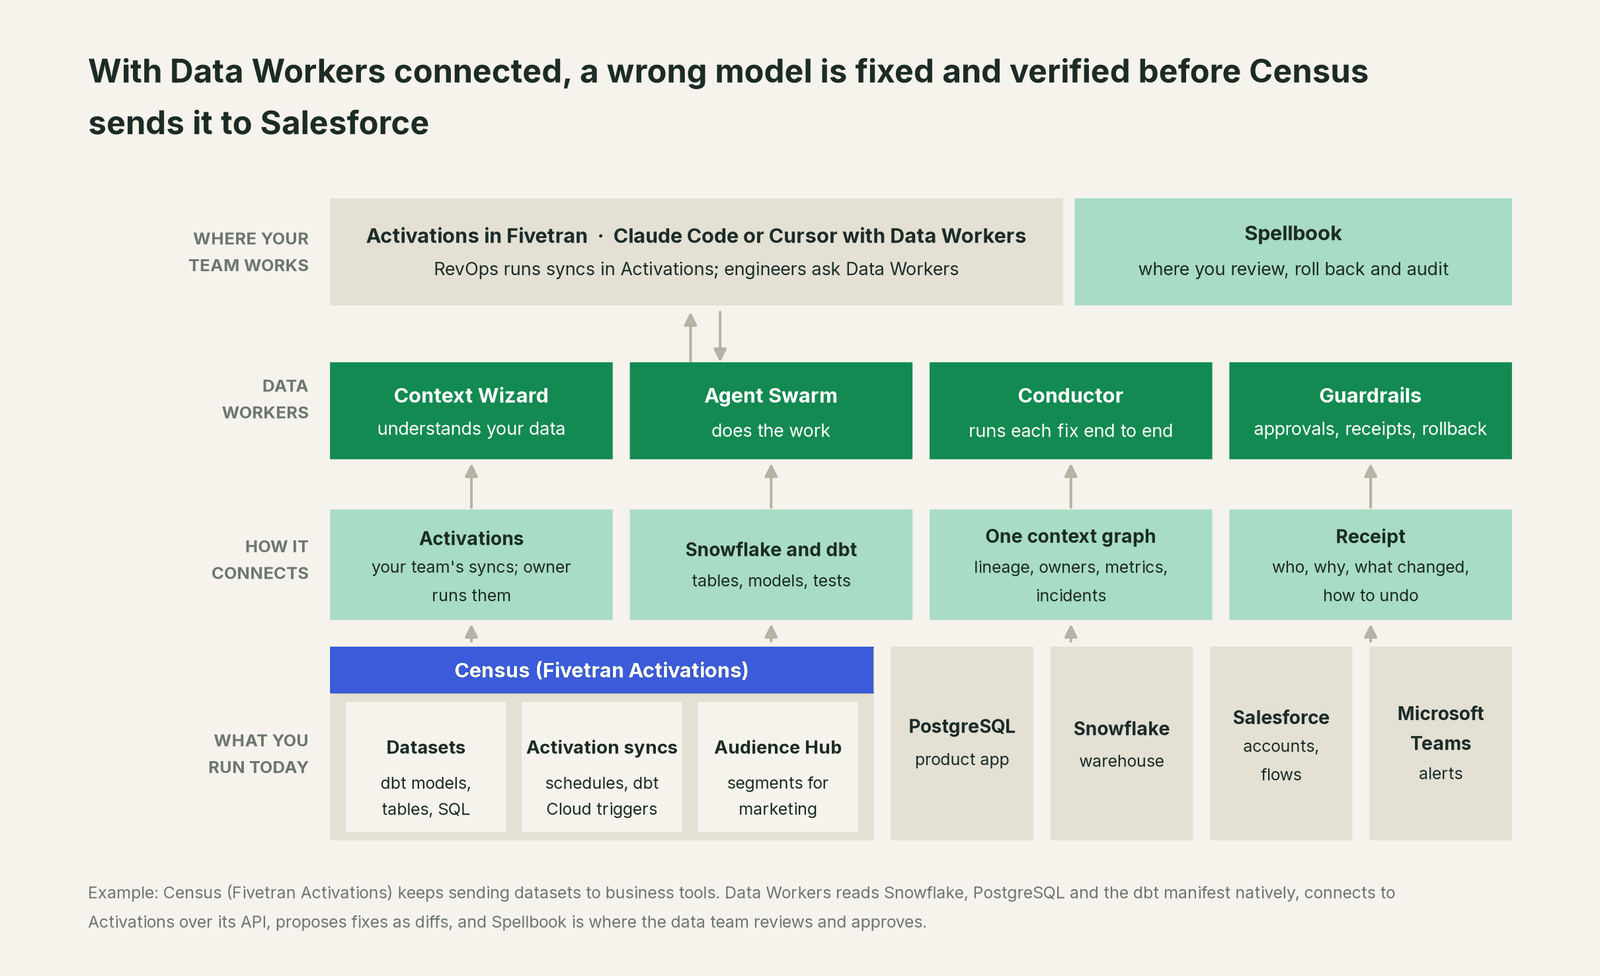
RevOps and marketing keep building datasets, syncs and audiences in Activations. Engineers ask Data Workers from Claude Code or Cursor. Spellbook Data Catalog (in preview) is where the data team reviews, approves and rolls back. Data Context Wizard joins the source app, the landed tables, the dbt project and each activation sync in one governed context graph, the Data-Agents Swarm does the work with 20+ specialist agents, and the Autonomous Data-Conductor carries each fix from detection to verification.
| What it covers | How | |
|---|---|---|
| Reads | The tables behind each dataset, and their schemas against a baseline | Native connections to Snowflake, BigQuery, Databricks and PostgreSQL |
| Reads | The dbt manifest; pull-request review's lineage diff also reads the exposures that name each activation sync | Native dbt connection |
| Reads | Datasets, activation syncs and their run history in Census's own terms | The Activations API today (Fivetran's MCP server covers connections and destinations, not Activations) |
| Runs | Scheduled checks on the tables behind each dataset, and approved reruns of the dbt jobs your team names | run_quality_check on the warehouse; reruns queued through your orchestrator, or by the owner in the dbt platform |
| Proposes | Model fixes, tests and sync holds | A diff for the owner to merge; holds with their reason, for your team to apply in Activations |
Record each activation sync in the context graph against its model, and the blast radius of any change reaches the CRM field it lands in; declare it as a dbt exposure too, and pull-request review's lineage diff names it. Data Workers reviews your team's dbt pull requests with that reach in the comment, and connects to Salesforce over its API today. On the inbound side, Data Workers + Fivetran covers schema changes step by step.
Setup in your coding agent. Every Data Workers agent is an MCP server, set up by the documented path in the client setup guide: clone the open-source repo and add one start-agent.sh entry per agent. Example for Claude Desktop or Cursor:
{
  "mcpServers": {
    "dw-quality": { "command": "/path/to/dataworkers-claw-community/start-agent.sh", "args": ["dw-quality"] },
    "dw-incidents": { "command": "/path/to/dataworkers-claw-community/start-agent.sh", "args": ["dw-incidents"] },
    "dw-context-catalog": { "command": "/path/to/dataworkers-claw-community/start-agent.sh", "args": ["dw-context-catalog"] },
    "dw-connectors": { "command": "/path/to/dataworkers-claw-community/start-agent.sh", "args": ["dw-connectors"] }
  }
}
Ask "is anything wrong in the models our Salesforce syncs read tonight?" and Data Workers returns each flagged table, its likely cause, the syncs it reaches and any proposal. List the tools with your client's own command, such as /mcp. For a shared endpoint, the Data Workers remote server serves /mcp with an API key (bearer) or OAuth tokens from your identity provider, verified through JWKS.
One Census incident, L0 to L4, set per domain.

- •L0 manual. A customer replies to a seat-limit email the next morning; an engineer finds the new workspace rows by afternoon.
- •L1 observe. Data Workers posts the diagnosis at 16:20: the grain change, the join and the Salesforce fields at risk. Nothing changes.
- •L2 propose. Data Workers proposes the diff, the test and the fallback hold. Nothing changes until the engineer approves and merges.
- •L3 act reversibly. For change classes with a proven record, such as queuing the rerun of a named dbt job after an approved fix merges, Data Workers runs the step, verifies it and writes the receipt.
- •L4 autonomous. For a scoped domain with a long clean record, Data Workers handles the repeatable steps end to end; activation syncs, audiences and model merges stay with your team.
For the safety model, read is it safe to let AI agents change production data and how approvals work. On where data lives: the agents run in your infrastructure and hold the warehouse credentials and model key, your data stays in your systems, and the hosted Conductor sees workflow metadata only.
What changes for your team
Census took the custom API scripts off your team's plate. Data Workers takes the next job: making sure what Census sends is right before a customer or a rep acts on it.
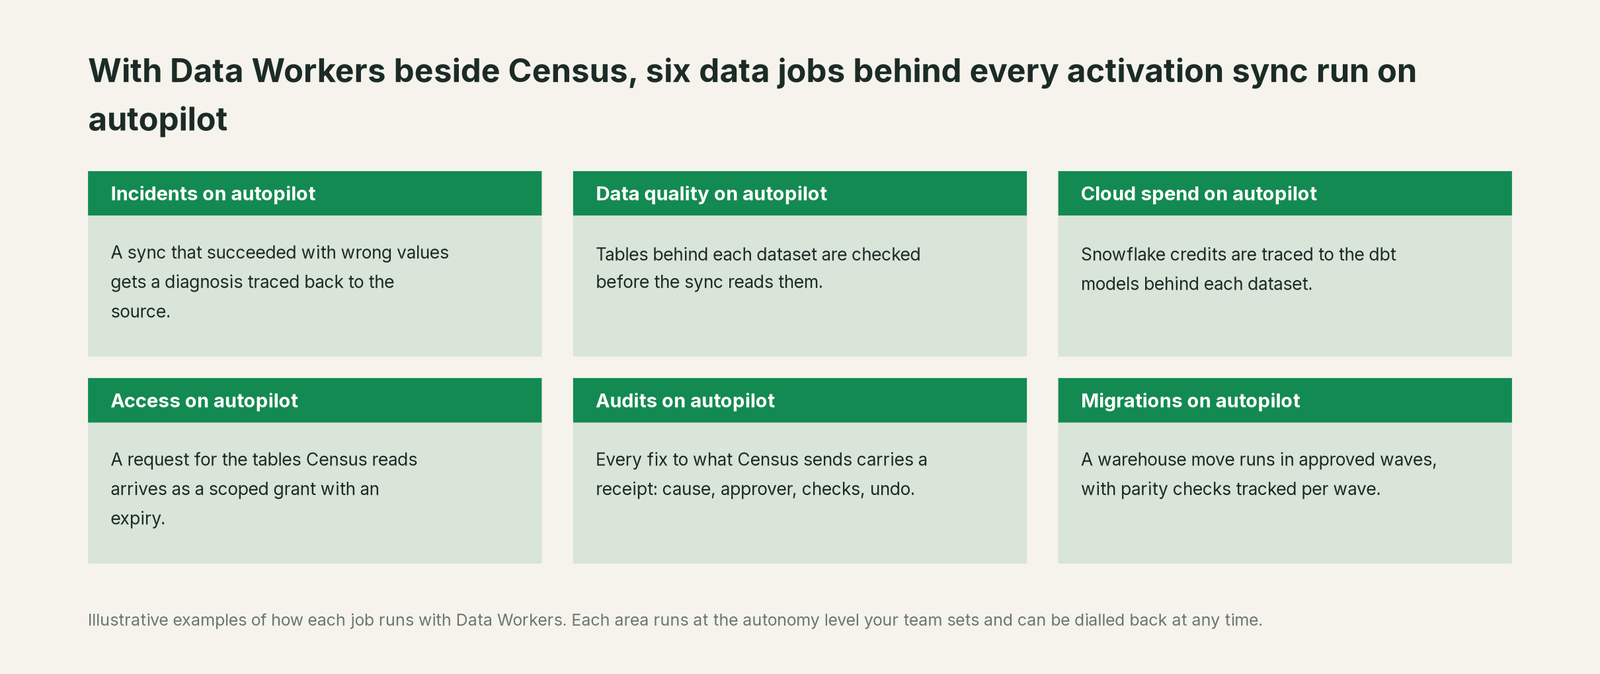
- •Incidents. A sync that succeeded with the wrong values gets a diagnosis traced back to the source change, with a fix proposal, before the next sync runs.
- •Data quality. The tables behind each dataset are checked for duplicates, nulls, freshness and volume on the schedule your team sets.
- •Cloud spend. Snowflake credits are traced to the dbt models behind each dataset, and fixes reach their owners drafted.
- •Access. A request for the tables Census reads becomes a scoped, time-boxed grant the data owner approves.
- •Audits. Every fix to what Census sends carries a receipt: cause, change, approver, checks and undo.
- •Migrations. A move to a new warehouse runs in approved waves, with parity checks planned and tracked per wave and a completion gate the owner signs.
RevOps changes most: a hold request arrives with its reason and its evidence, and most nights no hold is needed because the fix landed first. On accountability, read who owns the agents.
Keep Census, or consolidate?
Keep Census if you love it; Data Workers works with it from day one. Many teams consolidate once Data Workers runs that slice too.
For Census, keeping it is the norm: Data Workers doesn't send data to business tools, and your activation syncs are where reverse ETL lives. The move to Fivetran changes the bill and the console, not the job; Census Store and CSV uploads were sunset on August 1, 2026. What teams consolidate is the checking around Census: warehouse monitors that don't know which syncs read a table, dbt tests nobody connected to a CRM field, a runbook for pausing syncs by hand. With ingestion, transformation and activation now from one vendor, many teams also want an operating layer that stays neutral and covers every system the same way. The inbound half is in you're on Fivetran, the model layer in you're on dbt, the other reverse ETL path in you're on Hightouch and the CRM-side CDP in you're on Salesforce Data 360. Building the checks yourself? Read build it ourselves.
The case for your CFO
The outcome: seat counts, health scores, renewal dates and audiences reach your CRM, your lifecycle email and your ad platforms through Census, and customers and reps act on them the same day. Data Workers makes sure those numbers are right before they leave the warehouse, so an upstream change becomes a scoped fix in the afternoon instead of an apology email the next morning.
The risk story: at L1 Data Workers only reads; at L2 it changes nothing until a named person approves; at L3 it acts only on steps it can undo. Activation syncs, audiences and destinations stay with your team. An unanswered request expires and escalates, never auto-grants. No agent can promote its own work, and an org-wide stop halts all autonomous dispatch. Zero migration: Census, Fivetran, dbt, Snowflake and Salesforce stay put.
Why now: reverse ETL turned the warehouse into an operational system, and a wrong row now travels from a product database to a customer's inbox in one evening. You want one approval flow and one audit trail across that whole path. For the numbers, see the ROI of agentic data operations.
The first win is read-only: checks on the tables behind the one activation sync that reaches customers, usually Salesforce, plus the dbt lineage that feeds it. What stays the same: your syncs, schedules, audiences, dbt project and CRM.
The sentence to repeat upstairs: "Census sends our numbers to the field; Data Workers makes sure they're right before anyone acts on them, and shows us the receipt."
Getting started
Start with a pilot. Pick the activation sync whose values reach customers or revenue, usually the Salesforce Account sync, record it in the context graph against its model, connect Data Workers read-only to the warehouse tables and the dbt project behind it, and run at L1 so every flagged table gets a diagnosis, a blast radius and a proposed fix. Then move that domain to L2 so fixes arrive in Spellbook for a named owner. The pilot path and plans are on the pricing page, and the pilot is credited in full against the first year.
FAQ
Is Census still Census? Census joined Fivetran in 2025, and the product now ships as Fivetran Activations: datasets, activation syncs (what Census called syncs), Audience Hub and observability, inside the Fivetran console. The Activations V1 API keeps working during the transition; Fivetran plans to deprecate it and api.getcensus.com eventually.
Does Data Workers trigger, pause or edit activation syncs? No. Syncs, schedules, triggers and audiences stay with your team. When a hold is the safe move, Data Workers proposes it with the reason and the accounts involved, and your team sets the sync to Manual in Activations.
How does Data Workers know which syncs read a model? Through the dbt manifest and the context graph. Record each activation sync against the model it reads, and Data Workers traces any change from the source table through dbt to that sync; on a pull request, change review's lineage diff also reads the sync's dbt exposure. Activations connects over its API today, used by your team; Fivetran's MCP server has no Activations tools, and Data Workers works from the warehouse tables and dbt models the syncs read.
What changed with the move to Fivetran pricing? Month-to-month Census plans ended in March 2026. Annual plans continue until contract end, then usage moves to Fivetran's Monthly Active Rows, counted as unique rows per sync key each month. Data Workers is priced without a usage meter, so checking more syncs adds nothing to either bill.
Can it check Audience Hub segments? It checks the warehouse tables and dbt models those segments are built on, which is where a wrong segment usually starts. The segment definitions stay with marketing in Audience Hub.
Can we run it read-only? Yes. Start with read access to the warehouse tables and the dbt manifest behind your most important sync. Move the domain to L2 when the diagnoses have earned it.
Sources
- •Fivetran docs, Activations ("managed, automated reverse ETL pipelines without writing code"; datasets, syncs, Audience Hub, observability), https://fivetran.com/docs/activations (checked Oct 3, 2026)
- •Fivetran docs, Activations overview (hub-and-spoke model; least-privilege account; sync state schema in your warehouse), https://fivetran.com/docs/activations/overview (checked Oct 3, 2026)
- •Fivetran docs, Census Migration FAQ ("Census joined Fivetran"; month-to-month Census plans ended March 2026; MAR; plan mapping; activation syncs; workspaces; Census Store sunset August 1, 2026; V1 API), https://fivetran.com/docs/activations/census-migration-faq (checked Oct 3, 2026)
- •Fivetran docs, Activations triggering and scheduling (schedules, Manual, dbt Cloud job completion, Sequences, Airflow, Dagster, Prefect, API), https://fivetran.com/docs/activations/syncs/triggering-syncs (checked Oct 3, 2026)
- •Fivetran docs, Activations sync monitoring (logs, API Inspector, alerts), https://fivetran.com/docs/activations/syncs/sync-monitoring (checked Oct 3, 2026)
- •Fivetran docs, Activations datasets (warehouse tables, SQL, dbt), https://fivetran.com/docs/activations/datasets/overview (checked Oct 3, 2026)
- •Fivetran docs, Audience Hub, https://fivetran.com/docs/activations/audience-hub (checked Oct 3, 2026)
- •Fivetran docs, Activations AI model integrations (Dataset SQL Generation, AI Columns, your own model key, admin disable), https://fivetran.com/docs/activations/misc/ai-model-integrations (checked Oct 3, 2026)
- •Fivetran docs, Activations Salesforce destination (standard and custom objects, External ID identifiers, Update Only), https://fivetran.com/docs/activations/destinations/available-destinations/salesforce (checked Oct 3, 2026)
- •Fivetran blog, "Introducing Activations" ("the result of the integration of Census into Fivetran"; 200+ pre-built activations; Feb 2, 2026), https://www.fivetran.com/blog/introducing-activations-bridging-the-gap-between-data-and-action (checked Oct 3, 2026)
- •Census changelog (V2 API beta Sources endpoint with Fivetran Group IDs), https://whatsnew.getcensus.com/ (checked Oct 3, 2026)
- •TechCrunch, "Fivetran acquires Census to become end-to-end data movement platform" (May 1, 2025), https://techcrunch.com/2025/05/01/fivetran-acquires-census-to-become-end-to-end-data-movement-platform/ (checked Oct 3, 2026)
- •Data Workers open-source repository, https://github.com/DataWorkersProject/dataworkers-claw-community (checked Oct 3, 2026)
- •Data Workers client setup guide, https://dataworkers.io/opensource-docs/client-setup/ (checked Oct 3, 2026)