You're on Rivery: It Moves and Orchestrates Your SaaS and Database Data. Data Workers Owns Whether What Lands Is Right
Rivery, now Boomi Data Integration, moves and orchestrates your SaaS and database data. Data Workers owns whether what lands is right: it catches the problem, traces it and gets the fix approved.
Your team builds Data Flows. A Source to Target Flow pulls Salesforce, HubSpot, ad platforms or a production database into Snowflake, BigQuery or Databricks, with log-based CDC for the databases and auto mapping and schema drift handling so a new field never stops a load. Logic Flows (logic rivers, in Rivery's original vocabulary) chain SQL, Python, REST Action and Data Flow steps into one orchestrated run, and a reverse ETL step posts the results to the CRM or any REST API. Custom sources come from Blueprint, the low-code connector builder, or the Data Connector Agent. Environments keep dev and production apart, the Activity panel shows every run, and the bill is counted in BDU credits, which long-time users still call RPUs.
Rivery is now part of Boomi. Rivery announced the acquisition on its blog on December 19, 2024, and boomi.com now sells it as Boomi Data Integration (Rivery); rivery.io still carries the Rivery brand, and the docs live on Boomi's help site. The job is the same: Rivery moves and orchestrates your SaaS and database data. Data Workers owns whether what lands is right, traces it through dbt, BI and every system the data is sent back to, and gets the fix approved before anything downstream builds on it.
Key takeaways
- •Rivery keeps its job. Data Flows, Logic Flows, reverse ETL, schedules and environments stay with your team. Data Workers works on what those flows land and send.
- •Successful runs get checked too. Data Workers checks each landed table for nulls and volume and watches the metrics your team records, so a green run that landed the wrong rows becomes a diagnosed incident before the next step runs.
- •Connected over Rivery's REST API today. Data Workers reads the landed tables natively in Snowflake, BigQuery or Databricks, and the dbt project on top, among 50+ connectors.
- •Every fix goes through a named person. The owner approves the holds, the dbt diff and the rerun, and runs the Rivery side; each step leaves a receipt.
- •Autonomy is set per domain. Start at L1 observe, move to L2 propose, and open L3 act reversibly for narrow classes once the record earns it.
Rivery is the pipeline your data rides. Data Workers is the owner of whether it lands right.
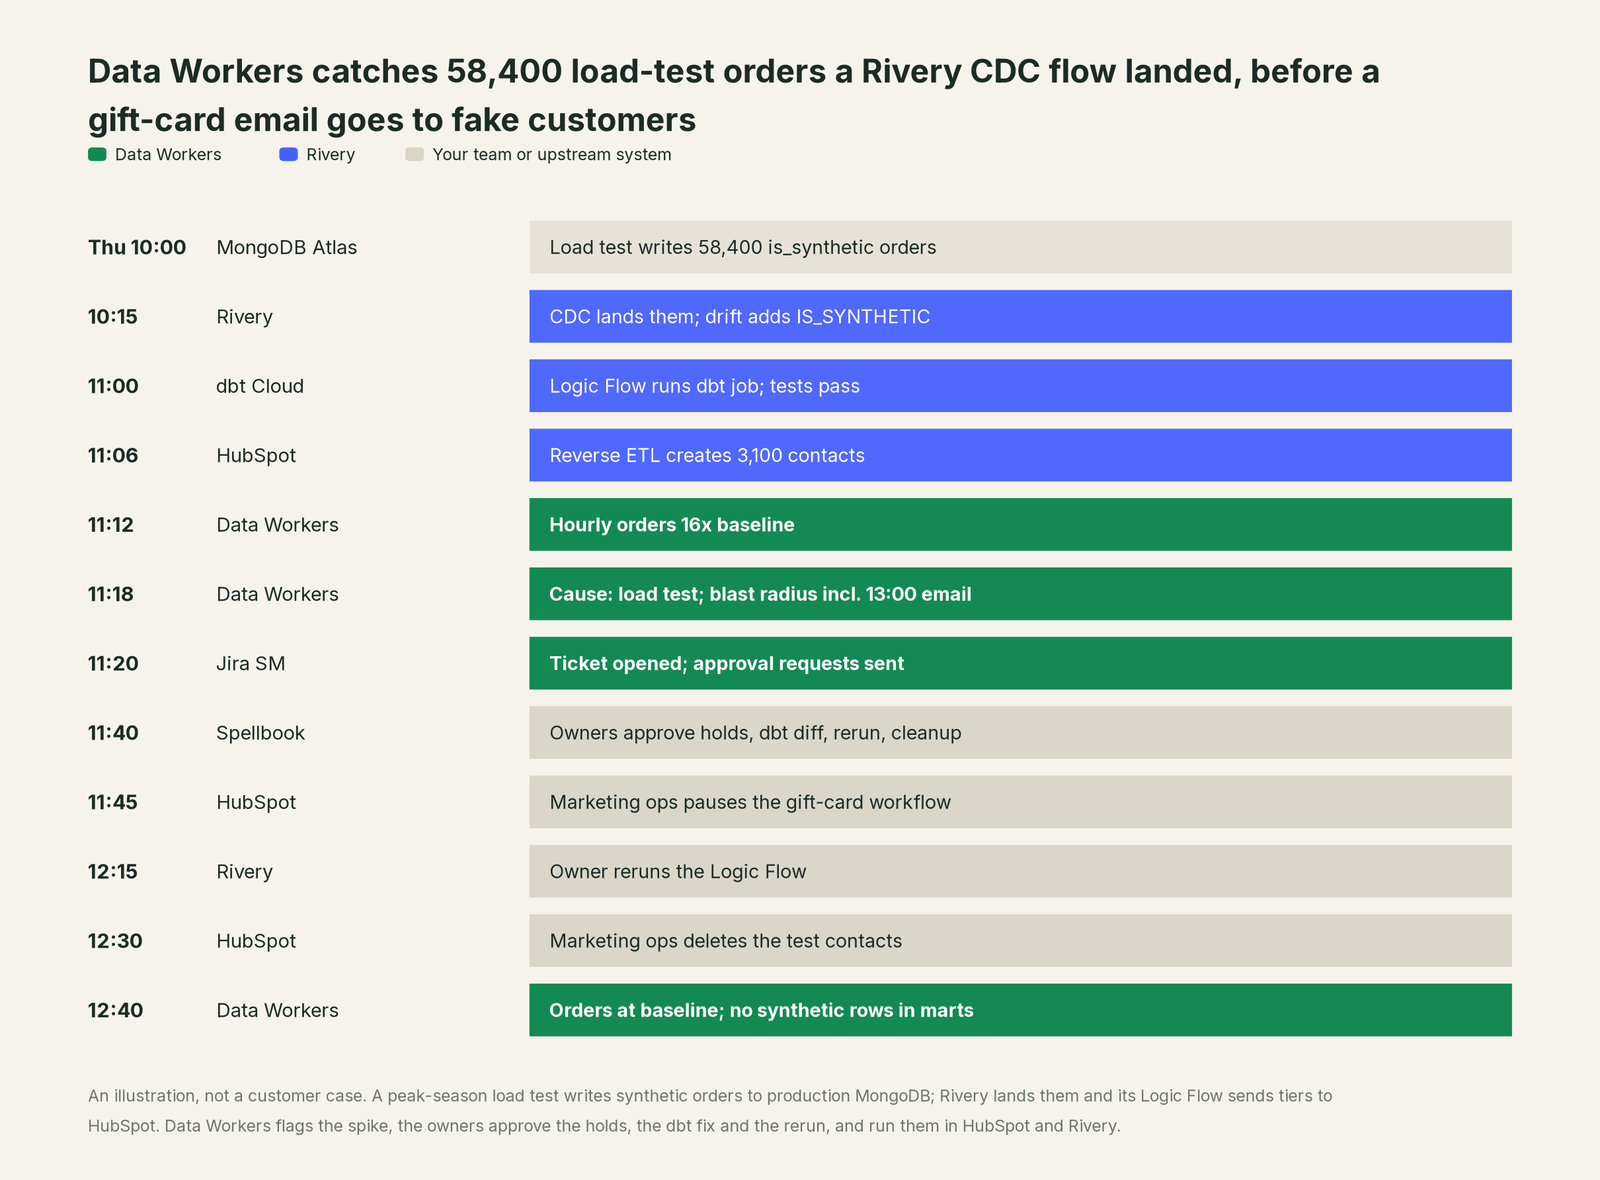
Rivery's job is to get data from every source into the warehouse, run the steps after it in order, and push the results back out, without stopping when a source changes shape. The job after the load is different: notice that a successful run landed rows that should never be there, find out why, size the damage, hold anything that would send the error to customers, get the cause fixed and prove the result. Here is one Thursday at a direct-to-consumer cookware brand. This is an illustrative example.
| Time | System | What happens |
|---|---|---|
| Thu 10:00 | MongoDB Atlas | Platform engineering starts a 90-minute peak-season load test against production checkout. The harness writes 58,400 orders from 3,100 test accounts on a loadtest email domain. Each order document carries a new field, is_synthetic: true |
| 10:15 | Rivery | The log-based CDC Data Flow from the orders and customers collections lands the changes in Snowflake RAW_MONGO.ORDERS and RAW_MONGO.CUSTOMERS. Schema drift handling adds an IS_SYNTHETIC column. Every run succeeds |
| 11:00 | Rivery + dbt Cloud | The Logic Flow commerce_hourly starts. Its REST Action step calls the dbt Cloud job hourly_marts, which builds fct_orders and dim_customers, including each customer's ltv_tier. The test baskets are large, so 2,240 test accounts come out Gold. Every dbt test passes |
| 11:06 | Rivery + HubSpot | The next step, a reverse ETL Action step that posts to HubSpot's contacts API, upserts ltv_tier by email. It creates 3,100 new contacts. A HubSpot workflow enrolls new Gold contacts in a thank-you email with a $25 gift card, sent at 13:00 |
| 11:12 | Data Workers + Snowflake | The hourly order count the team records reads 16 times its baseline for a Thursday morning. Data Workers opens an incident |
| 11:18 | Data Workers + dbt Cloud | The diagnosis, from a read-only query on the landed rows: every row behind the spike has IS_SYNTHETIC = TRUE and a loadtest email; real orders are on their normal curve. Blast radius from the dbt manifest and the team's context-graph notes: fct_orders, dim_customers, the Looker "Trading desk" dashboard and the HubSpot sync, with the gift-card email due at 13:00 |
| 11:20 | Jira Service Management + Slack | Data Workers opens a ticket with the diagnosis and sends approval requests in Slack to the Rivery owner in analytics engineering and the lifecycle marketing owner |
| 11:40 | Spellbook | The owners review five proposals: pause the gift-card workflow; turn off the commerce_hourly schedule; a dbt diff that filters synthetic rows in stg_mongo__orders and stg_mongo__customers, with a test that fails if one reaches a mart; a rerun plan; and the list of 3,100 test contacts to delete in HubSpot. They approve all five |
| 11:45 | HubSpot | Marketing ops pauses the workflow. No email has gone out |
| 11:50 | Rivery + GitHub | The Rivery owner turns off the Logic Flow schedule and merges the dbt diff |
| 12:15 | Rivery | She runs commerce_hourly by hand: the dbt Cloud job rebuilds the marts and the reverse ETL step pushes the corrected tiers |
| 12:30 | HubSpot | Marketing ops deletes the 3,100 test contacts from the list Data Workers built from Snowflake |
| 12:40 | Data Workers + Snowflake | Data Workers verifies: the hourly order count is back inside its baseline, no synthetic row reaches fct_orders or dim_customers, the Gold count matches the morning, and the owner reports the new test passing |
| 12:45 | Jira Service Management | The on-call engineer resolves the ticket, which links the Data Workers receipt: cause, approvals, runs, checks passed and the undo. The owner turns the schedule back on |
| 13:00 | HubSpot | Marketing ops resumes the workflow; the gift cards go to real Gold customers only |
| 14:00 | Looker | The trading desk reviews peak readiness on verified numbers |
Every part of Rivery did its job. Catching this takes knowledge Rivery was never meant to hold: that is_synthetic means the rows are not real, that dim_customers decides who gets a gift card, and that a HubSpot workflow will send money to anyone marked Gold at 13:00.
| Job | What Rivery does | What Data Workers does |
|---|---|---|
| The move | Runs Source to Target Flows from 200+ native connectors (Boomi's count), log-based CDC and custom sources built in Blueprint or with the Data Connector Agent | Reads what the flows land, natively in the warehouse; connects to Rivery over its REST API |
| The orchestration | Logic Flows run SQL, Python, REST Action and Data Flow steps in order, with containers, conditions and variables | Knows what each table feeds through the dbt manifest and the team's context-graph notes, so it sizes the damage before the next step runs |
| The signal | The Activity panel shows each run's status and logs; schema drift handling keeps loads green when a source adds a field | Watches the metrics the team records and runs warehouse checks on the landed tables, so a green run with wrong rows still raises an incident; a new column comes to it from the Rivery owner or the team's alert |
| The fix | Runs whatever Data Flows, steps and schedules the team configures | Proposes the holds, the dbt diff and the cleanup list to the owners, who approve and apply them |
| The send | Reverse ETL steps post warehouse query results to Salesforce, HubSpot or any REST API | Checks the model before the next send and proposes the hold when it is wrong |
| The proof | Keeps run activity, environments and deployment history | Re-checks the tables and writes a receipt: what changed, who approved it, how it was checked, how to undo it |
Why doesn't Rivery just do this itself?
Because Rivery is built to move and orchestrate data faithfully, and it made the right choices for that job. Schema drift handling exists so a source that adds a field keeps loading; a load that stopped for every new column would be a worse product. CDC copies every change from the source log, because a replica that guesses which changes to skip is not a replica. A Logic Flow runs its steps in the order you built them, and a reverse ETL step sends what the query returns. None of those steps can know that a field called is_synthetic means a load test, or that a HubSpot workflow turns a tier into a gift card.
Rivery's AI features point the same way. The Data Connector Agent builds custom connectors for REST sources, and the Data Integration Copilot creates YAML templates for Blueprint. Both help your team build pipelines inside Rivery faster, and the Data Integration API automates console work such as running Data Flows. Across the Boomi platform, Agentstudio builds agents and the AI Gateway controls AI and MCP interactions; we cover that side in you're on Boomi.
Owning whether landed data is right across a production database, a warehouse, dbt, BI and a CRM is a different product: a context graph of every table and consumer, blast-radius scoping, named approvers, a recorded undo and receipts an auditor can read. That is Data Workers. More in is it safe to let AI agents change production data.
Every tool owns a slice. Data Workers covers the whole lifecycle
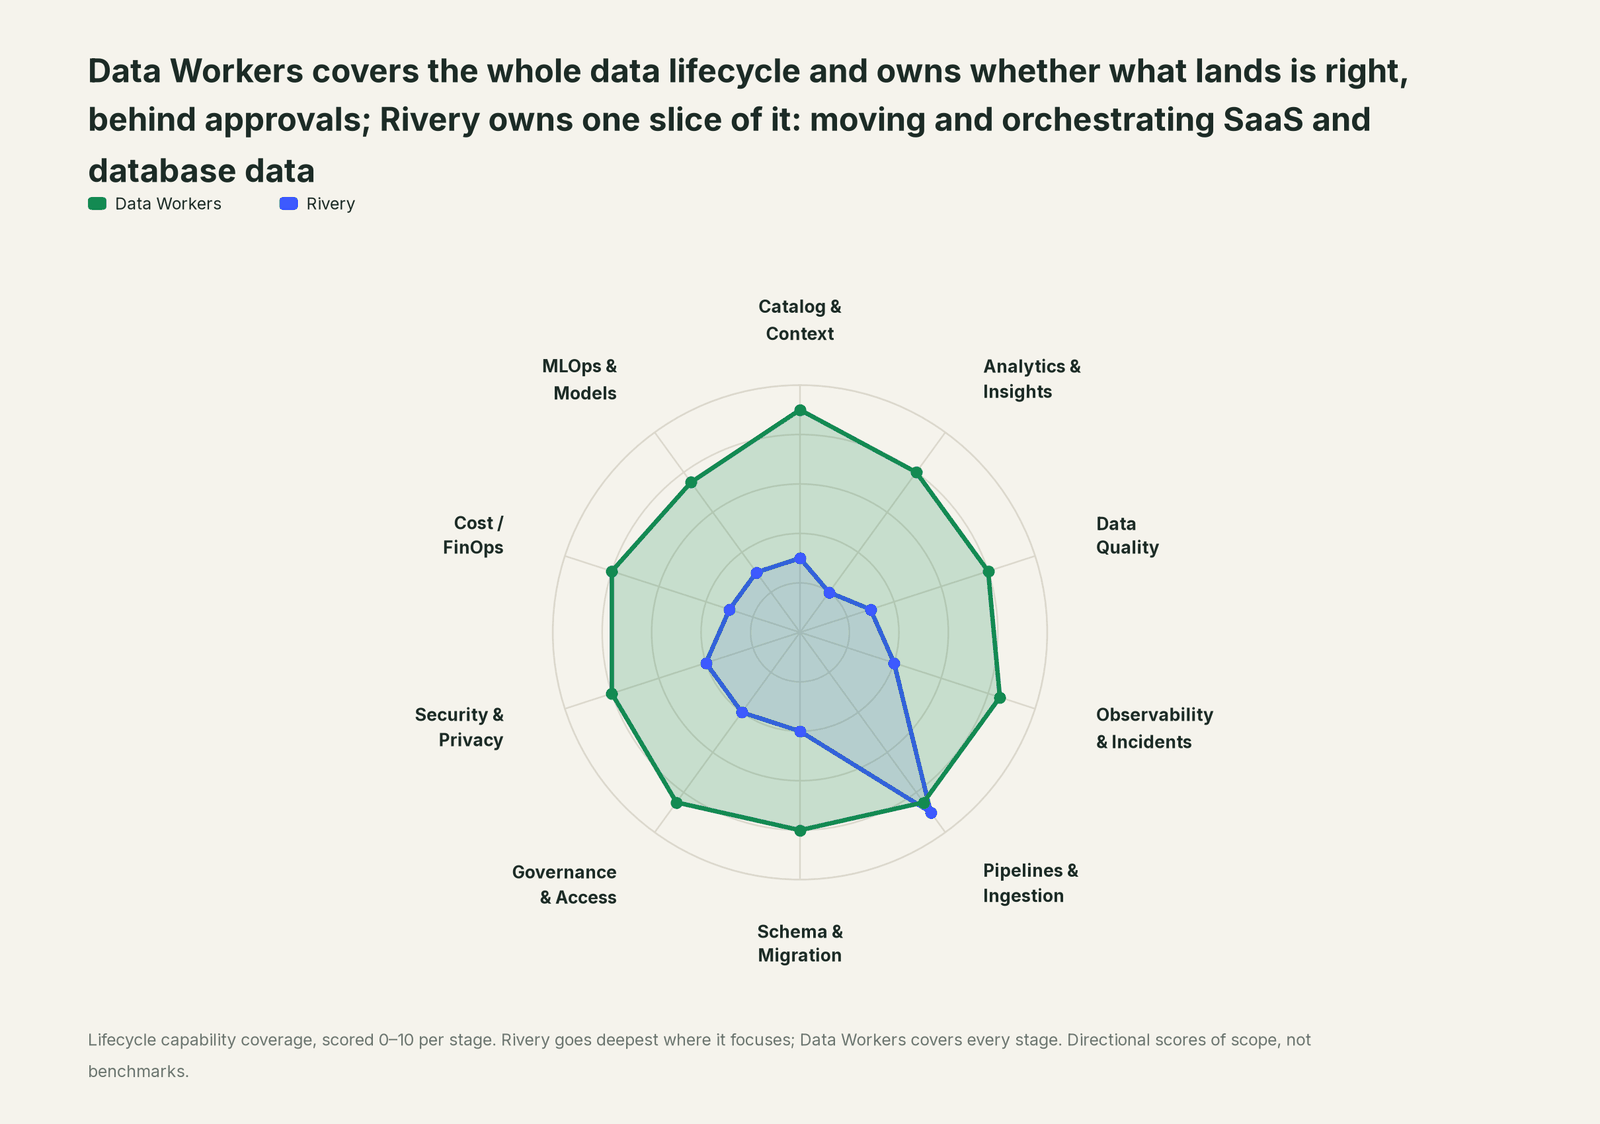
Each point tool adds another console, contract and handoff. Data Workers covers the whole lifecycle with one context, one approval flow and one audit trail, building on your Rivery Data Flows.
| Stage | Data Workers | Rivery | Why we scored it this way |
|---|---|---|---|
| Catalog & Context | 9 | 3 | Rivery keeps connections, Data Flows and variables per environment. Data Workers keeps one governed context graph of what each table means, who owns it and what reads it. |
| Analytics & Insights | 8 | 2 | Not Rivery's job: it lands and shapes the data, while business numbers live in BI. Data Workers answers data questions from governed definitions with lineage behind every number. |
| Data Quality | 8 | 3 | Logic Flow SQL and Python steps can hold a team's own checks. Data Workers checks nulls, uniqueness and minimum volume on landed tables, tracks lateness against a baseline your team records, flags recorded metrics that leave their baseline, and turns a miss into an incident. |
| Observability & Incidents | 8.5 | 4 | The Activity panel shows each run's status and logs. Data Workers diagnoses the data incident when every run succeeded, proposes the fix and verifies it. |
| Pipelines & Ingestion | 8.5 | 9 | Rivery's home stage: 200+ native connectors, log-based CDC, Logic Flows, reverse ETL, Blueprint and the Data Connector Agent for custom sources. Data Workers plans reruns for the owner. |
| Schema & Migration | 8 | 4 | Auto mapping and schema drift handling keep CDC and replication loading when a source adds a field. Data Workers traces the landed change through dbt, BI and everything that reads it. |
| Governance & Access | 8.5 | 4 | Environments, deployments and version control govern changes to the pipelines. Data Workers routes every data change to a named approver. |
| Security & Privacy | 8 | 4 | A fully managed SaaS with a European Platform Instance for data sovereignty secures the move. Data Workers leaves a receipt on every data change. |
| Cost / FinOps | 8 | 3 | BDU credits (also known as RPUs) meter the data volume moved and each Logic Flow execution. Data Workers attributes Snowflake credits to the dbt model behind them through query tags. |
| MLOps & Models | 7.5 | 3 | AI data pipelines feed AI apps and Boomi Agentstudio. Data Workers keeps the data under models and agents healthy. |
How Rivery and Data Workers work together
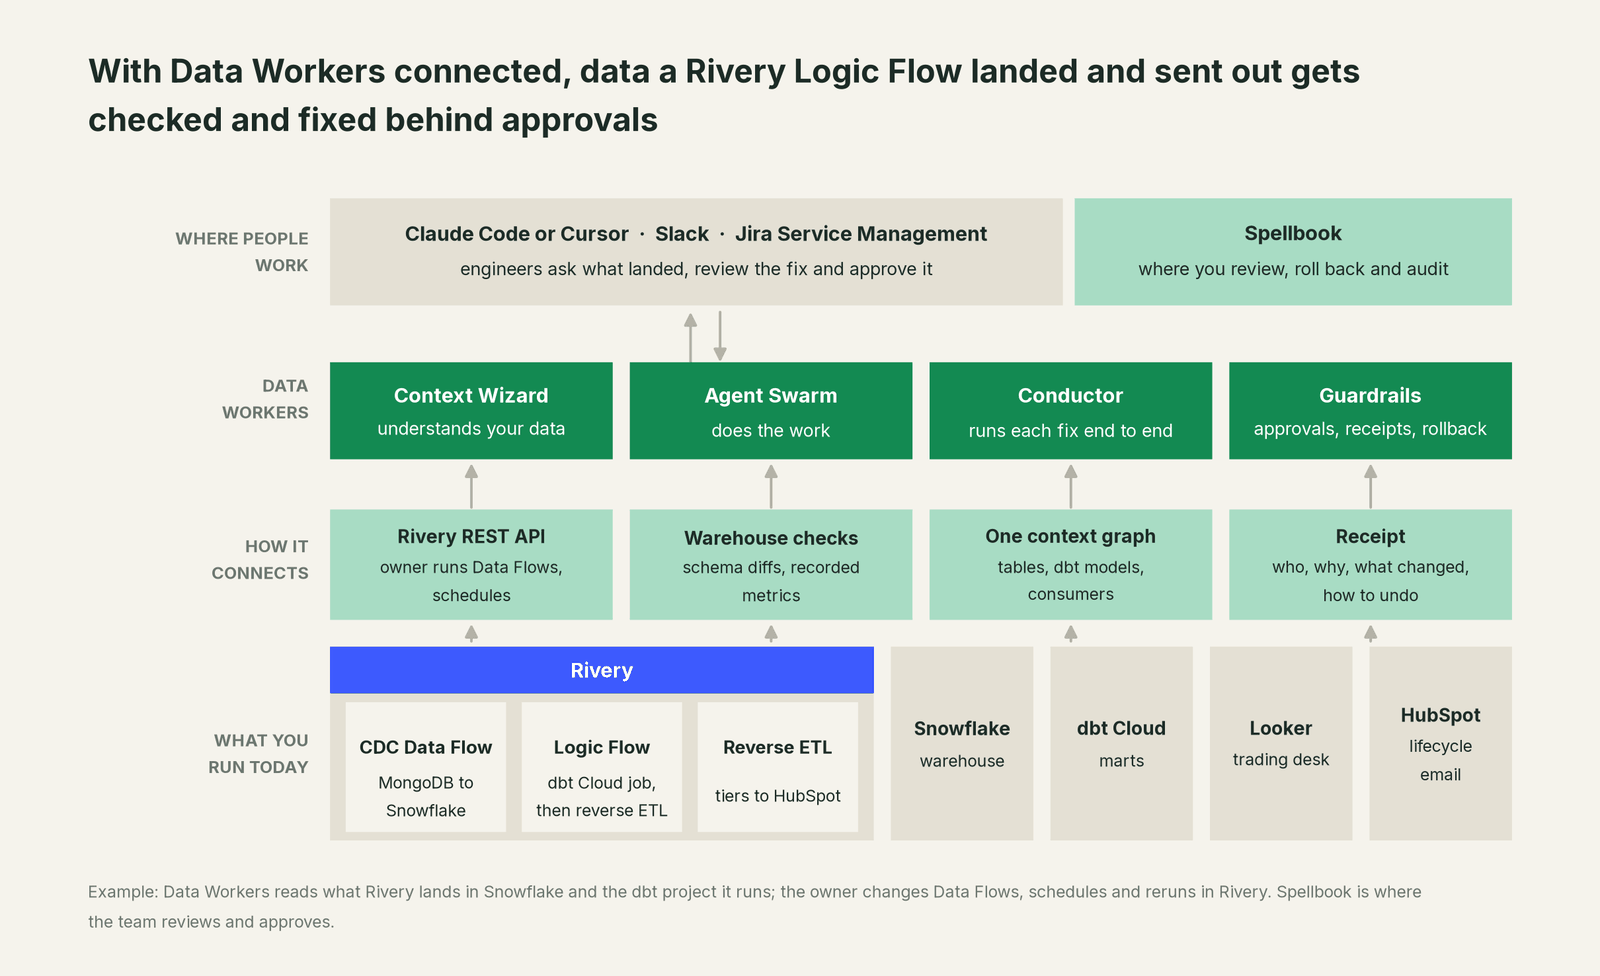
Data Workers connects to Rivery over its REST API today. What it needs from each run sits in the warehouse Rivery writes to, where landed tables, columns and row counts are objects it reads natively, and in the dbt project your Logic Flows run. Data Flows, Logic Flows, reverse ETL steps, schedules and environments stay with your team: Data Workers never runs, pauses or reruns a Rivery Data Flow and never writes to the systems your reverse ETL feeds. It proposes the hold, the rerun and the cleanup for the owner to carry out in Rivery or the destination tool. The rest of this incident runs on native connections: Snowflake, dbt Cloud, Looker (read), Jira Service Management, Slack and GitHub, among 50+ connectors. MongoDB Atlas and HubSpot connect over their APIs or MCP servers today. The full list is in what integrations Data Workers supports.
The Data Workers side follows the documented client setup: clone the open-source repo and add each agent's start-agent.sh entry to your client.
# Example: Data Workers agents in Claude Code, from a clone of the open-source repo
claude mcp add --scope user dw-incidents -- "$(pwd)/start-agent.sh" dw-incidents
claude mcp add --scope user dw-quality -- "$(pwd)/start-agent.sh" dw-quality
claude mcp add --scope user dw-catalog -- "$(pwd)/start-agent.sh" dw-context-catalog
claude mcp add --scope user dw-schema -- "$(pwd)/start-agent.sh" dw-schema
claude mcp add --scope user dw-connectors -- "$(pwd)/start-agent.sh" dw-connectors
List the tools with your client's own command (/mcp in Claude Code). In this incident: monitor_metrics (dw-incidents) tracks the hourly order count the team records against its baseline; diagnose_incident names the cause; blast_radius_analysis and trace_cross_platform_lineage (dw-context-catalog) map what the rows reached, with get_dbt_model_lineage (dw-connectors) reading the dbt side; create_jira_sm_ticket opens the ticket; run_quality_check (dw-quality) confirms row counts and keys on the rebuilt marts; remediate re-checks the quality assertions after the rerun and escalates any failure to a person. Its volume check is a minimum row count, so the spike comes from the recorded metric, and the guard against the next synthetic row is the owner's new dbt test.
In production the agents run in your infrastructure and hold the warehouse credentials and model key. Your data stays in your systems; the hosted Conductor sees workflow metadata only. More in where does our data go.
One incident, L0 to L4, set per domain:

- •L0 manual. On Friday, support asks why 2,240 gift cards went to addresses that bounce.
- •L1 observe. Data Workers flags the order spike and the new column at 11:12 with the cause and blast radius. Nothing changes.
- •L2 propose. Data Workers proposes the holds, the dbt diff, the rerun plan and the cleanup list; nothing moves until the named owners approve.
- •L3 act reversibly. For a class with a clean record, Data Workers re-runs its checks after each approved fix on its own and sends any failure to a person; dbt Cloud runs stay with the owner. Rivery schedules, reruns and HubSpot changes stay with the owners.
- •L4 autonomous. For a scoped domain, Data Workers checks landed tables on a short schedule, so the proposal is waiting before the next Logic Flow starts.
Who sets those levels: who owns the agents, how approvals work for AI data agents and autonomy levels L0 to L4 explained.
What changes for your team
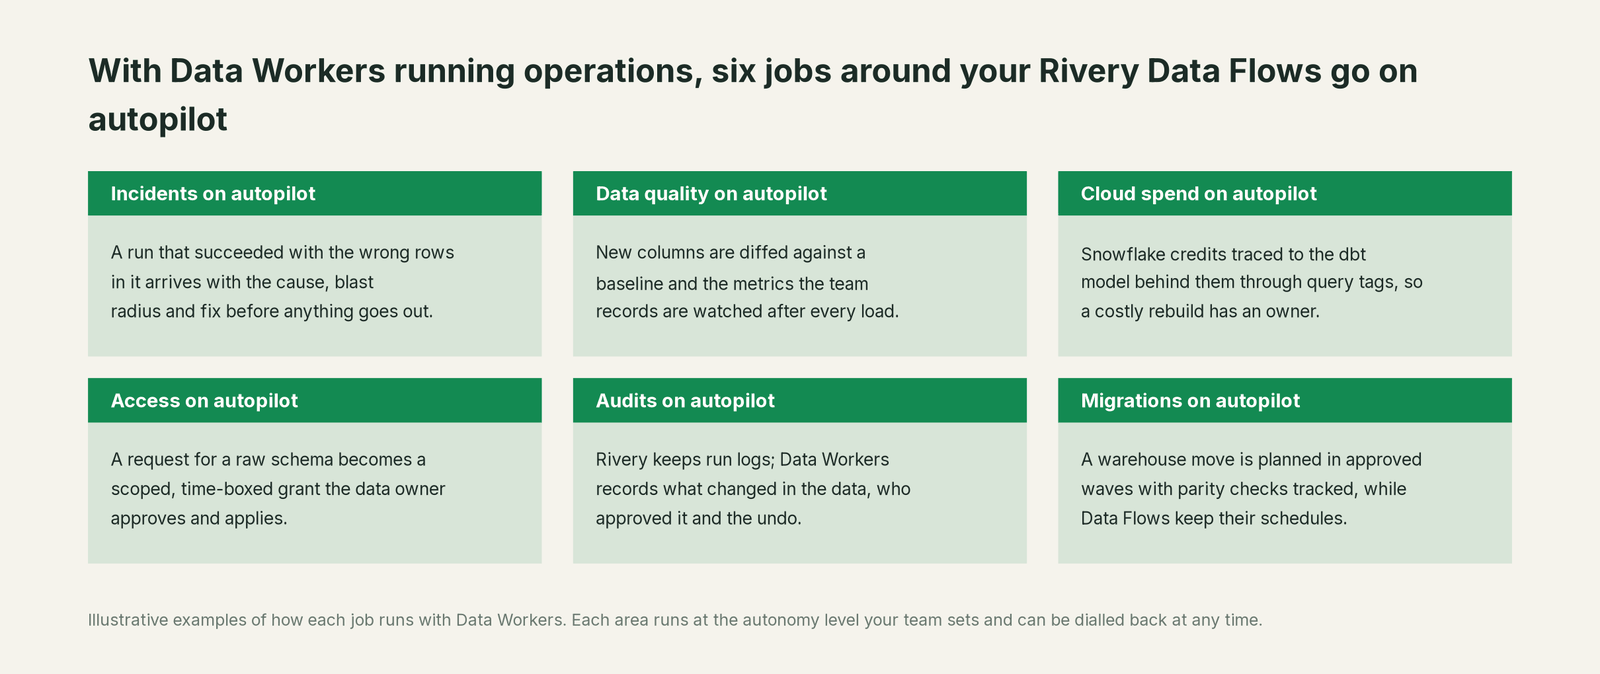
- •On-call starts from a cause. The ticket carries the rows, the damage, the fix and the rerun plan.
- •Reverse ETL gets a guard. When a model that a reverse ETL step sends to the CRM goes wrong, the hold is proposed before the next send.
- •Schema drift becomes a signal. A column drift handling adds quietly, once the Rivery owner or the team's alert hands it over, becomes a reviewed change with its downstream reach.
- •One record for data, platform and marketing. All three see the same incident and receipt in Spellbook Data Catalog (in preview), linked from the Jira ticket.
Running a separate monitoring tool? See Data Workers vs data observability. CDC background: change data capture explained and data ingestion vs ETL.
Keep Rivery, or consolidate?
Keep Rivery if you love it; Data Workers works with it from day one. Many teams consolidate once Data Workers runs that slice too.
For most Rivery teams the answer is keep it: one tool for ingestion, CDC, orchestration and reverse ETL, with no infrastructure to run, is hard to replace. What teams consolidate is the tooling around the landed data: a separate observability tool, hand-written check steps in every Logic Flow and "rerun it and eyeball the dashboard" runbooks. Many estates also run a second mover or sender: see you're on Fivetran, you're on Airbyte and, for reverse ETL, you're on Hightouch. If dbt holds your models, you're on dbt covers that side. One incident record spans them.
Weighing a build on the Data Integration API and a coding agent? Read build it ourselves with Claude Code and MCP servers: calling an API is easy; the context graph, approvals, undo and receipts are the work.
The case for your CFO
The outcome. When a Rivery flow lands rows that should not be behind revenue, customer tiers or anything your reverse ETL sends, it is caught right after the load and corrected before a customer, a campaign or a forecast acts on it.
The risk story. At L0 and L1, agents only read. At L2 they propose and a named person approves; an unanswered request expires and escalates, never auto-grants. At L3 they act on reversible changes inside the domains you open; L4 is a later choice per domain. Rivery and destination changes stay with their owners. No agent can promote its own work, and an org-wide stop halts all autonomous dispatch. Every change carries a receipt: what changed, who approved it, the blast radius and the undo.
Why now. Rivery now sits inside a Boomi platform that feeds AI agents as well as dashboards and CRMs, so a wrong row travels further before a person sees it.
The first win. L1 on the flows that feed money and customers: a load test, a backfill or a source change that lands the wrong rows becomes a diagnosed incident before the next reverse ETL send.
What stays the same. Nothing migrates: Rivery, your Data Flows and Logic Flows, your environments, your dbt project, your warehouse and your on-call rota. For the numbers, see the ROI of agentic data operations.
The sentence for upstairs: "Rivery moves our data and sends it back to our tools; Data Workers makes sure what lands is right and gets it fixed with our approval when it isn't, before a customer or a campaign acts on it."
Getting started
Start with a pilot. Pick the Rivery flows that feed the numbers leaders read and the systems your reverse ETL sends to, give Data Workers read access to the schemas they write, and run at L1 for a few weeks. Then turn on L2 for one domain, and open L3 for a narrow class once the receipts show the agents were right. The pilot path is on the pricing page, and the pilot is credited in full against the first year.
FAQ
Is Rivery still Rivery, or is it Boomi Data Integration now? Both names are in use. Boomi sells it as Boomi Data Integration (Rivery); rivery.io still carries the Rivery brand and the docs moved to Boomi's help site. Data Workers works the same with either: it reads what the flows land in your warehouse.
How does Data Workers connect to Rivery? Over Rivery's REST API today. Data Workers reads the landed tables natively in Snowflake, BigQuery or Databricks, plus the dbt project your Logic Flows run. Running Data Flows through the Data Integration API stays with your team.
Every run in the Activity panel succeeded. How can the data be wrong? Rivery reports whether it moved the data and ran each step. CDC copies every change the source made, including changes nobody meant for analytics, like the load test above. Data Workers checks what landed and what it means downstream.
Will Data Workers run, pause or rerun our Rivery Data Flows? No. Data Flows, Logic Flows, schedules and reruns stay with the owner, in the Rivery console or the Data Integration API. Data Workers proposes them in order with the reason, and at L3 re-runs its own checks after each approved fix; dbt Cloud runs stay with the owner.
Can Data Workers stop a bad reverse ETL send? It proposes the hold before the next send and names who approves it: the Rivery owner turns off the step or schedule, and the destination owner pauses anything that acts on the data. Data Workers never writes to the destination itself.
How is this different from the Data Connector Agent and Copilot? They help your team build pipelines in Rivery: the Data Connector Agent builds custom connectors for REST sources, and the Data Integration Copilot creates YAML templates for Blueprint. Data Workers works on what those pipelines deliver, across the warehouse, dbt, BI and the tools your data is sent to.
Sources
- •Boomi, Boomi Data Integration product page ("Boomi Data Integration (Rivery) makes it easy to build end-to-end ELT data pipelines quickly"; "200+ native data connectors"; Data Connector Agent; reverse ETL; Agentstudio), https://boomi.com/platform/data-integration/ (checked Oct 3, 2026)
- •Rivery, homepage and product pages (Data Ingestion, Orchestration, Transformation, DataOps Management, CDC Replication, Reverse ETL, Data Connector Agent; "auto mapping, and schema drift handling"), https://rivery.io/ and https://rivery.io/product/data-ingestion/ (checked Oct 3, 2026)
- •Rivery, Reverse ETL (targets Salesforce, HubSpot, Tableau, Slack and any REST API), https://rivery.io/product/reverse-etl/ (checked Oct 3, 2026)
- •Rivery, MongoDB integration (CDC or standard extraction to Snowflake and other targets), https://rivery.io/integration/mongodb/ (checked Oct 3, 2026)
- •Rivery, pricing ("BDU credit = Boomi Data Unit (also known as RPU) credit"; credits per 100MB moved and per workflow execution), https://rivery.io/pricing/ (checked Oct 3, 2026)
- •Rivery blog, post on Boomi's acquisition of Rivery (published Dec 19, 2024), https://rivery.io/blog/boomi-acquires-rivery/ (checked Oct 3, 2026)
- •Boomi documentation, Data Integration Overview (updated May 28, 2026; release notes for July and August 2026; European Platform Instance), https://help.boomi.com/docs/Atomsphere/Data_Integration/Data_Integration_Overview (checked Oct 3, 2026)
- •Boomi documentation, Getting started with Data Integration (Data Flow types, environments, Kits, Activity panel), https://help.boomi.com/docs/Atomsphere/Data_Integration/GettingStarted/start-here (checked Oct 3, 2026)
- •Boomi documentation, Logic Flow overview (SQL, Data Flow, Action and Python steps; containers; variables), https://help.boomi.com/docs/Atomsphere/Data_Integration/Rivers/LogicRiver/LogicRiverOverview/logic-overview (checked Oct 3, 2026)
- •Boomi documentation, Blueprint (low-code YAML connector builder; Data Integration Copilot templates; updated Jun 2, 2026), https://help.boomi.com/docs/Atomsphere/Data_Integration/Blueprint/blueprint-intro (checked Oct 3, 2026)
- •Boomi documentation, Data Integration API overview (updated Aug 31, 2026), https://help.boomi.com/docs/Atomsphere/Data_Integration/RESTAPI/dataintegration-api-overview (checked Oct 3, 2026)
- •Boomi, homepage navigation (Agentstudio; AI Gateway "Control every AI & MCP interaction"), https://boomi.com/ (checked Oct 3, 2026)
- •Data Workers open-source repository (tool registrations in dw-incidents, dw-quality, dw-context-catalog, dw-schema, dw-connectors), https://github.com/DataWorkersProject/dataworkers-claw-community (checked Oct 3, 2026)
- •Data Workers client setup guide, https://dataworkers.io/opensource-docs/client-setup/ (checked Oct 3, 2026)