Best practices for agentic company and person data: a field guide for company and contact data teams
A B2B data business sells one promise: the record is true today. Customers test it with bounced emails, stale titles and account lists that change underneath them, and every opt-out has to reach every copy ever delivered. This field guide shows how to keep company and contact records accurate with agents, practice by practice. It covers morning fill-rate and bounce reporting, tracing a bounce spike to its source, versioned hierarchies, risk-based re-verification and deletion evidence, while people own the privacy decisions.
Every company and contact data business sells the same promise: this record is true today. Customers test it the cheapest way they can, by emailing the contacts and counting what bounces. People change jobs, companies are acquired and rename themselves, and nothing in your pipeline fails when that happens. The product just gets a little less true each day, and the customer finds out first.
The mandate for a Head of Company and Contact Data is commercial: raise fill rate, accuracy and freshness with every release, keep the opt-out and deletion record clean, and do it without a team that grows with the record count. The trap is that upkeep grows with every source and customer, and crowds out the new fields and segments the product exists to add.
Our view: that upkeep is repeatable, so agents should do it, and the decisions that carry privacy and customer exposure should stay with named people. This field guide is the companion to the team playbook. It follows a record through its working life and judges each practice by what it does to the data you sell.
The old world
It is 07:40 on a Tuesday. A customer success manager forwards a bounce report: one delivered segment, mid-market companies in one region, is bouncing at about twice its normal rate. The fill-rate dashboard is green, because the addresses are all there. They are just old. An engineer spends the day joining feedback to segments, segments to sources and sources to refresh dates, and finds the cause on Wednesday: one supplier's latest refresh re-sent addresses with fresh-looking dates. The weekly bulk file has already shipped. Meanwhile an acquisition of 300 subsidiaries is still a spreadsheet edit, and a deletion request from Friday is waiting on a search across tables, files and shares.
The new world
Same Tuesday with Data Workers. Quality Monitoring flagged the one segment whose bounces moved while fill rate did not, Incident Debugging traced it to the supplier refresh, and the Data Context & Catalog agent listed the two API products and the Wednesday file that carry the affected records. Autonomous Data-Conductor held those records out and sent the data product owner one decision: release after re-verification, or without them. She approved re-verification before nine, and the file shipped clean with a short note.
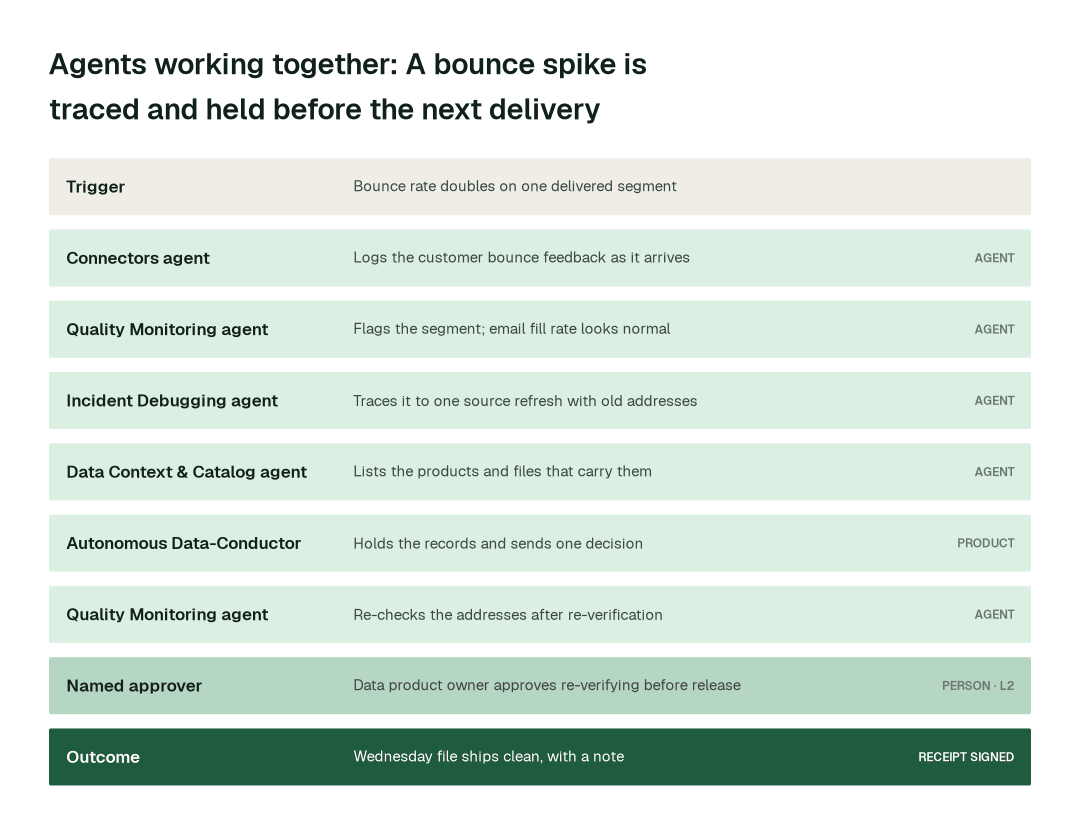
The rest of this report walks through the 7 practices that make that morning possible. At a glance:
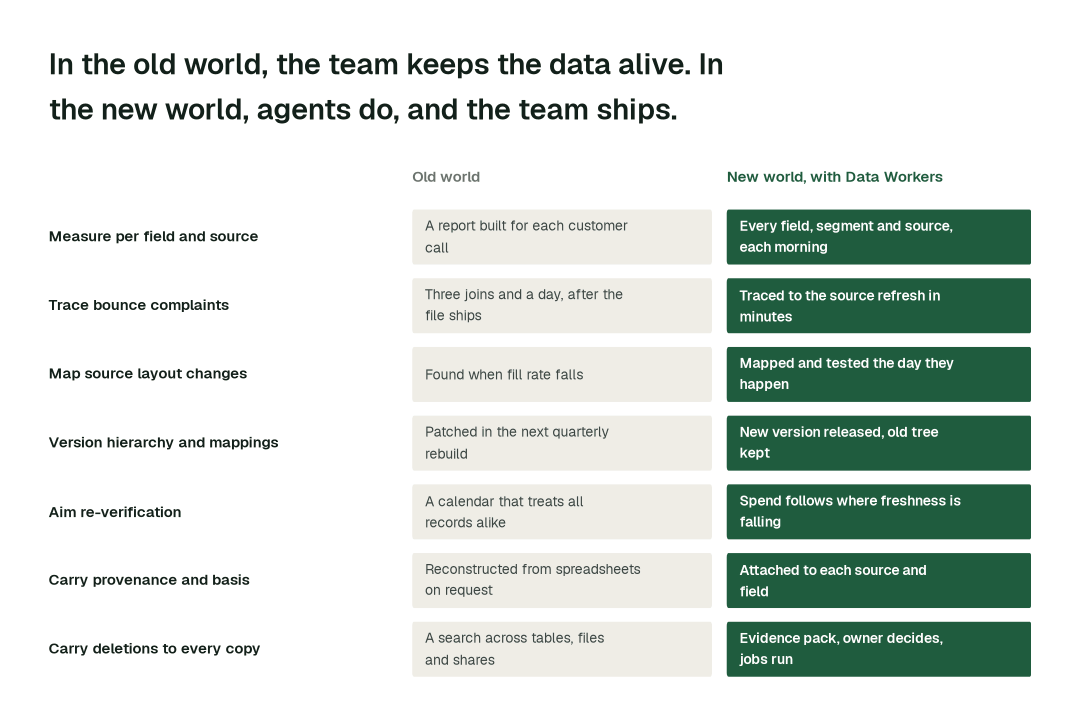
The practices, one by one
1. Measure the product per field and per source, every morning
A customer buys fields, not tables. A fill rate averaged across a table hides the job-title field that went quietly empty for one source.
Why it's harder than it looks: the measure is harder than the counting. "Verified email" means passed a check to sales and did not bounce to engineering, so the data sheet, the dashboard and the board deck drift apart. Splitting fill rate by source also needs lineage from every field back to the files behind it. The dimensions behind these measures are laid out in data quality dimensions.
- 1.The Data Context & Catalog agent records each measure you sell, such as "verified email" and "employee count band", with
define_business_rule, and ties each field to its sources withtrace_cross_platform_lineage. - 2.Quality Monitoring sets the commitment per field with
set_slaand runsrun_quality_checkevery morning by field, segment and source.get_quality_scoreshows the trend andget_quality_summaryreplaces the report built before each customer call. - 3.The data product owner approves any change to a definition the data sheet quotes. See data quality on autopilot.
2. Trace every bounce complaint to the refresh that caused it
Bounce rate is the metric customers trust most and the one you can least afford to chase by hand.
Why it's harder than it looks: the signal arrives per customer, the cause sits in one source refresh, and the fill-rate view that would normally catch a problem stays normal. Joining feedback to segment to source to refresh takes a day of an engineer's time, so the trace happens after the next file ships.
- 1.The Connectors agent registers each feedback load with
get_connector_status. - 2.Quality Monitoring calls
get_anomalieson bounce rate against fill rate, so a segment that moves on one and not the other is flagged. - 3.Incident Debugging splits the segment by source and refresh with
diagnose_incidentand names the cause withget_root_cause. - 4.The Data Context & Catalog agent runs
blast_radius_analysisto list the products, files and customers that carry the records. See data freshness monitoring and SLAs. - 5.Conductor holds the affected records and the data product owner approves one decision: release after re-verification, or without them.
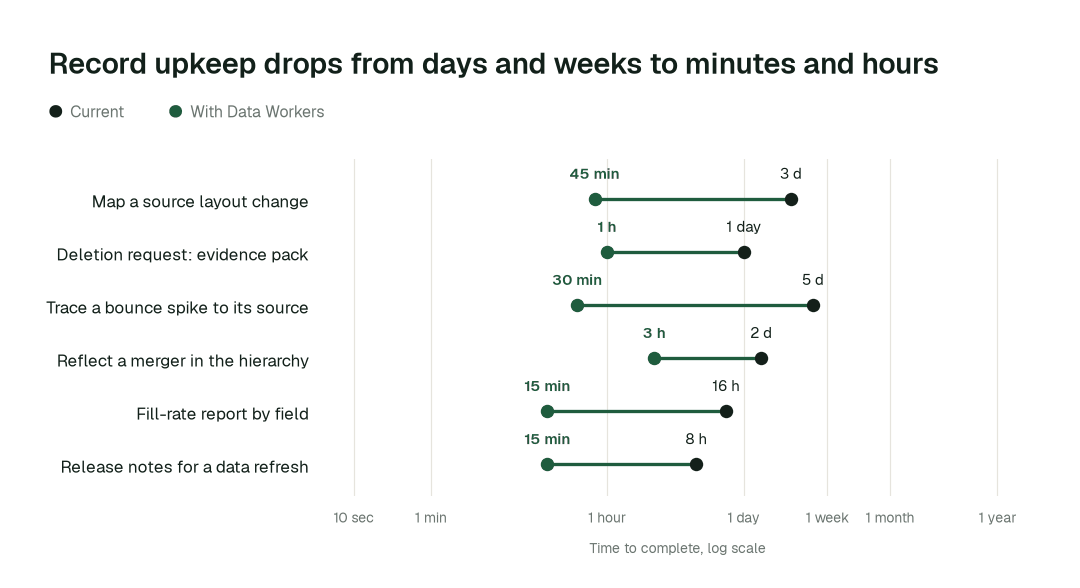
Practices like these compound. Across the routine work they cover, here is the difference in elapsed time:
3. Map source layout changes the day they happen
Sources rename columns, adopt a new industry code list or let a title field go quiet. Your acquisition team owns the supplier; this team owns what the change does to the record.
Why it's harder than it looks: a layout change rarely breaks a load. It lands nulls or unmapped codes, and the product degrades slowly enough that the first alarm is a customer.
- 1.Schema Evolution runs
detect_schema_changeon each delivery andassess_impactto list the fields, products and files affected. - 2.
generate_migrationdrafts the mapping with a rollback plan, and Quality Monitoring writes tests for it withcreate_quality_tests_for_pipeline. - 3.A data engineer approves any change that renames, removes or retypes a field, and
rollback_migrationreverses it if verification fails. Additive changes from known sources are where a source can earn L3. See schema changes that never break downstream and data contracts.
4. Version the hierarchy and the title and industry mappings
Customers who segment by ultimate parent build account lists on your tree. Title and industry mappings behave like code: "VP, Sales", "Vice President of Sales" and "Head of Revenue" must land in the same function and seniority, and a new variant must not move the old ones.
Why it's harder than it looks: a hierarchy edit changes what a customer has already bought, so the previous tree must be kept. After an acquisition of 300 subsidiaries, headcount and revenue must still roll up and no child can be left without a parent.
- 1.The Data Context & Catalog agent runs
blast_radius_analysison the old parent to list the products, feeds and customers that carry it. - 2.Pipeline Building drafts the change with
generate_pipelineas a new version, previous version kept, and tests it withvalidate_pipeline. - 3.Quality Monitoring runs
run_quality_checkon roll-ups, orphaned children and the function and seniority split of titles the change did not touch. - 4.The data product owner approves the diff, with the customers affected and a rollback point, before
deploy_pipelineapplies it.
5. Aim re-verification at the records most likely to have decayed
Re-checking every contact every few months treats a record that moved last week like one that has been stable for years, and the budget runs out before the segments customers care most about are covered.
Why it's harder than it looks: deciding where to spend needs freshness by segment, bounce feedback and job-change signals in one view, using the definitions your product sheet uses. Results then have to flow back through the same checks, or the freshness number in the sales deck and the one in the pipeline diverge.
- 1.The Data Context & Catalog agent measures last-verified date by segment against your promise with
check_freshness. - 2.Quality Monitoring joins it with bounce feedback through
get_quality_summaryand flags the segments where freshness is falling fastest. - 3.The Connectors agent schedules your existing verification runs on those segments with
trigger_airflow_dag. Your verification service still decides whether an address works. - 4.
run_quality_checkverifies the results and addresses that fail stay out of the release. The data product owner approves the verification budget.
6. Carry provenance and basis with every record
Customers' procurement teams, regulators and partners ask where a person's data came from and what basis it was collected under. Under the GDPR a company that obtains personal data from a source other than the person still has notice obligations (Article 14, regulation text).
Why it's harder than it looks: provenance is attached at the source and lost in the joins. The notice and basis live in contracts and privacy documents that never meet the pipeline, so the answer is rebuilt from spreadsheets on request.
- 1.Data Access & Governance runs
scan_piion the landing layer, and the Data Context & Catalog agent tags what it finds withauto_tag_dataset. See how Data Workers handles PII. - 2.
generate_documentationwrites a plain-English page per source and field with owner, definition and the basis your team records. - 3.
check_policyflags a field, or a proposed use, that the recorded basis does not clearly allow, andrequest_governance_reviewroutes it to the privacy owner.generate_audit_reportrecords who proposed, who approved and when. Supplier licence terms sit alongside, as in the sourcing field guide.
7. Hold opt-outs and deletions for a named owner, then carry them to every copy
Agents prepare the evidence and a person decides. Then the work is to reach every copy.
Why it's harder than it looks: a request is about one person and the answer is about copies. A GDPR controller that erases data must tell each recipient it was disclosed to, unless that proves impossible or disproportionate (Article 19), and California requires registered data brokers to check its deletion request platform at least every 45 days from August 1, 2026 (CPPA data broker page). Miss the extract copied for a data science project and the person reappears in the next refresh.
- 1.Data Access & Governance finds every table and field holding the person with
scan_pii. - 2.The Data Context & Catalog agent follows lineage with
trace_cross_platform_lineageto every product, feed and share, and your delivery records list the customers who received each file. - 3.
request_governance_reviewsends the privacy owner one request: where the data sits, what removal touches and the suppression change. - 4.After approval, the Connectors agent runs your existing suppression and deletion jobs with
trigger_airflow_dag,run_quality_checkconfirms the person is absent from the next build andgenerate_audit_reportrecords it. - 5.Cost Savings & Data Cleanup flags old extracts nobody reads with
detect_dead_assets, so no copy sits outside every deletion run. See DSAR automation and PII detection and masking.
Copies customers already hold are beyond an agent's reach; they are listed from your delivery records and flagged for the owner. By task class:
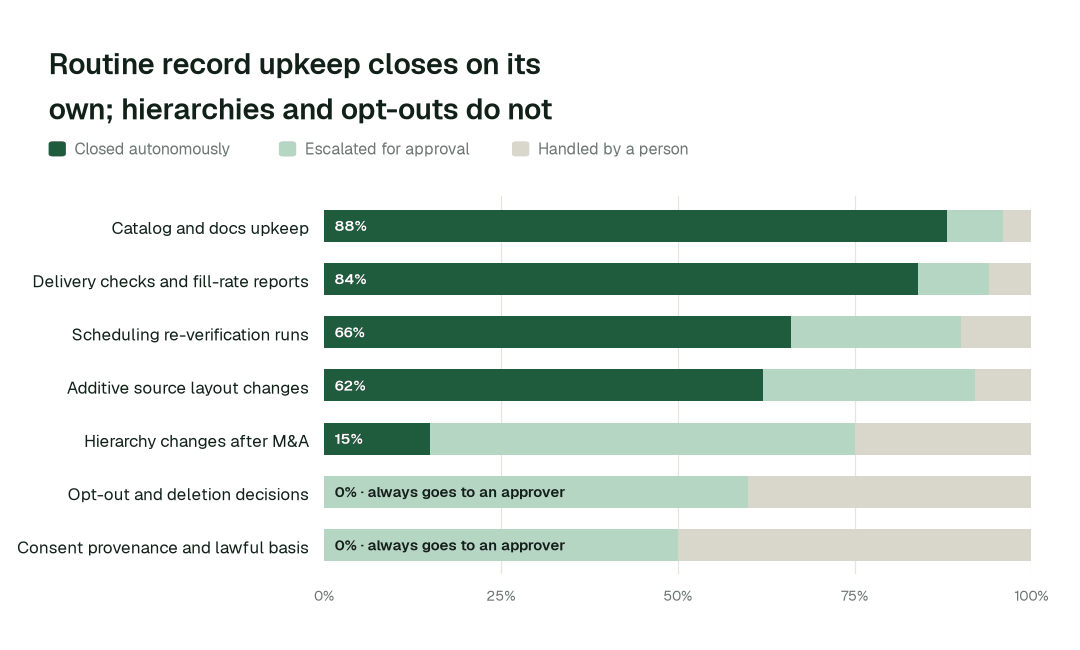
Catalog and docs upkeep closes autonomously 88% of the time. For opt-out and deletion decisions, autonomous closure is 0% by design.
Designing the autonomy ladder
Autonomy is set per task class and per source. L0 is off, L1 observes, L2 proposes and a person approves, L3 acts reversibly with a rollback point, L4 is fully autonomous. Every source starts at L1. L0 to L2 run today. L3 and L4 are where a domain can go on the evidence of its own review record ("On evidence" below), never a level reached by a date.
| Task class | L0 | L1 | L2 | L3 | L4 |
|---|---|---|---|---|---|
| Catalog and docs upkeep | Off | Shows gaps | Proposes updates | On evidence | On evidence |
| Morning fill-rate, bounce and freshness reports | Off | Reports on request | Proposes fixes for misses | On evidence | On evidence |
| Scheduling re-verification runs | Off | Shows where freshness falls | Proposes runs and budget | On evidence | Rarely |
| Additive source layout changes | Off | Detects and explains | Proposes mapping and diff | Known sources only | Rarely |
| Hierarchy and mapping changes | Off | Lists who is affected | Proposes a versioned diff | Rarely | No |
| Opt-out and deletion decisions | Off | Finds where data sits | Evidence to the privacy owner | No | No |
| Consent provenance and lawful basis | Off | Flags personal data | Holds it out and asks | No | No |
See the autonomy ladder for how a domain moves up.
The operating model: who owns what
Agents change who does the work, not who is accountable for it:
| Role | Owns | What the agents take off their plate |
|---|---|---|
| Head of Company and Contact Data | Standards, autonomy per field and source, which product goes next | Assembling status, building customer-call reports, chasing owners |
| Data product owner | Definitions, hierarchy releases, held-build decisions | Tracing which products, files and customers a problem reaches |
| Privacy owner | Opt-outs, deletions, consent and lawful-basis decisions | Searching for where a person's data sits and compiling the evidence |
| Data engineers | Reviewing agent proposals, building new fields and sources | Layout mappings, tests, reruns, documentation |
The swarm behind the practices
No single agent delivers these practices. Each one is a hand-off between specialists, coordinated under the autonomy you set per field and source.
| Agent | What it does on a company and person data team | Public tools it calls |
|---|---|---|
| Connectors and Data Ingestion | Land source files and bounce feedback, trigger your verification and suppression jobs | get_connector_status, trigger_airflow_dag |
| Schema Evolution | Detect and map source layout changes with a rollback | detect_schema_change, assess_impact, validate_schema_compatibility, generate_migration, rollback_migration |
| Pipeline Building | Build versioned hierarchy, title and industry models with tests | generate_pipeline, validate_pipeline, deploy_pipeline |
| Quality Monitoring | Measure fill rate, bounce rate and freshness per field and source | set_sla, run_quality_check, get_anomalies, get_quality_score, get_quality_summary, create_quality_tests_for_pipeline |
| Incident Debugging | Trace a bounce, coverage or freshness drop to its cause | diagnose_incident, get_root_cause |
| Data Access & Governance | Find personal data, route privacy decisions, keep the audit record | scan_pii, check_policy, request_governance_review, generate_audit_report |
| Data Context & Catalog | Document every field with source, definition and dependants | generate_documentation, trace_cross_platform_lineage, blast_radius_analysis, check_freshness, define_business_rule, auto_tag_dataset |
| Cost Savings & Data Cleanup | Find stale copies that still hold personal data | detect_dead_assets |
Data Context Wizard holds one governed definition of every measure you sell, from "verified email" to "ultimate parent", so a data sheet, a dashboard and an AI agent that reads your product answer alike. Autonomous Data-Conductor verifies the outcomes that matter before a release is delivered. Spellbook Data Catalog (in preview) gives each source and field a plain-English page: where it came from, what basis it was collected under and who owns it.
What disappears
- •The customer who finds the decayed segment before you do.
- •The fill-rate report built by hand for each customer call.
- •The hierarchy patched in the next quarterly rebuild.
- •The silent empty title field after a source layout change.
- •The deletion search across tables, files and shares.
- •The person who reappears in the next refresh.
What replaces them is quieter: a morning number for every field, every refresh checked on arrival, every privacy request at the owner with its evidence, and a signed receipt for each action so it can be rolled back.
A Head of Company and Contact Data's scorecard
Targets to bring to each quarterly review. They are targets to set, not results:
- •Fill rate per field, by segment and source: measured every morning against its commitment.
- •Bounce spike traced to its source: target about 30 min, from about a week.
- •Source layout change to verified mapping: target under an hour, from about three days.
- •Acquisition to hierarchy release: target the next release, with the previous tree kept.
- •Deletion request evidence pack: target about 1 h, from about a day, with no reappearance in the next release.
- •Freshness against customer promise: last-verified date by segment.
- •Upkeep closed autonomously, and its token cost: targeting 88% for catalog and docs upkeep as the deployment matures.
Where this goes next
Entity resolution decides which records are the same company or person, data delivery gets the product to customers and coverage and accuracy evaluation measures it. The family sits on the data businesses page. How a customer's sales team uses these records is covered in account intelligence.
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part was never knowing what to do but doing it. For company and person data teams:
- •Assisted. Agents propose each fix with a receipt; opt-outs, deletions and consent go to the privacy owner.
- •Autonomous, under your governance. Routine work runs on its own: refreshes checked on arrival, additive layout changes mapped, morning fill-rate and bounce reports, documentation kept current.
- •The agentic data business. A team that ships new fields and segments instead of repairing the last refresh.
The pilot: how company and person data teams start
The pilot proves the value on your own data.
- •What we connect. Your source drops, Snowflake or Databricks, dbt, Airflow or Dagster, your suppression list and the delivery layer, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Bounce-rate tracing and source layout changes on your highest-volume contact product, plus the evidence pack for deletion requests, at L2.
- •First week. Agents run at L1 on the scoped product: they profile every refresh, map lineage to delivered files and show the fixes and evidence packs they would have produced, before anything changes.
- •By week two. Delivery checks, morning reports and documentation upkeep run on reversible work. Layout and hierarchy changes and anything touching personal data stay at L2.
- •At day 30. We review against your baseline:
- •Source layout change mapped: from about three days to under an hour
- •Bounce spike traced to its source: from about a week to ~30 min
- •Deletion request evidence pack: from about a day to ~1 h
- •catalog and docs upkeep closed autonomously, targeting 88% as the deployment matures
- •What you decide. Whether to expand to the next product.
- •Guarantee. In a 90-day pilot, ten engineering hours per data engineer per week recovered against a baseline both sides sign on day one, or the $7,500 fee is refunded.
- •Cost. Start with a pilot ($7,500 one-time, a 6 to 12 week pilot, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
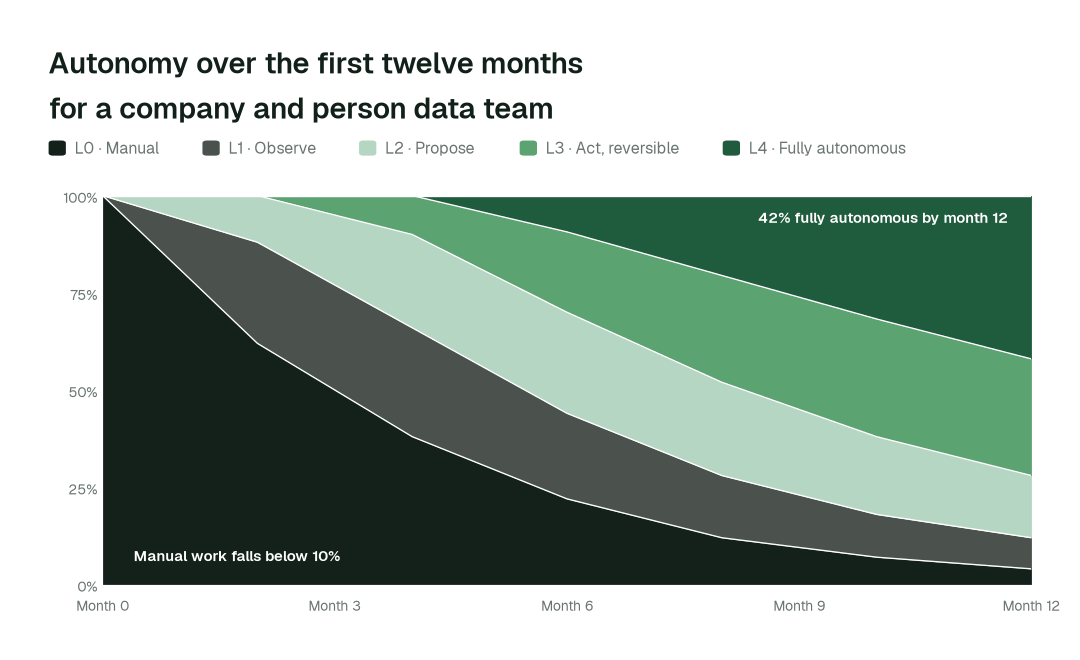
By month 12, more than 42% of agent actions run fully autonomously and manual work falls below 10%, while opt-outs, deletions and consent stay with the privacy owner.