Agentic data sourcing: a guide for data acquisition teams
Going fully agentic and autonomous does not mean pointing a chatbot at a folder of supplier files. For data acquisition and sourcing teams at data businesses, it means climbing from agents that assist, to agents that run the routine onboarding and upkeep under your governance, to a sourcing operation that largely runs itself: landing every new supplier in its own format, mapping layout changes the day they happen, measuring overlap and coverage per dollar, and keeping licence and consent provenance attached to every record, while people choose suppliers and sign terms. This is what that climb looks like, step by step.
Key takeaways
- •Who this is for. The team at a data business that finds, licenses, ingests and onboards new sources and suppliers, so the product the company sells keeps growing in coverage and staying fresh.
- •The problem today. Every supplier arrives in a new format, layouts change without notice and break ingestion silently, two suppliers cover the same entities and nobody can say which one adds coverage, and licence terms and consent provenance live in contracts and email instead of next to the data.
- •What changes. A new source is landed, profiled, checked and documented in a day. A layout change is mapped the day it happens. Every morning the team sees coverage, freshness and overlap per supplier, and every field carries its licence and provenance.
- •What stays with your people. Which suppliers to buy, what the contract says, and whether a source's consent and usage rights allow a use. Agents prepare the evidence; a named approver decides.
- •The result. More coverage and freshness for each dollar of licensing and engineering, and a sourcing team that spends its week finding the next valuable dataset instead of fixing the last one.
The PRD for agentic data acquisition and sourcing teams
This is the requirements document we would write with you for your team. Everything below expands on it.
| Who | Data acquisition, data sourcing, data partnerships, vendor management and data engineering teams at data providers, alternative data vendors, market data firms, location data companies and data marketplaces |
| The job | Add a source and know within a day what it did to coverage, freshness and cost. |
| Environment | Supplier SFTP, S3 and API drops; Snowflake or Databricks; dbt; Airflow or Dagster; an entity resolution layer; a contract or licence repository; the delivery layer (shares, feeds, marketplaces) that your customers buy through. |
| Constraints | Supplier selection, contract terms, licence and usage-rights decisions, and any use of personal data without clear consent always go to a named approver. |
| Success is measured by | New supplier to first clean load: from about two weeks to about a day; supplier layout change mapped: from about three days to under an hour; overlap report across two suppliers: from about a week to ~30 min; catalog and docs upkeep closed autonomously, targeting 88% as the deployment matures. |
| Owned by | A Head of Data Acquisition or Sourcing, with legal and the data product owner as named approvers. |
| Pilot scope | Onboarding two new suppliers, plus layout-change handling on the feeds you already run, at L2. |
What going fully agentic and autonomous means for data acquisition and sourcing teams
- •Put your data pipeline on autopilot. Supplier layout changes are detected and mapped into your raw and normalised layers the day they happen, so a renamed column on Friday does not become a coverage drop in your product on Monday.
- •Run the data back office without the busywork. The work that fills the week today moves to agents: profiling a sample file, writing the mapping, chasing a late delivery, building the overlap spreadsheet at renewal and filling in the source record by hand.
- •Scale data without scaling headcount. Fifty suppliers or two hundred, each new source gets the same profiling, checks, documentation and rights record, so the number of sources you can run grows without the team having to.
- •Get the plumbing off your plate. A sourcing team that negotiates, evaluates and chooses sources, rather than reformatting their files.
Who this is for
The team that turns the outside world into the raw material of a data product. At a B2B data provider, it finds company and contact sources and brings them in. At an alternative data vendor, it licenses panels, transaction feeds, web-derived signals and sensor data from suppliers and onboards each one. At a market data firm, it sources prices, filings and reference data from exchanges, regulators and contributors. At a location data company or a data marketplace, it signs up data partners and gets their datasets live for resale.
The titles: Head of Data Acquisition, Director of Data Sourcing, Data Partnerships Manager, Vendor Onboarding Lead, Data Acquisition Product Manager, and the data engineers and analysts who report to them. These leaders are measured on the commercial metrics of the product the company sells: coverage, accuracy, freshness, match rate, delivery and sell-through. Sourcing's job is to raise coverage and freshness per dollar of licensing and engineering. It sits upstream of the teams in the same family: entity resolution and unified profiles, company and person data, data delivery and feeds and coverage, accuracy and evaluation. The buy side has a mirror image in market and reference data, where banks consume the same vendor files, and sourcing overlaps with geospatial and marketplace data and people and labor-market data. All of them are gathered on the data businesses page.
The product you ship
- •The source portfolio: every supplier and dataset you license, with its owner, contract dates, licence terms, delivery schedule and cost, as a governed record rather than a folder.
- •Onboarding pipelines: the landing, profiling, mapping and checking that take a raw supplier file to a normalised, documented source ready to join your product.
- •Coverage and freshness gains: the measured effect of each source on how many entities, fields and regions you cover and how current they are.
- •Overlap and value analysis: which suppliers duplicate each other, which add coverage nobody else does, and what each costs per net new record.
- •Supplier scorecards: delivery on time, completeness, accuracy against a reference and stability of layout, used at renewal.
- •Rights and provenance metadata: for every source, what you may do with it, and for personal data, the notice and consent basis it came with.
Where the week goes
- •Every supplier arrives in a new format. CSV with a different delimiter, nested JSON, a zipped SFTP drop, a quarterly Parquet export, an API with its own pagination. Each one is a small integration project.
- •Layouts change without notice. A renamed column, a new code list, a changed date format or a field that goes quietly empty. Nothing fails; the product just gets worse.
- •Overlap hides in the middle. Three suppliers cover the same companies or places. The team cannot say which one adds coverage, and renewals are argued from the sales rep's deck.
- •Trial data is not production data. The sample looked complete. The first full delivery is thinner, later, or covers a different set of regions.
- •Licence and usage rights live elsewhere. Whether a field can be resold, redistributed or used to train a model sits in a contract. The data engineer who loads the file never sees it.
- •Consent and provenance are fragile. For personal data, where it came from, what notice was given and which uses were allowed has to travel with the record, and usually does not.
- •Freshness is a promise to customers. A supplier that delivers two days late makes your product two days stale, and you find out when a customer asks.
Add it up and upkeep is most of the team's week. Here is how a typical week splits today, and once agents own the back office:
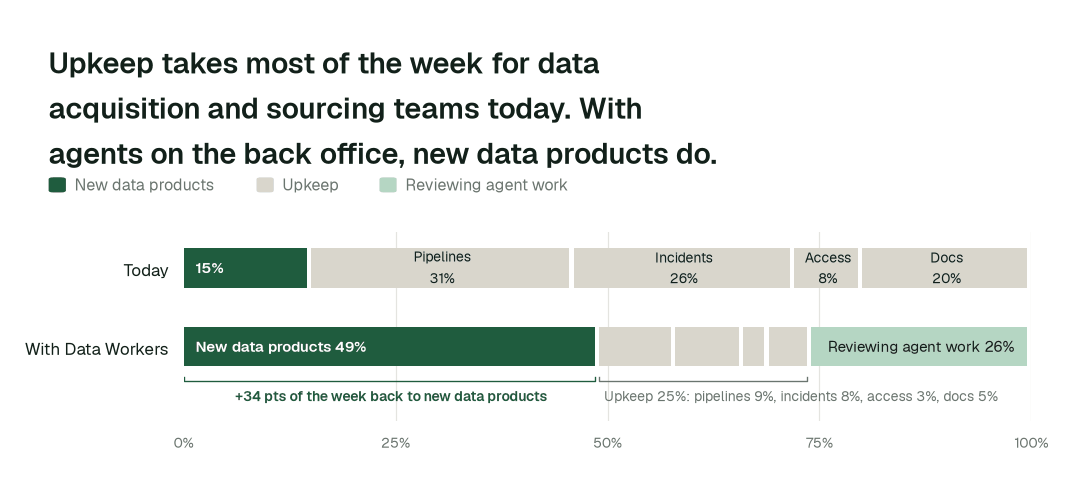
Time spent on new data products, which for this team means new sources and new coverage, moves from 15% of the week to 49%. Most of the rest becomes review: people steer and approve agent work instead of doing it by hand.
Then and now
| Work | Today | With Data Workers |
|---|---|---|
| New supplier onboarding | A project per supplier, weeks | Landed, profiled, checked and documented in a day |
| Supplier layout changes | Found when the product degrades | Mapped the day they happen, tested before the build |
| Overlap between suppliers | A spreadsheet built at renewal | Measured continuously, per supplier |
| Late or thin deliveries | Found by a customer | Caught on arrival, with the affected products listed |
| Licence and usage rights | In the contract, not the pipeline | Recorded against every source and field |
| Consent and provenance | Reconstructed on request | Carried with the data, reportable on demand |
These are the impact metrics we move for data acquisition and sourcing teams:
- •New supplier to first clean load: from about two weeks to about a day
- •Supplier layout change mapped: from about three days to under an hour
- •Overlap report across two suppliers: from about a week to ~30 min
Across the routine work in this domain:
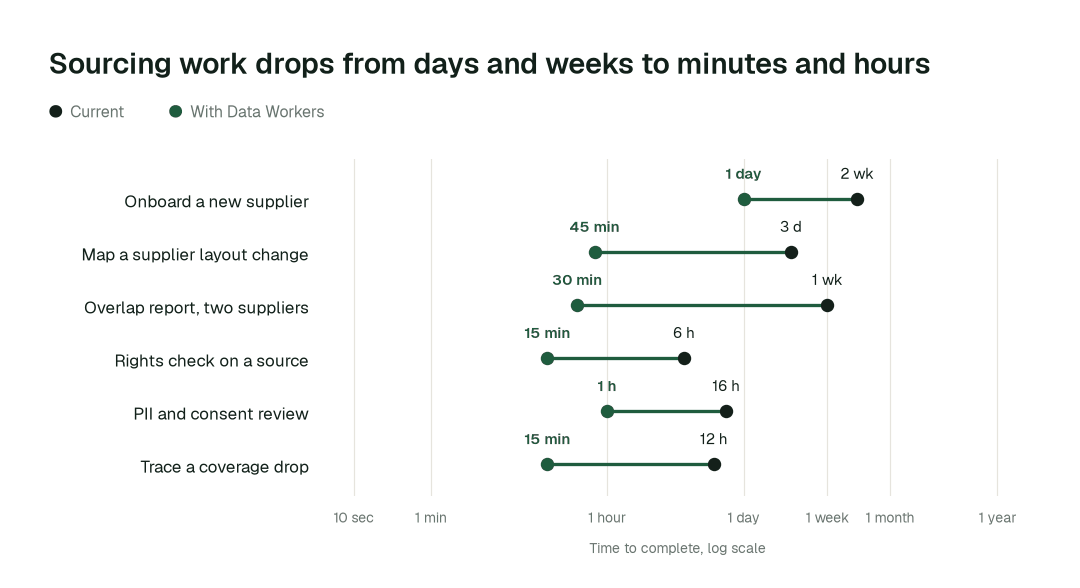
The biggest change is the overlap report across two suppliers: from about a week to ~30 min. Work that waited in queues finishes in minutes or hours, because agents detect, fix and verify in one pass.
Use cases, in depth
Onboarding a new supplier in a day
Today. The supplier sends a sample, an engineer writes a loader, someone profiles the columns by hand, the licence terms stay in an email thread, and the first full delivery turns up problems the sample never showed. The source reaches production weeks later, undocumented.
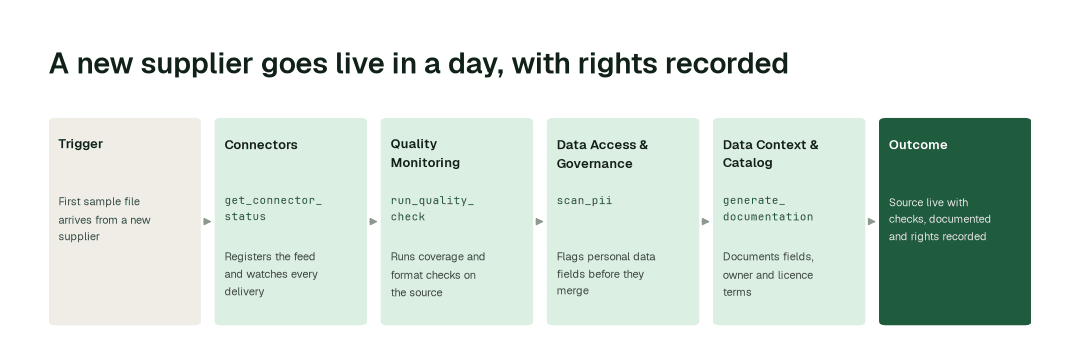
With Data Workers. The Connectors agent registers the feed and its delivery schedule. Quality Monitoring writes and runs coverage, format and range checks for the new source. Data Access & Governance flags personal data fields before they reach a shared layer, and the Data Context & Catalog agent documents each field with its owner and licence terms. The Data Ingestion agent lands and profiles every delivery, so the first full file is checked the same way as the sample.
What changes. A new source reaches the point where the team can decide whether to keep it within a day, with the evidence of what it added.
A supplier changes its layout without telling you
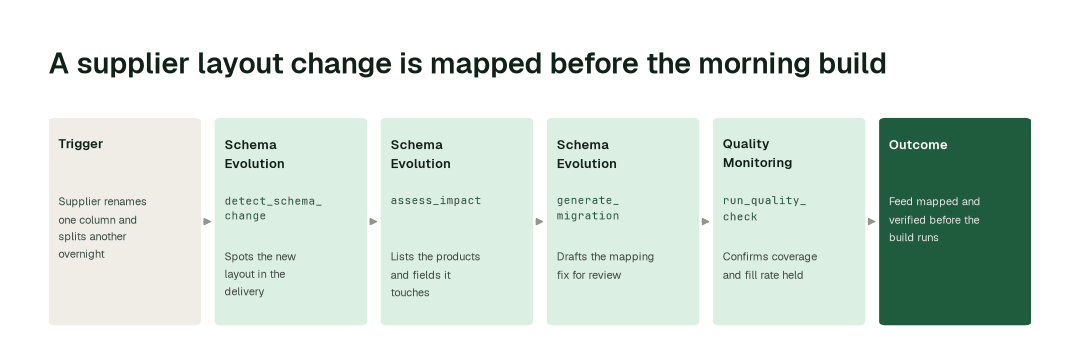
Today. A supplier renames a column and splits another. Ingestion keeps running and loads nulls. Fill rate on a field falls for a week before anyone notices, and the fix is a scramble across the supplier ticket, the pipeline and the customer-facing release notes.
With Data Workers. Schema Evolution detects the new layout in the delivery, shows the products and fields it touches, drafts the mapping and checks it for compatibility with the downstream model. Quality Monitoring confirms coverage and fill rate held. The change goes live as a reviewed diff with a rollback point.
What changes. The product does not get worse while the team finds out.
Renewal season: which supplier actually earns its fee
Today. Three suppliers cover overlapping companies, places or securities. At renewal the team assembles a one-off comparison, often by sampling, and the loudest account manager wins.
With Data Workers. The Data Context & Catalog agent traces every field in the product back to the suppliers that fed it, using lineage across the warehouse and the transformation layer. Quality Monitoring scores each supplier on completeness, freshness and stability. The Cost Savings & Data Cleanup agent finds sources whose data no product reads any more. The team opens renewal with net new coverage and cost per net new record for each supplier, and a list of feeds to drop.
What changes. Licensing spend follows the coverage it buys.
Measure the product, not just the pipeline
Sourcing leaders are measured on what the data product sells, not on how many files were loaded. The Autopilot dashboard shows how much of each source's upkeep runs on its own and at what token cost. Alongside it, the team can track what leadership cares about:
- •Coverage: entities, fields and regions covered, and the lift from each source.
- •Freshness: time from supplier delivery to a live product, against what you promise customers.
- •Accuracy: agreement with a reference set, and the share of fields that are populated.
- •Match rate: the share of supplier records that resolve to an entity in your product, which is where entity resolution picks up.
- •Delivery and sell-through: which sources reach customer feeds and which sold datasets depend on a source that is slipping, which is where data delivery and coverage and accuracy evaluation pick up.
Agents working together: a thin file on a Monday morning
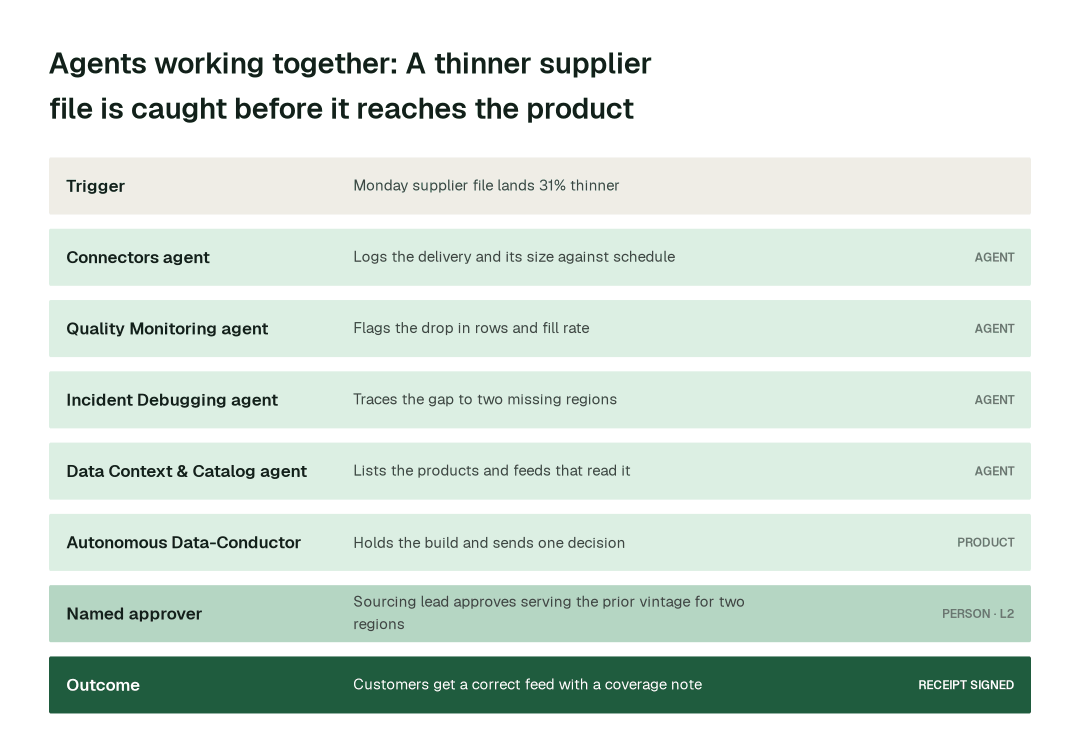
Every sourcing team has had this week. A supplier's weekly file arrives on time and in the right layout, so nothing fails. It is thinner than usual, because the supplier lost a data partner. The build runs, the product ships with a hole in two regions, and a customer is the first to notice. This is the same Monday run by Data Workers.
The setup
The team licenses a weekly consumer-panel file from one of nine suppliers. It feeds a regional product that is delivered to customers through a data share and a file feed on Monday morning. Autonomy in Autopilot:
- •Delivery monitoring, reruns and catalog upkeep: L2 today; a candidate for L3 on evidence.
- •Mapping changes from known suppliers: L2 today; additive changes can move to L3 on evidence, anything that renames or removes a field stays at L2.
- •Serving a prior vintage to customers, and supplier terms: L2, held for the sourcing lead.
The team scheduled one mission earlier: "Check every supplier delivery against its normal shape before the build."
05:30: the file arrives
The supplier drops this week's panel file on SFTP. The layout is unchanged.
05:32: log it
Connectors agent records the delivery against its schedule and notes that the file is 31% smaller than a normal week.
05:40: flag it
Quality Monitoring agent sees the row count and the fill rate on the region field both fall, concentrated in two of nine regions. The schema is intact, so no schema alert fires; the quality check does.
05:55: find the cause
Incident Debugging agent traces the gap to the two regions that are missing from the file and checks the supplier's delivery manifest. Those regions are absent upstream, not lost in ingestion.
06:10: see who is affected
Data Context & Catalog agent follows lineage from the file to the four products and two customer feeds that read it, and lists which customers receive the affected regions.
06:20: one decision
Autonomous Data-Conductor holds the Monday build for the two regions and sends the sourcing lead one decision, with the evidence and the options: serve last week's vintage for those regions with a coverage note, or publish as is.
07:00: approved
The sourcing lead approves the prior vintage for two regions and publishes the rest. Conductor applies it and drafts the query to the supplier. The affected customers' feeds carry a coverage note, so nobody finds the gap on their own.
11:15: the corrected file
The supplier sends a corrected file. The Connectors agent picks it up, Quality Monitoring confirms row count and fill rate are back in range, and Conductor refreshes the two regions and removes the coverage note.
What stays behind
- •A record of that delivery's shape, so the next thin file is compared with the same picture of normal.
- •A receipt for every change: who proposed it, who approved it and how to roll it back.
- •An updated Spellbook page for the supplier, with the incident attached.
- •A supplier scorecard entry for the renewal conversation.
Minute by minute
This is an illustrative example. The supplier file lands on SFTP; the product is built in Snowflake with dbt under Airflow and delivered to customers on Monday morning. Serving a prior vintage is at L2.
| Time | Who | What happens |
|---|---|---|
| 05:30 | Supplier | Weekly panel file lands, layout unchanged |
| 05:32 | Connectors agent | get_connector_status: delivery logged, 31% fewer rows |
| 05:40 | Quality Monitoring agent | get_anomalies: row count and fill rate down in two regions |
| 05:55 | Incident Debugging agent | get_root_cause: regions absent upstream, not lost in ingestion |
| 06:10 | Data Context & Catalog agent | trace_cross_platform_lineage: four products and two feeds affected |
| 06:20 | Spellbook Data Catalog | Build held for two regions at L2 with the evidence |
| 07:00 | Spellbook Data Catalog | Sourcing lead approves the prior vintage and a coverage note |
| 11:15 | Quality Monitoring agent | run_quality_check: corrected file back in range, note removed |
The agents on the job
| Agent | What it does on a sourcing team | Tools it calls |
|---|---|---|
| Connectors and Data Ingestion | Land supplier drops and API feeds, register each delivery against its schedule and profile every load | get_connector_status, trigger_airflow_dag, get_dbt_run_history |
| Schema Evolution | Detect and map supplier layout changes, show the blast radius and keep a rollback | detect_schema_change, assess_impact, validate_schema_compatibility, generate_migration, rollback_migration |
| Pipeline Building | Build the landing and normalisation pipelines for a new source, with tests, as a reviewed change | generate_pipeline, validate_pipeline, deploy_pipeline |
| Quality Monitoring | Check each delivery for shape, coverage and freshness and score every supplier over time | set_sla, run_quality_check, get_anomalies, get_quality_score, create_quality_tests_for_pipeline |
| Incident Debugging | Trace a coverage or freshness drop to the supplier, the pipeline or the change that caused it | diagnose_incident, get_root_cause |
| Data Access & Governance | Flag personal data, enforce the access that a source's terms allow and keep the audit evidence | scan_pii, check_policy, request_governance_review, generate_audit_report |
| Data Context & Catalog | Keep every source documented with owner, licence terms, lineage and the products that depend on it | generate_documentation, trace_cross_platform_lineage, check_freshness, define_business_rule |
| Cost Savings & Data Cleanup | Find sources and copies that no product reads any more | detect_dead_assets |
Data Context Wizard holds one governed definition of each coverage and freshness measure your company sells, so a supplier scorecard, a sales deck and a customer-facing data sheet quote the same number. Autonomous Data-Conductor verifies the outcomes that matter before a build is delivered and before a source is promoted into a product. Spellbook Data Catalog gives each supplier and dataset a page in plain English: what it is, what it covers, what you may do with it and who owns it.
What goes on autopilot
Once a source has earned it, this work runs on its own, and each item removes a problem your team deals with today:
- •Every delivery is checked against its normal shape on arrival, so a thin, late or empty file never reaches a customer feed unnoticed.
- •Additive layout changes from known suppliers are mapped and tested the day they happen, so a new column or code is carried through instead of discovered later.
- •Source pages, field documentation and lineage are kept current, so the answer to "where does this field come from and what can we do with it" is always on the page.
- •Unused sources and duplicate copies are flagged for retirement, so you stop paying to land data that no product reads.
Where your people stay in charge
Agents never get blanket access. Each source has its own autonomy level, set by you, and it only rises when the receipts show the agents are reliable. Everything starts at L1, observing only; reversible upkeep such as reruns, documentation and monitoring is usually first to run on its own.
- •Licence and usage-rights decisions go to a named approver. The agents show what the terms and the field metadata say; legal or the partnerships lead decides whether a use is allowed.
- •PII and consent provenance goes to a named approver. If a source carries personal data without a clear notice and consent basis, the agents hold it out of the shared layer and ask.
- •Supplier selection and contract terms stay entirely with people. Agents bring the coverage, overlap and cost evidence; they do not buy data.
Once a deployment has matured, here is how that ladder plays out across task classes:
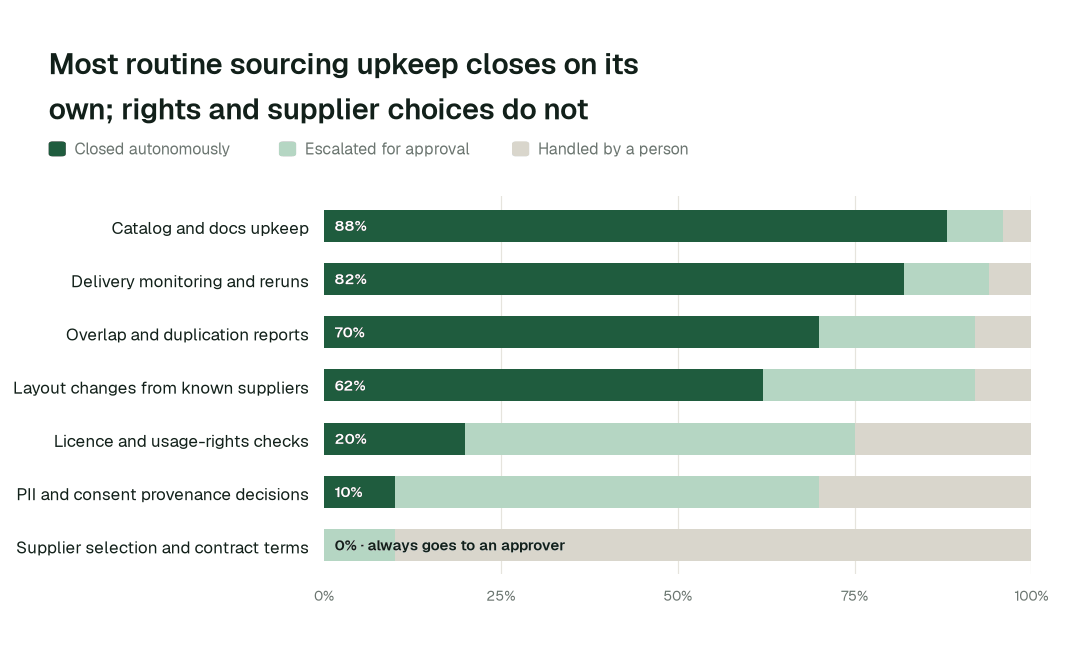
Catalog and docs upkeep closes autonomously 88% of the time. For supplier selection and contract terms, autonomous closure is 0% by design: agents prepare the evidence and a person decides.
What happens when an agent is wrong
- •At L2 propose, nothing changes until a named person approves. The proposal shows the full diff, the products it touches and how to roll it back. Unanswered requests expire and escalate.
- •L3 and L4 are where a domain can go next, on its own review record: acting on its own, with a rollback point on every change. Only the domain's owner raises its level, and if people start reverting the agents' changes, the domain pauses itself.
- •No agent approves or promotes its own work. Autonomy only grows on evidence, domain by domain, and repeated reverts pause the domain.
- •One org-wide stop halts all autonomous dispatch, and every action lands in a tamper-evident audit trail you can export with
generate_audit_report.
How it fits your stack
Data Workers connects to what you already run: supplier SFTP, S3 and API drops; Snowflake or Databricks; dbt; Airflow or Dagster; the entity resolution layer; your contract or licence records; and the delivery layer your customers buy through. Each agent is an MCP server, so the same agents work inside Claude Code, Cursor or Codex and in Slack or Teams through Spellbook. Over 50 connectors are available, and the Connectors agent can build a custom source connector from API documentation or a file format for a supplier nobody has a connector for. Nothing migrates.
- •Runs in your infrastructure with your credentials and your model key. The hosted Autonomous Data-Conductor sees workflow metadata only, never rows. That matters when the rows are a supplier's licensed data.
- •Uses the access you already govern. Agents act under scoped service identities and your existing roles; access to licensed or personal data goes through
check_policyand is logged. - •Fits a per-supplier data contract. Layout, freshness and completeness expectations for each supplier can be written down in an open format such as the Open Data Contract Standard, and agents enforce them on each delivery. See how agents enforce data contracts.
- •Proposes changes as diffs in your dbt project, orchestrator and warehouse, with blast radius, tests and a rollback point, and applies them only at the autonomy level you set for that source.
- •Open-source core. The Apache-2.0 community edition ships 11 agents and 160+ MCP tools, so your engineers can read exactly what the agents call.
For file-heavy feeds, the Data Ingestion agent lands messy files and survives re-runs without double-loading, and the Connectors agent keeps delivery status visible across every source. Freshness promises to customers are tracked the way described in data freshness monitoring and SLAs.
Governance and regulation
A data business is accountable for what it was allowed to take in and what it passes on. Licence terms decide what you may resell, redistribute or use for model training. For personal data, the law cares where it came from: under the GDPR, a company that obtains personal data from a source other than the individual still has notice obligations to that person (Article 14) and needs a lawful basis for each use. When a customer, a regulator or a supplier asks what a record is based on, the answer has to come from the pipeline, not from a search through contracts.
Data Workers keeps the rights and provenance metadata attached to each source, flags personal data with scan_pii before it reaches a shared layer, holds uses that the source terms do not clearly allow for a named approver, and records every change in a tamper-evident audit trail. See how Data Workers handles PII.
Data Workers doesn't make you compliant; your controls, people and assessors do. It supplies controls and evidence wherever agents touch data. Not legal advice.
The alternatives data acquisition and sourcing teams weigh
Build it yourselves. A strong team can wire a coding agent to MCP servers for the warehouse and dbt and generate loaders quickly. The work is everything around it: routing each decision to the right owner, blast radius, rollback, receipts, and a shared record of what every supplier's terms allow.
Ingestion tools and connector catalogs. Managed ELT and connector catalogs move files and API data well, and an agent can sit on top of them. They do not know a supplier's coverage last month, whether it overlaps another supplier, or what the licence says about a field. Data Workers takes their delivery signals, diagnoses what changed, proposes the fix, verifies it and leaves the receipt. See Data Workers alongside Fivetran and Airbyte.
Observability, catalogs and point tools. Observability alerts, catalogs document and quality tools test. Data Workers closes the gap between the alert and the fix and keeps the documentation and rights record current as a by-product.
Platform-native agents. Warehouse vendors' agents work well inside their platform. Sourcing crosses the supplier's drop, the orchestrator, the warehouse and the delivery layer, and Data Workers works across all of them.
In this space specifically. Data marketplaces and discovery tools help you find datasets to license. Data Workers is what runs after you sign: it brings the source in, keeps it correct and shows whether it earns its fee.
The case for your CTO
What this replaces. A project per supplier, silent breakage when a layout changes, renewal decisions made from a sales deck, and licence and consent facts held in contracts instead of the pipeline.
What your team gets back. A sourcing team that evaluates and negotiates for coverage instead of reformatting files, and a data product whose coverage and freshness improve every quarter.
Integration effort. Connecting is configuration, not a migration. The agents attach over MCP to the supplier drops, warehouse, orchestrator and dbt project you already run, under the roles you already govern, inside your own infrastructure. Your engineers can read every tool the agents call in the open-source core.
Risk and control. Autonomy is set per source. Everything starts at L1, observing only; reversible work moves up only when the receipts justify it; rights, consent and supplier decisions stay with a named approver; and one org-wide stop halts all autonomous work.
Why now. Customers buy coverage and freshness and compare data vendors on both. AI agents now consume data feeds directly, so a silent gap reaches more places faster.
The first win. Onboarding two new suppliers and handling layout changes on your existing feeds, at L2. The pilot below lays out the scope, what you see each week and the cost.
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For data acquisition and sourcing teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read every supplier feed, show what needs doing and propose every fix with a receipt; licence, consent and supplier decisions always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: every delivery is checked on arrival, additive layout changes are mapped the day they happen, and source documentation and lineage stay current. Your team governs the agents instead of doing the upkeep.
- •The agentic data business. A sourcing team that finds the next valuable dataset instead of fixing the last one. People set direction, and the platform carries it out.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how data acquisition and sourcing teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. Your supplier drops, Snowflake or Databricks, dbt, Airflow or Dagster, and the delivery layer, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Onboarding two new suppliers, plus layout-change handling on the feeds you already run, at L2.
- •First week. Agents run at L1 across the scoped feeds. They profile every supplier delivery, map lineage into your products and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Delivery checks on arrival and documentation upkeep start running on reversible work. Layout changes and anything touching rights or personal data stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •New supplier to first clean load: from about two weeks to about a day
- •Supplier layout change mapped: from about three days to under an hour
- •Overlap report across two suppliers: from about a week to ~30 min
- •the share of catalog and docs upkeep closed autonomously, targeting 88% as the deployment matures
- •What you decide. Whether to expand to the next set of suppliers. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, a 6 to 12 week pilot, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
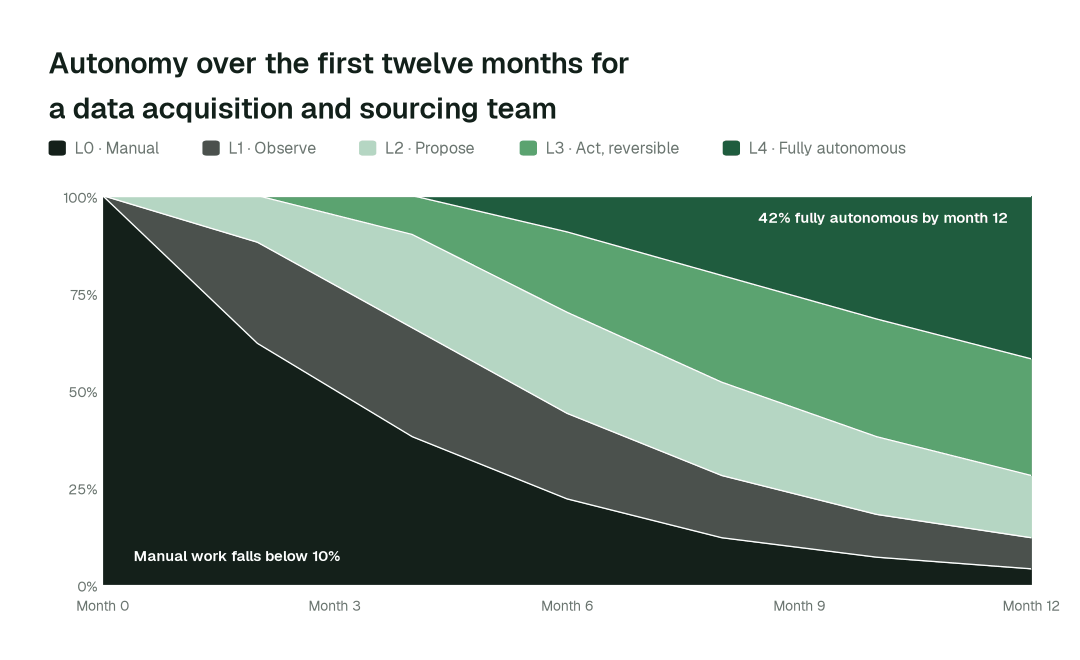
By month 12, more than 42% of agent actions run fully autonomously and manual work falls below 10%, while rights, consent and supplier decisions stay with a named approver.
FAQ
Does it work with the formats suppliers actually send? Agents land delivered files and API feeds from SFTP, S3 and HTTP sources, and can build a connector for a source that has none.
Will agents decide which suppliers we buy? No. They bring coverage, overlap, freshness and cost evidence; people choose and sign.
Can it tell us whether a field can be resold? It keeps the licence terms you record against each source and field next to the data and flags uses that the terms do not clearly allow. A named person makes the call.
How does it deal with personal data in a supplier file? It flags personal data fields before they reach a shared layer and keeps the provenance you record with the source. Whether a use is allowed goes to a named approver.
Where do the agents run? In your infrastructure, with your credentials and model key. The hosted Conductor sees workflow metadata only.
Do we have to migrate anything? No. Your warehouse, dbt project, orchestrator, catalog and delivery layer stay where they are.
Sources
- •Data Workers pricing: https://dataworkers.io/pricing/
- •European Union, General Data Protection Regulation (Regulation (EU) 2016/679), including Article 14 on information to be provided where personal data have not been obtained from the data subject: https://eur-lex.europa.eu/eli/reg/2016/679/oj
- •Bitol, Open Data Contract Standard: https://bitol-io.github.io/open-data-contract-standard/