How financial crime and AML data teams go fully agentic and autonomous
Going fully agentic and autonomous does not mean letting an agent clear alerts or file reports. For financial crime and AML data teams, it means climbing from agents that assist, to agents that keep the monitoring data complete, current and traceable under your governance, to a data back office that largely runs itself: catching the missing field that drops transactions out of a rule, landing sanctions list updates, keeping customer data tied out and leaving the evidence examiners ask for, while named investigators make every decision on customers, alerts and filings. This is what that climb looks like, step by step.
Key takeaways
- •Who this is for. The data teams behind financial crime compliance at banks, fintechs and payment companies: the people who feed transaction monitoring, customer due diligence and sanctions screening, and who hand examiners the evidence.
- •The problem today. A core banking or payments feed changes, a field arrives empty or renamed, and a rule quietly stops seeing a product, a channel or a country. Nothing errors. The gap shows up in a model validation, an internal audit or an exam, long after the transactions went through unmonitored.
- •What changes. Every feed is tied from source to the monitored population every morning, rule-critical fields are checked on arrival, and a source change is mapped before the next monitoring run, so nothing drops out of scope without someone being told the same day. Sanctions and PEP list updates are landed and verified, and every alert can be traced back to the source record.
- •What stays with your people. Decisions on customers, alerts, cases and filings. Alert disposition, case closure, risk-rating overrides, exits and SAR or STR filing stay with named investigators and officers. So do changes to scenarios, thresholds and models. Agents keep the data complete and the evidence ready.
- •The result. A financial crime data team that can show, for any day and any alert, what was in scope, what data the rule saw and where it came from.
The PRD for agentic financial crime and AML data teams
This is the requirements document we would write with you for your team. Everything below expands on it.
| Who | Financial crime data, AML technology, KYC and customer risk data, sanctions screening data and model validation data teams at banks, fintechs and payment companies |
| The job | No transaction silently out of scope, and every alert traceable to source. |
| Environment | Core banking, payments hubs and card processors; a cloud warehouse such as Snowflake or Databricks; Airflow or Control-M; dbt; transaction monitoring, screening and case management platforms such as NICE Actimize, Oracle or SAS; KYC, entity resolution and list-provider feeds. |
| Constraints | Decisions on customers, alerts, cases and filings are never automated. Scenarios, thresholds and models go to their named owners. SAR and case data is the most restricted data you hold. |
| Success is measured by | Source-to-monitoring tie-out: from about a week to 10-15 min; Silent exclusion explained: from about a week to under 1 h; Alert evidence pack: from about 2 days to about 1 h; lineage and docs upkeep closed autonomously 86% of the time. |
| Owned by | A Head of Financial Crime Data, with the monitoring, screening and model owners as named approvers. |
| Pilot scope | Source-to-monitoring completeness tie-out on one product line at L2 for the pilot. |
What going fully agentic and autonomous means for financial crime and AML data teams
- •Put your data pipeline on autopilot. Source changes are mapped into the monitoring inputs before the next run, so a renamed field or a new channel code never turns into a blind spot.
- •Run the data back office without the busywork. The work that fills the week today moves to agents: hunting for why a rule stopped firing, reconciling feeds by hand and assembling lineage for every request.
- •Scale data without scaling headcount. New payment rails, new products and new list sources arrive without the data team growing with them, because tie-outs, field checks and documentation run on their own.
- •Get the plumbing off your plate. A financial crime data team that spends its time on better typology data and customer views instead of proving, again, that the data was complete.
Who this is for
The data side of financial crime compliance. At a bank, it sits between the BSA or AML officer, the technology group and the chief data office, and owns the pipelines that feed transaction monitoring, KYC and customer due diligence (CDD), sanctions and PEP screening and case management. At a fintech or payment company, it is often a small team that has to satisfy a sponsor bank, a regulator and an auditor with the same data. The titles: Head of Financial Crime Data, Director of AML Technology, KYC Data Product Owner, Sanctions Screening Data Lead and Model Validation Data Analyst.
These teams do not make the decisions that compliance exists to make. They make sure the people who do are working from complete, timely and explainable data.
This playbook is one of the finance, insurance and investment data teams pages; the rest of that group covers the neighbouring teams you share data with.
The shift
Monitoring and screening systems are only as good as what they are fed. A scenario that depends on counterparty country does nothing for the transactions where that field is empty, and it does not report that it did nothing. Regulators and international bodies describe the same expectations from different angles: customer due diligence and ongoing monitoring, records kept so transactions can be reconstructed, and suspicious activity reported to the authorities. The FATF Recommendations set these out as international standards, and in the United States FinCEN collects the resulting reports. Each of those expectations rests on data that has to be there, current and attributable.
Agents are well suited to the unglamorous half of that problem. They can compare what the source said happened with what the monitoring system saw, every day, across every feed, and tell a named person when the two differ. They cannot and should not decide whether an activity is suspicious. The line between the two is the design of this playbook.
The product you ship
- •The monitored population: every in-scope transaction, account and customer, with the fields each rule needs, delivered on time to the monitoring platform.
- •Customer and counterparty data: KYC and CDD attributes, beneficial ownership, customer risk rating inputs and the resolved identity of customers and counterparties across systems.
- •Screening data: sanctions, PEP and adverse media lists, loaded and versioned so you can show which list was in force on a given day.
- •Case management data: alerts, cases, dispositions and the link from each to its source records.
- •Filing data: the inputs behind SAR and STR submissions and the supporting records.
- •Model validation evidence: documented inputs, lineage, drift and change history for the models and rules that run on all of the above.
Where the week goes
- •A feed changes and nobody tells you. Core banking releases, a new payments rail, a processor migration or an acquired book arrive with new codes, renamed fields and different formats.
- •Rules lose coverage silently. Missing counterparty country, null channel codes and unmapped product types exclude transactions from scenarios without an error.
- •Lists change daily. Sanctions and PEP list updates, vendor file changes and alias handling all need to land correctly and on time, with the version recorded.
- •Entities do not resolve. The same customer appears under three identifiers, a counterparty under five spellings, and risk ratings are computed on the wrong record.
- •Lineage is assembled by hand. Every internal audit, model validation and exam request means tracing a number or an alert back to source in a spreadsheet.
- •Model risk evidence is a project. Validators need inputs, lineage, change history and drift evidence, and the data team assembles it each cycle.
- •Case and SAR data is locked down for good reason. Access requests are slow, and every grant needs a record.
Add it up and upkeep is most of the team's week. Here is how a typical week splits today, and once agents own the back office:
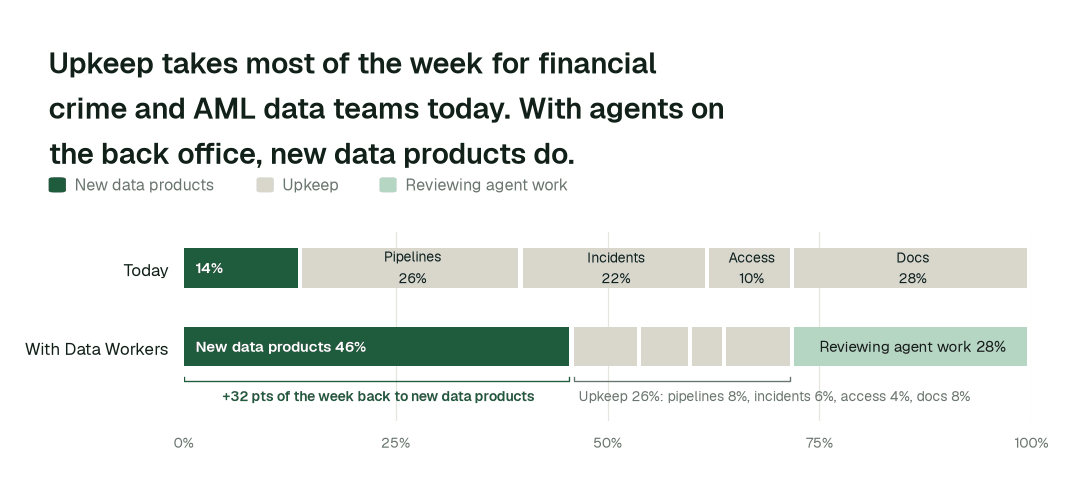
Time spent on new data products moves from 14% of the week to 46%. Most of the rest becomes review: people steer and approve agent work instead of doing it by hand.
Then and now
| Work | Today | With Data Workers |
|---|---|---|
| A core banking or payments change | Found when a rule goes quiet | Mapped on arrival, impact on every rule input shown |
| Source vs monitored population | Reconciled for an audit | Tied every morning, gaps explained the same day |
| Missing fields on rule inputs | Silent exclusions | Flagged on arrival with the transactions affected |
| Sanctions and PEP list updates | Loaded and trusted | Loaded, checked and versioned, with evidence of what was in force |
| Customer and counterparty identity | Duplicates found by analysts | Orphans and duplicates surfaced daily for the owner |
| Evidence for an alert or a validation | Assembled over days | Generated from live lineage |
These are the impact metrics we move for financial crime and AML data teams:
- •Source-to-monitoring tie-out: from about a week to 10-15 min
- •Silent exclusion explained: from about a week to under 1 h
- •Alert evidence pack: from about 2 days to about 1 h
Across the routine work in this domain:
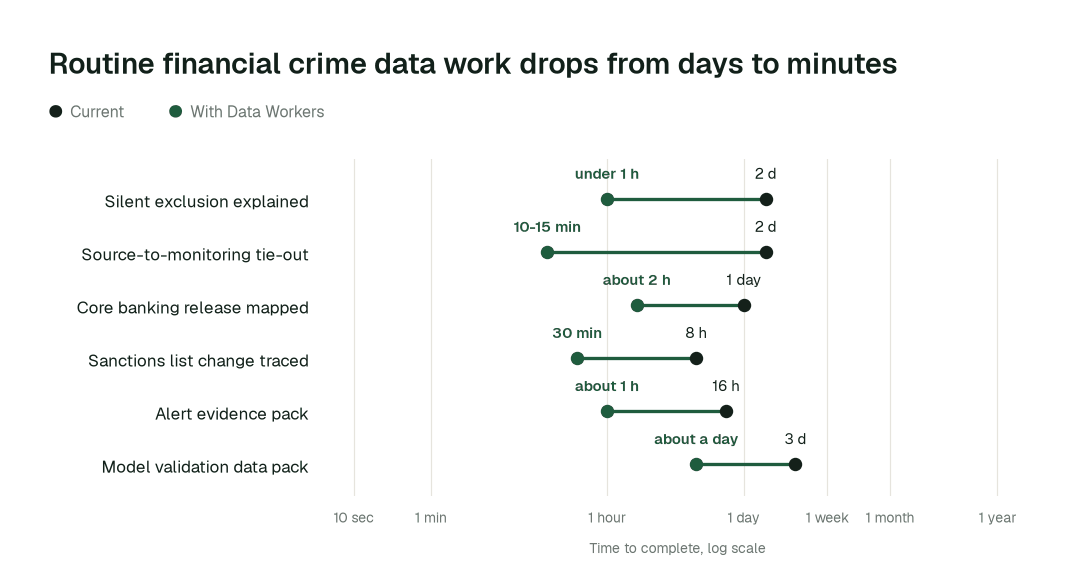
The biggest change is the model validation data pack: from about 2 weeks to about a day. Work that waited in queues finishes in minutes or hours, because agents detect, trace and prepare the evidence in one pass.
Use cases, in depth
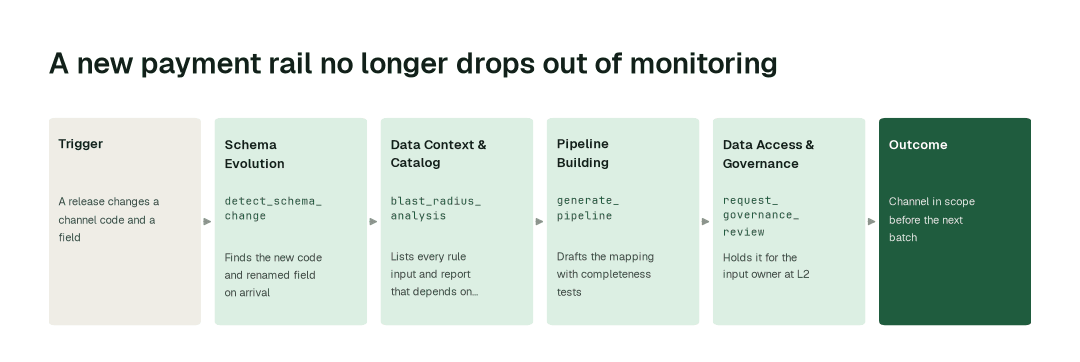
A new payment rail that silently fell out of scope
Today. A payments hub starts sending a new instant-payment channel code, and the counterparty country moves to a renamed field. The load succeeds. Four scenarios that depend on those fields stop seeing the new rail, and nobody knows until a validation sample comes up short.
With Data Workers. Schema Evolution detects the change on arrival, Data Context & Catalog shows every rule input and report that depends on those fields, Pipeline Building proposes the mapping with tests, and the change is held for the people who own the monitoring inputs.
What changes. The gap is closed before the next monitoring run, with a record of exactly which transactions were affected and for how long.
A sanctions list update that has to be right today
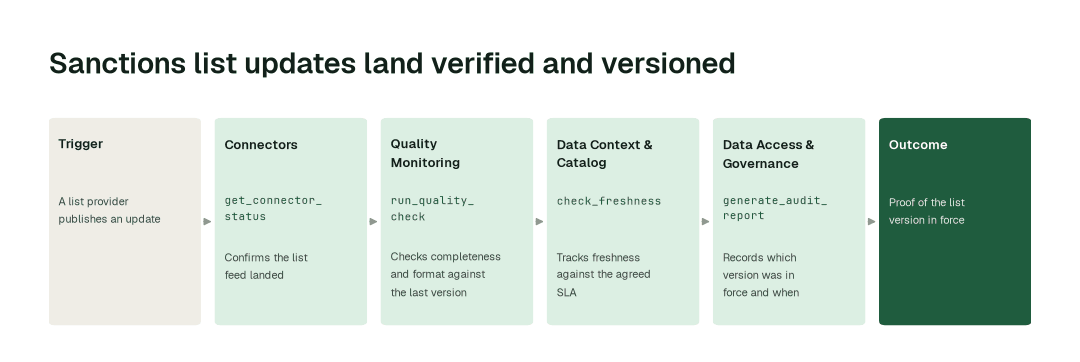
Today. A list provider changes a file layout, or a list update loads with malformed dates and dropped aliases. Screening runs against a list that is incomplete or a day old, and proving which version was in force means digging through load logs.
With Data Workers. Connectors watch the list feeds, Quality Monitoring checks each update for completeness and format against the previous version, Data Context & Catalog tracks freshness against an agreed SLA, and Data Access & Governance records which version was loaded and when.
What changes. List updates land verified, and you can show an examiner which list was in force at any moment. Decisions about screening settings and match handling stay with the sanctions team.
Evidence for an examiner or a model validation
Today. A validator or examiner picks an alert and asks where each field came from, what the model or rule saw, and whether the inputs have drifted since the last review. The data team spends two weeks assembling it.
With Data Workers. trace_cross_platform_lineage and get_audit_trail produce the path from source record to alert, detect_model_drift shows how the model's inputs have moved, and generate_audit_report packages the change history with owners and approvals.
What changes. The evidence pack takes an afternoon. The validator's conclusions, as always, are the validator's.
Agents working together: A core banking release that dropped a channel out of scope
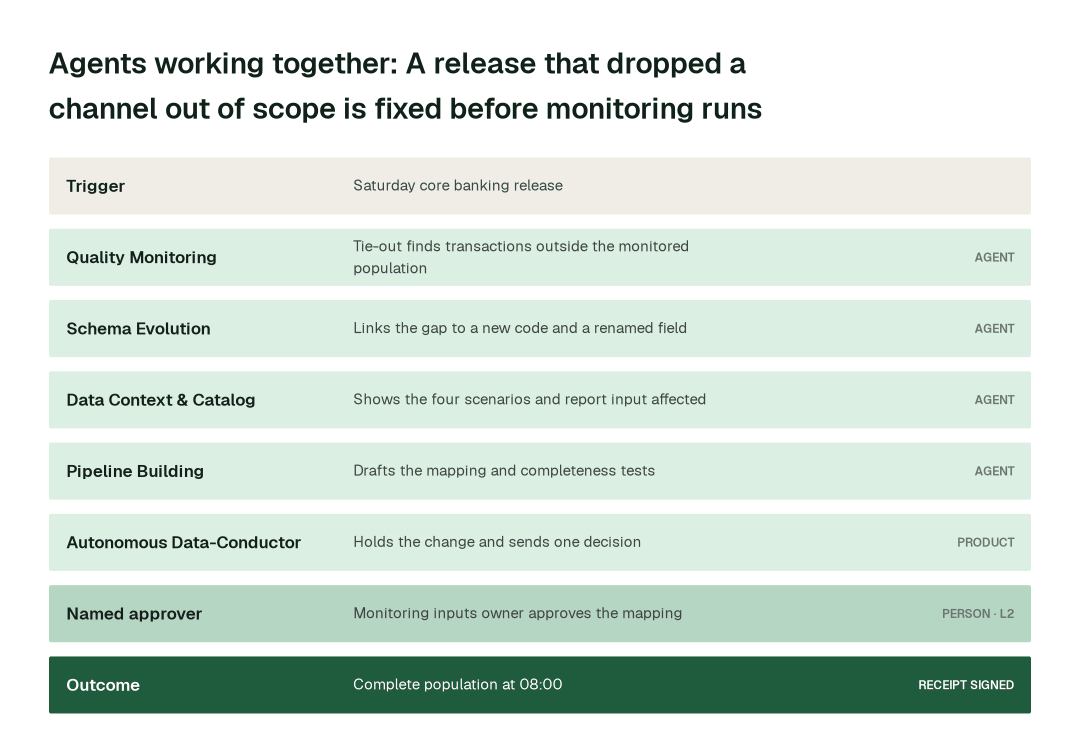
Every financial crime data team has lived some version of this. A release goes out on a Saturday, the feeds still load, and the first sign of trouble is a quiet week on a rule that should fire. This is the same release run by Data Workers.
The setup
Core banking and a payments hub land nightly in Snowflake. dbt builds the monitored population and the rule inputs, and the transaction monitoring platform runs its daily batch at 08:00. Autonomy in Autopilot:
- •Staging, field checks and tie-outs: L2 today; a candidate for L3 on evidence.
- •Mapping changes to monitoring inputs and customer data: L2, held for the named input owner.
- •Scenarios, thresholds, alert dispositions, cases and filings: L0.
The team scheduled one standing routine: "Tie source transactions to the monitored population by product, channel and currency, and check every rule-critical field."
02:05: the feed lands
The nightly payments extract arrives. It contains a new instant-payment channel code, and the counterparty country now arrives in a renamed field. The load completes without an error.
02:08: the tie-out fails
Quality Monitoring agent compares source transactions with the monitored population. In this illustrative example, 38,400 transactions on the new channel belong to no monitored product, and counterparty country is empty on every one of them.
Schema Evolution agent identifies the renamed field and the new code as the cause and links both to Saturday's release.
02:15: see what depends on it
Data Context & Catalog agent runs the blast radius: four scenarios that read counterparty country or channel, the customer activity profile and one regulatory report input.
02:30: propose the fix
Pipeline Building agent drafts the mapping change in dbt: the new channel code maps to the instant-payment product, and the renamed field feeds counterparty country. It writes tests that the tie-out is complete and that no rule-critical field is empty for the channel, and validates them in staging. The staging checks pass.
02:40: assemble the decision
Incident Debugging agent confirms the release as root cause and records the exposure window: the first affected load was tonight's, so no transaction has yet gone unmonitored. Autonomous Data-Conductor holds the mapping change at L2 and sends one decision to the on-call owner of the monitoring inputs: the diff, the tie-out result, the four scenarios affected and how to roll it back.
07:10: approved
The monitoring inputs owner approves. Conductor applies the mapping, reruns the tie-out and publishes. The new channel is in the monitored population with every rule-critical field populated.
08:00: monitoring runs
The batch reads a complete population. Nobody files a ticket, and nobody has to explain a quiet week later.
What stays behind
- •A mapping with tests, so the next change to that feed is caught the same way.
- •A record of what changed, who proposed it, who approved it and how to roll it back.
- •Updated Spellbook pages for every affected data set and rule input.
- •A reusable routine. The team can move the routine parts of this tie-out to L3 once the receipts justify it.
Minute by minute
This is an illustrative example. Core banking and a payments hub land in Snowflake, dbt builds the rule inputs, and the monitoring batch runs at 08:00. Mapping changes are at L2.
| Time | Who | What happens |
|---|---|---|
| Sat 22:40 | Core banking | Release adds an instant-payment channel code and renames a field |
| 02:05 | Connectors agent | get_connector_status: nightly payments extract landed |
| 02:08 | Quality Monitoring agent | run_quality_check: 38,400 transactions outside the monitored population |
| 02:10 | Schema Evolution agent | detect_schema_change: new code and renamed field found |
| 02:15 | Data Context & Catalog agent | blast_radius_analysis: four scenarios, one profile, one report input |
| 02:30 | Pipeline Building agent | generate_pipeline and validate_pipeline: mapping and tests ready |
| 02:40 | Spellbook Data Catalog | Mapping held at L2 with the full diff |
| 07:10 | Spellbook Data Catalog | Input owner approves |
| 07:20 | Autonomous Data-Conductor | Tie-out rerun passes, change published |
| 08:00 | Monitoring batch | Runs on a complete population |
Without the agents, the new channel runs unmonitored until someone notices the quiet rules, and the exposure is measured in weeks of transactions.
The agents on the job
| Agent | What it does for you | Tools it calls |
|---|---|---|
| Connectors and Data Ingestion | Land core banking, payments, card, KYC and list-provider feeds and profile every load | get_connector_status, trigger_airflow_dag, get_dbt_run_history |
| Schema Evolution | Detects source changes and versions the contracts monitoring depends on | detect_schema_change, assess_impact, validate_schema_compatibility, rollback_migration |
| Quality Monitoring | Source-to-monitoring tie-outs and rule-critical field checks, daily | set_sla, run_quality_check, get_anomalies, create_quality_tests_for_pipeline |
| Incident Debugging | Traces a gap or a moved population to the change that caused it | diagnose_incident, get_root_cause, get_incident_history |
| Data Context & Catalog | Lineage from source record to alert, freshness of lists and owners for every data set | trace_cross_platform_lineage, blast_radius_analysis, check_freshness, generate_documentation |
| Data Access & Governance | Scoped access to KYC, case and SAR data, with every grant logged | check_policy, enforce_rbac, scan_pii, generate_audit_report |
| Observability | Agent health and the audit trail of what each agent did | get_audit_trail, detect_drift, get_evaluation_report |
| MLOps & Models | Input drift and version history for monitoring and risk-rating models | detect_model_drift, get_model_versions, explain_model |
| Pipeline Building | Builds and versions monitoring input models with tests | generate_pipeline, validate_pipeline, deploy_pipeline |
Data Context Wizard holds one governed definition of each rule input, customer attribute, list and monitored product, so the monitoring platform, the model validators and the people investigating an alert read the same meaning. Autonomous Data-Conductor verifies the numbers that matter before the monitoring batch runs. Spellbook Data Catalog makes each data set discoverable with owner, lineage and approvals, in plain English.
What goes on autopilot
Once a domain has earned it, this work runs on its own, and each item removes a problem your team deals with today:
- •Source transactions are tied to the monitored population every morning, so a product, channel or currency that falls out of scope is flagged the same day.
- •Rule-critical fields are checked on arrival, so an empty counterparty country is a finding on Sunday night and not a surprise in a validation.
- •Sanctions and PEP list updates are verified and versioned as they land, so you can show which list was in force at any moment.
- •Lineage and documentation are generated from the live graph, so an examiner's question about one alert is answered with a path, not a project.
Where your people stay in charge
Agents never get blanket access. Each domain has its own autonomy level, set by you, and it only rises when the receipts show the agents are reliable. Everything starts at L1, observing only; reversible upkeep such as reruns, staging fixes, documentation and cleanup is usually first to run on its own.
- •Alert disposition, case closure and SAR or STR filing stay entirely with named investigators and officers. Agents may assemble the source data an investigator asks for; they do not decide, draft the decision or file.
- •Customer risk rating overrides, account exits and watchlist match decisions are people's decisions.
- •Scenario, threshold and model changes go to their owners and to your model risk process.
- •Mapping changes to monitoring inputs and customer data always go to the named input owner with the full diff.
Once a deployment has matured, here is how that ladder plays out across task classes:
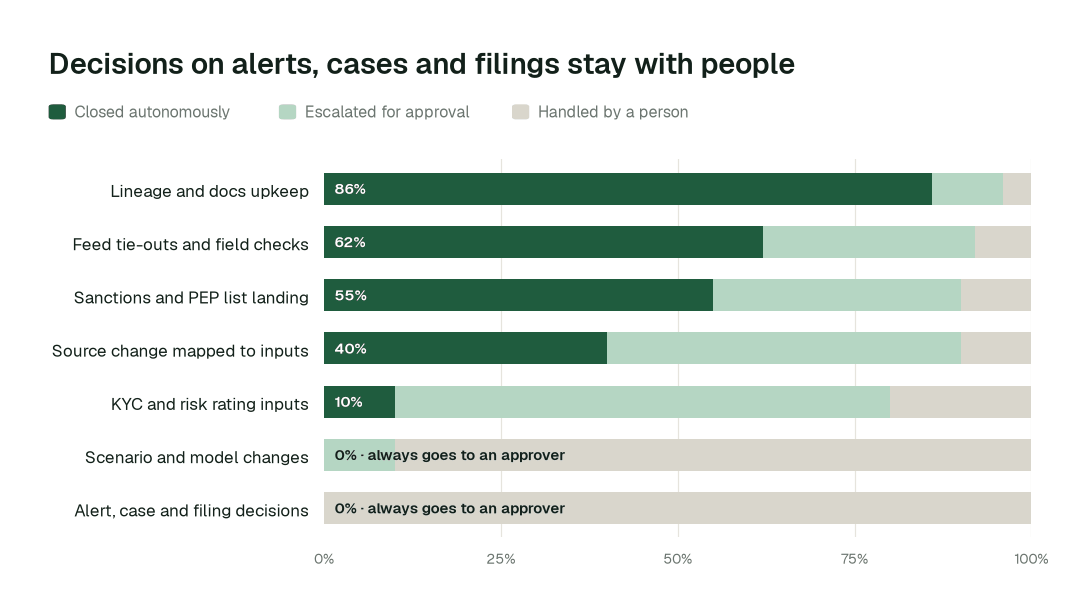
Lineage and docs upkeep closes autonomously 86% of the time. For alert, case and filing decisions, autonomous closure is 0% by design: they stay with named people.
What happens when an agent is wrong
- •At L2 propose, nothing changes until a named person approves. The proposal shows the full diff, the blast radius and how to roll it back. Unanswered requests expire and escalate.
- •L3 and L4 are where a domain can go next, on its own review record: acting on its own, with a rollback point on every change. Only the domain's owner raises its level, and if people start reverting the agents' changes, the domain pauses itself.
- •No agent approves or promotes its own work. Autonomy only grows on evidence, domain by domain, and repeated reverts pause the domain.
- •One org-wide stop halts all autonomous dispatch, and every action lands in a tamper-evident audit trail you can export with
generate_audit_report.
The failure that matters most here is the quiet one, so the checks are built around it: the tie-out compares the agents' own output with the source, not with itself, and a failed check is a finding to a person, never something to suppress.
How it fits your stack
Data Workers connects to what you already run: core banking, payments and card processor feeds; Snowflake or Databricks; Airflow or Control-M; dbt; your transaction monitoring, screening and case management platforms; and KYC, entity resolution and list-provider feeds. Each agent is an MCP server, so the same agents work inside Claude Code, Cursor or Codex and in Slack or Teams through Spellbook. Nothing migrates.
- •Runs in your infrastructure with your credentials and your model key. The hosted Autonomous Data-Conductor sees workflow metadata only, never rows.
- •Uses the access you already govern. Agents act under scoped service identities and your existing roles, so case and SAR tables can be excluded from agent access entirely. Every grant is logged.
- •Works beside your engines, not instead of them. Your monitoring platform still generates alerts, your screening engine still matches names and your case manager still holds the case. Agents keep the data under and around them complete and traceable.
- •Proposes changes as diffs in your dbt project, orchestrator and warehouse, with blast radius, tests and a rollback point, and applies them only at the autonomy level you set for that domain.
- •Open-source core. The Apache-2.0 community edition ships 11 agents and 160+ MCP tools, so your engineers can read exactly what the agents call.
Governance and regulation
Financial crime compliance is among the most examined areas of a bank, and several sources shape what your data has to do. Customer due diligence and ongoing monitoring appear in the FATF Recommendations (including the recommendations on customer due diligence, record keeping, wire transfers and suspicious transaction reporting). In the United States, FinCEN's customer due diligence rule covers identifying beneficial owners of legal entity customers and ongoing monitoring, FinCEN receives suspicious activity reports, and OFAC publishes the sanctions lists, with a machine-readable Sanctions List Service. Examiners use the FFIEC BSA/AML Examination Manual as a guide to how these are examined.
For models, the Federal Reserve, OCC and FDIC issued revised model risk management guidance in April 2026 (SR 26-2). It replaced the 2011 guidance (SR 11-7) and the 2021 interagency statement on BSA/AML models, and it is expected to be most relevant to banks with over $30 billion in assets. The letter states that it does not apply to generative and agentic AI models. Your model risk team decides how it applies to your monitoring and screening models; Data Workers does not interpret it for you.
What Data Workers supplies is evidence around the data: lineage from source record to alert, documented data quality rules, named approvals on changes to monitoring inputs, a version record for screening lists, and a tamper-evident audit trail of every agent action. Your compliance, model risk and legal functions decide what meets each expectation.
Data Workers doesn't make you compliant; your controls, people and assessors do. It supplies controls and evidence wherever agents touch data. Not legal advice.
The alternatives financial crime and AML data teams weigh
Build it yourselves. A strong team can wire a coding agent to MCP servers for the warehouse and dbt. The work is everything around it: routing approvals to the right owner, blast radius, rollback, receipts, and current context about every other system.
Observability, catalogs and point tools. Observability alerts, catalogs document, and quality tools test. Data Workers takes their signals, diagnoses, proposes the fix, verifies it and leaves the receipt.
Platform-native agents. Snowflake made its managed MCP server and Cortex Agents generally available on Nov 4, 2025, and Databricks made Genie One generally available on Jun 16, 2026. They are excellent inside their platform; this work crosses the source systems, orchestrator, warehouse and monitoring platforms, and Data Workers works across all of them.
In this space specifically. Transaction monitoring, screening and case management platforms detect, match and manage cases; Data Workers keeps the data feeding them complete, current and traceable, and leaves the decisions to your investigators. Fraud teams have a related problem in feature freshness, covered in fraud detection data, run by agents.
The case for your CTO
What this replaces. Hunting for why a rule went quiet, reconciling feeds for each audit by hand and assembling lineage for every validation and exam.
What your team gets back. A financial crime data team that ships better typology data and customer views, and never again has to prove from scratch that the data was complete.
Integration effort. Connecting is configuration, not a migration. The agents attach over MCP to the warehouse, orchestrator, dbt project and source systems you already run, under the roles you already govern, inside your own infrastructure. Your engineers can read every tool the agents call in the open-source core.
Risk and control. Autonomy is set per domain. Everything starts at L1, observing only; reversible work moves up only when the receipts justify it; changes to monitoring inputs stay at L2 with a named approver; decisions on alerts, cases and filings stay with people; and one org-wide stop halts all autonomous work. For how approvals work in practice, see how approvals work for AI data agents.
Why now. Payment rails multiply faster than data teams do, and supervisors increasingly ask not just whether you monitor but whether you can show what was monitored. For the wider picture, see the agentic data platform for financial services.
The first win. Source-to-monitoring tie-out on one product line at L2. The pilot below lays out the scope, what you see each week and the cost.
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For financial crime and AML data teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; mapping changes to monitoring inputs always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: source transactions are tied to the monitored population every morning, rule-critical fields are checked on arrival, and list updates are verified as they land. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. Monitoring data becomes continuous: complete every morning, lineage always current, and an exam or validation request a query instead of a project. People set direction, and investigators decide, with the data ready.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how financial crime and AML data teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. Core banking and payments feeds; Snowflake or Databricks; Airflow or Control-M; dbt; and your monitoring and screening platforms, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Source-to-monitoring completeness tie-out on one product line at L2.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes. A first tie-out often finds something nobody was looking for.
- •By week two. Daily source-to-monitoring tie-outs and rule-critical field checks start running on reversible work. Mapping changes to monitoring inputs stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •Source-to-monitoring tie-out: from about a week to 10-15 min
- •Silent exclusion explained: from about a week to under 1 h
- •Alert evidence pack: from about 2 days to about 1 h
- •the share of lineage and docs upkeep closed autonomously, targeting 86% as the deployment matures
- •What you decide. Whether to expand to the next product line or to sanctions list data. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, a 6 to 12 week pilot, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
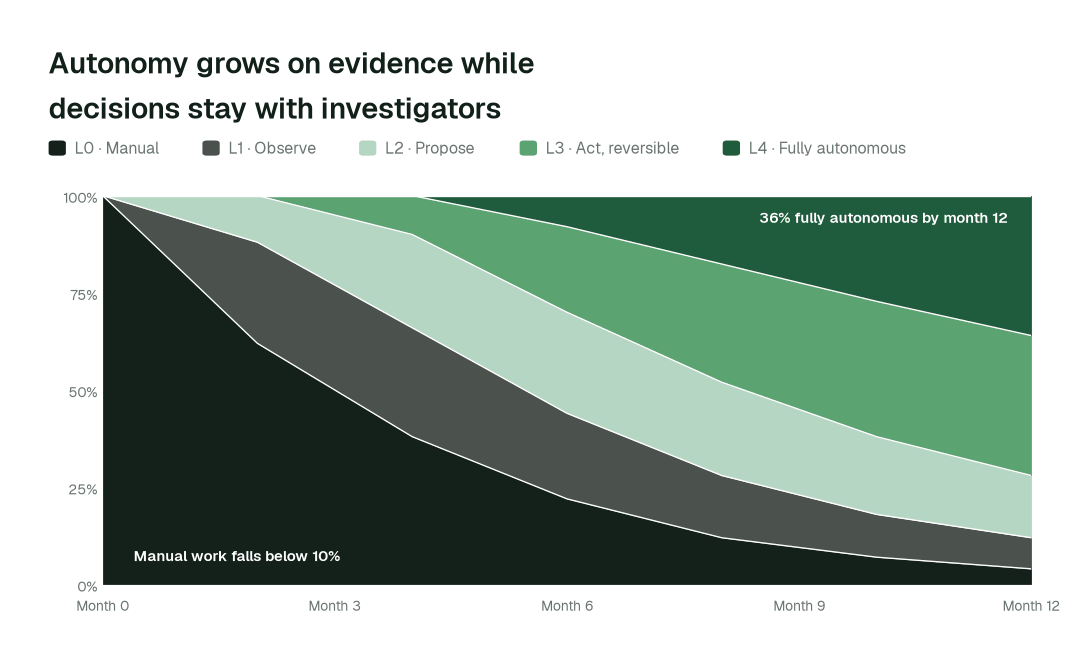
By month 12, more than 36% of agent actions run fully autonomously while decisions on alerts, cases and filings stay with named people.
FAQ
Will an agent clear an alert or file a SAR? No. Alert disposition, case decisions and SAR or STR filing stay with named investigators and officers. Agents prepare the data and evidence those people ask for.
Will agents tune our scenarios or thresholds? No. Scenario, threshold and model changes belong to their owners and your model risk process. Agents show the data behind a rule; they do not change what it decides.
Does it replace our monitoring, screening or case management platform? No. Those platforms keep detecting, matching and managing cases. Data Workers keeps the data feeding them complete and traceable.
Can agents see SAR and case data? Only if you let them. Agents act under scoped service identities, so SAR and case tables can be excluded entirely, and every access is logged.
How does it help with entity resolution? It does not replace your matching engine. It watches the output: orphaned identifiers, unexpected duplicates and drops in match rate are surfaced to the data owner each day, with lineage to the source records.
Where do the agents run? In your infrastructure, with your credentials and model key. The hosted Conductor sees workflow metadata only.
Do we have to migrate anything? No. Your warehouse, dbt project, orchestrator, catalog and monitoring platforms stay where they are.
Sources
- •FATF, The FATF Recommendations: https://www.fatf-gafi.org/en/publications/Fatfrecommendations/Fatf-recommendations.html
- •FinCEN, Customer Due Diligence final rule: https://www.fincen.gov/resources/statutes-and-regulations/cdd-final-rule
- •FinCEN, Filing information (SARs and other BSA reports): https://www.fincen.gov/resources/filing-information
- •OFAC, Sanctions List Service: https://ofac.treasury.gov/sanctions-list-service
- •Federal Reserve, SR 26-2, Revised Guidance on Model Risk Management (Apr 17, 2026): https://www.federalreserve.gov/supervisionreg/srletters/SR2602.htm
- •FFIEC, BSA/AML Examination Manual: https://bsaaml.ffiec.gov/manual
- •Data Workers pricing: https://dataworkers.io/pricing/
- •Snowflake, managed MCP server and Cortex Agents GA release note (Nov 4, 2025): https://docs.snowflake.com/en/release-notes/2025/other/2025-11-04-cortex-agents-mcp
- •Databricks, Genie One launch (Jun 16, 2026): https://www.databricks.com/company/newsroom/press-releases/databricks-launches-genie-one-all-new-agentic-coworker-every-team