Best practices for agentic market and reference data: a field guide for market and reference data teams
How market and reference data teams move their data back office to agents, practice by practice: the state of the space, the old world and the new, what the agents do step by step, how to set autonomy, who owns what, and how to start.
Every valuation, risk number and client statement starts as a vendor file. Market and reference data teams sit at the very top of that chain, and their mistakes travel further than anyone else's.
The work that keeps vendor data right is repeatable: profiling, mapping, comparing sources, tracking freshness and logging entitlements. That is exactly the work agents should own, so the team can focus on golden-source policy and new data products.
The state of the space
The team that owns the vendor feeds every valuation depends on: prices, curves, FX rates, corporate actions, the security master and counterparty reference data. It usually sits in operations or a chief data office, and its consumers are fund accounting, risk, trading and client reporting. Titles include Head of Market Data, Reference Data Product Owner, Pricing Data Lead and Security Master Manager.
Firms license data from a dozen vendors, each with its own formats, restatements and outage patterns, and every downstream number inherits their mistakes. Licensing costs keep rising, and AI copilots now quote prices and exposures directly to portfolio managers. The work of keeping vendor data clean, mapped, entitled and traceable is enormous and repeatable, which makes it the clearest case in the bank for an agentic back office.
The old world
At 7:30 fund accounting reports a NAV variance. By 9:40 an engineer has found a shifted column in a vendor file. The NAV is re-struck after cut-off and the team spends the afternoon on an incident note.
It is rarely one failure. Three patterns repeat:
- •The currency in the wrong column. A vendor adds a column and 140 positions price in the wrong currency; fund accounting finds it in a NAV variance two hours later.
- •Two vendors, one corporate action. A stock split arrives from two vendors with different ratios; ops spends the morning deciding which to trust.
- •License and entitlement control. Vendor audits ask who used which feed; nobody can say.
The new world
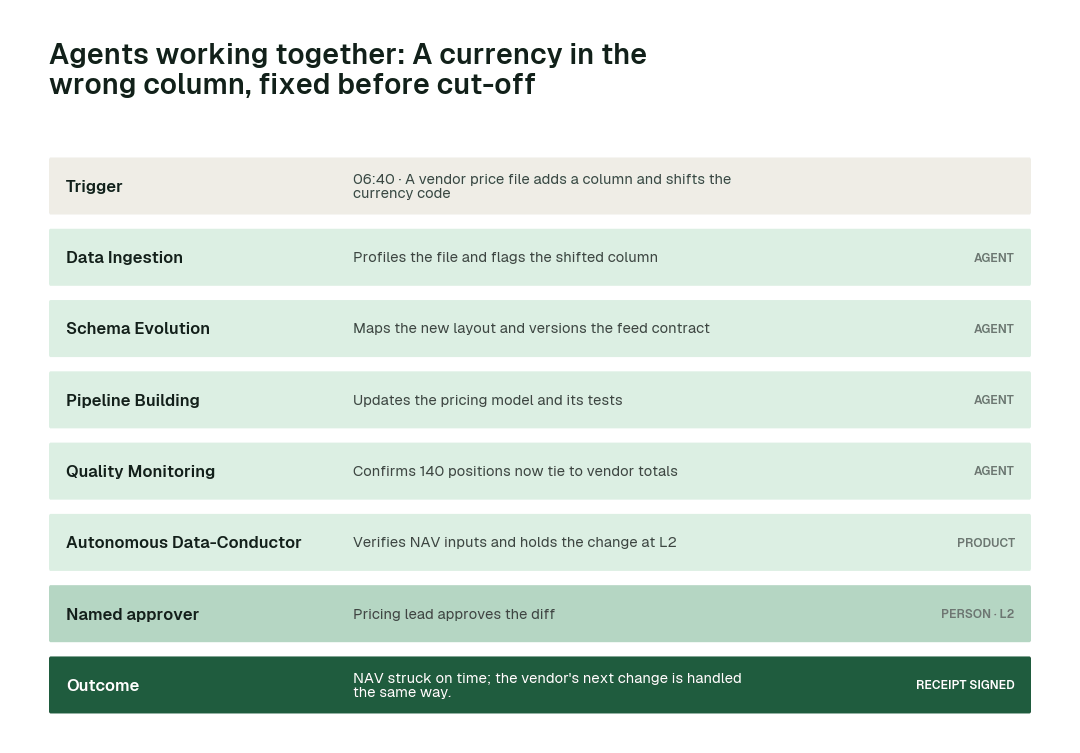
The shifted column was flagged at 6:42, mapped and tested by 6:49, and approved by the pricing lead at 7:05. Fund accounting never saw it.
Here is that new world as a chain of hand-offs between agents:
These are the impact metrics we move:
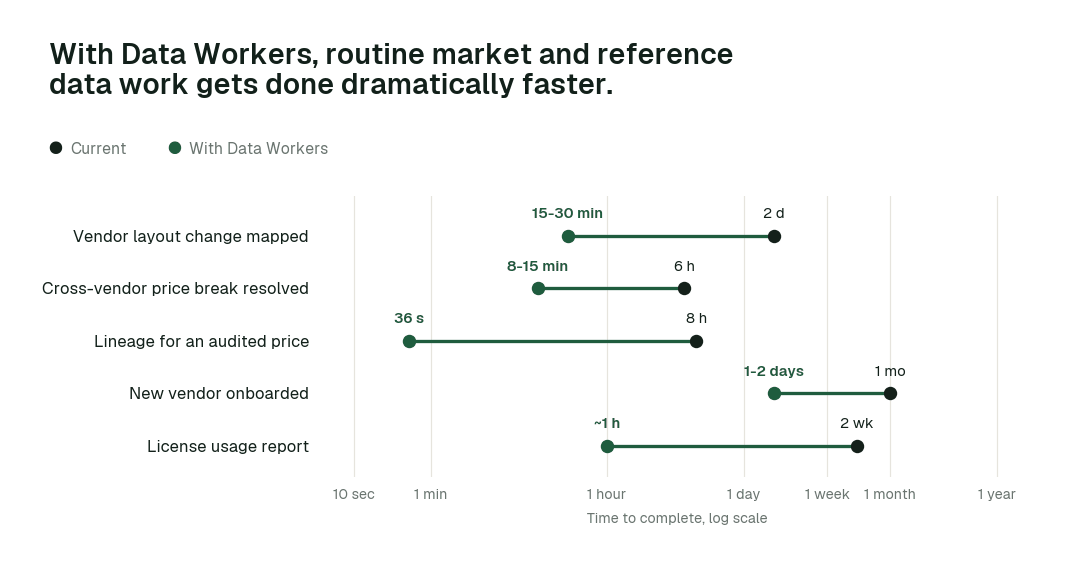
- •Lineage for an audited price: from about 8 hours to seconds
- •License usage report: from about 2 weeks to ~1 h
- •Vendor layout change mapped: from about 2 days to 15-30 min
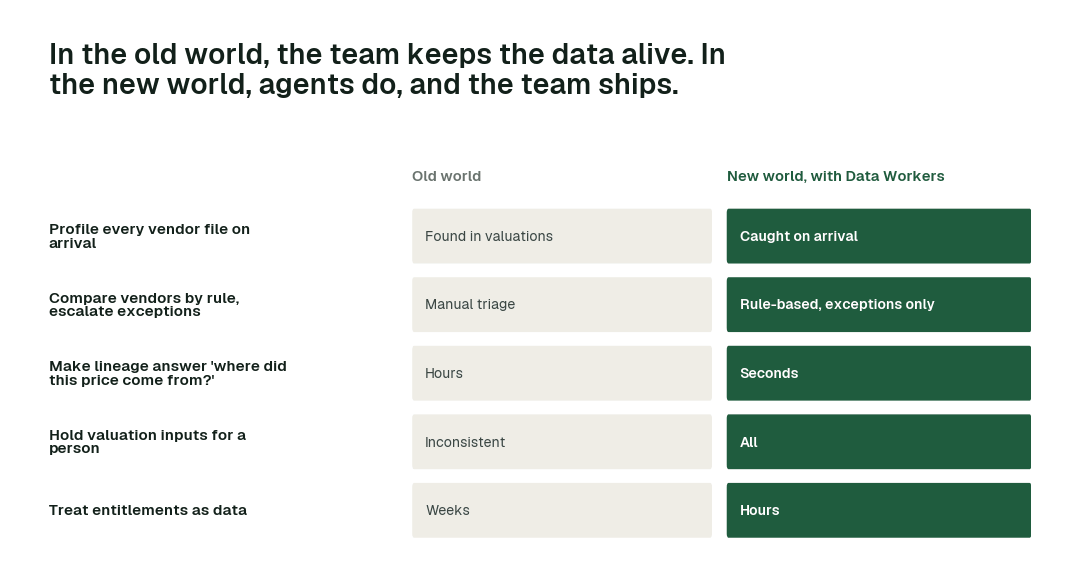
The rest of this report walks through the 5 practices that make that possible. At a glance:
The practices, one by one
1. Profile every vendor file on arrival
Most bad prices are visible in the file before anything reads it.
Why it is harder than it looks. Vendor files fail in ways schema checks miss: a currency shifting one column still loads cleanly.
The old world. Files load blind; problems surface in valuations.
The new world. Data Ingestion and Quality Monitoring profile every file with run_quality_check and detect_schema_change.
What the agents do, step by step:
- 1.The Data Ingestion agent calls
get_connector_statusand confirms the file landed and profiles it. - 2.The Schema Evolution agent calls
detect_schema_changeand compares the layout with the versioned contract. - 3.The Quality Monitoring agent calls
run_quality_checkand checks prices against tolerance and vendor totals.
In practice. A shifted column is caught one minute after load.
What to measure. Breaks reaching a valuation.
2. Compare vendors by rule, escalate exceptions
Two sources disagreeing is normal; resolving it by hand is not.
Why it is harder than it looks. Two vendors disagreeing is normal; deciding which one wins every morning by hand is the waste.
The old world. Ops decides by email each morning.
The new world. Golden-source rules live in Data Context Wizard; exceptions go to one person.
What the agents do, step by step:
- 1.The Quality Monitoring agent calls
get_anomaliesand finds cross-vendor disagreements. - 2.The Data Context & Catalog agent calls
define_business_ruleand applies the golden-source rule. - 3.The Autonomous Data-Conductor calls
request_governance_reviewand routes true exceptions to one person.
In practice. A split ratio conflict is resolved before positions update.
What to measure. Exceptions resolved before cut-off.
Practices like these compound. Across the routine work they cover:
3. Make lineage answer 'where did this price come from?'
Auditors and portfolio managers ask the same question.
Why it is harder than it looks. Lineage for a single price crosses vendor files, staging, dbt models and the EDM.
The old world. Hours of tracing.
The new world. trace_cross_platform_lineage returns value to file in seconds.
What the agents do, step by step:
- 1.The Data Context & Catalog agent calls
trace_cross_platform_lineageand walks value to file. - 2.The Data Context & Catalog agent calls
generate_documentationand writes the path with owners. - 3.The Data Access & Governance agent calls
generate_audit_reportand exports evidence.
In practice. An audit question is answered in the meeting.
What to measure. Time to trace a value.
4. Hold valuation inputs for a person
Prices feed NAV and capital.
Why it is harder than it looks. Speed matters most at cut-off, which is exactly when a wrong change hurts most.
The old world. All-or-nothing review.
The new world. NAV and risk inputs run at L2 with a named approver.
What the agents do, step by step:
- 1.The Pipeline Building agent calls
sandbox_testand tests the fix. - 2.The Data Context & Catalog agent calls
blast_radius_analysisand shows affected valuations. - 3.The Autonomous Data-Conductor calls
request_governance_reviewand holds NAV inputs for the pricing lead.
In practice. Reruns run alone; the NAV input waits for one approval.
What to measure. Valuation changes with an approver on record.
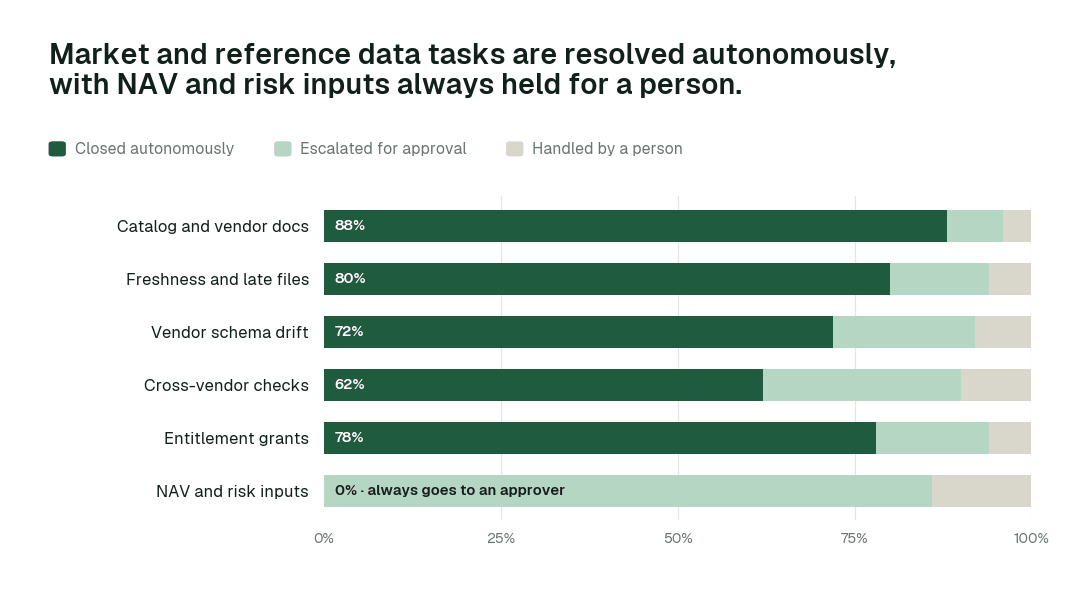
Autonomy where work is reversible, a named approver where it matters:
5. Treat entitlements as data
License audits need evidence.
Why it is harder than it looks. License audits ask who saw which feed over a year, not who has access today.
The old world. Annual spreadsheets.
The new world. provision_access scopes grants; generate_audit_report exports usage.
What the agents do, step by step:
- 1.The Data Access & Governance agent calls
provision_accessand scopes each entitlement. - 2.The Usage Intelligence agent calls
get_adoption_dashboardand tracks real use per feed. - 3.The Data Access & Governance agent calls
generate_audit_reportand exports usage for the vendor.
In practice. A vendor audit closes in an afternoon.
What to measure. Hours to answer a license audit.
Designing the autonomy ladder
Autonomy is set per task class, not per tool. This is where we would set each class for a mature deployment, and why:
| Task class | Closed autonomously | Escalated | Handled by a person | Where we set it | Why |
|---|---|---|---|---|---|
| Catalog and vendor docs | 88% | 8% | 4% | L4 once the receipts are clean | The work is reversible and repeatable |
| Freshness and late files | 80% | 14% | 6% | L4 once the receipts are clean | The work is reversible and repeatable |
| Vendor schema drift | 72% | 20% | 8% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Cross-vendor checks | 62% | 28% | 10% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Entitlement grants | 78% | 16% | 6% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| NAV and risk inputs | 0% | 86% | 14% | L2: always proposed to a named approver | The number carries accountability outside the data team |
The operating model: who owns what
Agents change who does the work, not who is accountable for it:
| Role | Owns | What the agents take off their plate |
|---|---|---|
| Head of Market Data | Standards, autonomy levels per domain and which domain goes next | Assembling status, chasing owners, keeping the catalog current |
| Domain owners and approvers | Changes to NAV, risk or client-reporting inputs | Preparing the diff, blast radius and rollback plan for every proposal |
| Data engineers | Reviewing agent proposals and building new data products | Every vendor file is profiled the minute it lands; prices are compared across vendors by your golden-source rules |
The swarm behind the practices
| Agent | What it does for you | Tools it calls |
|---|---|---|
| Data Ingestion | Profiles every vendor file on arrival and detects late or restated deliveries | get_connector_status, trigger_airflow_dag, register_kafka_schema |
| Schema Evolution | Maps vendor layout changes and versions each feed contract | detect_schema_change, validate_schema_compatibility, generate_migration, rollback_migration |
| Quality Monitoring | Price tolerance, stale-price and cross-vendor comparison checks | set_sla, run_quality_check, get_anomalies, create_quality_tests_for_pipeline |
| Incident Debugging | Traces a bad valuation to the file and field behind it | diagnose_incident, get_root_cause, prepare_backfill, execute_backfill |
| Data Access & Governance | Scopes vendor entitlements and logs usage for license audits | provision_access, check_policy, request_governance_review, generate_audit_report |
| Data Context & Catalog | Keeps golden-source rules, lineage and vendor terms current | trace_cross_platform_lineage, blast_radius_analysis, define_business_rule, generate_documentation |
Data Context Wizard keeps one governed graph of definitions, lineage and owners that every agent and person answers from. Autonomous Data-Conductor runs each job from detection to a verified result. Spellbook Data Catalog is where your team approves, audits and rolls back, and asks questions in plain English.
What disappears
- •NAV re-strikes caused by vendor layout changes.
- •Morning email threads about conflicting prices.
- •Hours spent tracing a single price.
- •Annual entitlement spreadsheets.
- •Unused feeds nobody dares cancel.
The magic is not any single agent. It is that the back office keeps running: bad data is caught where it enters, every new table gets quality rules and documentation without anyone writing them, access follows policy, fixes are verified before anyone opens a dashboard, and every action leaves a signed receipt.
A product manager's scorecard
| Metric | How to read it |
|---|---|
| Vendor breaks reaching a valuation | Baseline it in the first week of the pilot; review it monthly. |
| Exceptions resolved before cut-off | Baseline it in the first week of the pilot; review it monthly. |
| Time to trace a value to source | Baseline it in the first week of the pilot; review it monthly. |
| Entitlement grants logged | Baseline it in the first week of the pilot; review it monthly. |
| Feeds retired and license cost saved | Baseline it in the first week of the pilot; review it monthly. |
Where this goes next
Within a few years, market data teams will run a fully autonomous vendor layer: every file profiled, compared and entitled without a person in the loop, with humans owning golden-source policy and vendor strategy. The teams that get there first will cut license spend and become the fastest source of truth in their firm.
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For market and reference data teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; changes to NAV, risk or client-reporting inputs always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: every vendor file is profiled the minute it lands, prices are compared across vendors by your golden-source rules, and entitlement grants and usage are logged continuously. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. Within a few years, market data teams will run a fully autonomous vendor layer: every file profiled, compared and entitled without a person in the loop, with humans owning golden-source policy and vendor strategy. The teams that get there first will cut license spend and become the fastest source of truth in their firm.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how market and reference data teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. Snowflake, Databricks or BigQuery; Airflow or Control-M; dbt; vendor SFTP and APIs from Bloomberg, Refinitiv/LSEG, ICE and S&P; an EDM or security master, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Freshness SLAs and cross-vendor checks on the pricing feeds, at L2 propose, for one quarter.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Every vendor file is profiled the minute it lands and prices are compared across vendors by your golden-source rules start running on reversible work. Changes to NAV, risk or client-reporting inputs stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •Lineage for an audited price: from about 8 hours to seconds
- •License usage report: from about 2 weeks to ~1 h
- •Vendor layout change mapped: from about 2 days to 15-30 min
- •the share of catalog and vendor docs closed autonomously, targeting 88% as the deployment matures
- •What you decide. Whether to expand to the next domain. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
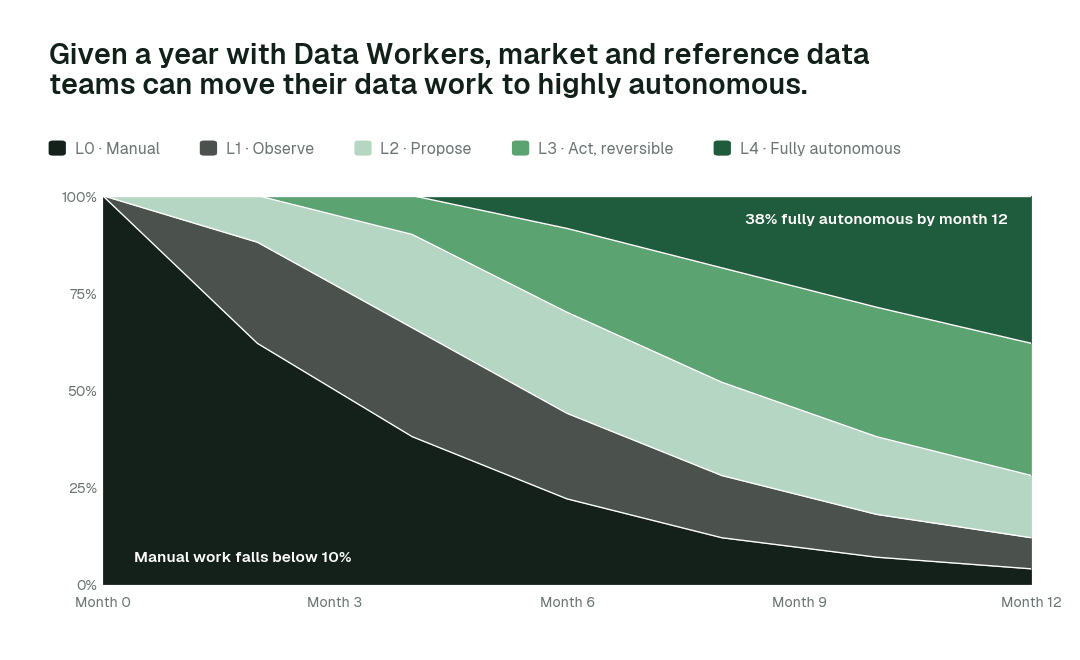
The pilot is the start of a longer curve:
Read the full playbook: Data Workers for market and reference data teams