Best practices for agentic ads data marts: a field guide for measurement data teams
Every number in an ads data mart ends up on an invoice. This report covers how measurement data teams move the back office to agents so that delivery, reach, attribution and billing are verified before anyone sees them.
Ads businesses sell numbers. Impressions, viewable impressions, reach, frequency, conversions and lift are what advertisers pay for, and the ads data mart is where those numbers are made. At streaming companies it lives in the ads platform org; at media groups it sits under ad sales; at retail media networks it sits beside loyalty data.
The pressure on these teams has never been higher. The end of third-party cookies pushed measurement into first-party identity and clean rooms, ad-supported streaming tiers multiplied the event volume, and advertisers expect reports every morning. Meanwhile ad servers ship weekly, identity providers change formats and measurement vendors change methods.
The teams that keep up treat verification as automatic and constant, not as a monthly reconciliation. That is exactly what agents are good at.
The old world
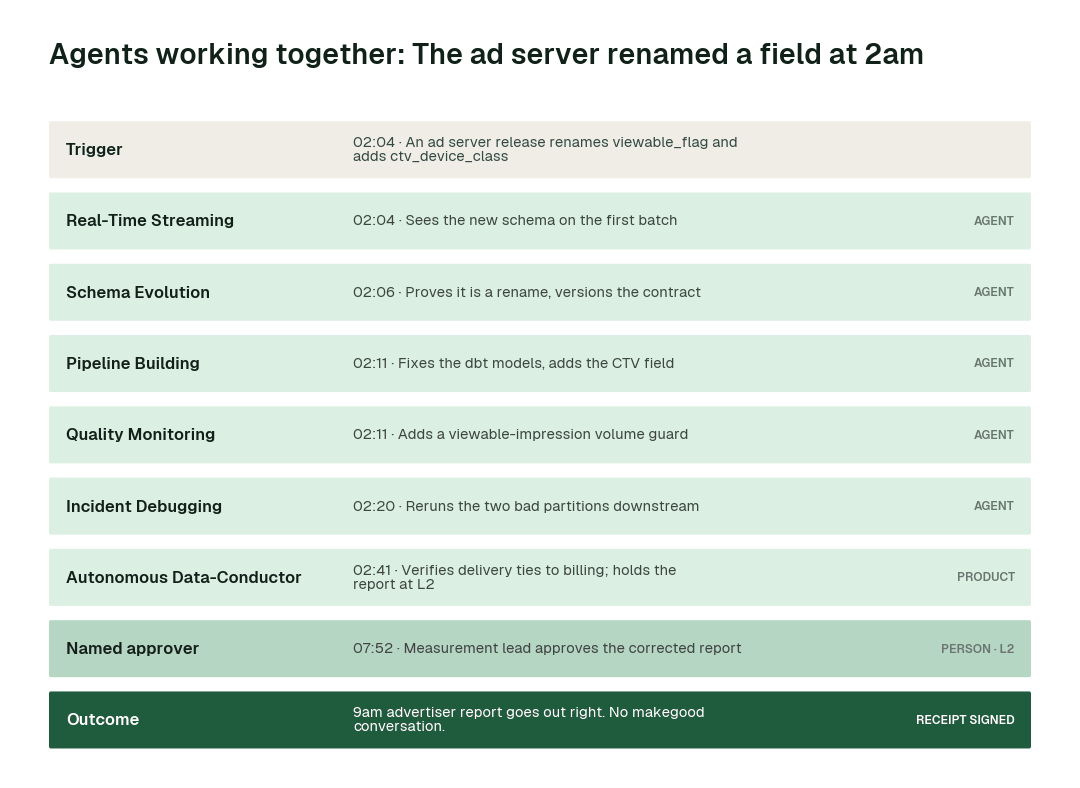
02:04: an ad server release renames a field. Two hourly partitions load with zero viewable impressions. Nobody notices until the 9am delivery report goes out short to 40 advertisers. Account managers open makegood discussions by noon. A data engineer traces it by 15:00 and backfills the next day. At month end, finance and the data team spend three days reconciling delivered against billed.
The new world
With Data Workers, Real-Time Streaming saw the new schema on the first batch, Schema Evolution proved it was a rename, Pipeline Building fixed the models, Incident Debugging reran the bad partitions, and Conductor verified delivery tied to billing before holding the corrected report for one approval at 07:52. Delivered and billed reconcile every morning, so month end is a formality.
Here is that new world as a chain of hand-offs between agents:
The full playbook walks through this scenario and three more use cases in depth.
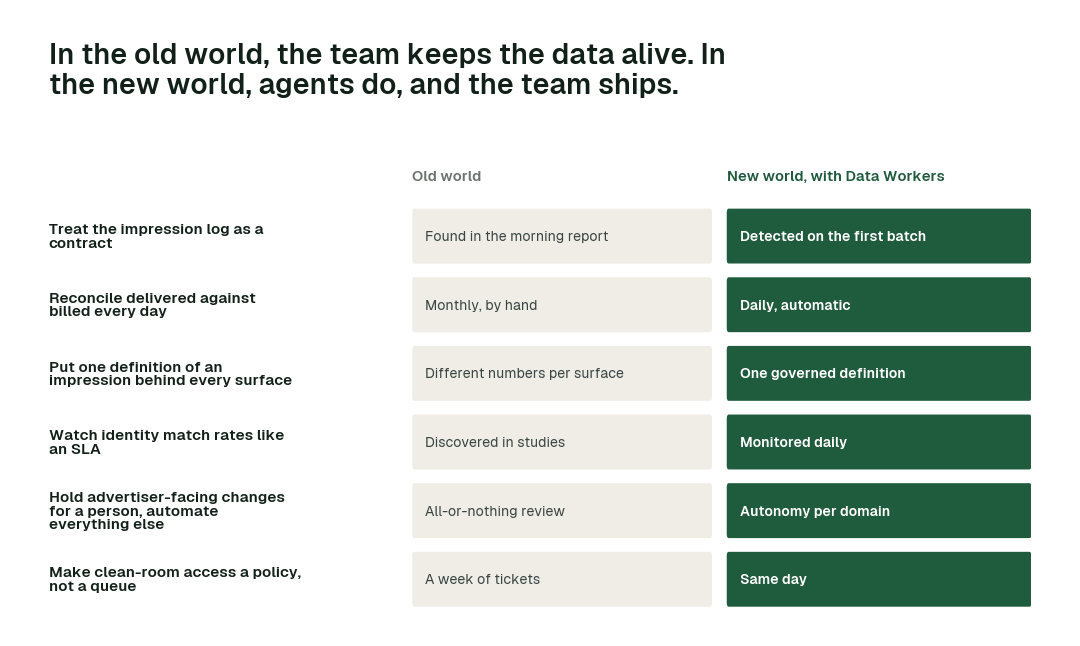
The rest of this report walks through the 6 practices that make that morning possible. At a glance:
The practices, one by one
1. Treat the impression log as a contract
Silent field renames are the most common cause of short delivery reports.
The old world. Producers change schemas without telling anyone; consumers find out from advertisers.
The new world. Schema Evolution and Real-Time Streaming version the contract, detect renames and drops on the first batch, and map them downstream.
In practice. A rename is mapped within two minutes of the first batch landing.
What to measure. Time from schema change to mapped contract.
2. Reconcile delivered against billed every day
Month-end reconciliation finds problems after invoices have gone out.
The old world. Finance and the data team reconcile by hand at month end.
The new world. Conductor runs a daily delivered-vs-billed routine and escalates one decision with evidence when they diverge.
In practice. An invalid-traffic filter change opens a gap; it is explained the same morning.
What to measure. Days to explain a delivered-vs-billed gap.
Practices like these compound. Across the routine work they cover, here is the difference in elapsed time:
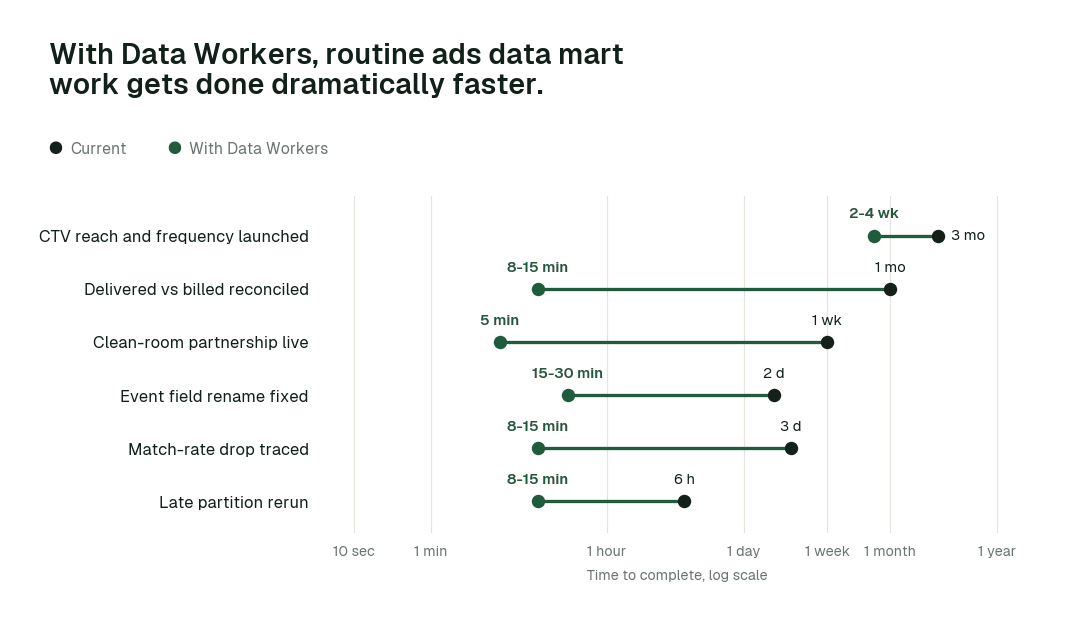
The biggest change is Delivered vs billed reconciled: from about a month to 8-15 min. Work that waited in queues finishes in minutes or hours, because agents detect, fix and verify in one pass.
3. Put one definition of an impression behind every surface
The clean room, the dashboard and the invoice should never disagree.
The old world. Each surface computes its own version.
The new world. Context Wizard holds governed definitions of impression, viewable impression, reach and conversion with provenance.
In practice. An advertiser's clean-room query matches the invoice to the impression.
What to measure. Discrepancies between surfaces.
4. Watch identity match rates like an SLA
A falling match rate weakens attribution and lift studies.
The old world. Drops are found when a lift study loses power.
The new world. Quality Monitoring tracks match rate by provider and source; Incident Debugging traces drops to the format change behind them.
In practice. A provider changes a hash format; the drop is traced on day one.
What to measure. Match rate by identity provider.
5. Hold advertiser-facing changes for a person, automate everything else
Speed and control are not a trade-off when autonomy is set per domain.
The old world. Everything waits for review, or nothing does.
The new world. Staging runs at L3; advertiser-facing reports and billing at L2 with a named approver.
In practice. Reruns happen overnight; the corrected report waits for one approval.
What to measure. Share of fixes closed autonomously.
That balance, autonomy where work is reversible and a named approver where it matters, shows up clearly by task class:
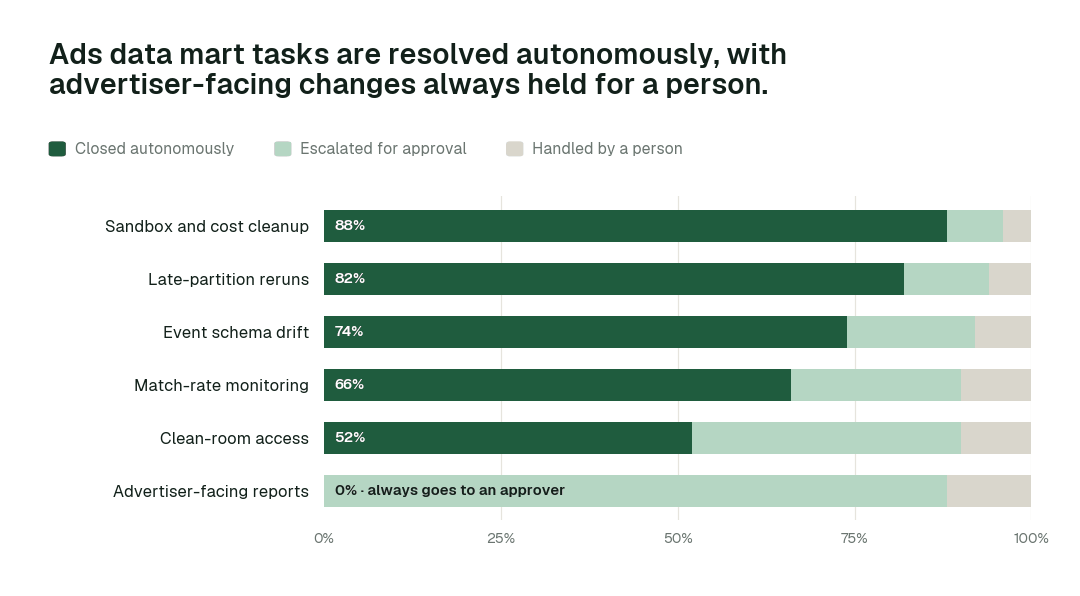
Sandbox and cost cleanup closes autonomously 88% of the time. For Advertiser-facing reports, autonomous closure is 0% by design: every change is proposed with a full diff and approved by a named person.
6. Make clean-room access a policy, not a queue
New partnerships should not mean a week of tickets.
The old world. Each advertiser waits on access requests and PII review.
The new world. Data Access & Governance applies clean-room policy and Data Security confirms no raw identifiers leave.
In practice. A new advertiser queries the clean room the day the deal closes.
What to measure. Days from deal to clean-room access.
Designing the autonomy ladder
Autonomy is set per task class, not per tool. This is where we would set each class for a mature deployment, and why:
| Task class | Closed autonomously | Escalated | Handled by a person | Where we set it | Why |
|---|---|---|---|---|---|
| Sandbox and cost cleanup | 88% | 8% | 4% | L4 once the receipts are clean | The work is reversible and repeatable |
| Late-partition reruns | 82% | 12% | 6% | L4 once the receipts are clean | The work is reversible and repeatable |
| Event schema drift | 74% | 18% | 8% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Match-rate monitoring | 66% | 24% | 10% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Clean-room access | 52% | 38% | 10% | L3 for routine cases, L2 for the rest | Judgment is needed often enough to keep a person close |
| Advertiser-facing reports | 0% | 88% | 12% | L2: always proposed to a named approver | The number carries accountability outside the data team |
The operating model: who owns what
Agents change who does the work, not who is accountable for it:
| Role | Owns | What the agents take off their plate |
|---|---|---|
| Head of Ads Measurement Data | Standards, autonomy levels per domain and which domain goes next | Assembling status, chasing owners, keeping the catalog current |
| Domain owners and approvers | Any change to an advertiser-facing report or invoice | Preparing the diff, blast radius and rollback plan for every proposal |
| Data engineers | Reviewing agent proposals and building new data products | Every impression partition is checked against the ad server's own totals as it lands; delivered and billed are reconciled every morning |
The swarm behind the practices
No single agent delivers these practices. Each one is a hand-off between specialists, coordinated under the autonomy you set per domain.
| Agent | What it does on an ads data mart |
|---|---|
| Real-Time Streaming | Keeps impression and click stream schemas, consumers and downstream tables in step when a producer changes |
| Schema Evolution | Maps renamed and new event fields, versions the contract and updates downstream models |
| Incident Debugging | Traces a short report to the partition or join that caused it, reruns and backfills |
| Quality Monitoring | Volume, match-rate and delivered-vs-billed checks on every advertiser-facing table |
| Data Access & Governance | Handles clean-room and warehouse access requests against your policies |
| Data Security | Classifies PII across event and audience tables and scrubs it before it reaches context |
| Cost Savings & Data Cleanup | Finds idle, duplicate and oversized workloads on event tables and cleans them up |
Autonomous Data-Conductor tracks freshness on every advertiser-facing table and reconciles delivered against billed daily. Data Context Wizard holds one governed definition of an impression, a viewable impression, a reached household and a conversion, so the clean-room number matches the invoice. Spellbook Data Catalog gives every event source and measurement table a living page that agents keep current.
What disappears
The clearest sign the practices are working is what stops happening:
- •Short delivery reports after a release.
- •Month-end delivered-vs-billed reconciliation.
- •Makegood conversations caused by data errors.
- •Clean-room access queues.
- •Mismatched numbers between clean room and invoice.
- •Petabytes of experiment tables nobody dares delete.
The magic is not any single agent. It is that the back office simply keeps running. Bad data is caught where it enters, not where it is read. Every new table gets quality rules and documentation without anyone writing them. Access follows policy instead of a queue. Fixes are rerun, verified and explained before anyone opens a dashboard. Cost is cleaned up every week instead of every budget cycle. And every one of those actions leaves a signed receipt, so the team can see exactly what happened and roll anything back. For the people on the team, the experience is quieter mornings, fewer tickets and more time for the products the business asked for.
A product manager's scorecard
If you own this data as a product, these are the numbers to bring to every quarterly review:
- •Advertiser-facing incidents per month
- •Time from schema change to verified report
- •Days to explain a delivered-vs-billed gap
- •Identity match rate by provider
- •Days from deal to clean-room access
- •Event-table spend per billion impressions
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For ads data mart and measurement teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; any change to an advertiser-facing report or invoice always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: every impression partition is checked against the ad server's own totals as it lands, delivered and billed are reconciled every morning, and new advertisers get clean-room access the day the deal closes. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. The engineering weeks that went to backfills and reconciliation, spent instead on new measurement products advertisers will pay for. People set direction, and the platform carries it out.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how ads data mart and measurement teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. Kafka or Kinesis impression streams; Snowflake, BigQuery or Databricks; dbt; Airflow; AWS Clean Rooms, Snowflake or LiveRamp clean rooms; billing systems, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Daily delivered-vs-billed on one product line at L2.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Every impression partition is checked against the ad server's own totals as it lands and delivered and billed are reconciled every morning start running on reversible work. Any change to an advertiser-facing report or invoice stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •Delivered vs billed reconciled: from about a month to 8-15 min
- •Clean-room partnership live: from about a week to 5 min
- •Match-rate drop traced: from about 3 days to 8-15 min
- •the share of sandbox and cost cleanup closed autonomously, targeting 88% as the deployment matures
- •What you decide. Whether to expand to the next domain. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
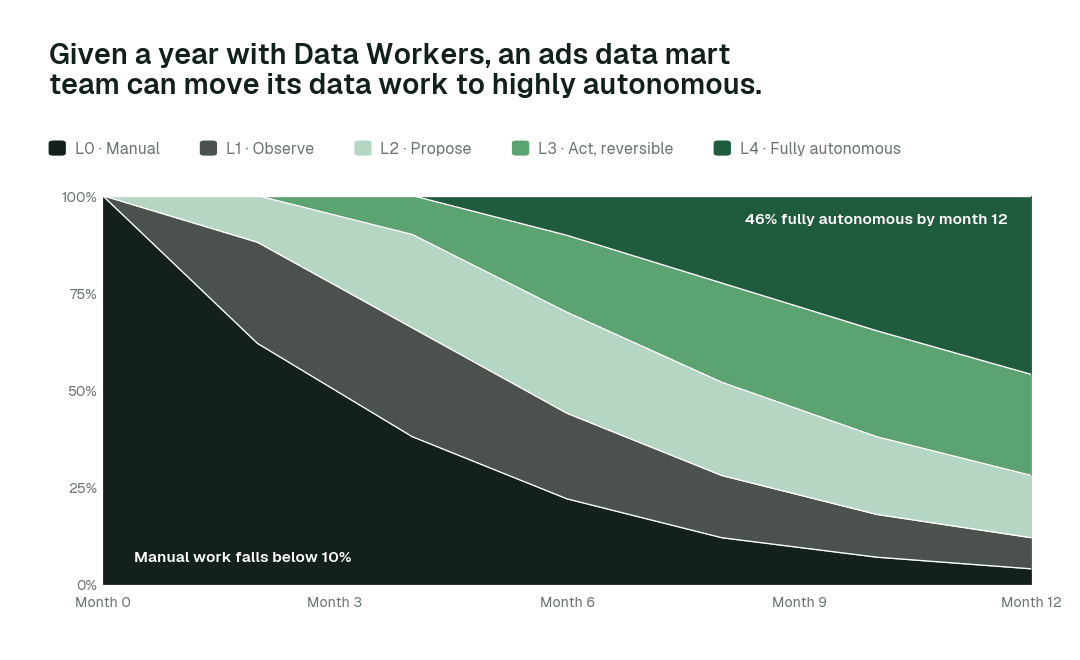
By month 12, more than 46% of agent actions run fully autonomously and manual work falls below 10%, while advertiser-facing changes stay with a named approver.
Read the full playbook: Ads data mart, measurement and analytics engineering teams