Best practices for agentic shipment and logistics network data: a field guide for logistics data teams
How logistics data teams move their data back office to agents, practice by practice: the state of the space, the old world and the new, what the agents do step by step, how to set autonomy, who owns what, and how to start.
Carriers now sell visibility as a product.
Keeping scan and event data complete is repeatable; agents should own it.
The state of the space
Data organizations inside carriers and logistics companies that turn package scans, route events and network capacity into products for operations and for shippers. Some run as dedicated data units with their own product, design and engineering teams. Titles include Product Manager Principal, Data Platform Lead and Head of Visibility Data.
Shippers now expect real-time visibility and accurate ETAs as a product, and carriers increasingly sell data services. Scan gaps, late feeds and inconsistent identifiers across hubs break those products. Agents keep the network's data complete and consistent at the speed the network runs.
The old world
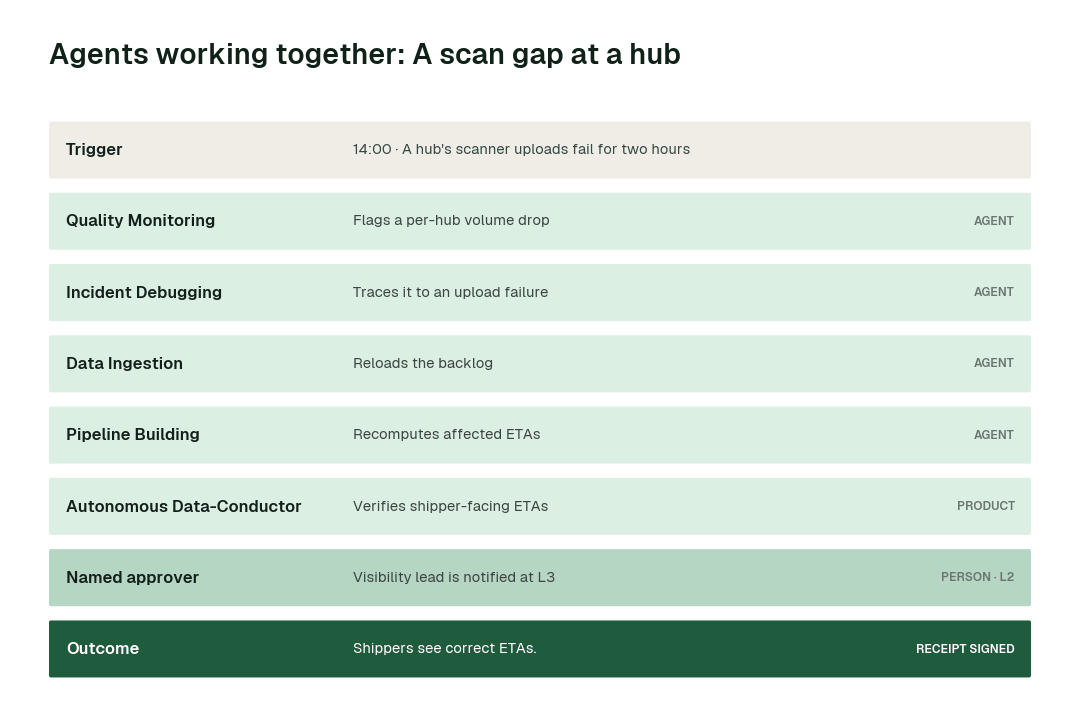
A hub's uploads fail; ETAs go stale for two hours; shippers call before the team knows.
It is rarely one failure. Three patterns repeat:
- •A scan gap at a hub. A hub's scanners drop events for two hours; ETAs for 80,000 packages go stale.
- •A partner carrier's new format. A last-mile partner changes its event schema.
- •A visibility data product for shippers. Large shippers want their own data feed.
The new world
The volume drop was flagged in 15 minutes and ETAs recomputed as uploads resumed.
Here is that new world as a chain of hand-offs between agents:
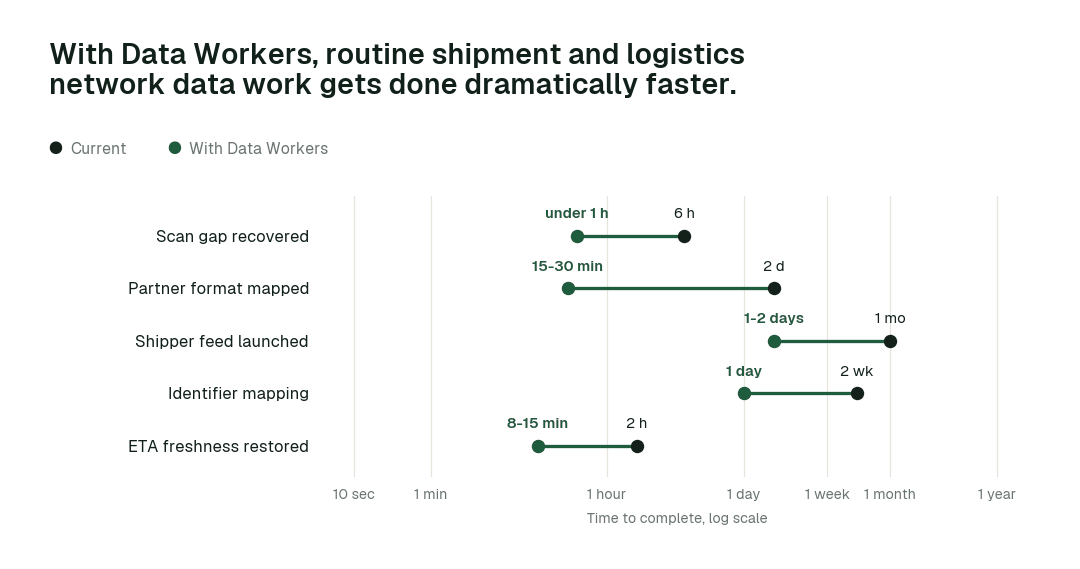
These are the impact metrics we move:
- •Partner format mapped: from about 2 days to 15-30 min
- •Shipper feed launched: from about a month to 1-2 days
- •Identifier mapping: from about 2 weeks to 1 day
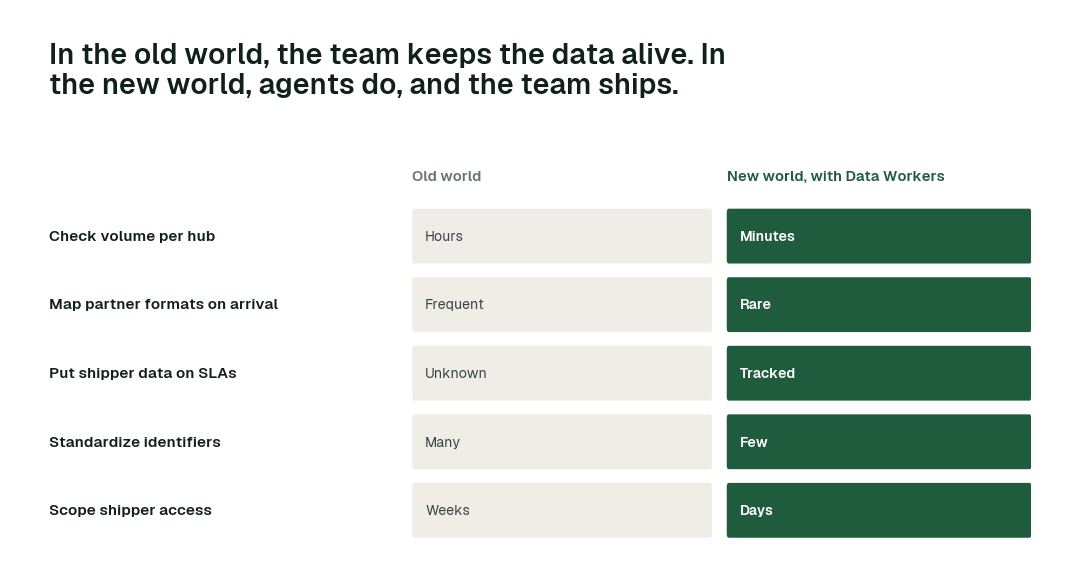
The rest of this report walks through the 5 practices that make that possible. At a glance:
The practices, one by one
1. Check volume per hub
Gaps hide in totals.
Why it is harder than it looks. Network totals hide local gaps.
The old world. Network-level checks.
The new world. Per-hub Quality Monitoring.
What the agents do, step by step:
- 1.The Quality Monitoring agent calls
get_anomaliesand checks volume per hub. - 2.The Incident Debugging agent calls
diagnose_incidentand finds the cause. - 3.The Incident Debugging agent calls
execute_backfilland reloads the backlog.
In practice. Hub 12 flagged in 15 minutes.
What to measure. Minutes to detect a gap.
2. Map partner formats on arrival
Partners change formats.
Why it is harder than it looks. Last-mile partners change formats without notice.
The old world. Broken feeds.
The new world. Schema Evolution.
What the agents do, step by step:
- 1.The Schema Evolution agent calls
detect_schema_changeand catches it. - 2.The Schema Evolution agent calls
generate_migrationand maps it. - 3.The Pipeline Building agent calls
sandbox_testand tests it.
In practice. No visibility gap.
What to measure. Partner breaks.
Practices like these compound. Across the routine work they cover:
3. Put shipper data on SLAs
Shippers pay for freshness.
Why it is harder than it looks. Shippers pay for freshness, not just accuracy.
The old world. Unknown.
The new world. set_sla.
What the agents do, step by step:
- 1.The Quality Monitoring agent calls
set_slaand sets freshness. - 2.The Autonomous Data-Conductor calls
verify_dataand verifies ETAs. - 3.The Quality Monitoring agent calls
get_quality_scoreand reports SLA.
In practice. Fresh ETAs.
What to measure. SLA attainment.
4. Standardize identifiers
Joins fail across systems.
Why it is harder than it looks. Every system names a shipment differently.
The old world. Manual.
The new world. Pipeline Building mappings.
What the agents do, step by step:
- 1.The Pipeline Building agent calls
generate_pipelineand builds mappings. - 2.The Data Context & Catalog agent calls
define_business_ruleand defines identifiers. - 3.The Quality Monitoring agent calls
run_quality_checkand checks joins.
In practice. One shipment ID.
What to measure. Join failures.
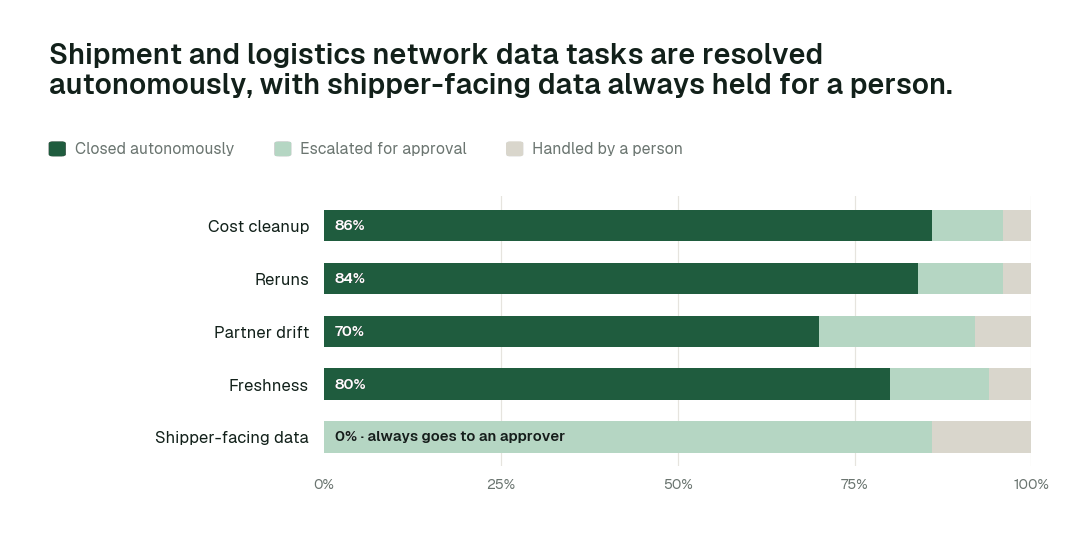
Autonomy where work is reversible, a named approver where it matters:
5. Scope shipper access
Each shipper sees only theirs.
Why it is harder than it looks. Each shipper must see only its own data.
The old world. Custom work.
The new world. provision_access.
What the agents do, step by step:
- 1.The Data Access & Governance agent calls
check_policyand checks the contract. - 2.The Data Access & Governance agent calls
provision_accessand scopes the feed. - 3.The Data Access & Governance agent calls
generate_audit_reportand logs it.
In practice. Feeds in weeks.
What to measure. Days to a shipper feed.
Designing the autonomy ladder
Autonomy is set per task class, not per tool. This is where we would set each class for a mature deployment, and why:
| Task class | Closed autonomously | Escalated | Handled by a person | Where we set it | Why |
|---|---|---|---|---|---|
| Cost cleanup | 86% | 10% | 4% | L4 once the receipts are clean | The work is reversible and repeatable |
| Reruns | 84% | 12% | 4% | L4 once the receipts are clean | The work is reversible and repeatable |
| Partner drift | 70% | 22% | 8% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Freshness | 80% | 14% | 6% | L4 once the receipts are clean | The work is reversible and repeatable |
| Shipper-facing data | 0% | 86% | 14% | L2: always proposed to a named approver | The number carries accountability outside the data team |
The operating model: who owns what
Agents change who does the work, not who is accountable for it:
| Role | Owns | What the agents take off their plate |
|---|---|---|
| Head of Logistics Data Products | Standards, autonomy levels per domain and which domain goes next | Assembling status, chasing owners, keeping the catalog current |
| Domain owners and approvers | Shipper-facing data and billing-relevant events | Preparing the diff, blast radius and rollback plan for every proposal |
| Data engineers | Reviewing agent proposals and building new data products | Scan volume is checked per hub; partner event formats are mapped on arrival |
The swarm behind the practices
| Agent | What it does for you | Tools it calls |
|---|---|---|
| Data Ingestion | Scan and partner event feeds, profiled per hub | get_connector_status, trigger_airflow_dag, register_kafka_schema |
| Schema Evolution | Partner format changes | detect_schema_change, validate_schema_compatibility, generate_migration, rollback_migration |
| Quality Monitoring | Per-hub volume and ETA freshness | set_sla, run_quality_check, get_anomalies, create_quality_tests_for_pipeline |
| Incident Debugging | Traces scan gaps | diagnose_incident, get_root_cause, prepare_backfill, execute_backfill |
| Pipeline Building | Shipper-facing feeds | generate_pipeline, validate_pipeline, sandbox_test, deploy_pipeline |
| Data Access & Governance | Shipper-scoped access | provision_access, check_policy, request_governance_review, generate_audit_report |
Data Context Wizard keeps one governed graph of definitions, lineage and owners that every agent and person answers from. Autonomous Data-Conductor runs each job from detection to a verified result. Spellbook Data Catalog is where your team approves, audits and rolls back, and asks questions in plain English.
What disappears
- •Stale ETAs found by shippers.
- •Broken partner feeds.
- •Manual identifier joins.
- •Peak cost overhang.
- •Custom feeds per shipper.
The magic is not any single agent. It is that the back office keeps running: bad data is caught where it enters, every new table gets quality rules and documentation without anyone writing them, access follows policy, fixes are verified before anyone opens a dashboard, and every action leaves a signed receipt.
A product manager's scorecard
| Metric | How to read it |
|---|---|
| Minutes to detect a gap | Baseline it in the first week of the pilot; review it monthly. |
| Partner breaks | Baseline it in the first week of the pilot; review it monthly. |
| ETA SLA attainment | Baseline it in the first week of the pilot; review it monthly. |
| Join failures | Baseline it in the first week of the pilot; review it monthly. |
| Shipper feeds launched | Baseline it in the first week of the pilot; review it monthly. |
Where this goes next
Carriers will sell real-time visibility as a premium product, backed by data that is checked per hub and per partner every minute. Data teams will build new shipper services instead of chasing gaps.
The climb: from assisted to autonomous to agentic
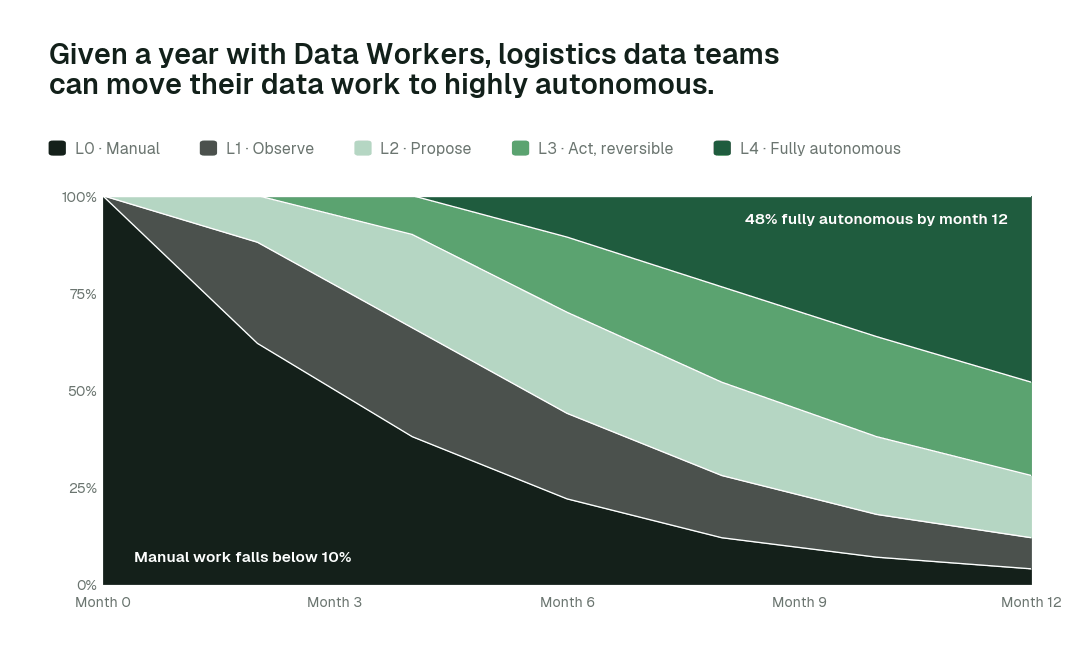
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For logistics data teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; shipper-facing data and billing-relevant events always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: scan volume is checked per hub, partner event formats are mapped on arrival, and shipper-facing feeds run on freshness SLAs. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. Carriers will sell real-time visibility as a premium product, backed by data that is checked per hub and per partner every minute. Data teams will build new shipper services instead of chasing gaps.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how logistics data teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. Kafka; Snowflake or BigQuery; TMS and WMS; partner APIs and EDI; dbt; shipper-facing APIs, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Per-hub freshness on shipper-facing data at L3.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Scan volume is checked per hub and partner event formats are mapped on arrival start running on reversible work. Shipper-facing data and billing-relevant events stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •Partner format mapped: from about 2 days to 15-30 min
- •Shipper feed launched: from about a month to 1-2 days
- •Identifier mapping: from about 2 weeks to 1 day
- •the share of cost cleanup closed autonomously, targeting 86% as the deployment matures
- •What you decide. Whether to expand to the next domain. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
Read the full playbook: Data Workers for logistics data teams