Best practices for agentic finance data: a field guide for finance data teams
Finance data is the one data domain where every number is eventually read by an auditor. This field guide covers how to run the ledger and subledger marts so the close starts reconciled: seven practices for tying out daily, remapping ERP changes at the boundary, explaining flux as the month runs, governing definitions and holding every entry for a named approver. Each practice shows the old world, the new world, which agent does what with public tools, and where a person signs.
Ask a controller what makes close hard and the answer is rarely accounting. It is the AP subledger that is off by a round number nobody can find, the intercompany pair that disagrees every quarter, the SAP transport that moved a field on Thursday, and the flux package written on day four from memory. Finance data teams sit under all of it. They own the ledger and subledger marts, the close and consolidation data, the planning inputs and the lineage behind every figure in the board pack.
The mandate is to close faster, put AI assistants in front of the ledger and hand the auditor an answer instead of a project. Each of those multiplies the cost of a number that does not tie: a copilot reading an untied mart repeats the wrong number to the whole finance organisation.
Our view: the work that keeps finance data correct is repeatable, and agents should own it. Entries, adjustments and published numbers stay with the people accountable for them. Everything around those decisions can run on its own.
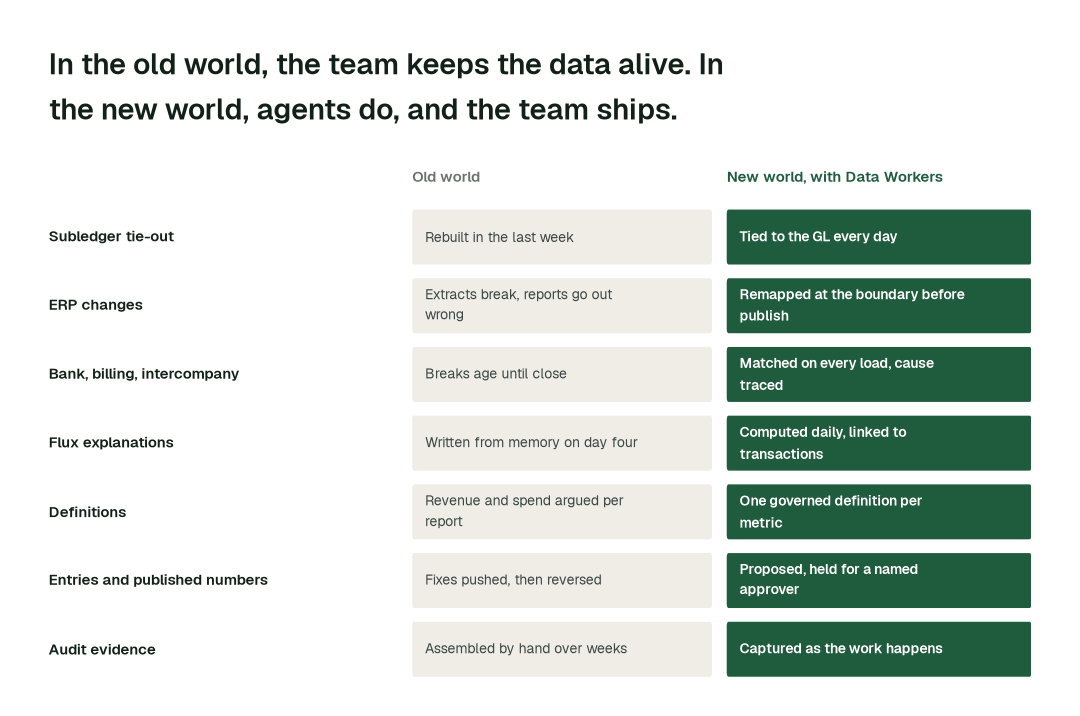
The old world
It is working day two. The subledgers closed overnight and the SAP extracts landed, but the subsidiary's ERP export arrived with a renamed field and nobody noticed. An analyst starts the tie-out in a spreadsheet at 09:00. By noon AP and AR tie, one entity's bank file is missing, and an intercompany pair is off by 41,000, traced by end of day to an invoice booked in different periods. The flux package is drafted on day four while FP&A and the controller argue over which revenue definition the board pack should use. Audit evidence is assembled three weeks later from tickets and screenshots. The roadmap does not move all week.
The new world
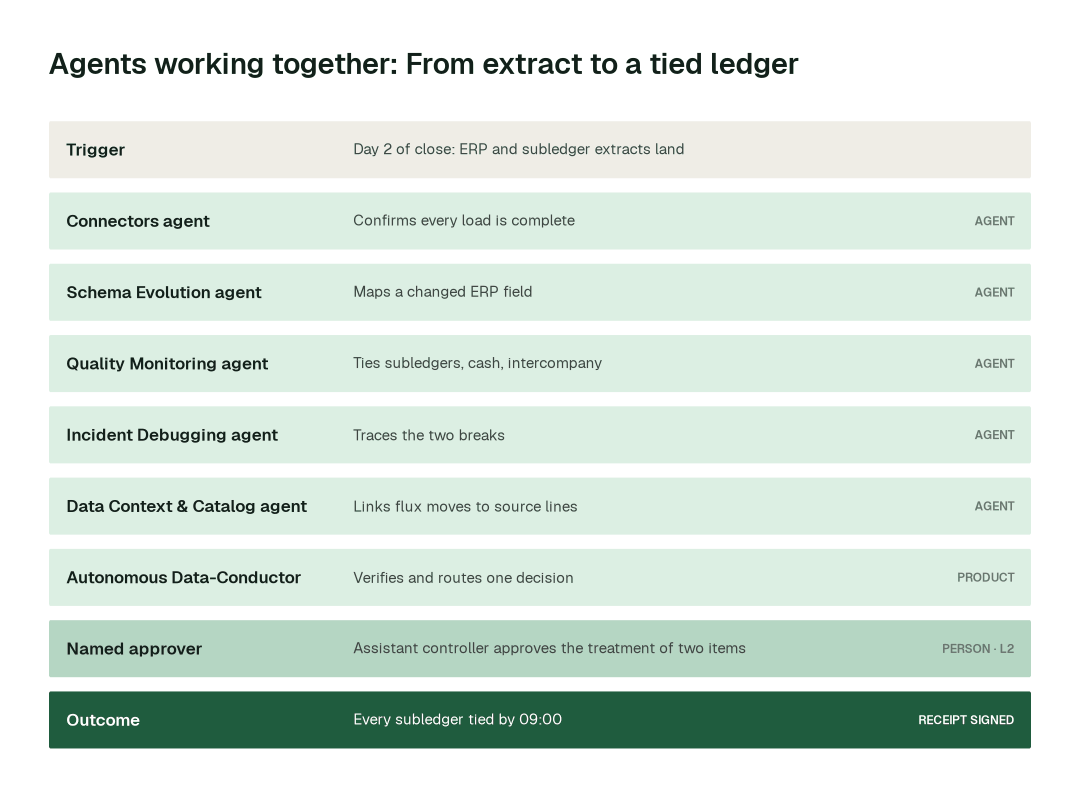
Same morning with Data Workers. The renamed field was mapped the previous evening. At 06:20 the Quality Monitoring agent tied each subledger to its GL control account and found the intercompany difference and a prepaid with no matching invoice. The Incident Debugging agent traced both to their records, and the Data Context & Catalog agent linked each material flux move to the lines behind it. The Autonomous Data-Conductor routed one decision to the assistant controller, who approved the treatment before 08:30. The entries were posted by their owners in the ERP. The team spends the day on the forecasting product.
Here is that morning as a chain of hand-offs between agents:
The full playbook walks through this scenario and the use cases behind it. The rest of this report covers the seven practices that make that morning possible, with the group page for finance, insurance and investment data teams showing how this team fits among its neighbours. At a glance:
The practices, one by one
1. Tie every subledger to the general ledger every day
A tie-out done once, at close, finds problems when they cost most to fix. Done daily, it finds them while the person who booked the entry still remembers it.
Why it's harder than it looks: The tie is not one comparison. It is AP, AR, fixed assets, payroll and billing against their control accounts, bank against cash, each per entity and currency, and the ledger moves under you with late postings and reversals. Most teams tie once, at the end, because maintaining thirty spreadsheet checks daily is itself a job.
- 1.After the nightly run, the Connectors agent calls
get_connector_statusandget_dbt_run_historyto confirm every extract is complete and on time. - 2.The Quality Monitoring agent writes the tie-out tests once per subledger with
create_quality_tests_for_pipeline, runs them withrun_quality_checkand sets a deadline per tie withset_sla. - 3.Breaks go to the account owner with the records attached, and the controller sees a checklist where every subledger is tied or has a named open item. The owner approves each open item's treatment.
The workflow is in month-end close.
2. Remap ERP changes at the boundary, before a report publishes
Upgrades, transports and new company codes alter fields in SAP, Oracle, NetSuite or Workday Financials. The damage is a wrong report reaching the CFO before anyone knew.
Why it's harder than it looks: ERP changes are made by people outside the data team, and a new company code is a business event, not a schema event, so no ticket arrives. The extract still lands and the numbers look plausible: a new code silently drops out of consolidation and nothing fails.
- 1.The Schema Evolution agent runs
detect_schema_changeon each extract as it lands, thenassess_impact. - 2.The Data Context & Catalog agent runs
blast_radius_analysisto list every mart and report that reads the field. - 3.The Schema Evolution agent writes the remap with
generate_migration, checks it withvalidate_schema_compatibilityand keepsrollback_migrationready. Quality Monitoring re-ties the rebuilt mart to the ledger. - 4.The owner of the affected report approves the diff before it reaches production.
See SAP and ERP reporting. If your estate is also leaving SAP BW, the move to Business Data Cloud shows where the boundary shifts. Across the routine work these practices cover, here is the difference in elapsed time:
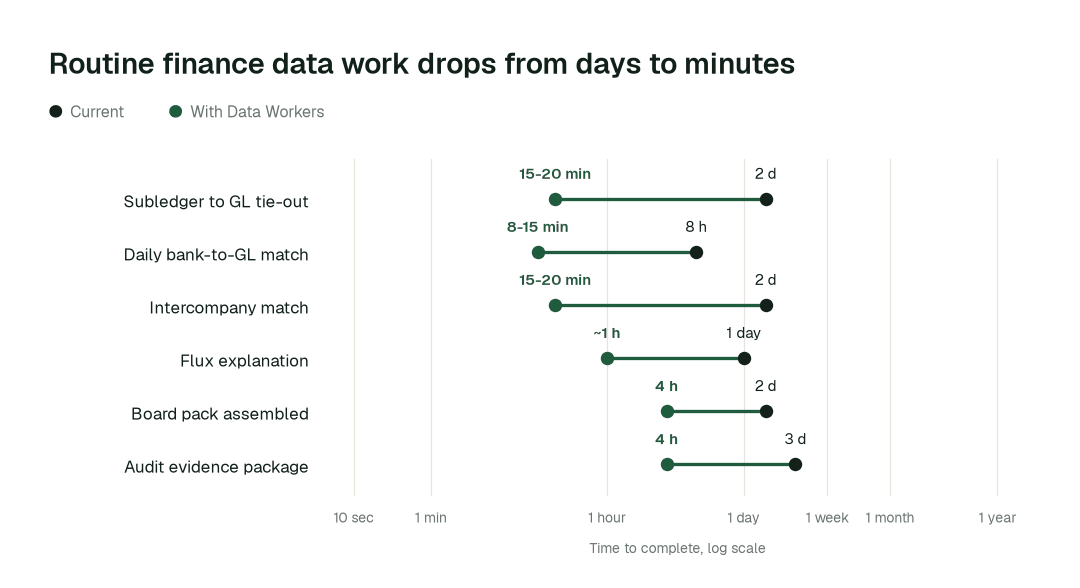
The biggest change is the intercompany match: from about a week to 15-20 min. Work that waited in queues finishes in minutes or hours, because agents detect, trace and verify in one pass.
3. Match bank, billing and intercompany on every load, and trace each break
Unmatched items age. A day-old item has one explanation; at close it has six.
Why it's harder than it looks: Most breaks are not data faults. They are cut-off timing, a missed renewal, a duplicate or an FX rate taken on different dates, so a generic anomaly flag tells the reviewer nothing. The useful output is a cause with the records attached.
- 1.On each load, the Quality Monitoring agent runs
run_quality_checkfor bank to cash, billing to revenue and each intercompany pair. - 2.The Incident Debugging agent calls
get_root_causefor every difference andget_incident_historyto see whether the pair has broken this way before. - 3.It sorts each break into a data fault (fixed through the normal change route) or an accounting item (written up, never adjusted by the agent). The assistant controller or account owner decides the treatment.
Related: data reconciliation.
4. Explain flux as the month runs, linked to transactions
A variance explanation written on day four is a memory. One computed daily is evidence.
Why it's harder than it looks: Flux spans accounts, entities, periods and drivers at once, and the reviewer wants to click from "revenue up 6%" to the invoices behind it. That only works if every layer reads the same account hierarchy. Commentary that cannot be traced is what the auditor challenges first.
- 1.The Quality Monitoring agent uses
get_anomaliesto separate material moves from noise as the month runs. - 2.The Incident Debugging agent names the driver with
get_root_cause: volume, price, timing or a mapping change. - 3.The Data Context & Catalog agent links each move to its source lines with
trace_cross_platform_lineage. - 4.The account owner reviews a drafted explanation with the transactions attached, edits it and signs.
Detail: flux and variance analysis.
5. Govern one definition of each metric before AI reads the ledger
Revenue, bookings, headcount and spend each have several versions in a typical company. An assistant pointed at the wrong one makes every disagreement faster.
Why it's harder than it looks: The definitions are not wrong; they serve different purposes. FP&A, the controller and the business each need a view, and the conflict appears only when one number must serve all three. Picking a winner in a meeting does not survive the next reorg.
- 1.The Data Context & Catalog agent records each definition with
define_business_ruleand serves it throughresolve_metric. - 2.
generate_documentationwrites the plain-English page for each finance data product, with owner and lineage. - 3.The Data Access & Governance agent keeps payroll and executive compensation to the allowed roles with
check_policy. - 4.A change to a definition goes to its owner, usually the controller or head of FP&A, as a proposal that shows every report it would move.
6. Hold entries, adjustments and published numbers for a named approver
For anything that changes reported results, accountability matters more than speed.
Why it's harder than it looks: There are two failure modes. Either everything waits for review and the benefit disappears, or a fix goes straight through and is reversed after a complaint. The workable rule separates reversible work (reruns, remaps, documentation) from work that shapes reported results (entries, accruals, eliminations, forecasts), and keeps the preparer from ever being the approver.
- 1.The Data Access & Governance agent assembles each proposed adjustment with its evidence, lineage and accounts affected, and calls
request_governance_review. - 2.The Autonomous Data-Conductor checks that downstream numbers still hold and routes one decision to the named owner.
- 3.The controller, account owner or CFO approves or declines; unanswered requests expire and escalate.
- 4.A person posts the entry in the ERP through your existing approval workflow. No agent posts to the ledger.
How approvals work: how approvals work for AI data agents. For undoing a change afterwards, see how to roll back an agent's change. By task class, the balance looks like this:
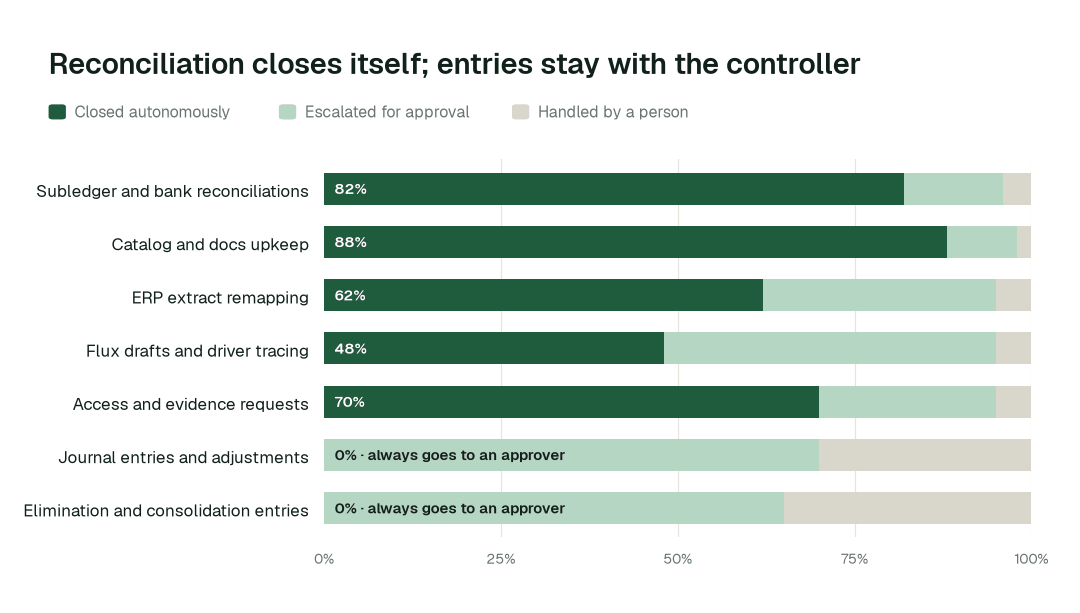
Catalog and docs upkeep closes autonomously 88% of the time. For journal entries and adjustments, autonomous closure is 0% by design: every entry is prepared as a proposal and approved by a named person.
7. Capture audit evidence as the work happens
An audit request should be an export, not a project.
Why it's harder than it looks: Auditors ask who changed what, who approved it and whether a figure traces to source. Each answer lives in a different place (tickets, chat, the ERP change log, the warehouse), and reconstructing it weeks later depends on memory.
- 1.Every agent action, approval and change lands in a tamper-evident audit trail, which the Observability agent surfaces with
get_audit_trail. - 2.The Data Access & Governance agent logs each grant through
provision_access. - 3.When the request arrives, it runs
generate_audit_reportfor the control, period and report in scope. - 4.The control owner reviews the package and sends it. Your controls and assessors decide whether it satisfies the requirement.
Designing the autonomy ladder
Autonomy is set per task class, not per tool. L0 is manual, L1 observes, L2 proposes, L3 acts reversibly and L4 runs on its own (the levels in full). Every deployment starts at L1. L0 to L2 run today. L3 and L4 are where a domain can go on evidence, never on a date, and a class that touches reported results stops at L2.
| Task class | L0 | L1 | L2 | L3 | L4 |
|---|---|---|---|---|---|
| Load and tie-out checks | Today | Today | Today | On evidence | On evidence |
| ERP change remapping | Today | Today | Today | On evidence | Not set |
| Catalog and docs upkeep | Today | Today | Today | On evidence | On evidence |
| Flux drafts and accrual flags | Today | Today | Today, owner reviews | Not set | Not set |
| Entries, adjustments, eliminations | Today | Today | Ceiling | Never | Never |
| Published forecasts and board numbers | Today | Today | Ceiling | Never | Never |
"On evidence" means the receipts for that class are clean and the domain owner chooses to raise the level.
The operating model: who owns what
Agents change who does the work, not who is accountable for it:
| Role | Owns | What the agents take off their plate |
|---|---|---|
| Controller or Head of Finance Data | Standards, autonomy per domain, which entity goes next | Assembling status, chasing owners, keeping the checklist current |
| Account owners and approvers | Entries, accruals, eliminations, flux commentary, published numbers | Preparing evidence, lineage and rollback plan for every proposal |
| Analytics and data engineers | Reviewing agent proposals, building forecasting and spend products | Remapping extracts, writing tie-out tests, tracing breaks |
The swarm behind the practices
Each practice is a hand-off between specialists, under the autonomy you set per domain.
| Agent | Public tools it calls | What it does for finance data |
|---|---|---|
| Connectors | get_connector_status, get_dbt_run_history | Lands ERP, subledger, bank and AP data and confirms every load |
| Schema Evolution | detect_schema_change, generate_migration | Detects ERP changes and remaps extracts |
| Quality Monitoring | run_quality_check, get_anomalies, set_sla | Ties subledgers, bank and intercompany balances |
| Incident Debugging | get_root_cause, get_incident_history | Traces a break or flux move to its record |
| Data Context & Catalog | trace_cross_platform_lineage, resolve_metric | One definition per metric, figures linked to sources |
| Data Access & Governance | request_governance_review, generate_audit_report | Role rules, review requests, audit evidence |
Data Context Wizard holds one governed definition of revenue, bookings, headcount, spend and each account hierarchy. Autonomous Data-Conductor verifies the numbers that matter before the flash report and board pack go out. Spellbook Data Catalog makes each finance data product discoverable for controllers, analysts and auditors, in plain English.
What disappears
- •The day-two hunt for a difference nobody can find.
- •The last-week rebuild of reconciliations in spreadsheets.
- •The report that went out wrong after an ERP upgrade.
- •The flux package written from memory.
- •The argument over which revenue number the board sees.
- •The three-week scramble to answer an evidence request.
None of this is one agent. The back office keeps running: bad data is caught where it enters, and fixes are rerun, verified and explained before the controller opens the checklist. Every action leaves a signed receipt, so the team can see what happened and reverse anything reversible.
A controller's scorecard
These are targets, set against a baseline you measure first:
- •Subledger tie-out: from about a week to 15-20 min
- •Flux explained: from about 3 days to about an hour
- •Audit evidence package: from about 2 weeks to 4 h
- •Closes where every subledger ties by the deadline: every one
- •ERP change to verified remap: inside the same working day
- •Catalog and docs upkeep closed autonomously: targeting 88% as the deployment matures
- •Entries and adjustments with a named approver on record: 100%
Where this goes next
Once one entity runs these practices, the constraint is the number of entities. A new company code or an acquired subsidiary becomes a mission with a checklist, and real-time reporting follows: with ERP, billing and warehouse data tied continuously, a flash report is current on any day of the month.
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For finance data teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; entries, adjustments and published numbers always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: tie-outs run daily, ERP changes are remapped before reports publish and evidence is captured as work happens.
- •The agentic enterprise. A finance data team that ships forecasting and spend products instead of rebuilding the tie-out. People set direction, and the platform carries it out.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how finance data teams start
- •What we connect. Your ERP extracts, subledgers and bank files, Snowflake or Databricks, dbt, Airflow and the BI tools finance reads, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Daily tie-out and the close checklist for one entity.
- •First week. Agents run at L1 across the scoped entity. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Daily subledger and bank tie-outs and ERP change remapping start running on reversible work. Adjustments, accruals and published numbers stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •Subledger tie-out: from about a week to 15-20 min
- •Flux explained: from about 3 days to about an hour
- •Audit evidence package: from about 2 weeks to 4 h
- •the share of catalog and docs upkeep closed autonomously, targeting 88% as the deployment matures
- •What you decide. Whether to expand to the next entity or process. The pilot fee is credited in full against the first year.
- •The guarantee. In a 90-day pilot, ten engineering hours per data engineer per week are recovered against a baseline both sides sign on day one, or the $7,500 fee is refunded.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
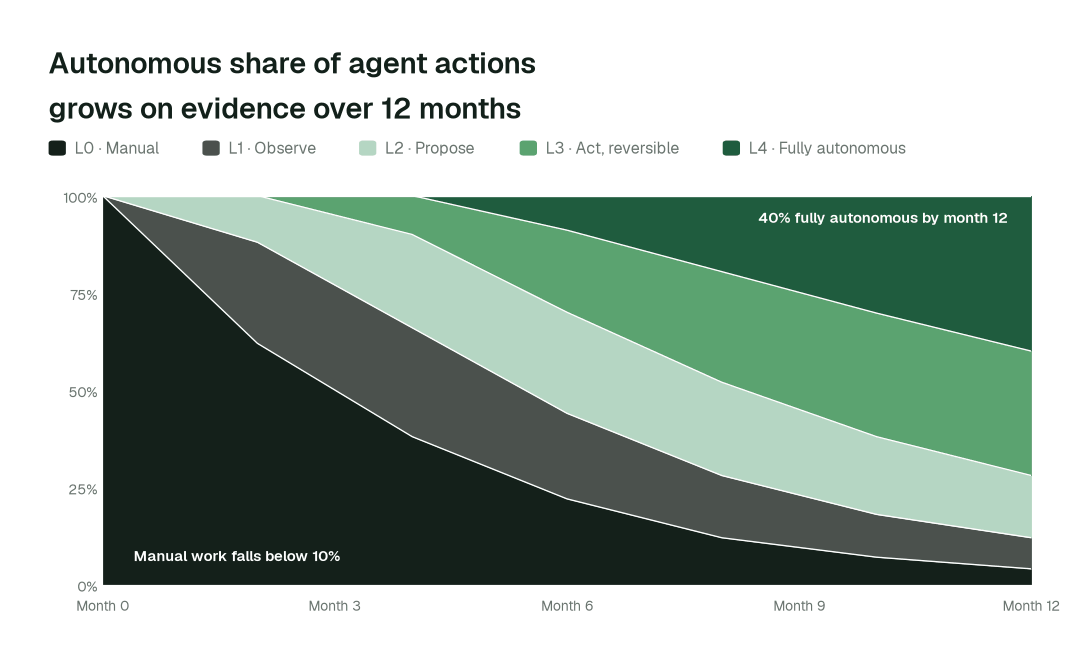
By month 12, more than 40% of agent actions run fully autonomously and manual work falls below 10%, while entries and published numbers stay with a named approver.