Best practices for agentic data platforms: a field guide for platform and fleet data teams
A data platform is only as good as the contracts behind it. This report covers how platform teams use agents to keep data products joinable, governed and affordable.
Platform teams build the internal data platform itself: the governed layer that brings fleet, machine, cost and usage data together as authoritative data products. They exist at cloud providers, infrastructure companies, SaaS platforms and every large engineering organization.
Their problems are structural. Producers ship schemas without warning, identifiers do not join across sources, onboarding is a queue, and cost grows with every source. The platform team becomes a bottleneck for the very teams it serves.
Agents let the platform scale with its producers: contracts enforced on every deploy, sources onboarded as missions, cost visible per product and cleanups run safely.
The old world
A producing team renames a node identifier. Fleet dashboards break and the platform team learns from angry consumers. Twenty new telemetry sources wait in the onboarding queue, and the quarterly spend review finds the warehouse bill up 30% with no clear owner.
The new world
With Data Workers, Schema Evolution caught the contract break on deploy and notified the producer, Pipeline Building updated the mapping, and join rates recovered before consumers noticed. Onboarding runs as a mission. A cost mission across 100 pipelines cut spend without missing an SLA.
Here is that new world as a chain of hand-offs between agents:
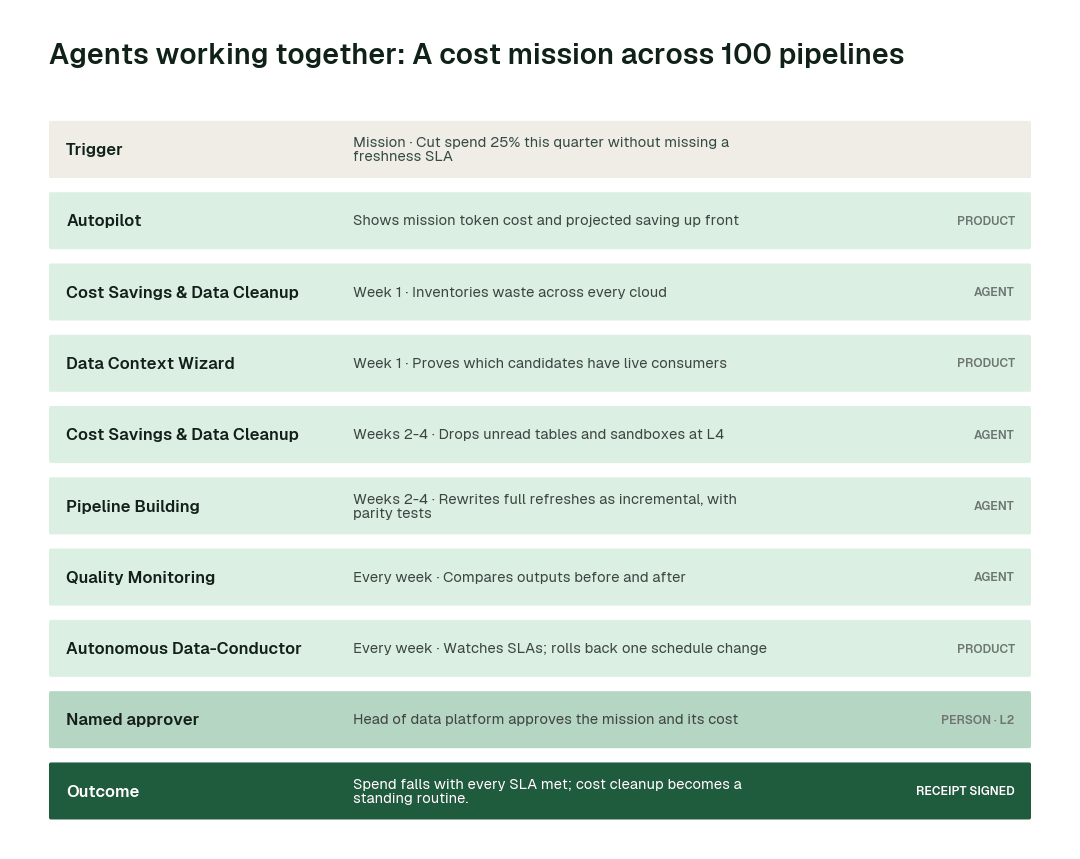
The full playbook walks through this scenario and three more use cases in depth.
The rest of this report walks through the 6 practices that make that morning possible. At a glance:
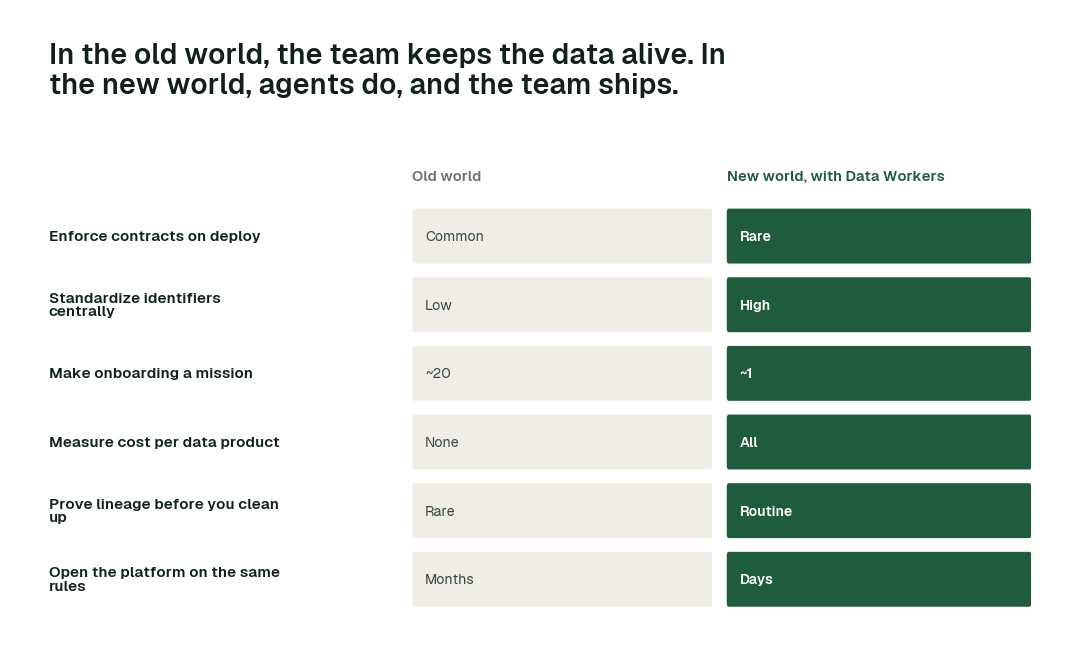
The practices, one by one
1. Enforce contracts on deploy
Producers should find out they broke a contract before consumers do.
The old world. Consumers find out in production.
The new world. Schema Evolution checks contracts on every producer change.
In practice. A rename is caught at deploy.
What to measure. Contract breaks reaching consumers.
2. Standardize identifiers centrally
Products that do not join are not products.
The old world. Each product has its own IDs.
The new world. Context Wizard holds standard identifiers and Pipeline Building maintains mappings.
In practice. Fleet products join on one node ID.
What to measure. Cross-product join rate.
Practices like these compound. Across the routine work they cover, here is the difference in elapsed time:
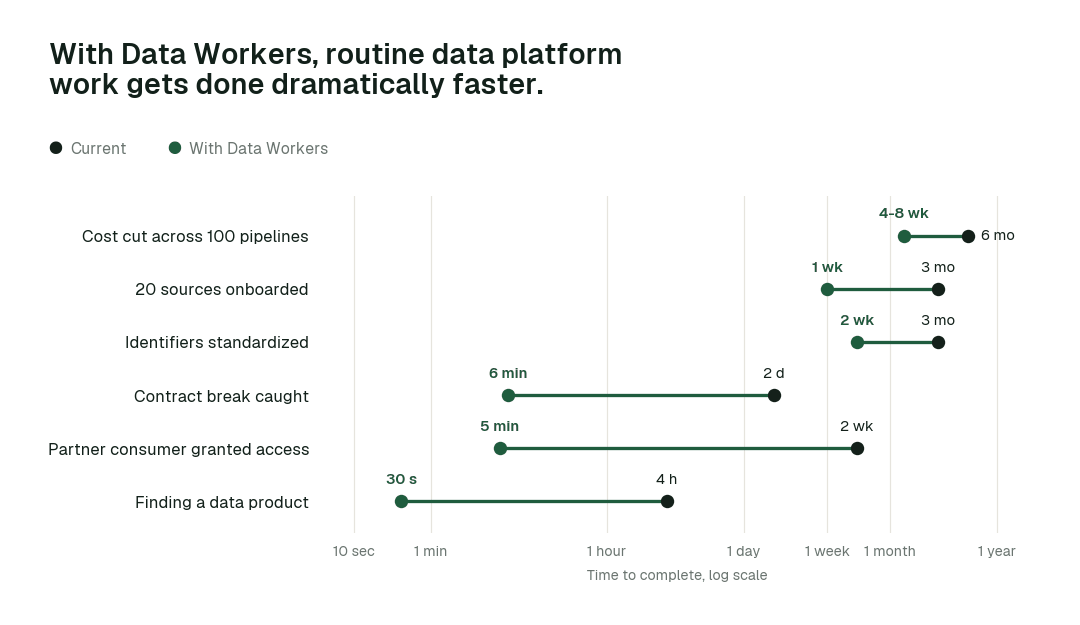
The biggest change is Partner consumer granted access: from about 2 weeks to 5 min. Work that waited in queues finishes in minutes or hours, because agents detect, fix and verify in one pass.
3. Make onboarding a mission
Source onboarding should not be a queue.
The old world. Weeks per source.
The new world. Autopilot onboards sources to staging with profiling and contracts.
In practice. Twenty sources in a week.
What to measure. Days to onboard a source.
4. Measure cost per data product
Cost should be visible where decisions are made.
The old world. One bill, no owners.
The new world. The Autopilot dashboard shows cost and autonomy per product.
In practice. Each product owner sees its spend.
What to measure. Products with visible cost.
5. Prove lineage before you clean up
Cleanups fail when dependencies are guessed.
The old world. Abandoned cleanups.
The new world. Context Wizard checks every consumer first.
In practice. A cost mission cuts spend safely.
What to measure. Spend reduced without SLA misses.
That balance, autonomy where work is reversible and a named approver where it matters, shows up clearly by task class:
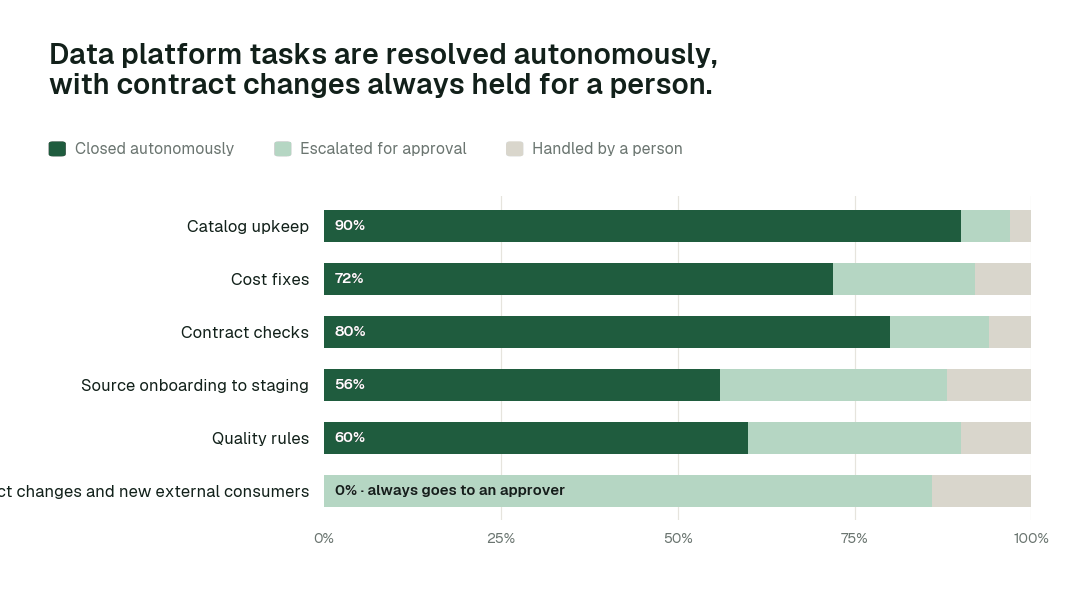
Catalog upkeep closes autonomously 90% of the time. For Contract changes and new external consumers, autonomous closure is 0% by design: every change is proposed with a full diff and approved by a named person.
6. Open the platform on the same rules
External access should reuse the internal security model.
The old world. A separate project.
The new world. Access & Governance applies the same policies to partner consumers.
In practice. Two partners onboard without new infrastructure.
What to measure. Days to onboard an external consumer.
Designing the autonomy ladder
Autonomy is set per task class, not per tool. This is where we would set each class for a mature deployment, and why:
| Task class | Closed autonomously | Escalated | Handled by a person | Where we set it | Why |
|---|---|---|---|---|---|
| Catalog upkeep | 90% | 7% | 3% | L4 once the receipts are clean | The work is reversible and repeatable |
| Cost fixes | 72% | 20% | 8% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Contract checks | 80% | 14% | 6% | L4 once the receipts are clean | The work is reversible and repeatable |
| Source onboarding to staging | 56% | 32% | 12% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Quality rules | 60% | 30% | 10% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Contract changes and new external consumers | 0% | 86% | 14% | L2: always proposed to a named approver | The number carries accountability outside the data team |
The operating model: who owns what
Agents change who does the work, not who is accountable for it:
| Role | Owns | What the agents take off their plate |
|---|---|---|
| Data Platform PM | Standards, autonomy levels per domain and which domain goes next | Assembling status, chasing owners, keeping the catalog current |
| Domain owners and approvers | Contract changes and new external consumers | Preparing the diff, blast radius and rollback plan for every proposal |
| Data engineers | Reviewing agent proposals and building new data products | Every producer deploy is checked against its data contract; unused tables, oversized jobs and stale copies are cleaned up continuously after lineage proves they are safe |
The swarm behind the practices
No single agent delivers these practices. Each one is a hand-off between specialists, coordinated under the autonomy you set per domain.
| Agent | What it does for data platform teams |
|---|---|
| Connectors and Data Ingestion | Onboard new sources and profile them against the platform's standards |
| Schema Evolution | Enforces data contracts and versions every producer change |
| Pipeline Building | Builds and standardizes data products and identifier mappings |
| Quality Monitoring | Contract, freshness and join-rate checks on every data product |
| Data Access & Governance | Applies the platform's security model to internal and partner consumers |
| Cost Savings & Data Cleanup | Keeps storage and compute per data product in check |
Context Wizard holds the standard identifiers and definitions every product joins on. Conductor watches every contract and SLA and handles breaks. Spellbook is the platform's catalog, with every product's owner, contract version, SLA and consumers on one page. Autopilot shows autonomy and cost per data product.
What disappears
The clearest sign the practices are working is what stops happening:
- •Consumers finding contract breaks.
- •Onboarding queues.
- •Unowned spend growth.
- •Abandoned cleanups.
- •Products that do not join.
- •Separate projects for partner access.
The magic is not any single agent. It is that the back office simply keeps running. Bad data is caught where it enters, not where it is read. Every new table gets quality rules and documentation without anyone writing them. Access follows policy instead of a queue. Fixes are rerun, verified and explained before anyone opens a dashboard. Cost is cleaned up every week instead of every budget cycle. And every one of those actions leaves a signed receipt, so the team can see exactly what happened and roll anything back. For the people on the team, the experience is quieter mornings, fewer tickets and more time for the products the business asked for.
A product manager's scorecard
If you own this data as a product, these are the numbers to bring to every quarterly review:
- •Contract breaks reaching consumers
- •Days to onboard a source
- •Cross-product join rate
- •Cost per data product
- •SLA misses during cost work
- •Share of upkeep autonomous
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For data platform and fleet data teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; contract changes and new external consumers always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: every producer deploy is checked against its data contract, unused tables, oversized jobs and stale copies are cleaned up continuously after lineage proves they are safe, and new sources are onboarded to staging with profiling, a contract and documentation. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. A platform team that scales with its producers instead of becoming their bottleneck. People set direction, and the platform carries it out.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how data platform and fleet data teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. Snowflake, Databricks and BigQuery; Kafka; dbt; Airflow or Dagster; a catalog (Unity Catalog, DataHub, OpenMetadata); cost and usage telemetry, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. A cost mission on one domain.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Every producer deploy is checked against its data contract and unused tables, oversized jobs and stale copies are cleaned up continuously after lineage proves they are safe start running on reversible work. Contract changes and new external consumers stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •Partner consumer granted access: from about 2 weeks to 5 min
- •Contract break caught: from about 2 days to minutes
- •Finding a data product: from about 4 hours to 30 s
- •the share of catalog upkeep closed autonomously, targeting 90% as the deployment matures
- •What you decide. Whether to expand to the next domain. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
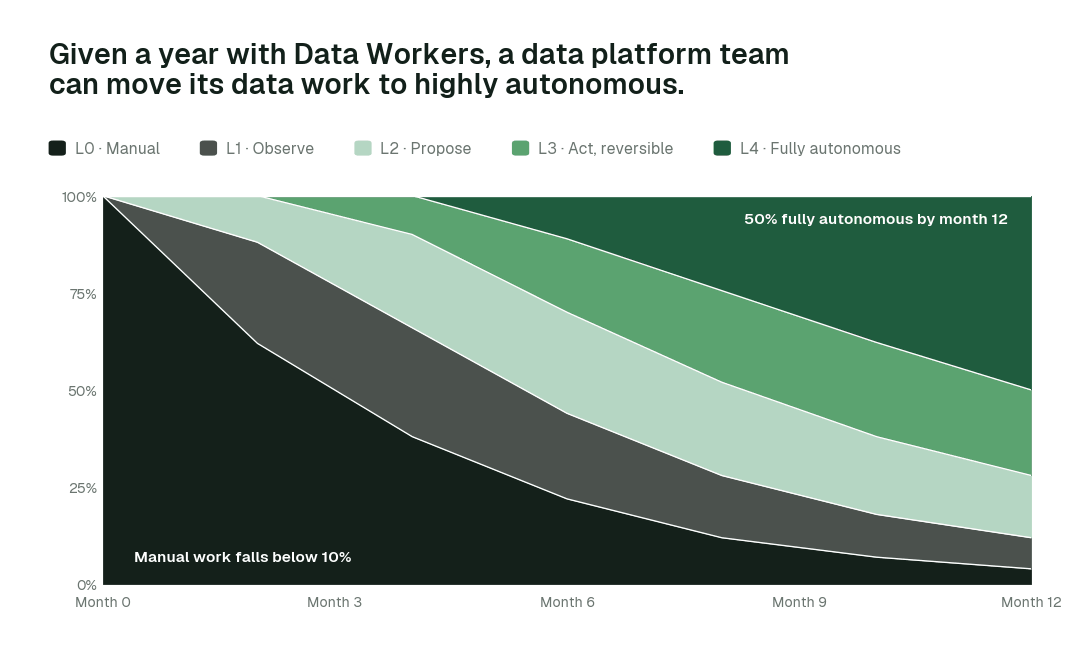
By month 12, more than 50% of agent actions run fully autonomously and manual work falls below 10%, while contract changes stay with a named approver.
Read the full playbook: Data platform, fleet data and platform engineering teams