Best practices for agentic Customer 360 and CDP data: a field guide for Customer 360 and CDP teams
How Customer 360 and CDP teams move their data back office to agents, practice by practice: the state of the space, the old world and the new, what the agents do step by step, how to set autonomy, who owns what, and how to start.
The customer profile is now the input to every AI agent that talks to customers.
Identity, consent and freshness need continuous checks agents can run.
The state of the space
Teams that unify customer identity across CRM, commerce, marketing, support and product into one profile and activate it: Salesforce Data Cloud and CDP owners, Customer 360 product teams, martech data engineering. Titles include Salesforce PM (Marketing & Data Clouds), Customer 360 Lead and CDP Product Owner.
Every company now runs a customer data platform and expects AI agents to personalize on top of it. The profile is only as good as identity resolution, consent and freshness behind it, and those break quietly. Agents can keep identity, consent and segments correct so marketing and service teams trust what they activate.
The old world
An opt-out export fails; the nightly audience syncs to ad platforms with opted-out customers; legal finds out a week later.
It is rarely one failure. Three patterns repeat:
- •Profiles that collided. A shared email merges two households; offers go to the wrong person.
- •Opt-outs before the next audience. A consent change must reach audiences before the next sync.
- •Customer context for service agents. AI service agents need the same profile as marketing.
The new world
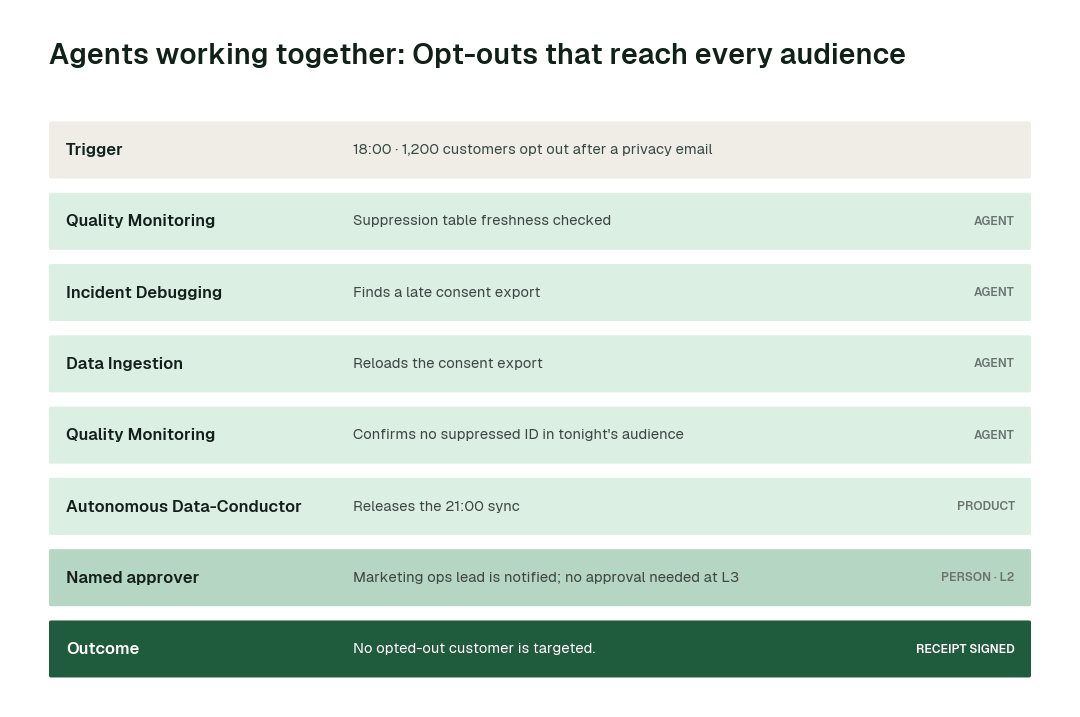
The stale suppression table was caught at 19:30, the export rerun and the audience verified before the 21:00 sync.
Here is that new world as a chain of hand-offs between agents:
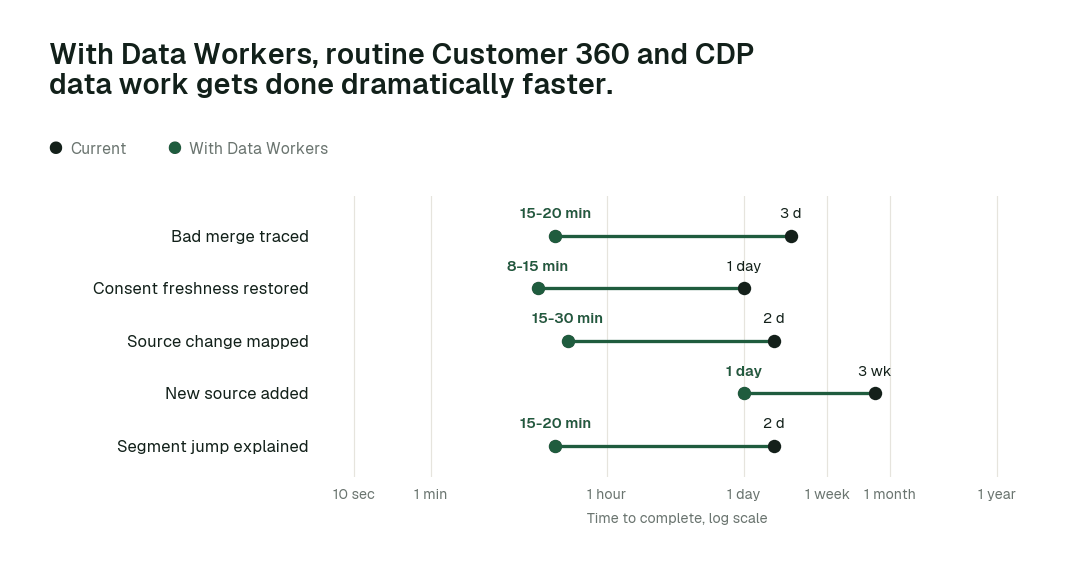
These are the impact metrics we move:
- •Bad merge traced: from about 3 days to 15-20 min
- •Segment jump explained: from about 2 days to 15-20 min
- •Consent freshness restored: from about a day to 8-15 min
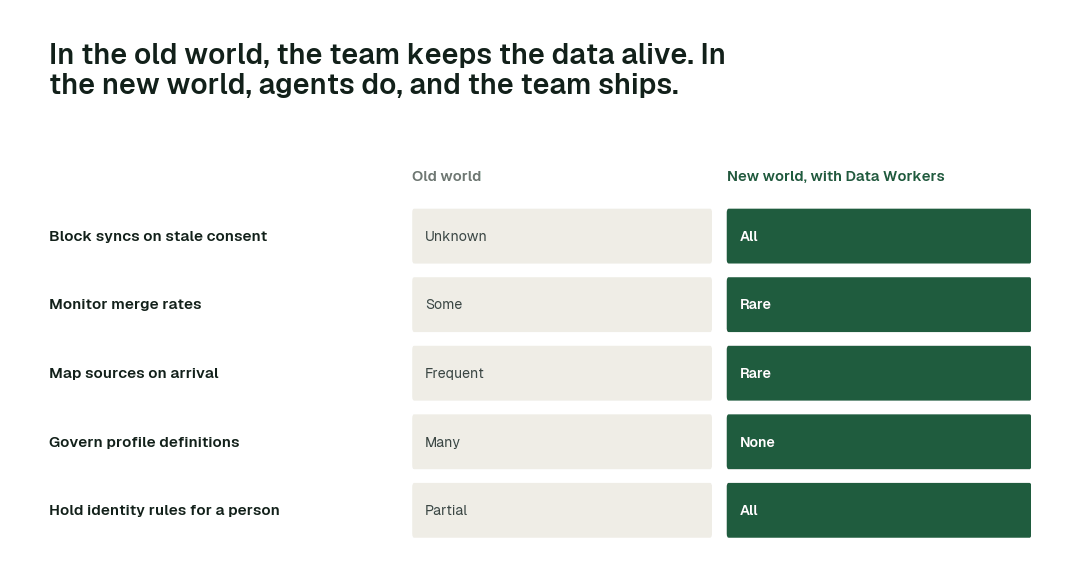
The rest of this report walks through the 5 practices that make that possible. At a glance:
The practices, one by one
1. Block syncs on stale consent
Opt-outs must win the race.
Why it is harder than it looks. Consent changes and audience syncs race each other every night.
The old world. Hope.
The new world. set_sla and blocking checks.
What the agents do, step by step:
- 1.The Quality Monitoring agent calls
set_slaand sets freshness on suppression. - 2.The Incident Debugging agent calls
diagnose_incidentand finds failed exports. - 3.The Autonomous Data-Conductor calls
verify_dataand blocks the sync until fresh.
In practice. No opted-out customer synced.
What to measure. Syncs with fresh consent.
2. Monitor merge rates
Bad merges are silent.
Why it is harder than it looks. Bad merges look like normal data until a customer complains.
The old world. Complaints.
The new world. Quality Monitoring on match and merge rates.
What the agents do, step by step:
- 1.The Quality Monitoring agent calls
get_anomaliesand watches merge rates. - 2.The Incident Debugging agent calls
get_root_causeand traces the rule. - 3.The Autonomous Data-Conductor calls
request_governance_reviewand proposes the fix.
In practice. A collision caught on the first spike.
What to measure. Bad merges reaching activation.
Practices like these compound. Across the routine work they cover:
3. Map sources on arrival
Sources change weekly.
Why it is harder than it looks. Every commerce or CRM release can move a field.
The old world. Broken ingestion.
The new world. Schema Evolution.
What the agents do, step by step:
- 1.The Schema Evolution agent calls
detect_schema_changeand catches it. - 2.The Schema Evolution agent calls
generate_migrationand maps it. - 3.The Pipeline Building agent calls
validate_pipelineand tests it.
In practice. A commerce field rename absorbed.
What to measure. Ingestion breaks.
4. Govern profile definitions
Agents and humans must agree.
Why it is harder than it looks. Service agents and marketing must see the same customer.
The old world. Different profiles.
The new world. Context Wizard.
What the agents do, step by step:
- 1.The Data Context & Catalog agent calls
define_business_ruleand defines the profile. - 2.The Data Context & Catalog agent calls
mark_authoritativeand sets the source. - 3.The Data Context & Catalog agent calls
trace_cross_platform_lineageand shows consumers.
In practice. One customer.
What to measure. Profile discrepancies.
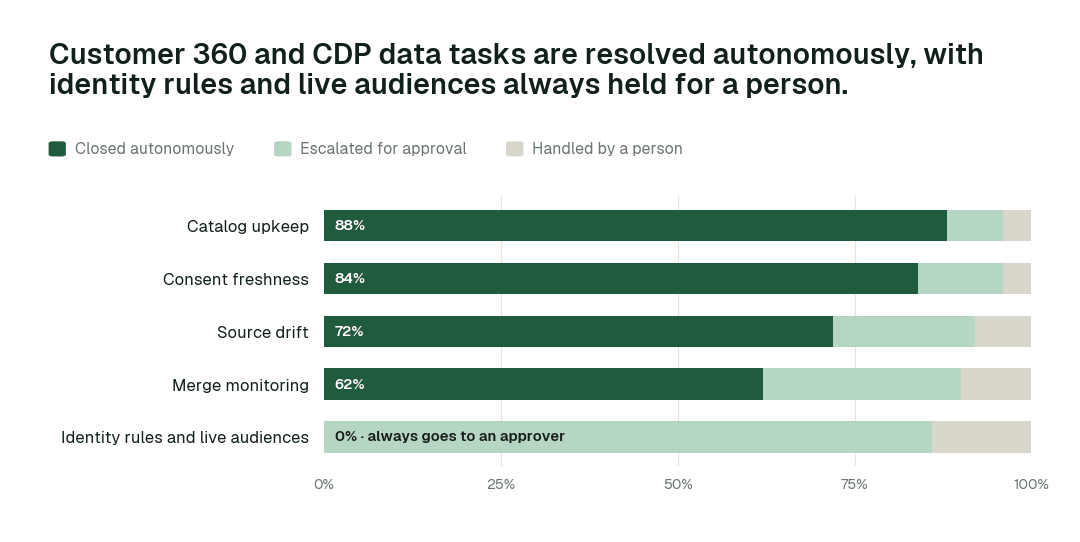
Autonomy where work is reversible, a named approver where it matters:
5. Hold identity rules for a person
Rules change who gets what.
Why it is harder than it looks. Identity rules decide who receives what.
The old world. Ad hoc.
The new world. L2 approvals.
What the agents do, step by step:
- 1.The Data Context & Catalog agent calls
blast_radius_analysisand shows affected audiences. - 2.The Autonomous Data-Conductor calls
request_governance_reviewand holds at L2. - 3.The Data Access & Governance agent calls
generate_audit_reportand records it.
In practice. Every rule change approved.
What to measure. Rule changes with approver.
Designing the autonomy ladder
Autonomy is set per task class, not per tool. This is where we would set each class for a mature deployment, and why:
| Task class | Closed autonomously | Escalated | Handled by a person | Where we set it | Why |
|---|---|---|---|---|---|
| Catalog upkeep | 88% | 8% | 4% | L4 once the receipts are clean | The work is reversible and repeatable |
| Consent freshness | 84% | 12% | 4% | L4 once the receipts are clean | The work is reversible and repeatable |
| Source drift | 72% | 20% | 8% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Merge monitoring | 62% | 28% | 10% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Identity rules and live audiences | 0% | 86% | 14% | L2: always proposed to a named approver | The number carries accountability outside the data team |
The operating model: who owns what
Agents change who does the work, not who is accountable for it:
| Role | Owns | What the agents take off their plate |
|---|---|---|
| Customer 360 Product Lead | Standards, autonomy levels per domain and which domain goes next | Assembling status, chasing owners, keeping the catalog current |
| Domain owners and approvers | Identity rules, consent logic and live audiences | Preparing the diff, blast radius and rollback plan for every proposal |
| Data engineers | Reviewing agent proposals and building new data products | Consent freshness is checked before every audience sync; merge and match rates are monitored |
The swarm behind the practices
| Agent | What it does for you | Tools it calls |
|---|---|---|
| Connectors and Data Ingestion | Land CRM, commerce, support and product sources | get_connector_status, trigger_airflow_dag, get_dbt_run_history |
| Schema Evolution | Maps source changes into the profile model | detect_schema_change, validate_schema_compatibility, generate_migration, rollback_migration |
| Quality Monitoring | Match rates, merge anomalies and consent freshness | set_sla, run_quality_check, get_anomalies, create_quality_tests_for_pipeline |
| Incident Debugging | Traces segment jumps and bad merges | diagnose_incident, get_root_cause, prepare_backfill, execute_backfill |
| Data Security | Classifies personal data | scan_pii, review_pii_writes, pci_card_data_masking |
| Data Context & Catalog | Governed profile and segment definitions | trace_cross_platform_lineage, blast_radius_analysis, define_business_rule, generate_documentation |
Data Context Wizard keeps one governed graph of definitions, lineage and owners that every agent and person answers from. Autonomous Data-Conductor runs each job from detection to a verified result. Spellbook Data Catalog is where your team approves, audits and rolls back, and asks questions in plain English.
What disappears
- •Opted-out customers in audiences.
- •Household collisions.
- •Broken ingestion after source changes.
- •Unexplained segment jumps.
- •Two different profiles.
The magic is not any single agent. It is that the back office keeps running: bad data is caught where it enters, every new table gets quality rules and documentation without anyone writing them, access follows policy, fixes are verified before anyone opens a dashboard, and every action leaves a signed receipt.
A product manager's scorecard
| Metric | How to read it |
|---|---|
| Syncs with fresh consent | Baseline it in the first week of the pilot; review it monthly. |
| Bad merges reaching activation | Baseline it in the first week of the pilot; review it monthly. |
| Ingestion breaks | Baseline it in the first week of the pilot; review it monthly. |
| Profile discrepancies | Baseline it in the first week of the pilot; review it monthly. |
| Days to add a source | Baseline it in the first week of the pilot; review it monthly. |
Where this goes next
CDPs will become the customer context layer for every AI agent in the company, and consent will be enforced by the data itself. Teams that automate identity and consent checks first will personalize fastest with the least risk.
The climb: from assisted to autonomous to agentic
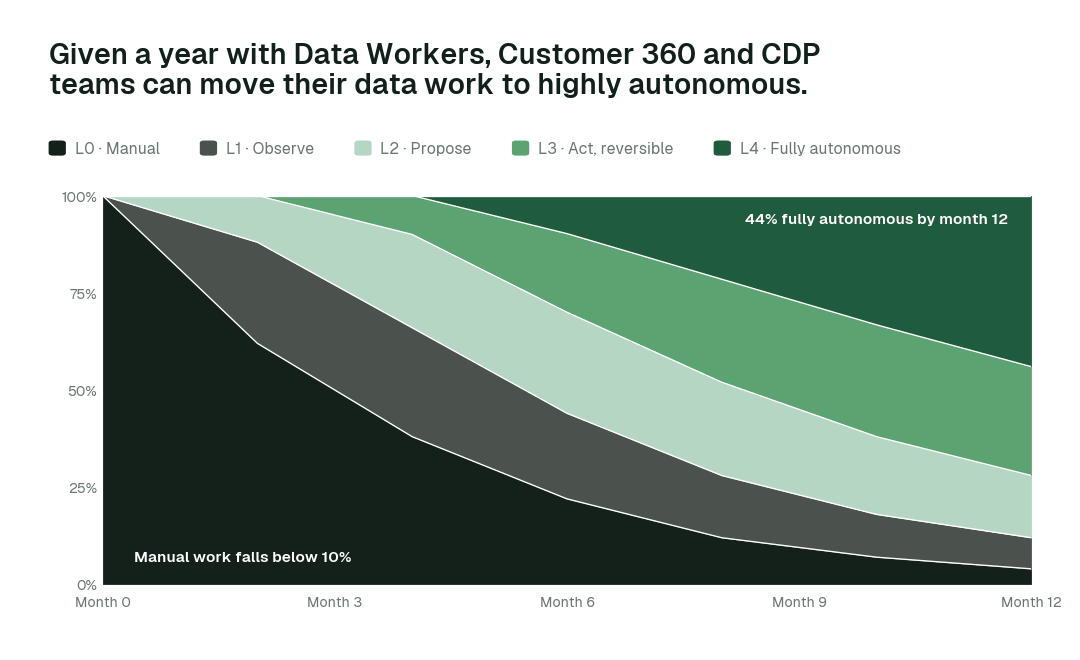
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For Customer 360 and CDP teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; identity rules, consent logic and live audiences always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: consent freshness is checked before every audience sync, merge and match rates are monitored, and source changes are mapped on arrival. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. CDPs will become the customer context layer for every AI agent in the company, and consent will be enforced by the data itself. Teams that automate identity and consent checks first will personalize fastest with the least risk.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how Customer 360 and CDP teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. Salesforce Data Cloud or a composable CDP on Snowflake/BigQuery; Segment or RudderStack; Hightouch or Census; dbt; consent platforms, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Consent freshness and merge monitoring on one brand at L3.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Consent freshness is checked before every audience sync and merge and match rates are monitored start running on reversible work. Identity rules, consent logic and live audiences stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •Bad merge traced: from about 3 days to 15-20 min
- •Segment jump explained: from about 2 days to 15-20 min
- •Consent freshness restored: from about a day to 8-15 min
- •the share of catalog upkeep closed autonomously, targeting 88% as the deployment matures
- •What you decide. Whether to expand to the next domain. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
Read the full playbook: Data Workers for Customer 360 and CDP teams