Best practices for agentic claims data: a field guide for payer and clearinghouse data teams
Claims data moves money. This report covers how payer and claims data teams keep partner feeds, code sets and linkage reliable with an agentic back office.
Health plans, clearinghouses and payer-provider exchange platforms run on files from hundreds of trading partners. Claims, eligibility, remittance and prior-auth data feed risk adjustment, quality programs, actuarial models and value-based contracts.
Every one of those uses is payment-affecting. A resent file, a code-set update or a broken member match does not just break a dashboard; it changes what someone gets paid. That is why claims data teams are cautious, and why they are buried in manual checks.
Agents let these teams be fast and careful at once: everything reversible runs automatically, and anything that touches payment is proposed with evidence to a named person.
The old world
A provider group resends March with corrections. Both versions load. Paid amounts for that group double in the risk-adjustment run until an actuary notices a week later. Meanwhile the quarterly code-set update is a two-week project, and 12 new provider groups wait to join the exchange.
The new world
With Data Workers, the resend was fingerprinted on arrival, every table that loaded the first version was found, the corrected data swapped through and paid amounts verified, and the risk-adjustment refresh held for one approval. Code-set updates run as missions, and new groups onboard in a week.
Here is that new world as a chain of hand-offs between agents:
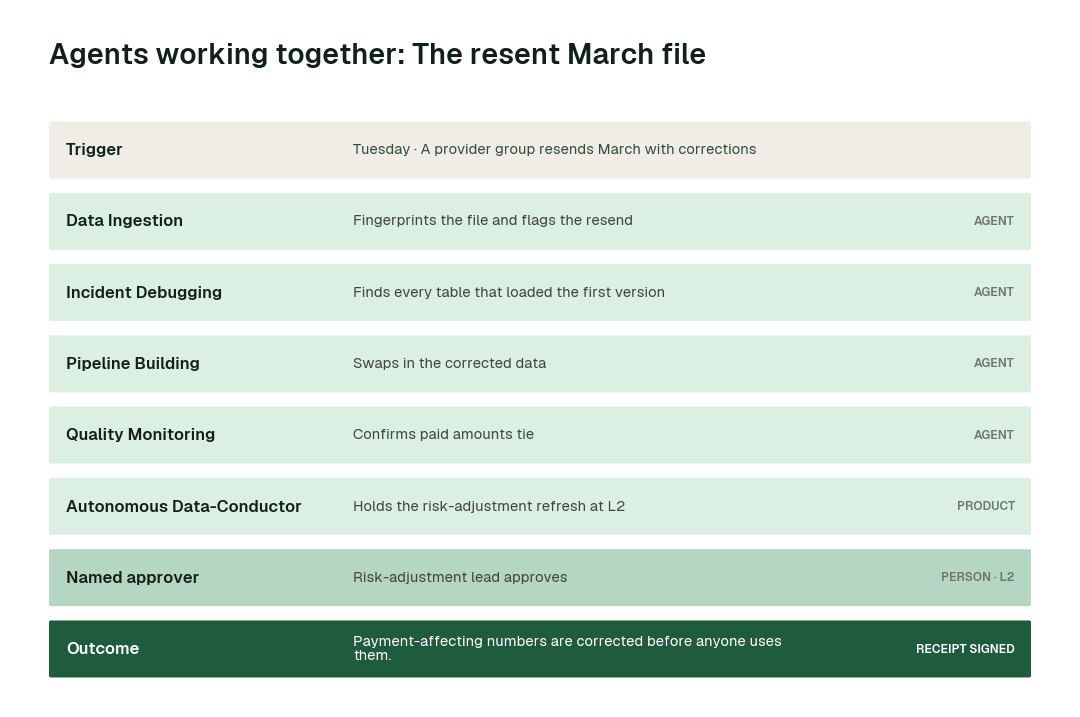
The full playbook walks through this scenario and three more use cases in depth.
The rest of this report walks through the 6 practices that make that morning possible. At a glance:
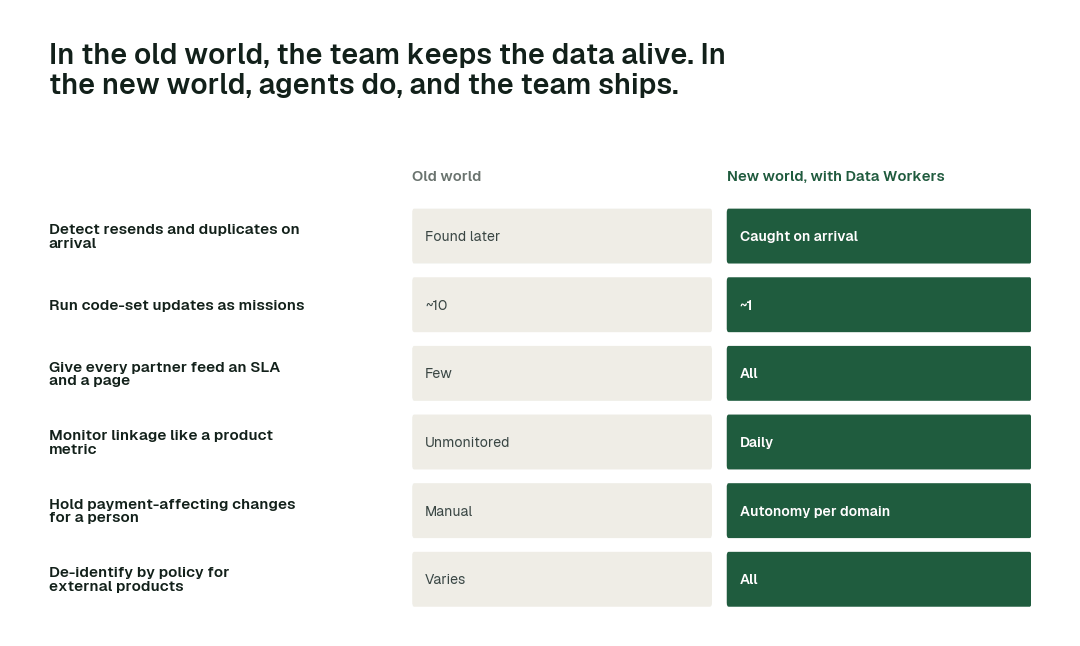
The practices, one by one
1. Detect resends and duplicates on arrival
A resent month double-counts paid amounts.
The old world. Found by actuaries later.
The new world. Data Ingestion fingerprints every file; Incident Debugging swaps corrected versions through.
In practice. A resend is handled before the risk-adjustment run.
What to measure. Duplicate files reaching downstream models.
2. Run code-set updates as missions
ICD-10, CPT, HCPCS and NDC updates ripple everywhere.
The old world. Two-week projects.
The new world. Autopilot runs each update with impact analysis and approvals.
In practice. An NDC update is rolled out in a day.
What to measure. Days per code-set update.
Practices like these compound. Across the routine work they cover, here is the difference in elapsed time:
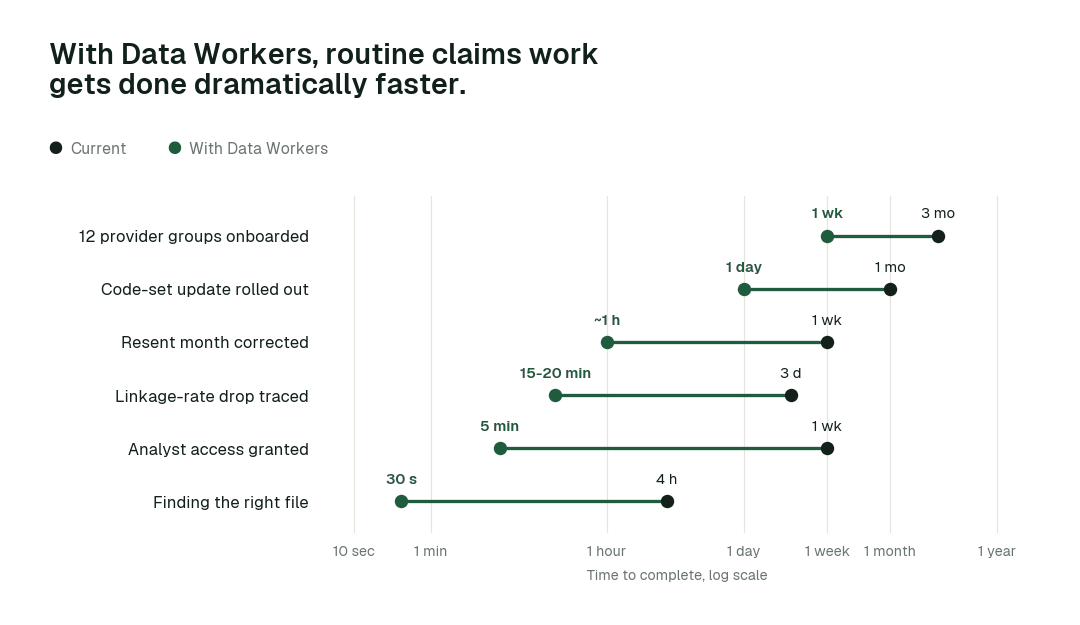
The biggest change is Analyst access granted: from about a week to 5 min. Work that waited in queues finishes in minutes or hours, because agents detect, fix and verify in one pass.
3. Give every partner feed an SLA and a page
Feeds without owners fail silently.
The old world. Informal expectations.
The new world. Spellbook gives each feed a living page with owner, SLA, spec version and history.
In practice. A late partner feed is visible the hour it misses its SLA.
What to measure. Feeds with owner and SLA.
4. Monitor linkage like a product metric
Member matching breaks quietly.
The old world. Found in analyses.
The new world. Quality Monitoring tracks linkage by source and flags drops on the first load.
In practice. An ID format change is caught on day one.
What to measure. Member linkage rate.
5. Hold payment-affecting changes for a person
Speed must not cost accuracy.
The old world. Everything reviewed manually.
The new world. Payment-affecting domains run at L2 with a named approver; the rest runs at L3 and L4.
In practice. Reruns are automatic; risk-adjustment inputs wait for approval.
What to measure. Share of fixes closed autonomously.
That balance, autonomy where work is reversible and a named approver where it matters, shows up clearly by task class:
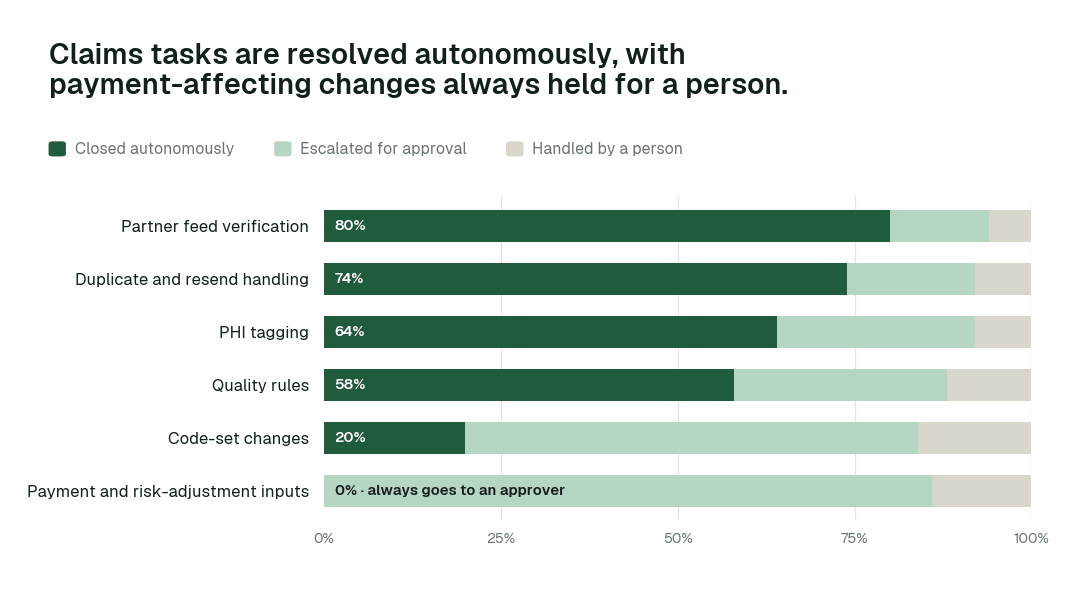
Partner feed verification closes autonomously 80% of the time. For Payment and risk-adjustment inputs, autonomous closure is 0% by design: every change is proposed with a full diff and approved by a named person.
6. De-identify by policy for external products
External datasets need consistent rules.
The old world. Applied by hand.
The new world. Data Security and Access & Governance enforce de-identification on every delivery.
In practice. A partner extract is de-identified the same way every time.
What to measure. External deliveries with policy on record.
Designing the autonomy ladder
Autonomy is set per task class, not per tool. This is where we would set each class for a mature deployment, and why:
| Task class | Closed autonomously | Escalated | Handled by a person | Where we set it | Why |
|---|---|---|---|---|---|
| Partner feed verification | 80% | 14% | 6% | L4 once the receipts are clean | The work is reversible and repeatable |
| Duplicate and resend handling | 74% | 18% | 8% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| PHI tagging | 64% | 28% | 8% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Quality rules | 58% | 30% | 12% | L3: acts and keeps a rollback point | Most cases are routine; the rest escalate with evidence |
| Code-set changes | 20% | 64% | 16% | L3 for routine cases, L2 for the rest | Judgment is needed often enough to keep a person close |
| Payment and risk-adjustment inputs | 0% | 86% | 14% | L2: always proposed to a named approver | The number carries accountability outside the data team |
The operating model: who owns what
Agents change who does the work, not who is accountable for it:
| Role | Owns | What the agents take off their plate |
|---|---|---|
| Director of Payer Data Products | Standards, autonomy levels per domain and which domain goes next | Assembling status, chasing owners, keeping the catalog current |
| Domain owners and approvers | Anything feeding risk adjustment or payment | Preparing the diff, blast radius and rollback plan for every proposal |
| Data engineers | Reviewing agent proposals and building new data products | Every partner file is fingerprinted on arrival, so resends and duplicates are caught before loading twice; partner feeds are tracked against SLAs |
The swarm behind the practices
No single agent delivers these practices. Each one is a hand-off between specialists, coordinated under the autonomy you set per domain.
| Agent | What it does for claims and payer data |
|---|---|
| Connectors and Data Ingestion | Land partner files and APIs, detect resends and duplicates, profile every load |
| Schema Evolution | Maps partner layout changes and code-set updates into downstream models |
| Quality Monitoring | Claim volume by partner, paid-amount ranges, eligibility gaps and duplicate checks |
| Incident Debugging | Traces a broken report to the partner file or code change that caused it |
| Data Security | Classifies PHI and enforces de-identification for external products |
| Data Access & Governance | Applies role and partner policies to every request and logs every grant |
Context Wizard holds governed definitions of a member month, an allowed amount and an attributed member. Conductor reconciles claims against payments and keeps SLAs on partner feeds. Spellbook gives every partner feed a living page with SLA and schema history.
What disappears
The clearest sign the practices are working is what stops happening:
- •Double-counted paid amounts from resent files.
- •Two-week code-set projects.
- •Silent partner-feed failures.
- •Linkage drops found in analyses.
- •Manual de-identification.
- •Ticket queues for analyst access.
The magic is not any single agent. It is that the back office simply keeps running. Bad data is caught where it enters, not where it is read. Every new table gets quality rules and documentation without anyone writing them. Access follows policy instead of a queue. Fixes are rerun, verified and explained before anyone opens a dashboard. Cost is cleaned up every week instead of every budget cycle. And every one of those actions leaves a signed receipt, so the team can see exactly what happened and roll anything back. For the people on the team, the experience is quieter mornings, fewer tickets and more time for the products the business asked for.
A product manager's scorecard
If you own this data as a product, these are the numbers to bring to every quarterly review:
- •Payment-affecting incidents per quarter
- •Days per code-set update
- •Partner feeds meeting SLA
- •Member linkage rate
- •Days to onboard a provider group
- •Share of upkeep autonomous
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For claims and payer data teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; anything feeding risk adjustment or payment always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: every partner file is fingerprinted on arrival, so resends and duplicates are caught before loading twice, partner feeds are tracked against SLAs, and code-set updates run as missions with impact analysis. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. Payment-affecting numbers that are right before actuaries and risk adjustment use them. People set direction, and the platform carries it out.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how claims and payer data teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. 837/835/834 files and APIs; clearinghouse feeds; Snowflake or Databricks; dbt; risk adjustment and quality tools, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Resend detection and tie-outs at L2.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Every partner file is fingerprinted on arrival, so resends and duplicates are caught before loading twice and partner feeds are tracked against SLAs start running on reversible work. Anything feeding risk adjustment or payment stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •Analyst access granted: from about a week to 5 min
- •Finding the right file: from about 4 hours to 30 s
- •Linkage-rate drop traced: from about 3 days to 15-20 min
- •the share of partner feed verification closed autonomously, targeting 80% as the deployment matures
- •What you decide. Whether to expand to the next domain. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
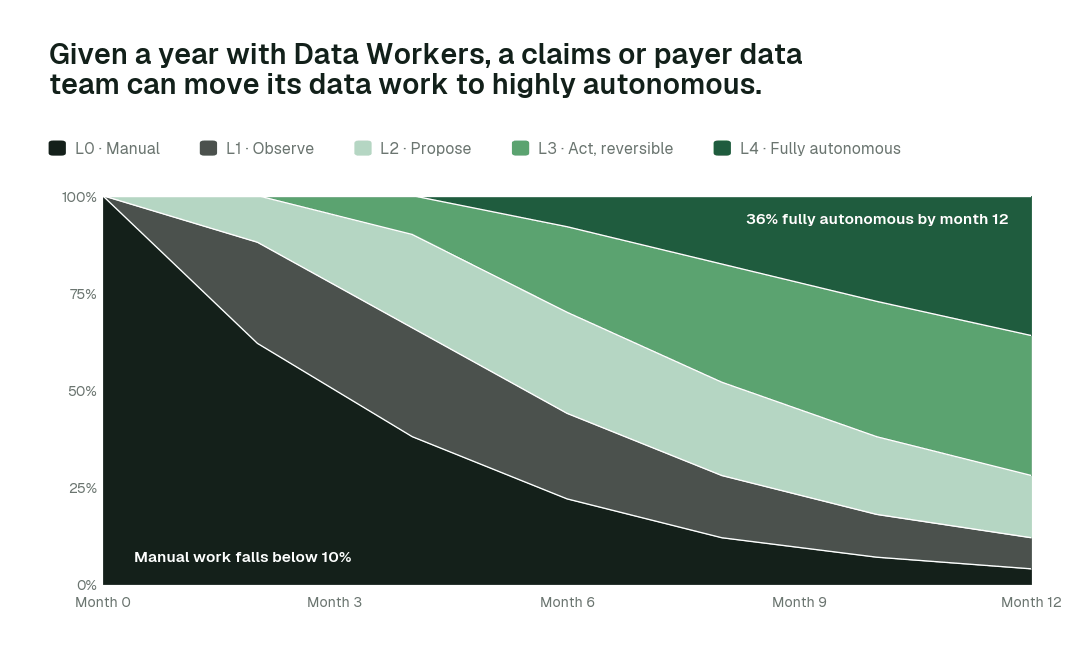
By month 12, more than 36% of agent actions run fully autonomously and manual work falls below 10%, while payment-affecting changes stay with a named approver.
Read the full playbook: Payer, clearinghouse and claims data teams