Stars and quality data, run by agents
HEDIS and Stars measures depend on claims, lab, pharmacy and supplemental data from dozens of sources, and gaps are found weeks before submission. Here is how Data Workers runs it instead.
Key takeaways
- •The problem today. HEDIS and Stars measures depend on claims, lab, pharmacy and supplemental data from dozens of sources, and gaps are found weeks before submission.
- •What changes. Agents keep every measure input fresh and complete, flag gaps as they appear and document lineage for each measure.
- •What stays with your people. Submitted measure rates: they carry regulatory accountability.
- •The result. Gaps are closed months before submission, with lineage ready for audit.
The problem today
HEDIS and Stars measures depend on claims, lab, pharmacy and supplemental data from dozens of sources, and gaps are found weeks before submission.
What changes with Data Workers
Agents keep every measure input fresh and complete, flag gaps as they appear and document lineage for each measure.
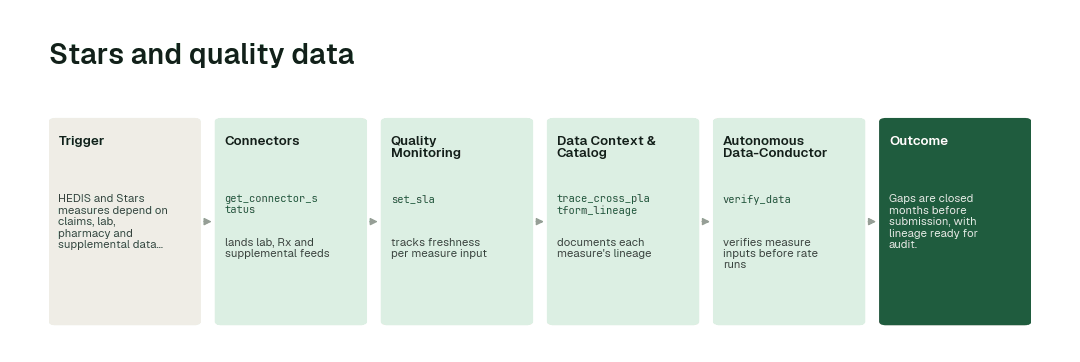
The workflow, step by step
- 1.The Connectors agent calls
get_connector_statusand lands lab, Rx and supplemental feeds. - 2.The Quality Monitoring agent calls
set_slaand tracks freshness per measure input. - 3.The Data Context & Catalog agent calls
trace_cross_platform_lineageand documents each measure's lineage. - 4.The Autonomous Data-Conductor calls
verify_dataand verifies measure inputs before rate runs.
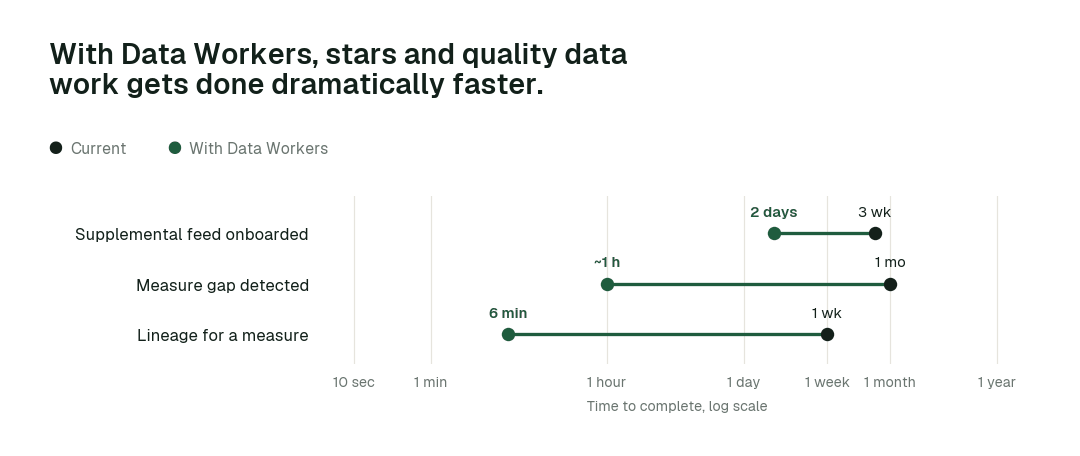
The impact metrics we move
- •Supplemental feed onboarded: from about 3 weeks to 2 days
- •Measure gap detected: from about a month to ~1 h
- •Lineage for a measure: from about a week to minutes
What goes on autopilot
- •Freshness and completeness are tracked per measure input, so gaps surface while there is still time to close them.
- •Lineage is documented for every measure, so audit evidence is ready.
Where your people stay in charge
Submitted measure rates always go to a named approver, because they carry regulatory accountability. Everything starts at L1, observing only, and autonomy rises only on evidence.
The pilot
- •Scope. Freshness and completeness on the top ten measures.
- •First week. Agents run at L1, observing only, and show the fixes they would have made, with receipts.
- •By week two. The routine work above runs on its own; anything sensitive stays with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •Supplemental feed onboarded: from about 3 weeks to 2 days
- •Measure gap detected: from about a month to ~1 h
- •Lineage for a measure: from about a week to minutes
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.