Retail data teams: onboard brands in a day, not a ticket queue
Onboard brands in a day, not a ticket queue. Most of the week on retail media data teams goes to upkeep: broken feeds, reruns, access queues and documentation. Data Workers hands that work to agents so the team ships the data products the business has been asking for.
Key takeaways
- •Who this is for. The teams that turn a retailer's transactions into products: retail data science subsidiaries, retail media networks, supplier insights platforms and commercial data units.
- •The problem today. Two-day investigations into supplier share drops, a ticket per brand onboarding and manual privacy-threshold reviews.
- •What changes. Store sales are tied to finance every night before the supplier portal refreshes, so brands never see a data error before you do. Aggregation thresholds are enforced inside the pipeline, so nothing below the privacy minimum can be published.
- •What stays with your people. Supplier-facing numbers and new supplier access: these are commercial commitments, so the insights lead approves.
- •The result. A retail data business that onboards brands as fast as sales signs them and never shows a supplier a false dip.
The PRD for agentic retail media and transaction data teams
This is the requirements document we would write with you for your team. Everything below expands on it.
| Who | Retail data science units, retail media networks and supplier data products teams |
| The job | Every supplier number tied out before it publishes. |
| Environment | POS and e-commerce platforms; loyalty; Snowflake, BigQuery or Databricks; dbt; clean rooms; supplier portals. |
| Constraints | Supplier-facing numbers and new supplier access always go to a named approver. Retail data products carry consent and privacy obligations (CCPA, GDPR) and aggregation thresholds. |
| Success is measured by | Supplier question answered: from about 2 days to seconds; Tender-code change caught: from about 2 days to 15-30 min; Hierarchy reorg absorbed: from about a month to hours; catalog upkeep closed autonomously 88% of the time. |
| Owned by | A Head of Retail Data Products, with domain owners as named approvers. |
| Pilot scope | Nightly tie-out and supplier onboarding at L2. |
What going fully agentic and autonomous means for retail media and transaction data teams
- •Put your data pipeline on autopilot. Store sales are tied to finance every night before the supplier portal refreshes, so brands never see a data error before you do.
- •Run the data back office without the busywork. The work that fills the week today moves to agents: two-day investigations into supplier share drops, a ticket per brand onboarding and manual privacy-threshold reviews.
- •Scale data without scaling headcount. Aggregation thresholds are enforced inside the pipeline and brand onboarding runs as a batch mission with access, templates and documentation, so the data you manage grows without the team having to.
- •Get the plumbing off your plate. A retail data business that onboards brands as fast as sales signs them and never shows a supplier a false dip.
Who this is for
The teams that turn a retailer's transactions into products: retail data science subsidiaries, retail media networks, supplier insights platforms and commercial data units. They often run with their own P&L and sell to CPG brands, agencies and suppliers. Titles include Data Product Manager, Retail Media PM, Insights Product Lead and Head of Data Commercialization.
The product you ship
- •Insights products suppliers log into: sales, share, basket, loyalty and path-to-purchase views.
- •Audiences built on verified purchase behavior, activated on and off your properties.
- •Closed-loop measurement that connects media exposure to store and online sales.
- •Clean-room collaborations with brands that never move raw shopper data.
Where the week goes
- •POS and e-commerce feeds drift. A store system upgrade or a new fulfillment channel changes a field and sales numbers shift.
- •Item and store hierarchies change constantly. Every reorg, resize and new private-label line breaks a rollup.
- •Supplier-facing numbers have to tie. If the insights portal and the retail media report disagree, the brand notices first.
- •Privacy thresholds are non-negotiable. Every audience and report has to respect aggregation and consent rules.
- •Supplier onboarding is manual. Each new brand needs access, scoping and its own clean-room template.
Add it up and upkeep is most of the team's week. Here is how a typical week splits today, and once agents own the back office:
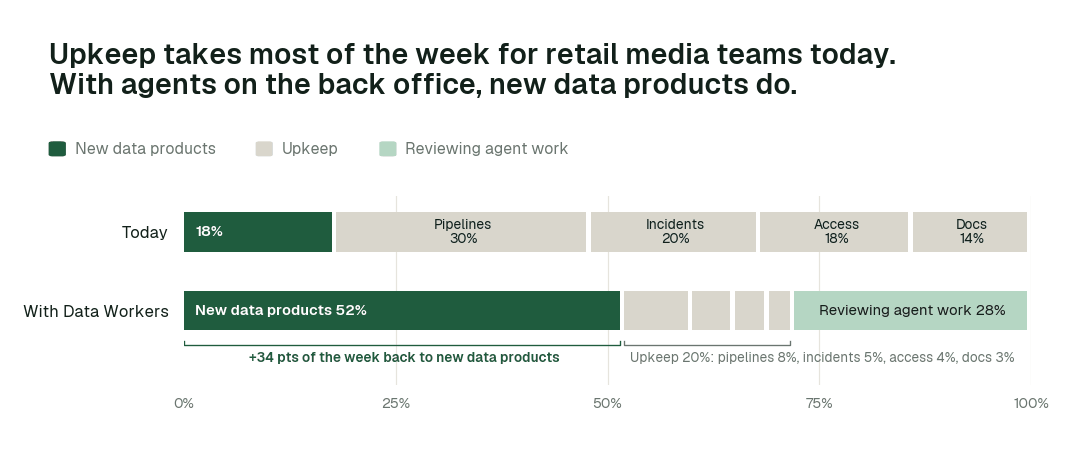
Time spent on new data products moves from 18% of the week to 52%. Most of the rest becomes review: people steer and approve agent work instead of doing it by hand.
Then and now
| Work | Today | With Data Workers |
|---|---|---|
| POS or e-commerce changes | Found when supplier numbers move | Caught on arrival and tied to finance before publishing |
| Hierarchy reorgs | Weeks of broken rollups | Versioned hierarchies, prior periods restated |
| Supplier onboarding | A ticket per brand | A mission per batch of brands |
| Supplier-facing tie-outs | When a brand complains | Every night, held if they do not tie |
| Aggregation thresholds | Checked in reviews | Enforced in the pipeline |
| New insights modules | Two quarters | About six weeks |
These are the impact metrics we move for retail media and transaction data teams:
- •Supplier question answered: from about 2 days to seconds
- •Tender-code change caught: from about 2 days to 15-30 min
- •Hierarchy reorg absorbed: from about a month to hours
Across the routine work in this domain:
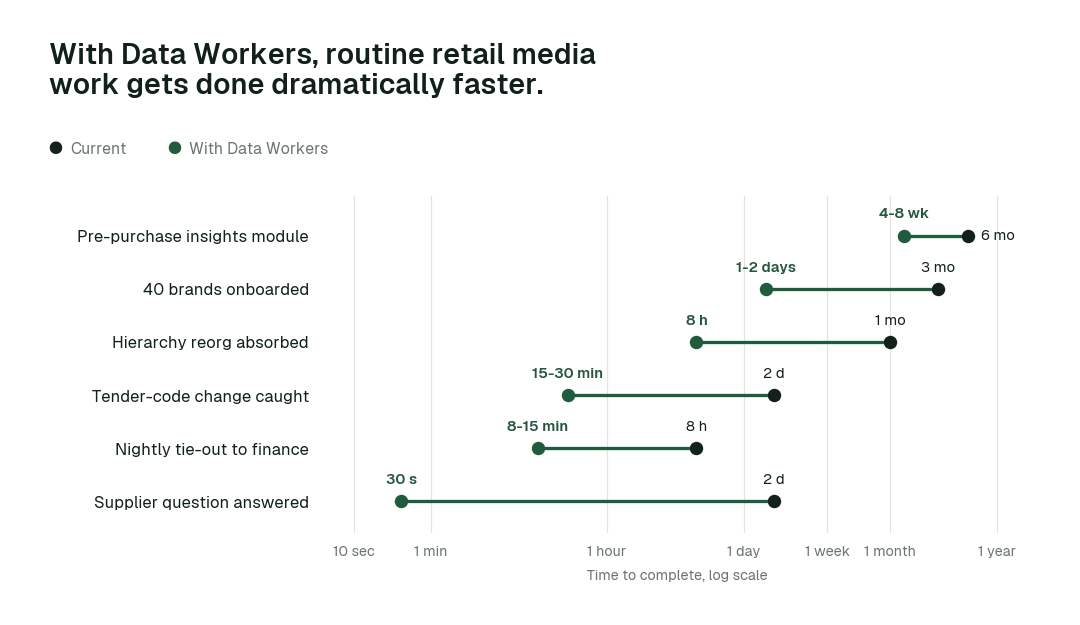
The biggest change is Tender-code change caught: from about 2 days to 15-30 min. Work that waited in queues finishes in minutes or hours, because agents detect, fix and verify in one pass.
Use cases, in depth
The tender code that looked like a share drop
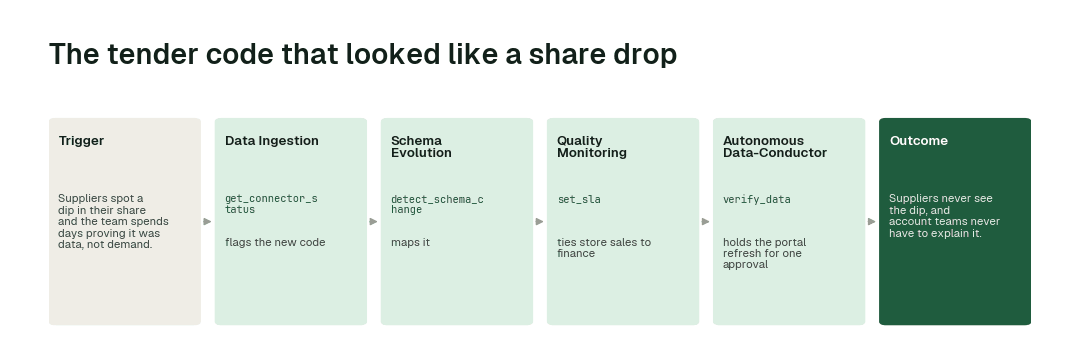
Today. Suppliers spot a dip in their share and the team spends days proving it was data, not demand.
With Data Workers. Ingestion flags the new code, Schema Evolution maps it, Quality Monitoring ties store sales to finance and Conductor holds the portal refresh for one approval.
What changes. Suppliers never see the dip, and account teams never have to explain it.
Onboarding 40 brands in a quarter
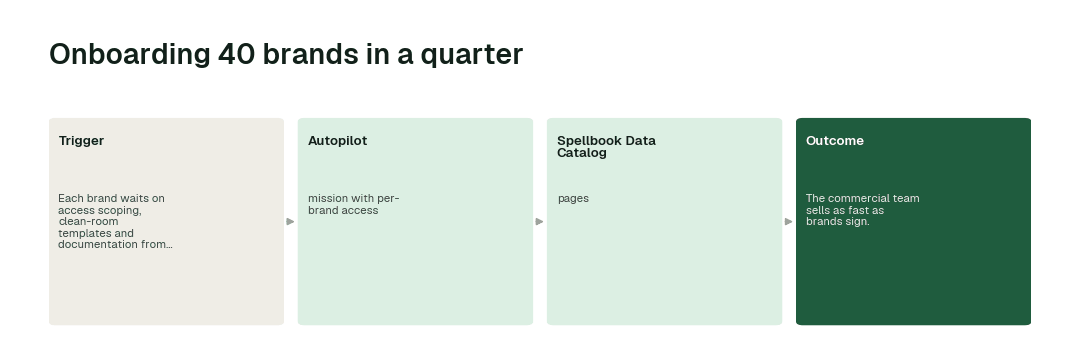
Today. Each brand waits on access scoping, clean-room templates and documentation from the data team.
With Data Workers. Supplier onboarding runs as one Autopilot mission with per-brand access, templates and Spellbook pages, reviewed in batches.
What changes. The commercial team sells as fast as brands sign.
Pre-purchase browse data as a product
Today. A new module takes two quarters to source, model, aggregate and document.
With Data Workers. Agents land the browse events, model the paths, enforce privacy thresholds, write tests and document the module; people decide what it shows and how it is priced.
What changes. New revenue lines reach suppliers in weeks.
Agents working together: The tender code that looked like a share drop
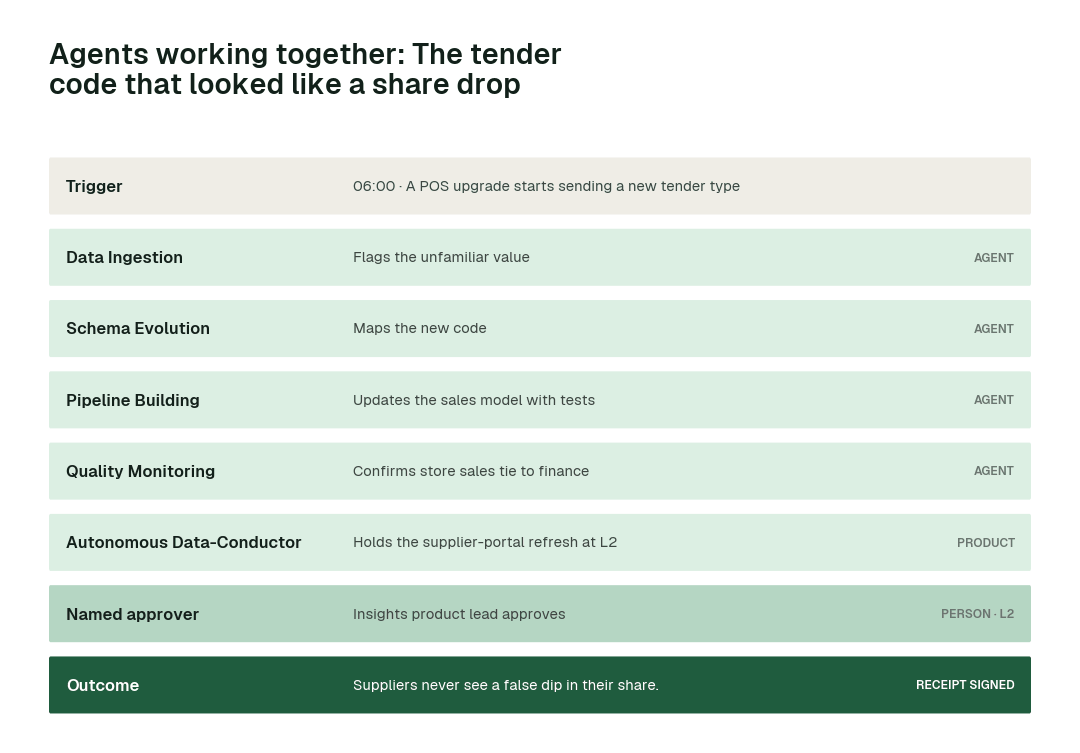
A store system upgrade starts sending a new tender-type code. Ingestion flags the unfamiliar value, Schema Evolution maps it, Pipeline Building updates the sales model, Quality Monitoring confirms the store's sales now tie to finance, and Conductor holds the supplier-portal refresh for one approval. Suppliers never see the dip.
Minute by minute
Illustrative example. POS loads land nightly in BigQuery; the supplier portal refreshes at 06:00. Supplier-facing numbers are at L2.
| Time | Who | What happens |
|---|---|---|
| 02:10 | POS | 300 stores send a new tender code |
| 02:12 | Schema Evolution agent | Unfamiliar value flagged; detect_schema_change |
| 02:30 | Pipeline Building agent | Sales model diff with tests |
| 02:41 | Quality Monitoring agent | run_quality_check: store sales tie to finance |
| 05:20 | Spellbook Data Catalog | Insights lead approves the refresh |
| 06:00 | Supplier portal | Brands see correct sales |
The agents on the job
| Agent | What it does for retail data teams | Tools it calls |
|---|---|---|
| Data Ingestion and Connectors | Land POS, e-commerce, loyalty, inventory and media data on schedule and profile every load | get_connector_status, trigger_airflow_dag, register_kafka_schema |
| Schema Evolution | Maps store-system and item-hierarchy changes into downstream models | detect_schema_change, validate_schema_compatibility, generate_migration, rollback_migration |
| Pipeline Building | Builds new supplier views, audiences and measurement models with tests | generate_pipeline, validate_pipeline, sandbox_test, deploy_pipeline |
| Quality Monitoring | Ties sales across the insights portal, retail media reports and finance | set_sla, run_quality_check, get_anomalies, create_quality_tests_for_pipeline |
| Data Access & Governance | Onboards suppliers with scoped access and clean-room templates under your policies | provision_access, check_policy, request_governance_review, generate_audit_report |
| Data Security | Keeps shopper PII classified and enforces aggregation thresholds | scan_pii, review_pii_writes, pci_card_data_masking |
| Cost Savings & Data Cleanup | Keeps petabyte-scale transaction tables affordable | get_snowflake_usage, get_cost_enrichment, detect_dead_assets |
Context Wizard holds governed definitions of a household, a sale, an incremental sale and a lift. Conductor verifies supplier-facing numbers before they publish. Spellbook gives every product and dataset a living page.
What goes on autopilot
Once a domain has earned it, this work runs on its own, and each item removes a problem your team deals with today:
- •Store sales are tied to finance every night before the supplier portal refreshes, so brands never see a data error before you do.
- •Aggregation thresholds are enforced inside the pipeline, so nothing below the privacy minimum can be published.
- •Brand onboarding runs as a batch mission with access, templates and documentation, so account teams stop waiting on data.
Where your people stay in charge
Agents never get blanket access. Each domain has its own autonomy level, set by you, and it only rises when the receipts show the agents are reliable. Everything starts at L1, observing only; reversible upkeep such as reruns, staging fixes, documentation and cleanup is usually first to run on its own.
- •Supplier-facing numbers and new supplier access always goes to a named approver: these are commercial commitments, so the insights lead approves.
- •Pricing and commercial terms with brands: these stay with people.
Once a deployment has matured, here is how that ladder plays out across task classes:
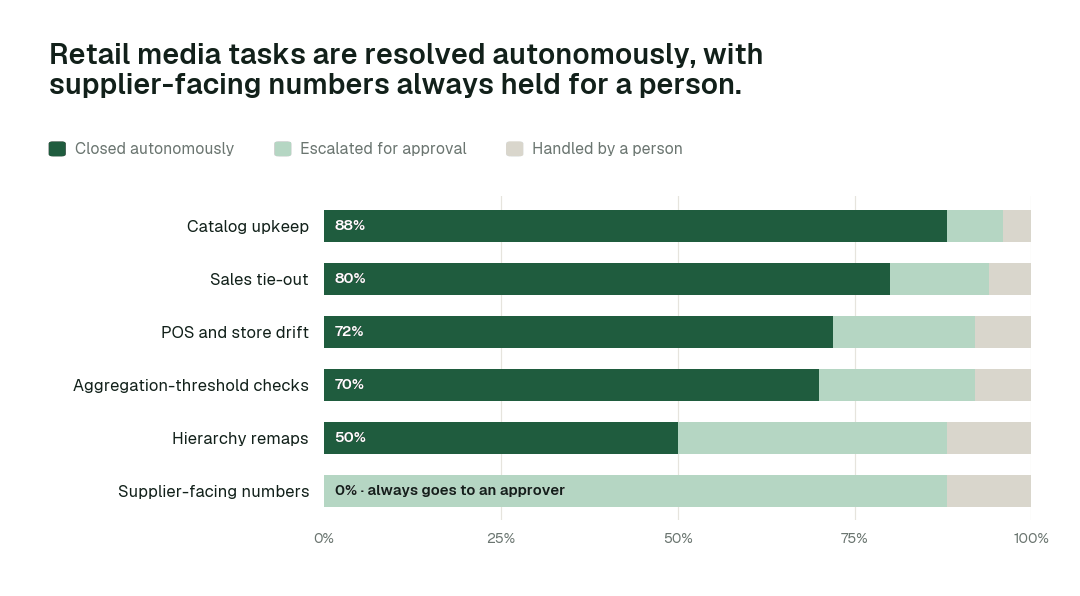
Catalog upkeep closes autonomously 88% of the time. For Supplier-facing numbers, autonomous closure is 0% by design: every change is proposed with a full diff and approved by a named person.
What happens when an agent is wrong
- •At L2 propose, nothing changes until a named person approves. The proposal shows the full diff, the blast radius and how to roll it back. Unanswered requests expire and escalate.
- •At L3 act, reversibly, every change keeps a rollback point, and Conductor verifies the downstream number after the change. If verification fails, the change is reversed and the domain drops a level.
- •No agent approves or promotes its own work. Autonomy only grows on evidence, per repair class, and repeated errors shrink scope automatically.
- •One org-wide stop halts all autonomous dispatch, and every action lands in a hash-chained audit trail you can export with generate_audit_report.
How it fits your stack
Data Workers connects to what you already run: POS and e-commerce platforms; loyalty; Snowflake, BigQuery or Databricks; dbt; clean rooms; supplier portals. Each agent is an MCP server, so the same agents work inside Claude Code, Cursor or Codex and in Slack or Teams through Spellbook. Nothing migrates.
- •Runs in your infrastructure with your credentials and your model key. The hosted Autonomous Data-Conductor sees workflow metadata only, never rows.
- •Uses the access you already govern. Agents act under scoped service identities and your existing roles; every grant goes through provision_access and is logged.
- •Proposes changes as diffs in your dbt project, orchestrator and warehouse, with blast radius, tests and a rollback point, and applies them only at the autonomy level you set for that domain.
- •Open-source core. The Apache-2.0 community edition ships 11 agents and 160+ MCP tools, so your engineers can read exactly what the agents call.
Governance and regulation
Retail data products carry consent and privacy obligations (CCPA, GDPR) and aggregation thresholds. Data Workers enforces thresholds as blocking checks, keeps suppression tables fresh and logs every access.
Data Workers doesn't make you compliant; your controls, people and assessors do. It supplies controls and evidence wherever agents touch data. Not legal advice.
The alternatives retail media and transaction data teams weigh
Build it yourselves. A strong team can wire a coding agent to MCP servers for the warehouse and dbt. The work is everything around it: routing approvals to the right owner, blast radius, rollback, receipts, and current context about every other system.
Observability, catalogs and point tools. Observability alerts, catalogs document, and quality tools test. Data Workers takes their signals, diagnoses, proposes the fix, verifies it and leaves the receipt.
Platform-native agents. Snowflake made its managed MCP server and Cortex Agents generally available on Nov 4, 2025, and Databricks made Genie One generally available on Jun 16, 2026. They are excellent inside their platform; this work crosses the source systems, orchestrator, warehouse and BI, and Data Workers works across all of them.
In this space specifically. Retail media platforms and clean rooms activate; Data Workers keeps the transaction data under them tied out and private.
The case for your CTO
What this replaces. Two-day investigations into supplier share drops, a ticket per brand onboarding and manual privacy-threshold reviews.
What your team gets back. A retail data business that onboards brands as fast as sales signs them and never shows a supplier a false dip.
Integration effort. Connecting is configuration, not a migration. The agents attach over MCP to the warehouse, orchestrator, dbt project and source systems you already run, under the roles you already govern, inside your own infrastructure. Your engineers can read every tool the agents call in the open-source core.
Risk and control. Autonomy is set per domain. Everything starts at L1, observing only; reversible work moves up only when the receipts justify it; supplier-facing numbers and new supplier access stay at L2 with a named approver; and one org-wide stop halts all autonomous work.
Why now. Retail media is a growth line and suppliers pay for accuracy.
The first win. Nightly tie-out and supplier onboarding at L2. The pilot below lays out the scope, what you see each week and the cost.
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For retail media and transaction data teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; supplier-facing numbers and new supplier access always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: store sales are tied to finance every night before the supplier portal refreshes, aggregation thresholds are enforced inside the pipeline, and brand onboarding runs as a batch mission with access, templates and documentation. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. A retail data business that onboards brands as fast as sales signs them and never shows a supplier a false dip. People set direction, and the platform carries it out.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how retail media and transaction data teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. POS and e-commerce platforms; loyalty; Snowflake, BigQuery or Databricks; dbt; clean rooms; supplier portals, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Nightly tie-out and supplier onboarding at L2.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Store sales are tied to finance every night before the supplier portal refreshes and aggregation thresholds are enforced inside the pipeline start running on reversible work. Supplier-facing numbers and new supplier access stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •Supplier question answered: from about 2 days to seconds
- •Tender-code change caught: from about 2 days to 15-30 min
- •Hierarchy reorg absorbed: from about a month to hours
- •the share of catalog upkeep closed autonomously, targeting 88% as the deployment matures
- •What you decide. Whether to expand to the next domain. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
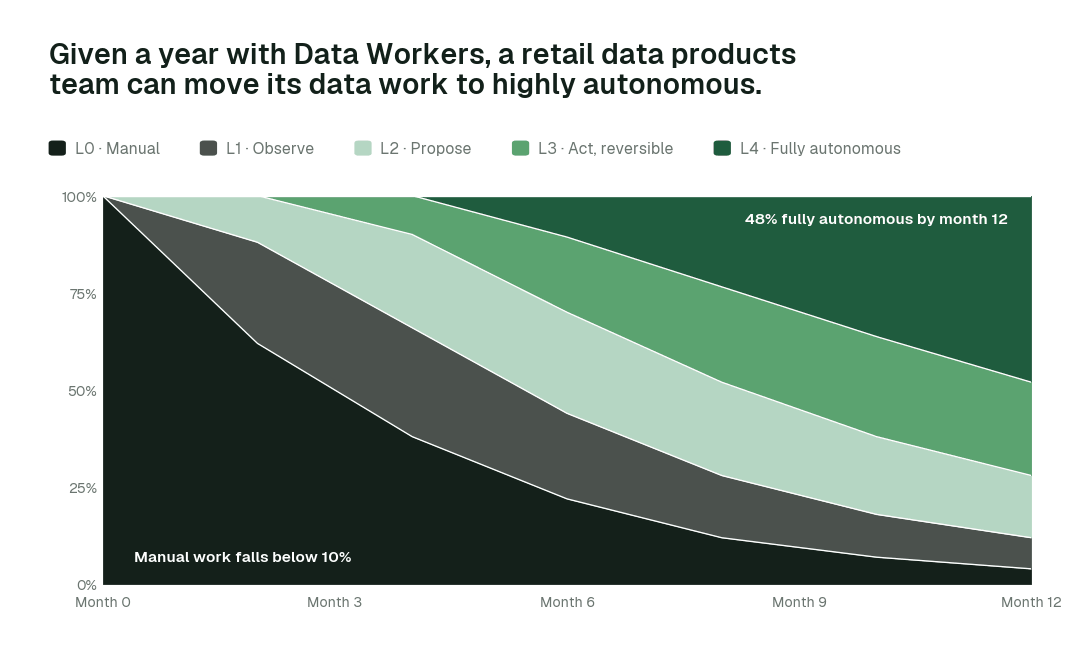
By month 12, more than 48% of agent actions run fully autonomously and manual work falls below 10%, while supplier-facing numbers stay with a named approver.
FAQ
Does it work with our clean room? Yes, for access, templates and PII rules.
Can it enforce aggregation thresholds? Yes, as blocking checks.
Will agents change supplier numbers? Supplier-facing numbers are L2.
Where do the agents run? In your infrastructure, with your credentials and model key. The hosted Conductor sees workflow metadata only.
Do we have to migrate anything? No. Your warehouse, dbt project, orchestrator, catalog and BI stay where they are.
Sources
- •Grocery Dive, Kroger unifies retail media, insights and loyalty: https://www.grocerydive.com/news/kroger-unifies-retail-media-consumer-insights-loyalty-marketing/756207/
- •Walmart Luminate data roles (Indeed): https://www.indeed.com/q-walmart-luminate-data-analyst-jobs.html
- •Data Workers pricing: https://dataworkers.io/pricing/
- •Data Workers open-source repository (tool registrations): https://github.com/DataWorkersProject/dataworkers-claw-community
- •Snowflake, managed MCP server and Cortex Agents GA release note (Nov 4, 2025): https://docs.snowflake.com/en/release-notes/2025/other/2025-11-04-cortex-agents-mcp
- •Databricks, Genie One launch (Jun 16, 2026): https://www.databricks.com/company/newsroom/press-releases/databricks-launches-genie-one-all-new-agentic-coworker-every-team