Agentic revenue cycle data: a guide for revenue cycle analytics teams
This guide explains how revenue cycle analytics teams adopt agents for their data back office. It covers the shift underway, the use cases that matter most, charts of the impact, how the agents work together, and a month-by-month path to autonomy.
Key takeaways
- •Who this is for. The team that turns hospital and professional billing data into revenue performance: charge capture, coding, claims, denials, AR and cash.
- •The problem today. Month-end reconciliation of Clarity extracts, conflicting KPI definitions and denial spikes found a month late.
- •What changes. Charges, claims and remits are tied every day, so leakage is visible within a day. Denials are monitored by payer and reason, so spikes are traced the week they appear.
- •What stays with your people. Write-offs and financial reporting inputs: they hit the P&L, so finance approves.
- •The result. A revenue cycle team that finds leakage weekly and spends its time recovering revenue.
The PRD for agentic revenue cycle analytics teams
This is the requirements document we would write with you for your team. Everything below expands on it.
| Who | Revenue cycle analytics, patient financial services and revenue integrity teams at health systems and RCM companies |
| The job | Charges, claims, denials and cash tied out every day. |
| Environment | Epic Clarity and Caboodle, Resolute HB and PB; clearinghouses; contract management; Snowflake or Databricks; dbt; BI. |
| Constraints | Write-offs and financial reporting inputs always go to a named approver. Billing data is PHI and feeds financial reporting. |
| Success is measured by | KPI question: from about a day to seconds; Charge-to-remit tie-out: from about a week to 15-20 min; Denial spike traced: from about 2 weeks to ~1 h; catalog upkeep closed autonomously 88% of the time. |
| Owned by | A Director of Revenue Cycle Analytics, with domain owners as named approvers. |
| Pilot scope | Daily charge-to-remit tie-out for one hospital. |
What going fully agentic and autonomous means for revenue cycle analytics teams
- •Put your data pipeline on autopilot. Charges, claims and remits are tied every day, so leakage is visible within a day.
- •Run the data back office without the busywork. The work that fills the week today moves to agents: month-end reconciliation of Clarity extracts, conflicting KPI definitions and denial spikes found a month late.
- •Scale data without scaling headcount. Denials are monitored by payer and reason and epic upgrades are absorbed on load, so the data you manage grows without the team having to.
- •Get the plumbing off your plate. A revenue cycle team that finds leakage weekly and spends its time recovering revenue.
Who this is for
The team that turns hospital and professional billing data into revenue performance: charge capture, coding, claims, denials, AR and cash. It works from Epic Clarity and Resolute (hospital and professional billing), clearinghouses and contract management systems, and serves revenue cycle leadership, finance and revenue integrity.
The shift
Revenue cycle performance decides a health system's margin, and the data behind it is spread across billing modules, clearinghouses and payer remits. Analysts spend most of their time reconciling extracts and defining KPIs instead of finding leakage. Agents can tie the chain from charge to cash every day and trace every denial spike to its cause.
The product you ship
- •Charge-to-cash reconciliation
- •Denial analytics by payer, reason and service line
- •AR and cash forecasting data
- •Executive revenue cycle KPIs
Where the week goes
- •Clarity extracts change after Epic upgrades.
- •Denial categories differ between teams.
- •Remits and claims never quite tie.
- •KPI definitions are rebuilt for every report.
- •Payer behavior changes faster than reports.
Add it up and upkeep is most of the team's week. Here is how a typical week splits today, and once agents own the back office:
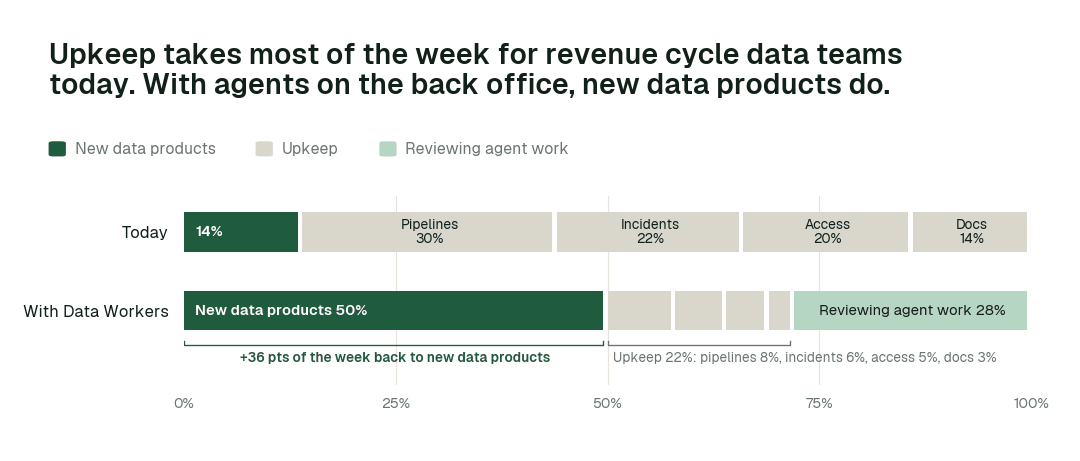
Time spent on new data products moves from 14% of the week to 50%. Most of the rest becomes review: people steer and approve agent work instead of doing it by hand.
Then and now
| Work | Today | With Data Workers |
|---|---|---|
| Charge-to-claim tie-out | Month-end | Daily |
| Denial spike | Found in monthly reports | Traced the week it appears |
| Epic upgrade impact | Broken reports | Mapped on load |
| KPI definitions | Rebuilt per report | Governed once |
| Payer remit changes | Missed | Detected |
These are the impact metrics we move for revenue cycle analytics teams:
- •KPI question: from about a day to seconds
- •Charge-to-remit tie-out: from about a week to 15-20 min
- •Denial spike traced: from about 2 weeks to ~1 h
Across the routine work in this domain:
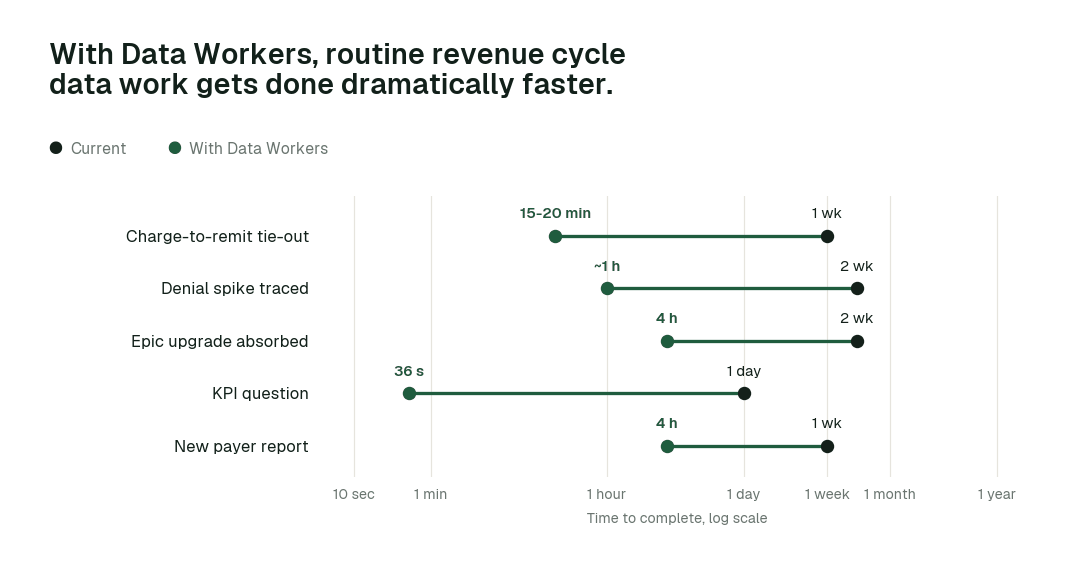
The biggest change is Charge-to-remit tie-out: from about a week to 15-20 min.
Use cases, in depth
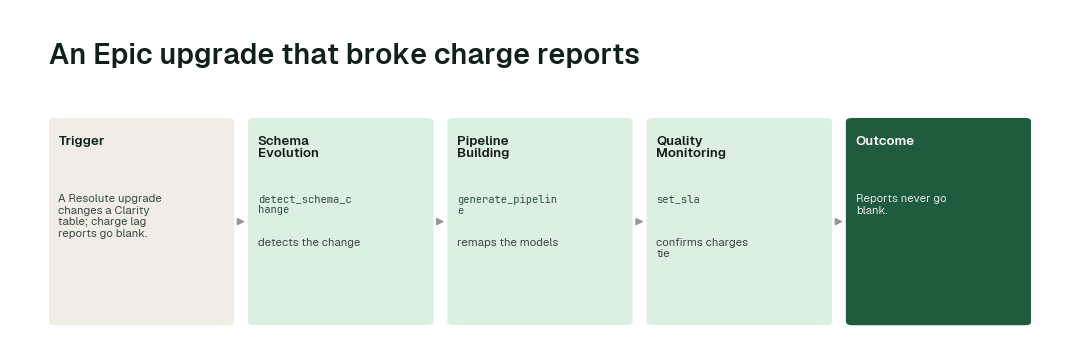
A denial spike from one payer
Today. Denials from one payer rise 40% for a service line; it surfaces in the monthly review.
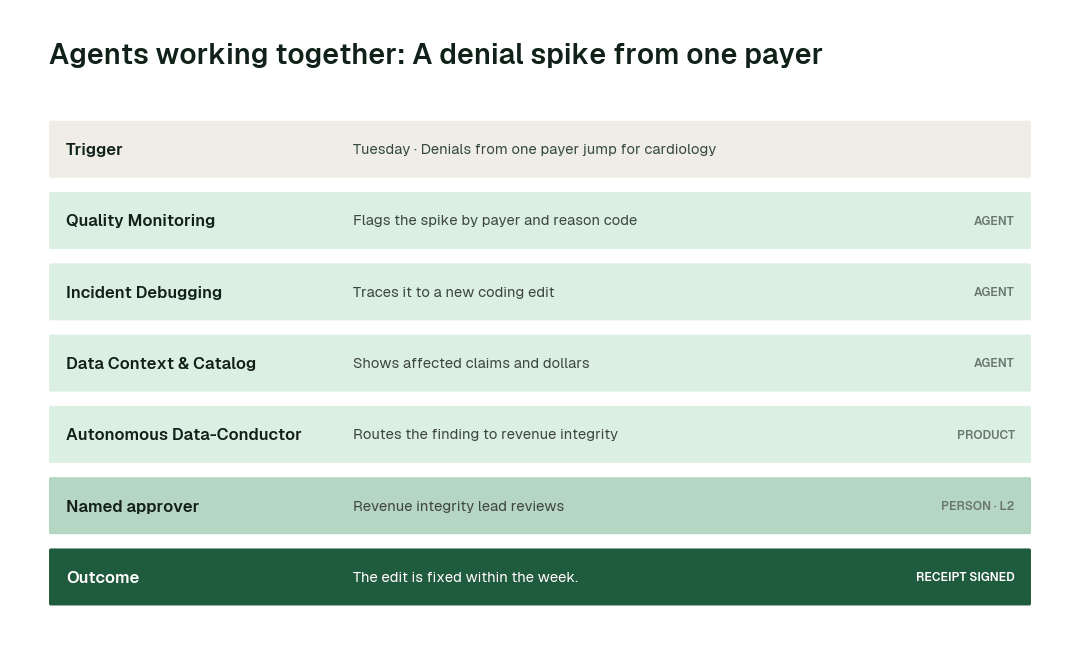
With Data Workers. Quality Monitoring flags the spike by payer and reason, Incident Debugging traces it to a coding edit, and Conductor routes it to revenue integrity.
What changes. The fix lands within the week.
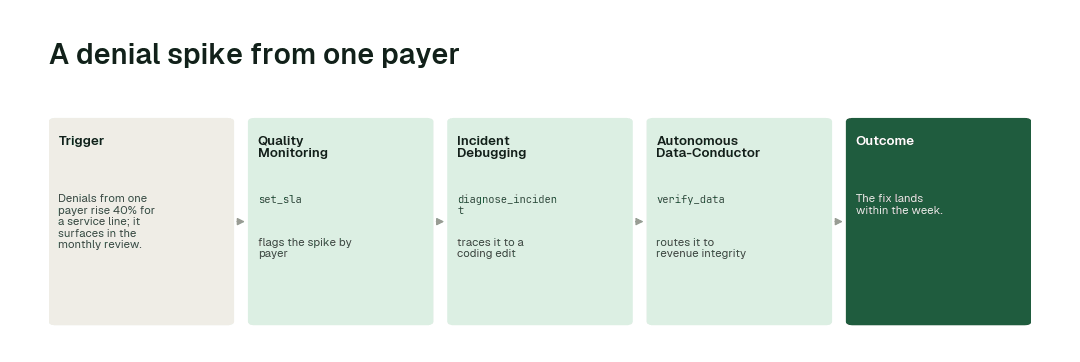
An Epic upgrade that broke charge reports
Today. A Resolute upgrade changes a Clarity table; charge lag reports go blank.
With Data Workers. Schema Evolution detects the change, Pipeline Building remaps the models, Quality Monitoring confirms charges tie.
What changes. Reports never go blank.
One definition of a clean claim
Today. Finance, PFS and leadership each compute clean claim rate differently.
With Data Workers. Context Wizard governs the KPI definitions with lineage.
What changes. One number in every meeting.
Agents working together: A denial spike from one payer
Minute by minute
Illustrative example. Clarity extracts and remits load nightly into Snowflake; denial dashboards refresh at 06:00.
| Time | Who | What happens |
|---|---|---|
| Tue 02:00 | Clearinghouse | Remits with new denial codes |
| 02:30 | Quality Monitoring agent | Denial spike flagged for one payer |
| 02:45 | Incident Debugging agent | Traced to a coding edit |
| 03:00 | Data Context & Catalog agent | $420k in affected claims quantified |
| 08:30 | Spellbook Data Catalog | Revenue integrity lead reviews |
The agents on the job
| Agent | What it does for you | Tools it calls |
|---|---|---|
| Connectors and Data Ingestion | Clarity, clearinghouse and remit data | get_connector_status, trigger_airflow_dag, get_dbt_run_history |
| Schema Evolution | Epic upgrade and Clarity changes | detect_schema_change, validate_schema_compatibility, generate_migration, rollback_migration |
| Quality Monitoring | Charge-to-claim-to-remit tie-outs and denial spikes | set_sla, run_quality_check, get_anomalies, create_quality_tests_for_pipeline |
| Incident Debugging | Traces denials and leakage to cause | diagnose_incident, get_root_cause, prepare_backfill, execute_backfill |
| Data Context & Catalog | Governed revenue cycle KPIs | trace_cross_platform_lineage, blast_radius_analysis, define_business_rule, generate_documentation |
| Data Security | PHI classification | scan_pii, review_pii_writes, pci_card_data_masking |
Data Context Wizard keeps one governed graph of definitions, lineage and owners that every agent and person answers from. Autonomous Data-Conductor runs each job from detection to a verified result. Spellbook Data Catalog is where your team approves, audits and rolls back, and asks questions in plain English.
What goes on autopilot
Once a domain has earned it, this work runs on its own, and each item removes a problem your team deals with today:
- •Charges, claims and remits are tied every day, so leakage is visible within a day.
- •Denials are monitored by payer and reason, so spikes are traced the week they appear.
- •Epic upgrades are absorbed on load, so reports never go blank.
Where your people stay in charge
Agents never get blanket access. Each domain has its own autonomy level, set by you, and it only rises when the receipts show the agents are reliable. Everything starts at L1, observing only; reversible upkeep such as reruns, staging fixes, documentation and cleanup is usually first to run on its own.
- •Write-offs and financial reporting inputs always goes to a named approver: they hit the P&L, so finance approves.
- •Payer and contract decisions: these stay with people.
Once a deployment has matured, here is how that ladder plays out across task classes:
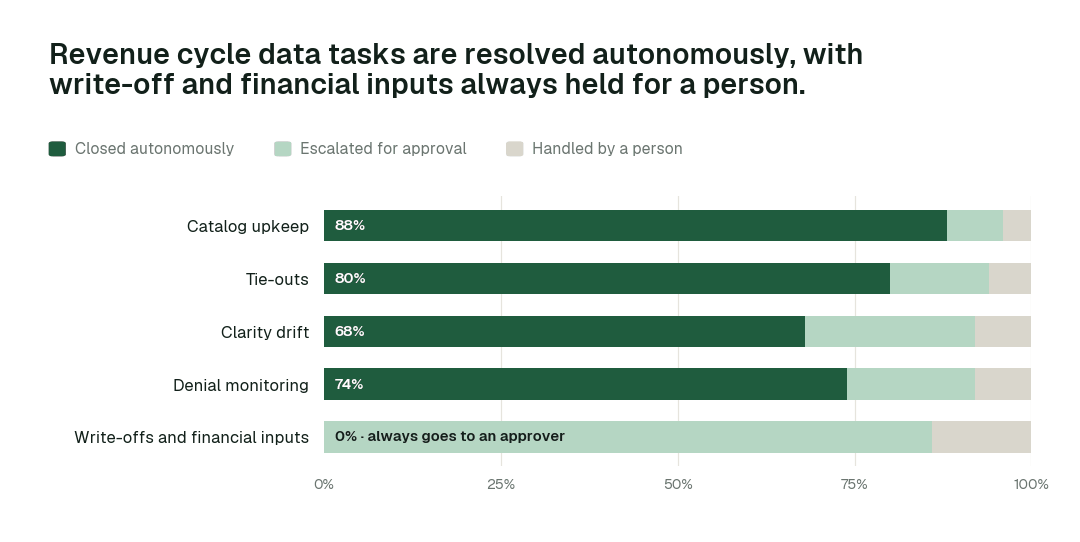
Catalog upkeep closes autonomously 88% of the time. For Write-offs and financial inputs, autonomous closure is 0% by design.
What happens when an agent is wrong
- •At L2 propose, nothing changes until a named person approves. The proposal shows the full diff, the blast radius and how to roll it back. Unanswered requests expire and escalate.
- •At L3 act, reversibly, every change keeps a rollback point, and Conductor verifies the downstream number after the change. If verification fails, the change is reversed and the domain drops a level.
- •No agent approves or promotes its own work. Autonomy only grows on evidence, per repair class, and repeated errors shrink scope automatically.
- •One org-wide stop halts all autonomous dispatch, and every action lands in a hash-chained audit trail you can export with generate_audit_report.
How it fits your stack
Data Workers connects to what you already run: Epic Clarity and Caboodle, Resolute HB and PB; clearinghouses; contract management; Snowflake or Databricks; dbt; BI. Each agent is an MCP server, so the same agents work inside Claude Code, Cursor or Codex and in Slack or Teams through Spellbook. Nothing migrates.
- •Runs in your infrastructure with your credentials and your model key. The hosted Autonomous Data-Conductor sees workflow metadata only, never rows.
- •Uses the access you already govern. Agents act under scoped service identities and your existing roles; every grant goes through provision_access and is logged.
- •Proposes changes as diffs in your dbt project, orchestrator and warehouse, with blast radius, tests and a rollback point, and applies them only at the autonomy level you set for that domain.
- •Open-source core. The Apache-2.0 community edition ships 11 agents and 160+ MCP tools, so your engineers can read exactly what the agents call.
Governance and regulation
Billing data is PHI and feeds financial reporting. Data Workers classifies PHI, holds financial reporting inputs for a named approver and logs every change.
Data Workers doesn't make you compliant; your controls, people and assessors do. It supplies controls and evidence wherever agents touch data. Not legal advice.
The alternatives revenue cycle analytics teams weigh
Build it yourselves. A strong team can wire a coding agent to MCP servers for the warehouse and dbt. The work is everything around it: routing approvals to the right owner, blast radius, rollback, receipts, and current context about every other system.
Observability, catalogs and point tools. Observability alerts, catalogs document, and quality tools test. Data Workers takes their signals, diagnoses, proposes the fix, verifies it and leaves the receipt.
Platform-native agents. Snowflake made its managed MCP server and Cortex Agents generally available on Nov 4, 2025, and Databricks made Genie One generally available on Jun 16, 2026. They are excellent inside their platform; this work crosses the source systems, orchestrator, warehouse and BI, and Data Workers works across all of them.
In this space specifically. RCM platforms run the workflow; Data Workers keeps the data behind revenue cycle analytics tied out and explained.
The case for your CTO
What this replaces. Month-end reconciliation of Clarity extracts, conflicting KPI definitions and denial spikes found a month late.
What your team gets back. A revenue cycle team that finds leakage weekly and spends its time recovering revenue.
Integration effort. Connecting is configuration, not a migration. The agents attach over MCP to the warehouse, orchestrator, dbt project and source systems you already run, under the roles you already govern, inside your own infrastructure. Your engineers can read every tool the agents call in the open-source core.
Risk and control. Autonomy is set per domain. Everything starts at L1, observing only; reversible work moves up only when the receipts justify it; write-offs and financial reporting inputs stay at L2 with a named approver; and one org-wide stop halts all autonomous work.
Why now. Margins depend on revenue cycle performance.
The first win. Daily charge-to-remit tie-out for one hospital. The pilot below lays out the scope, what you see each week and the cost.
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For revenue cycle analytics teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; write-offs and financial reporting inputs always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: charges, claims and remits are tied every day, denials are monitored by payer and reason, and epic upgrades are absorbed on load. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. Revenue cycle teams will run on a continuously reconciled charge-to-cash chain, with denial prevention driven by agents that spot payer behavior changes as remits land.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how revenue cycle analytics teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. Epic Clarity and Caboodle, Resolute HB and PB; clearinghouses; contract management; Snowflake or Databricks; dbt; BI, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Daily charge-to-remit tie-out for one hospital.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Charges, claims and remits are tied every day and denials are monitored by payer and reason start running on reversible work. Write-offs and financial reporting inputs stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- KPI question: from about a day to seconds
- Charge-to-remit tie-out: from about a week to 15-20 min
- Denial spike traced: from about 2 weeks to ~1 h
- the share of catalog upkeep closed autonomously, targeting 88% as the deployment matures
- •What you decide. Whether to expand to the next domain. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
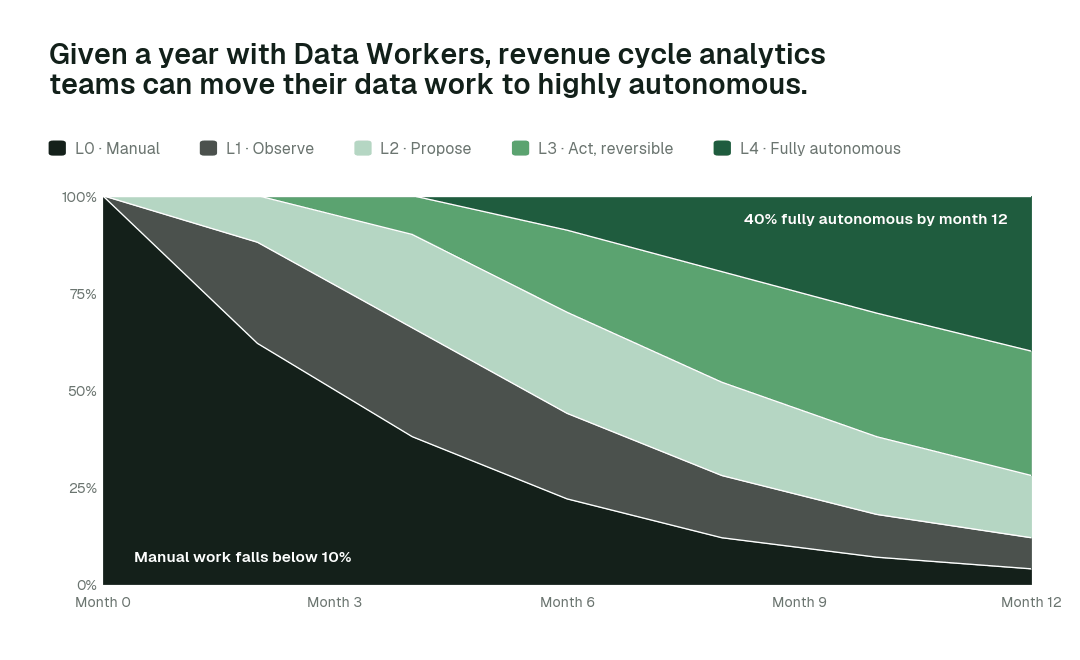
By month 12, more than 40% of agent actions run fully autonomously while write-off and financial inputs stay with a named approver.
FAQ
Does it work with Epic Clarity? Yes, from Clarity and Caboodle extracts.
Can it change billing data? Financial inputs are L2.
Does PHI stay in our environment? Yes.
Where do the agents run? In your infrastructure, with your credentials and model key. The hosted Conductor sees workflow metadata only.
Do we have to migrate anything? No. Your warehouse, dbt project, orchestrator, catalog and BI stay where they are.
Sources
- •Data Workers pricing: https://dataworkers.io/pricing/
- •Snowflake, managed MCP server and Cortex Agents GA release note (Nov 4, 2025): https://docs.snowflake.com/en/release-notes/2025/other/2025-11-04-cortex-agents-mcp
- •Databricks, Genie One launch (Jun 16, 2026): https://www.databricks.com/company/newsroom/press-releases/databricks-launches-genie-one-all-new-agentic-coworker-every-team