Machine data teams: stop fixing machine feeds, start building precision products
Stop fixing machine feeds, start building precision products. Most of the week on machine data teams goes to upkeep: broken feeds, reruns, access queues and documentation. Data Workers hands that work to agents so the team ships the data products the business has been asking for.
Key takeaways
- •Who this is for. Teams at equipment makers and industrial companies that turn machine telemetry and agronomic data into products: operations centers, partner APIs and analytics for farmers and fleet owners.
- •The problem today. Converter backlogs for every new model year, manual sharing permissions and partner apps that break on internal changes.
- •What changes. New model formats are mapped on first upload, so farmers see their maps on day one. Sharing permissions are enforced in the data, so every share is instant and auditable.
- •What stays with your people. Shared data and partner APIs: customers and partners depend on them, so the product data lead approves.
- •The result. Machine data services that work on day one of every model year.
The PRD for agentic machine data teams
This is the requirements document we would write with you for your team. Everything below expands on it.
| Who | Machine data, precision agriculture, connected equipment and industrial IoT data teams |
| The job | Machine and agronomic data ready for farmers and partners. |
| Environment | IoT ingestion; cloud lakes on AWS or Azure; Databricks or Snowflake; partner APIs; operations center applications. |
| Constraints | Shared data and partner APIs always go to a named approver. Customers own and control sharing of their data. |
| Success is measured by | Sharing permission applied: from about a week to 5 min; API change checked: from about 3 days to 15-20 min; New model format mapped: from about a month to hours; catalog upkeep closed autonomously 88% of the time. |
| Owned by | A Head of Machine Data Products, with domain owners as named approvers. |
| Pilot scope | Model-format mapping on one product line at L3. |
What going fully agentic and autonomous means for machine data teams
- •Put your data pipeline on autopilot. New model formats are mapped on first upload, so farmers see their maps on day one.
- •Run the data back office without the busywork. The work that fills the week today moves to agents: converter backlogs for every new model year, manual sharing permissions and partner apps that break on internal changes.
- •Scale data without scaling headcount. Sharing permissions are enforced in the data and partner API contracts are checked before release, so the data you manage grows without the team having to.
- •Get the plumbing off your plate. Machine data services that work on day one of every model year.
Who this is for
Teams at equipment makers and industrial companies that turn machine telemetry and agronomic data into products: operations centers, partner APIs and analytics for farmers and fleet owners. Titles include Product Manager (Data Platform), Connected Equipment Data Lead and Precision Ag Data Product Owner.
The shift
Equipment now ships with telemetry, and customers expect their data available in an operations center and shared with advisors and partner apps. Every model year and firmware adds formats, and data sharing needs permissions enforced in the data. Agents keep machine data flowing, mapped and permissioned.
The product you ship
- •Machine telemetry and health data
- •Agronomic data: yield, seeding, as-applied
- •Partner APIs and data sharing
- •Fleet and service analytics
Where the week goes
- •New model years bring new formats.
- •Data sharing permissions handled by hand.
- •Partner API consumers break on changes.
- •Field data arrives late from low-connectivity areas.
- •Service teams need machine health fast.
Add it up and upkeep is most of the team's week. Here is how a typical week splits today, and once agents own the back office:
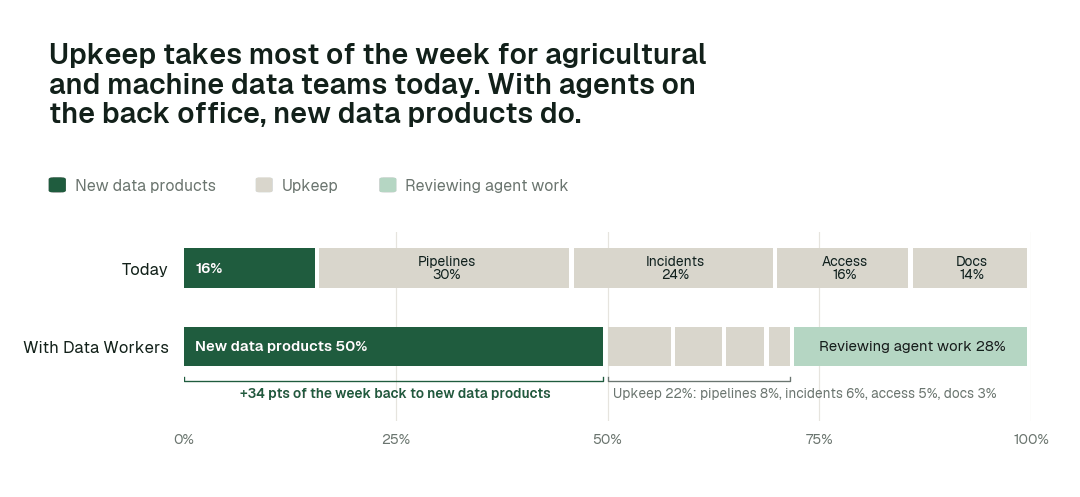
Time spent on new data products moves from 16% of the week to 50%. Most of the rest becomes review: people steer and approve agent work instead of doing it by hand.
Then and now
| Work | Today | With Data Workers |
|---|---|---|
| New model formats | Converters per model | Mapped to the standard |
| Sharing permissions | Manual | Enforced as policy |
| Partner APIs | Break on changes | Versioned contracts |
| Late field data | Gaps | Backfilled and verified |
| Machine health | Reports | Alerts and products |
These are the impact metrics we move for machine data teams:
- •Sharing permission applied: from about a week to 5 min
- •API change checked: from about 3 days to 15-20 min
- •New model format mapped: from about a month to hours
Across the routine work in this domain:
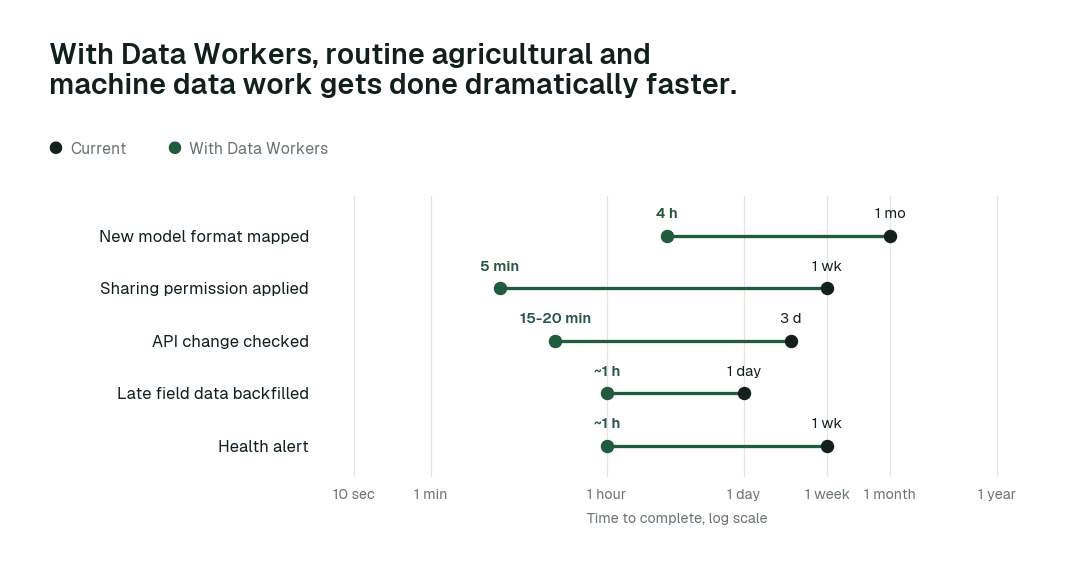
The biggest change is Sharing permission applied: from about a week to 5 min.
Use cases, in depth
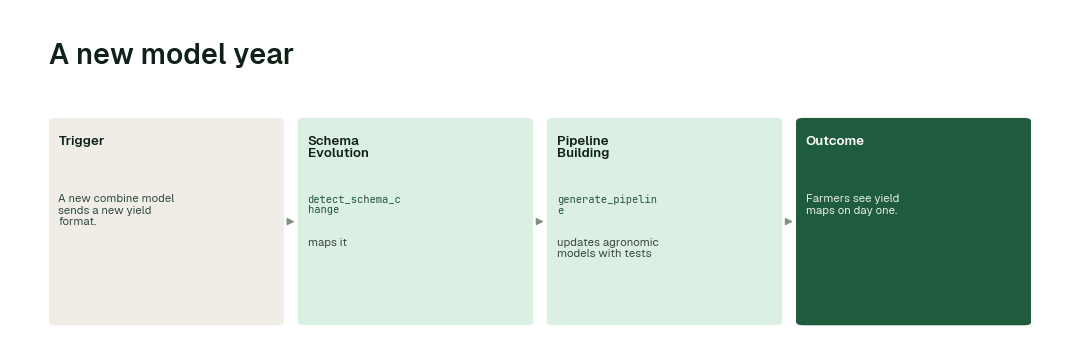
A new model year
Today. A new combine model sends a new yield format.
With Data Workers. Schema Evolution maps it; Pipeline Building updates agronomic models with tests.
What changes. Farmers see yield maps on day one.
Sharing with an advisor
Today. A farmer shares field data with an agronomist.
With Data Workers. Data Access & Governance enforces the permission scope and logs it.
What changes. Sharing is instant and auditable.
A partner API change
Today. An internal change breaks partner apps.
With Data Workers. Schema Evolution versions the contract and flags consumers before release.
What changes. Partners never break.
Agents working together: A new model year's yield data
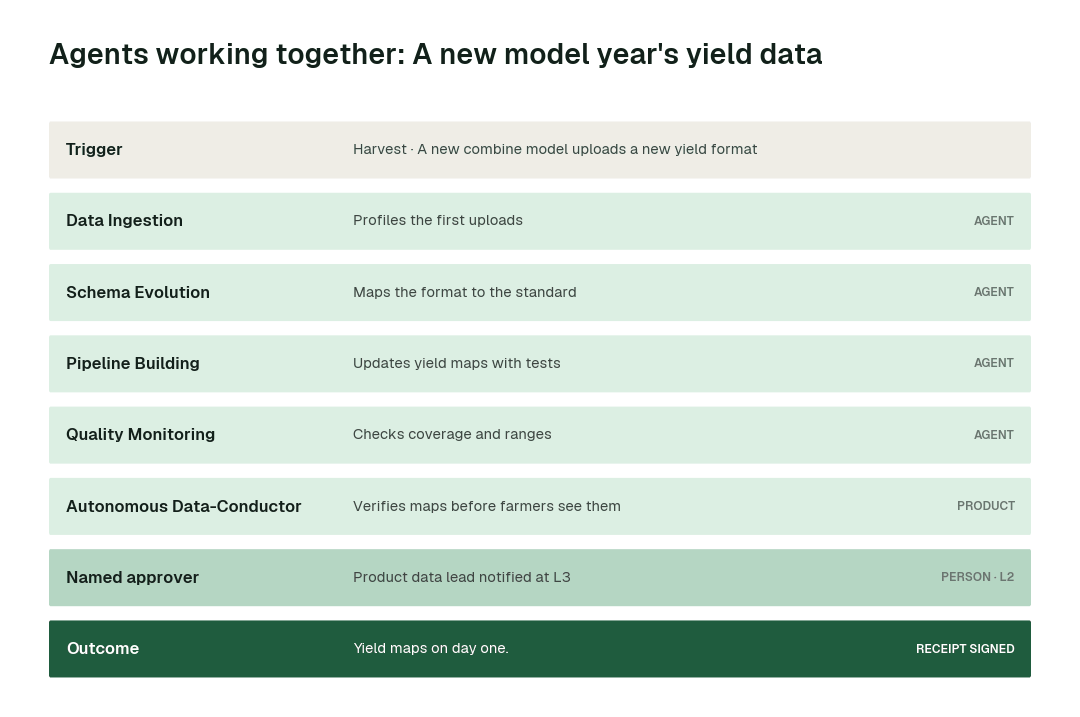
Minute by minute
Illustrative example. Machine uploads land in a cloud lake; yield maps publish to an operations center.
| Time | Who | What happens |
|---|---|---|
| 08:00 | Combine | First uploads in new format |
| 08:05 | Data Ingestion agent | Format profiled; deviations found |
| 08:30 | Autonomous Data-Conductor | Mapping and tests |
| 09:00 | Operations center | Yield maps published |
Without the agents, maps wait for a converter release.
The agents on the job
| Agent | What it does for you | Tools it calls |
|---|---|---|
| Data Ingestion | Telemetry and field uploads | get_connector_status, trigger_airflow_dag, register_kafka_schema |
| Schema Evolution | Model-year and firmware formats; API contracts | detect_schema_change, validate_schema_compatibility, generate_migration, rollback_migration |
| Quality Monitoring | Coverage and range checks | set_sla, run_quality_check, get_anomalies, create_quality_tests_for_pipeline |
| Pipeline Building | Agronomic and health products | generate_pipeline, validate_pipeline, sandbox_test, deploy_pipeline |
| Data Access & Governance | Farmer-controlled sharing permissions | provision_access, check_policy, request_governance_review, generate_audit_report |
| MLOps & Models | Predictive maintenance model drift | detect_model_drift, evaluate_model, register_model |
Data Context Wizard keeps one governed graph of definitions, lineage and owners that every agent and person answers from. Autonomous Data-Conductor runs each job from detection to a verified result. Spellbook Data Catalog is where your team approves, audits and rolls back, and asks questions in plain English.
What goes on autopilot
Once a domain has earned it, this work runs on its own, and each item removes a problem your team deals with today:
- •New model formats are mapped on first upload, so farmers see their maps on day one.
- •Sharing permissions are enforced in the data, so every share is instant and auditable.
- •Partner API contracts are checked before release, so partner apps never break.
Where your people stay in charge
Agents never get blanket access. Each domain has its own autonomy level, set by you, and it only rises when the receipts show the agents are reliable. Everything starts at L1, observing only; reversible upkeep such as reruns, staging fixes, documentation and cleanup is usually first to run on its own.
- •Shared data and partner APIs always goes to a named approver: customers and partners depend on them, so the product data lead approves.
- •Customer decisions: these stay with people.
Once a deployment has matured, here is how that ladder plays out across task classes:
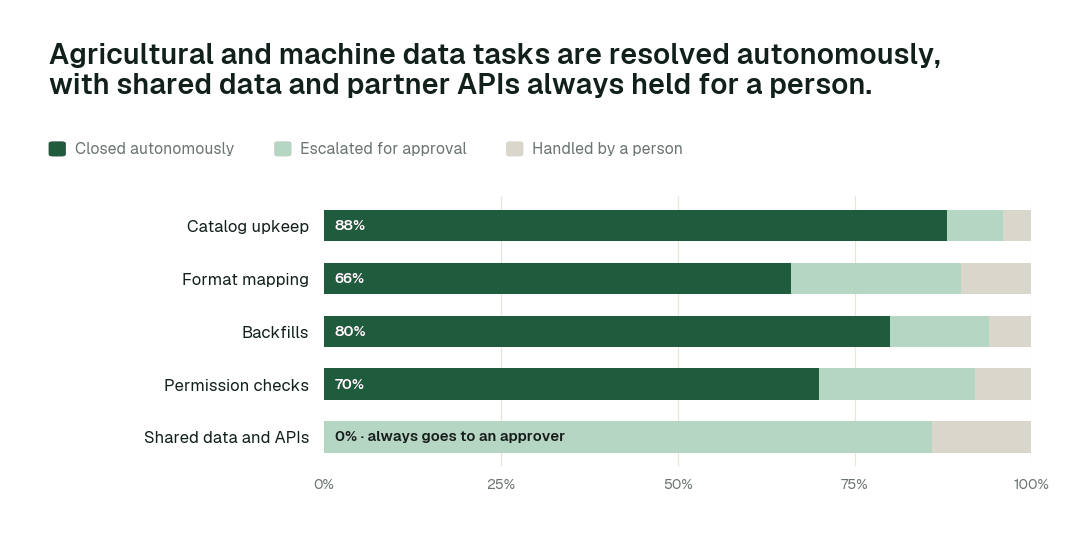
Catalog upkeep closes autonomously 88% of the time. For Shared data and APIs, autonomous closure is 0% by design.
What happens when an agent is wrong
- •At L2 propose, nothing changes until a named person approves. The proposal shows the full diff, the blast radius and how to roll it back. Unanswered requests expire and escalate.
- •At L3 act, reversibly, every change keeps a rollback point, and Conductor verifies the downstream number after the change. If verification fails, the change is reversed and the domain drops a level.
- •No agent approves or promotes its own work. Autonomy only grows on evidence, per repair class, and repeated errors shrink scope automatically.
- •One org-wide stop halts all autonomous dispatch, and every action lands in a hash-chained audit trail you can export with generate_audit_report.
How it fits your stack
Data Workers connects to what you already run: IoT ingestion; cloud lakes on AWS or Azure; Databricks or Snowflake; partner APIs; operations center applications. Each agent is an MCP server, so the same agents work inside Claude Code, Cursor or Codex and in Slack or Teams through Spellbook. Nothing migrates.
- •Runs in your infrastructure with your credentials and your model key. The hosted Autonomous Data-Conductor sees workflow metadata only, never rows.
- •Uses the access you already govern. Agents act under scoped service identities and your existing roles; every grant goes through provision_access and is logged.
- •Proposes changes as diffs in your dbt project, orchestrator and warehouse, with blast radius, tests and a rollback point, and applies them only at the autonomy level you set for that domain.
- •Open-source core. The Apache-2.0 community edition ships 11 agents and 160+ MCP tools, so your engineers can read exactly what the agents call.
Governance and regulation
Customers own and control sharing of their data. Data Workers enforces permissions in the data and logs every share.
Data Workers doesn't make you compliant; your controls, people and assessors do. It supplies controls and evidence wherever agents touch data. Not legal advice.
The alternatives machine data teams weigh
Build it yourselves. A strong team can wire a coding agent to MCP servers for the warehouse and dbt. The work is everything around it: routing approvals to the right owner, blast radius, rollback, receipts, and current context about every other system.
Observability, catalogs and point tools. Observability alerts, catalogs document, and quality tools test. Data Workers takes their signals, diagnoses, proposes the fix, verifies it and leaves the receipt.
Platform-native agents. Snowflake made its managed MCP server and Cortex Agents generally available on Nov 4, 2025, and Databricks made Genie One generally available on Jun 16, 2026. They are excellent inside their platform; this work crosses the source systems, orchestrator, warehouse and BI, and Data Workers works across all of them.
In this space specifically. IoT platforms collect telemetry; Data Workers maps, verifies and governs it into products.
The case for your CTO
What this replaces. Converter backlogs for every new model year, manual sharing permissions and partner apps that break on internal changes.
What your team gets back. Machine data services that work on day one of every model year.
Integration effort. Connecting is configuration, not a migration. The agents attach over MCP to the warehouse, orchestrator, dbt project and source systems you already run, under the roles you already govern, inside your own infrastructure. Your engineers can read every tool the agents call in the open-source core.
Risk and control. Autonomy is set per domain. Everything starts at L1, observing only; reversible work moves up only when the receipts justify it; shared data and partner APIs stay at L2 with a named approver; and one org-wide stop halts all autonomous work.
Why now. Data-driven services drive equipment value.
The first win. Model-format mapping on one product line at L3. The pilot below lays out the scope, what you see each week and the cost.
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For machine data teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; shared data and partner APIs always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: new model formats are mapped on first upload, sharing permissions are enforced in the data, and partner API contracts are checked before release. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. Equipment makers will ship data products with every machine, and farmers and fleet owners will share data freely because permissions are enforced in the data. Machine data teams will build services, not converters.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how machine data teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. IoT ingestion; cloud lakes on AWS or Azure; Databricks or Snowflake; partner APIs; operations center applications, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Model-format mapping on one product line at L3.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. New model formats are mapped on first upload and sharing permissions are enforced in the data start running on reversible work. Shared data and partner APIs stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •Sharing permission applied: from about a week to 5 min
- •API change checked: from about 3 days to 15-20 min
- •New model format mapped: from about a month to hours
- •the share of catalog upkeep closed autonomously, targeting 88% as the deployment matures
- •What you decide. Whether to expand to the next domain. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
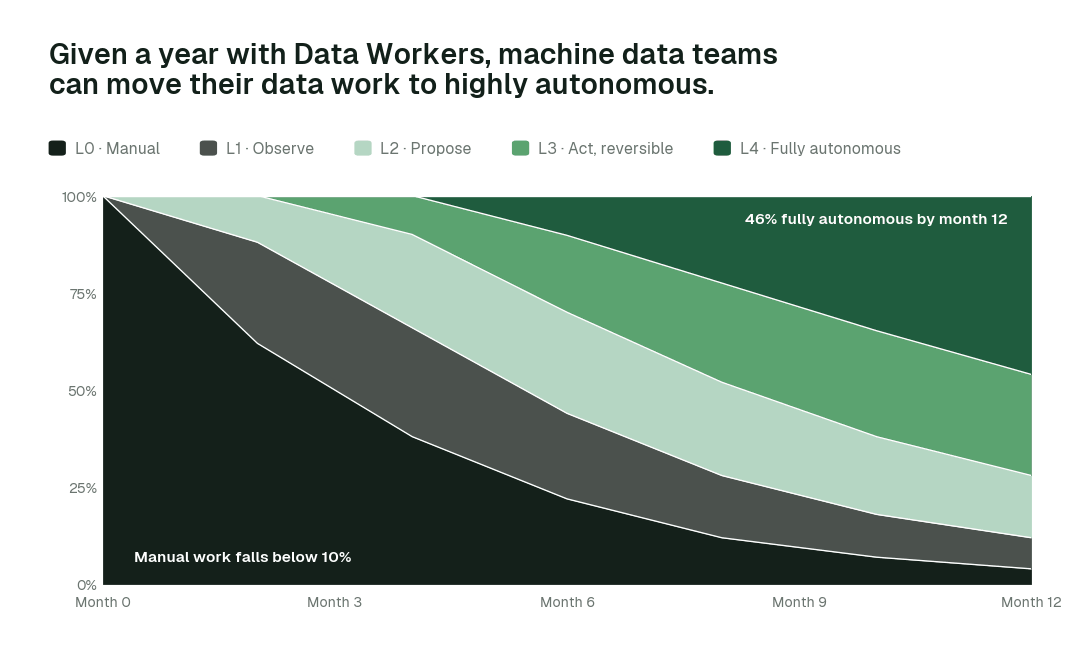
By month 12, more than 46% of agent actions run fully autonomously while shared data and partner APIs stay with a named approver.
FAQ
Does it work with edge uploads? It handles late and partial uploads.
Can farmers revoke sharing? Permissions are enforced and logged.
Does it break partner APIs? Contracts are versioned before release.
Where do the agents run? In your infrastructure, with your credentials and model key. The hosted Conductor sees workflow metadata only.
Do we have to migrate anything? No. Your warehouse, dbt project, orchestrator, catalog and BI stay where they are.
Sources
- •OEM Off-Highway, John Deere opens data platform to other software suppliers: https://www.oemoffhighway.com/engineering-manufacturing/software/press-release/12251295/john-deere-opens-data-platform-to-other-software-suppliers
- •Data Workers pricing: https://dataworkers.io/pricing/
- •Data Workers open-source repository (tool registrations): https://github.com/DataWorkersProject/dataworkers-claw-community
- •Snowflake, managed MCP server and Cortex Agents GA release note (Nov 4, 2025): https://docs.snowflake.com/en/release-notes/2025/other/2025-11-04-cortex-agents-mcp
- •Databricks, Genie One launch (Jun 16, 2026): https://www.databricks.com/company/newsroom/press-releases/databricks-launches-genie-one-all-new-agentic-coworker-every-team