A playbook for Data Platform PMs who own event data
If you are a Data Platform PM who owns event data, this is your playbook. It covers what your team ships, where its week goes today, the use cases agents take over first, the autonomy you can safely grant in each domain, and what to show leadership after the first quarter.
Key takeaways
- •Who this is for. The teams that own user behavior data: event delivery and data collection platforms, product analytics, experimentation platforms and metric layers.
- •The problem today. Two-day funnel investigations that turn out to be logging, week-long backfills and four definitions of active user.
- •What changes. Instrumentation is checked on every client release, so a dropped property is caught on release day, not after an experiment ships. Backfills run and are verified automatically after a fix, so history is right again overnight.
- •What stays with your people. Changes to certified metrics like active user: executives and experiments depend on them, so the metric owner approves.
- •The result. Product teams that trust their experiment readouts and a platform team that isn't on call for every client release.
The PRD for agentic clickstream and product analytics platform teams
This is the requirements document we would write with you for your team. Everything below expands on it.
| Who | Event delivery, product analytics, experimentation and data platform teams at consumer and SaaS companies |
| The job | Broken instrumentation caught on the release that broke it. |
| Environment | Segment, Snowplow or in-house SDKs; Kafka; BigQuery, Snowflake or Databricks; dbt; experimentation platforms; metric layers. |
| Constraints | Changes to certified metrics like active user always go to a named approver. Behavioral data includes personal data under GDPR and CCPA. |
| Success is measured by | PM question on an event: from about a day to seconds; New event documented: from about a day to minutes; Broken funnel traced to release: from about 2 days to 15-20 min; event catalog upkeep closed autonomously 90% of the time. |
| Owned by | A Data Platform PM who owns event data, with domain owners as named approvers. |
| Pilot scope | Per-release instrumentation checks at L3. |
What going fully agentic and autonomous means for clickstream and product analytics platform teams
- •Put your data pipeline on autopilot. Instrumentation is checked on every client release, so a dropped property is caught on release day, not after an experiment ships.
- •Run the data back office without the busywork. The work that fills the week today moves to agents: two-day funnel investigations that turn out to be logging, week-long backfills and four definitions of active user.
- •Scale data without scaling headcount. Backfills run and are verified automatically after a fix and unused events and tables retire once lineage proves nobody reads them, so the data you manage grows without the team having to.
- •Get the plumbing off your plate. Product teams that trust their experiment readouts and a platform team that isn't on call for every client release.
Who this is for
The teams that own user behavior data: event delivery and data collection platforms, product analytics, experimentation platforms and metric layers. In most companies, product squads define events and a central platform owns the pipes. Titles include Data Platform PM, Data Product Manager (Product Analytics), Analytics Engineering Lead and Experimentation Platform Lead.
The product you ship
- •The event pipeline that takes billions of client events a day to the warehouse.
- •Core datasets that represent the user journey: sessions, engagement, funnels, retention.
- •The metric layer every dashboard, experiment and model reads from.
- •Experiment results product teams use to ship or kill features.
Where the week goes
- •Hundreds of teams ship events, few document them. Event types multiply and nobody knows which are still used.
- •Instrumentation breaks silently. A client release drops a property and a funnel step goes to zero.
- •Metrics drift. "Active user" has four definitions and two of them disagree in the board deck.
- •Backfills are painful. Every schema fix means reprocessing weeks of partitions.
- •Storage grows forever. Raw event tables cost more every month.
Add it up and upkeep is most of the team's week. Here is how a typical week splits today, and once agents own the back office:
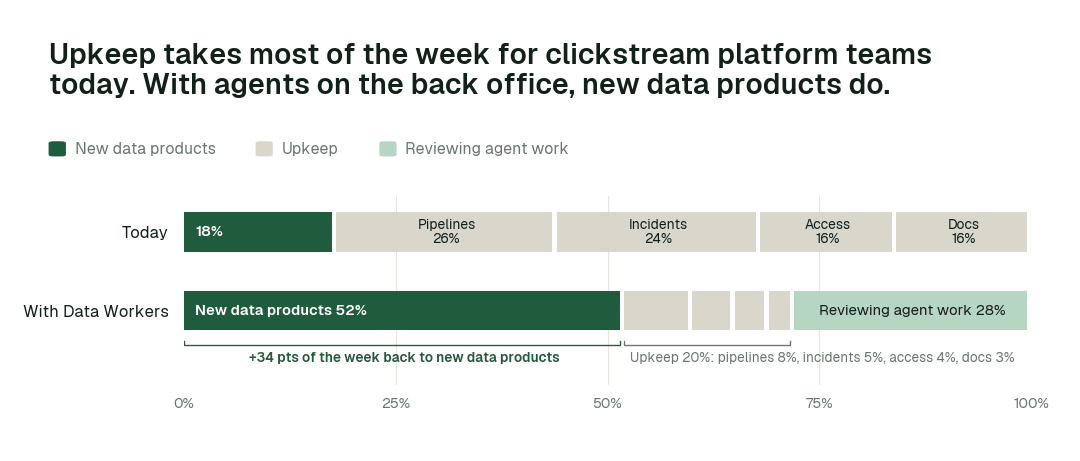
Time spent on new data products moves from 18% of the week to 52%. Most of the rest becomes review: people steer and approve agent work instead of doing it by hand.
Then and now
| Work | Today | With Data Workers |
|---|---|---|
| A client release drops a property | Found when a funnel step goes to zero | Caught on the release that dropped it |
| Event catalog | Hundreds of undocumented event types | Every event documented with owner and consumers |
| Active-user definitions | Four definitions in four decks | One governed metric everywhere |
| Backfills after a fix | A painful, manual project | A routine rerun with verification |
| Unused events and tables | Stored forever | Retired once lineage proves nobody reads them |
| Experiment data integrity | Questioned after the decision | Affected experiments flagged with exact windows |
These are the impact metrics we move for clickstream and product analytics platform teams:
- •PM question on an event: from about a day to seconds
- •New event documented: from about a day to minutes
- •Broken funnel traced to release: from about 2 days to 15-20 min
Across the routine work in this domain:
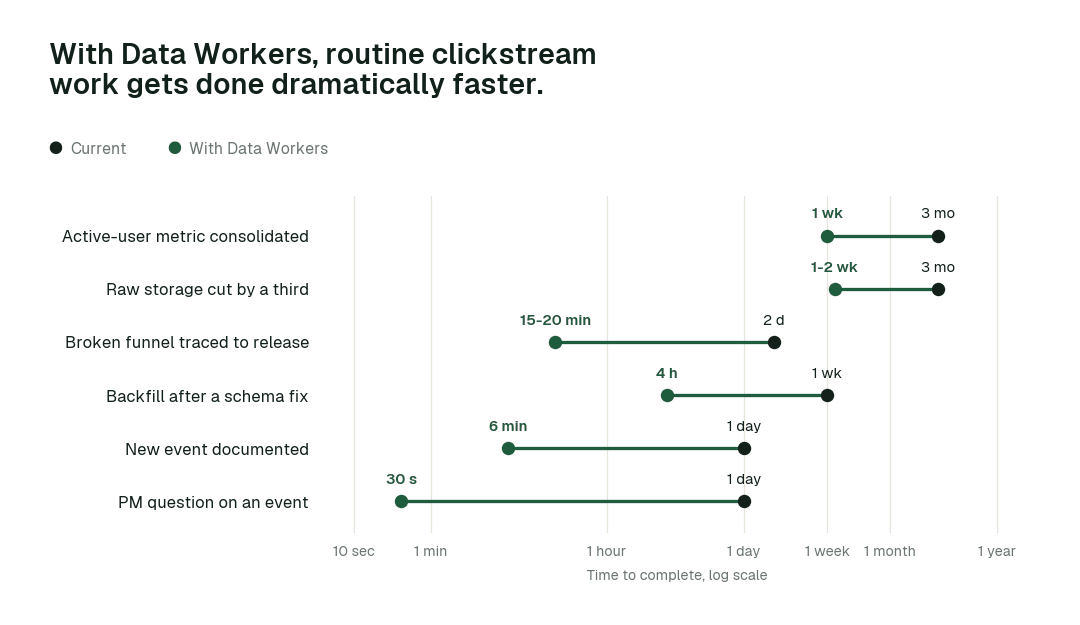
The biggest change is New event documented: from about a day to minutes. Work that waited in queues finishes in minutes or hours, because agents detect, fix and verify in one pass.
Use cases, in depth
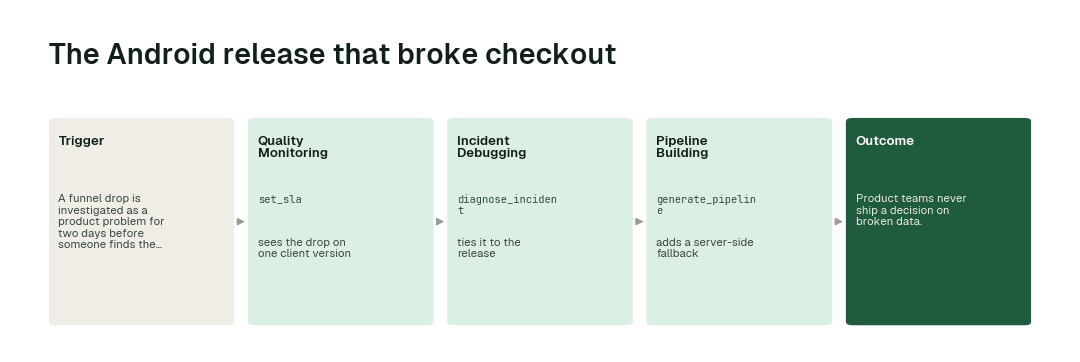
The Android release that broke checkout
Today. A funnel drop is investigated as a product problem for two days before someone finds the missing property.
With Data Workers. Quality Monitoring sees the drop on one client version, Incident Debugging ties it to the release, Pipeline Building adds a server-side fallback, and the experimentation team gets the exact affected window.
What changes. Product teams never ship a decision on broken data.
Consolidating active-user definitions
Today. Leadership sees different active-user counts from product, finance and marketing.
With Data Workers. Context Wizard finds every definition in use, shows where they diverge, and publishes one governed metric once the owner approves; every dashboard and agent moves to it.
What changes. The board deck and the product dashboard agree.
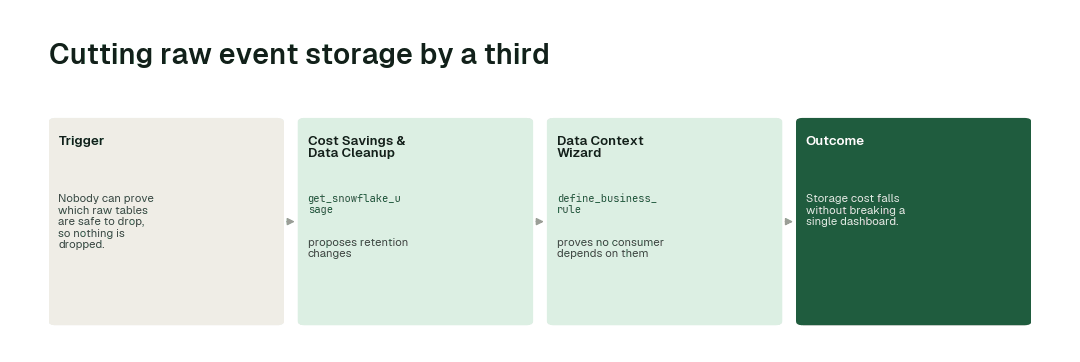
Cutting raw event storage by a third
Today. Nobody can prove which raw tables are safe to drop, so nothing is dropped.
With Data Workers. Cost Savings & Data Cleanup proposes retention changes and table retirements, Context Wizard proves no consumer depends on them, and changes ship in reversible waves.
What changes. Storage cost falls without breaking a single dashboard.
Agents working together: The Android release that broke checkout
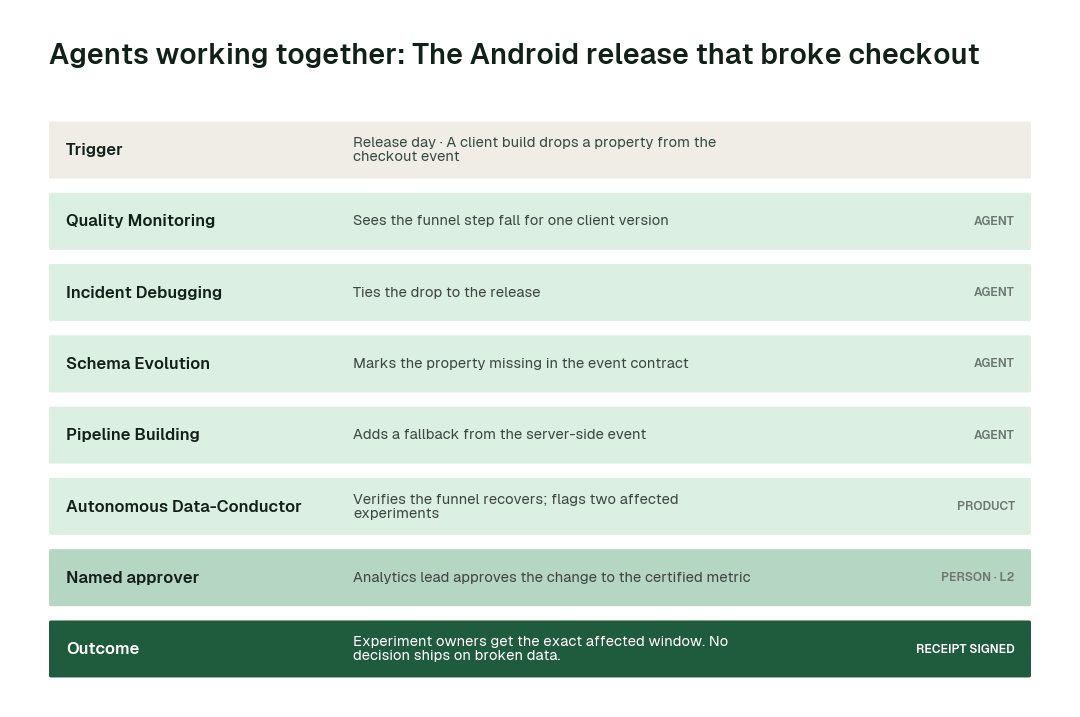
An Android release drops a property from the checkout event. Quality Monitoring sees the funnel step fall for that client version only. Incident Debugging ties it to the release, Schema Evolution marks the property as missing, Pipeline Building adds a fallback from the server-side event, and Conductor verifies the funnel recovers. The experimentation team gets a note that two experiments read affected data, with the exact window.
Minute by minute
Illustrative example. Client events stream into BigQuery; the checkout funnel feeds an experiment readout at noon.
| Time | Who | What happens |
|---|---|---|
| 09:00 | Android release | Checkout event loses a property |
| 09:40 | Quality Monitoring agent | Funnel step drops for one client version |
| 09:45 | Incident Debugging agent | diagnose_incident ties it to the release |
| 10:10 | Pipeline Building agent | Server-side fallback with tests |
| 10:30 | Spellbook Data Catalog | Analytics lead approves the certified metric change |
| 11:00 | Experimentation | Owners told the exact affected window |
The agents on the job
| Agent | What it does for clickstream platforms | Tools it calls |
|---|---|---|
| Real-Time Streaming | Keeps event schemas, consumers and downstream tables in step when a client changes | register_kafka_schema, register_stream_schema, detect_schema_change |
| Schema Evolution | Detects renamed, dropped and new properties and versions every event contract | detect_schema_change, validate_schema_compatibility, generate_migration, rollback_migration |
| Quality Monitoring | Volume, null-rate and funnel-step checks per event and client version | set_sla, run_quality_check, get_anomalies, create_quality_tests_for_pipeline |
| Incident Debugging | Traces a broken funnel to the release and event that caused it, then backfills | diagnose_incident, get_root_cause, prepare_backfill, execute_backfill |
| Data Context & Catalog | Documents every event type with owner, schema history and consumers | trace_cross_platform_lineage, blast_radius_analysis, define_business_rule, generate_documentation |
| Cost Savings & Data Cleanup | Retires unused event types and tables and right-sizes retention | get_snowflake_usage, get_cost_enrichment, detect_dead_assets |
Context Wizard holds one governed definition of active user, session, conversion and retention for every dashboard, experiment and agent. Conductor verifies core metrics after every fix. Spellbook makes the event catalog searchable for product managers.
What goes on autopilot
Once a domain has earned it, this work runs on its own, and each item removes a problem your team deals with today:
- •Instrumentation is checked on every client release, so a dropped property is caught on release day, not after an experiment ships.
- •Backfills run and are verified automatically after a fix, so history is right again overnight.
- •Unused events and tables retire once lineage proves nobody reads them, so raw storage stops growing forever.
Where your people stay in charge
Agents never get blanket access. Each domain has its own autonomy level, set by you, and it only rises when the receipts show the agents are reliable. Everything starts at L1, observing only; reversible upkeep such as reruns, staging fixes, documentation and cleanup is usually first to run on its own.
- •Changes to certified metrics like active user always goes to a named approver: executives and experiments depend on them, so the metric owner approves.
- •Experiment ship decisions: these stay with product teams.
Once a deployment has matured, here is how that ladder plays out across task classes:
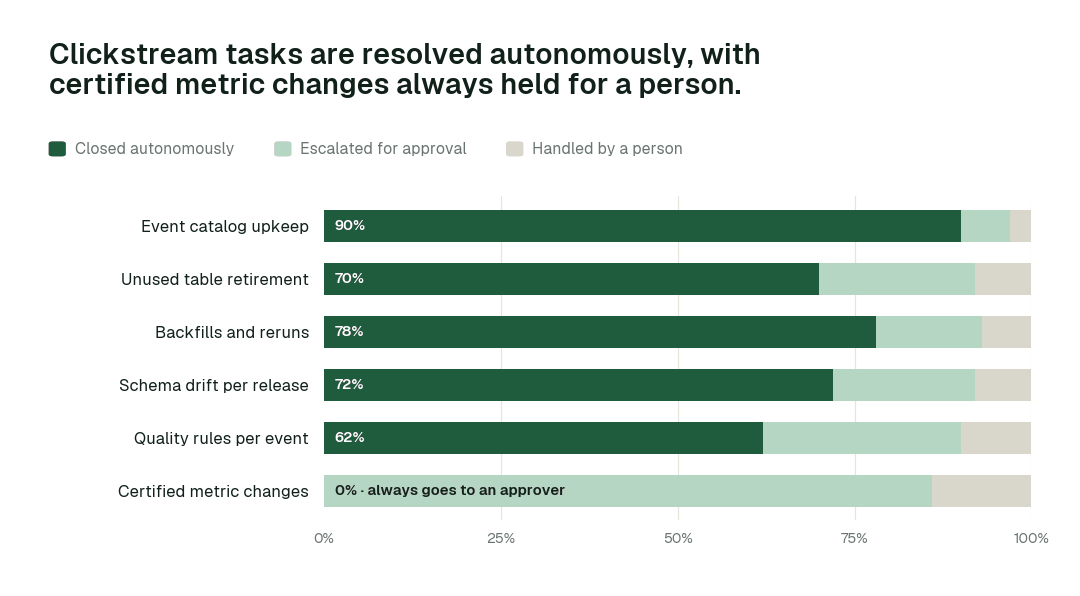
Event catalog upkeep closes autonomously 90% of the time. For Certified metric changes, autonomous closure is 0% by design: every change is proposed with a full diff and approved by a named person.
What happens when an agent is wrong
- •At L2 propose, nothing changes until a named person approves. The proposal shows the full diff, the blast radius and how to roll it back. Unanswered requests expire and escalate.
- •At L3 act, reversibly, every change keeps a rollback point, and Conductor verifies the downstream number after the change. If verification fails, the change is reversed and the domain drops a level.
- •No agent approves or promotes its own work. Autonomy only grows on evidence, per repair class, and repeated errors shrink scope automatically.
- •One org-wide stop halts all autonomous dispatch, and every action lands in a hash-chained audit trail you can export with generate_audit_report.
How it fits your stack
Data Workers connects to what you already run: Segment, Snowplow or in-house SDKs; Kafka; BigQuery, Snowflake or Databricks; dbt; experimentation platforms; metric layers. Each agent is an MCP server, so the same agents work inside Claude Code, Cursor or Codex and in Slack or Teams through Spellbook. Nothing migrates.
- •Runs in your infrastructure with your credentials and your model key. The hosted Autonomous Data-Conductor sees workflow metadata only, never rows.
- •Uses the access you already govern. Agents act under scoped service identities and your existing roles; every grant goes through provision_access and is logged.
- •Proposes changes as diffs in your dbt project, orchestrator and warehouse, with blast radius, tests and a rollback point, and applies them only at the autonomy level you set for that domain.
- •Open-source core. The Apache-2.0 community edition ships 11 agents and 160+ MCP tools, so your engineers can read exactly what the agents call.
Governance and regulation
Behavioral data includes personal data under GDPR and CCPA. Data Workers classifies it, scopes access and logs every change.
Data Workers doesn't make you compliant; your controls, people and assessors do. It supplies controls and evidence wherever agents touch data. Not legal advice.
The alternatives clickstream and product analytics platform teams weigh
Build it yourselves. A strong team can wire a coding agent to MCP servers for the warehouse and dbt. The work is everything around it: routing approvals to the right owner, blast radius, rollback, receipts, and current context about every other system.
Observability, catalogs and point tools. Observability alerts, catalogs document, and quality tools test. Data Workers takes their signals, diagnoses, proposes the fix, verifies it and leaves the receipt.
Platform-native agents. Snowflake made its managed MCP server and Cortex Agents generally available on Nov 4, 2025, and Databricks made Genie One generally available on Jun 16, 2026. They are excellent inside their platform; this work crosses the source systems, orchestrator, warehouse and BI, and Data Workers works across all of them.
In this space specifically. Product analytics tools visualize; observability alerts. Data Workers traces the break to the release, fixes it and verifies the metric.
The case for your CTO
What this replaces. Two-day funnel investigations that turn out to be logging, week-long backfills and four definitions of active user.
What your team gets back. Product teams that trust their experiment readouts and a platform team that isn't on call for every client release.
Integration effort. Connecting is configuration, not a migration. The agents attach over MCP to the warehouse, orchestrator, dbt project and source systems you already run, under the roles you already govern, inside your own infrastructure. Your engineers can read every tool the agents call in the open-source core.
Risk and control. Autonomy is set per domain. Everything starts at L1, observing only; reversible work moves up only when the receipts justify it; changes to certified metrics like active user stay at L2 with a named approver; and one org-wide stop halts all autonomous work.
Why now. Experiment velocity depends on trusted events.
The first win. Per-release instrumentation checks at L3. The pilot below lays out the scope, what you see each week and the cost.
The climb: from assisted to autonomous to agentic
Our thesis is that the data platform climbs the way analytics did, in stages, and that the hard part of data work was never knowing what to do but doing it. For clickstream and product analytics platform teams, the climb looks like this:
- •Assisted. Agents work alongside your team. They read the whole stack, show what needs doing and propose every fix with a receipt; changes to certified metrics like active user always go to a named approver.
- •Autonomous, under your governance. Routine work runs on its own: instrumentation is checked on every client release, backfills run and are verified automatically after a fix, and unused events and tables retire once lineage proves nobody reads them. Your team governs the agents instead of doing the upkeep.
- •The agentic enterprise. Product teams that trust their experiment readouts and a platform team that isn't on call for every client release. People set direction, and the platform carries it out.
You choose the altitude, every step is visible and reversible, and the pilot below is the first rung.
The pilot: how clickstream and product analytics platform teams start
The pilot is how your team proves the value on its own data before committing.
- •What we connect. Segment, Snowplow or in-house SDKs; Kafka; BigQuery, Snowflake or Databricks; dbt; experimentation platforms; metric layers, over MCP, inside your infrastructure. Nothing migrates.
- •Scope. Per-release instrumentation checks at L3.
- •First week. Agents run at L1 across the scoped domain. They map every pipeline, definition and lineage path and show the fixes they would have made, with receipts, so your team sees the value before anything changes.
- •By week two. Instrumentation is checked on every client release and backfills run and are verified automatically after a fix start running on reversible work. Changes to certified metrics like active user stay at L2 with a named approver.
- •At day 30. We review the impact metrics against your baseline:
- •PM question on an event: from about a day to seconds
- •New event documented: from about a day to minutes
- •Broken funnel traced to release: from about 2 days to 15-20 min
- •the share of event catalog upkeep closed autonomously, targeting 90% as the deployment matures
- •What you decide. Whether to expand to the next domain. The pilot fee is credited in full against the first year.
- •Cost. Start with a pilot ($7,500 one-time, credited in full against the first year). Scale is from $1,000 a month and Enterprise from $3,000 a month, billed annually, with unlimited seats, no usage meter and no markup on model spend. See pricing.
The pilot is the start of a longer curve:
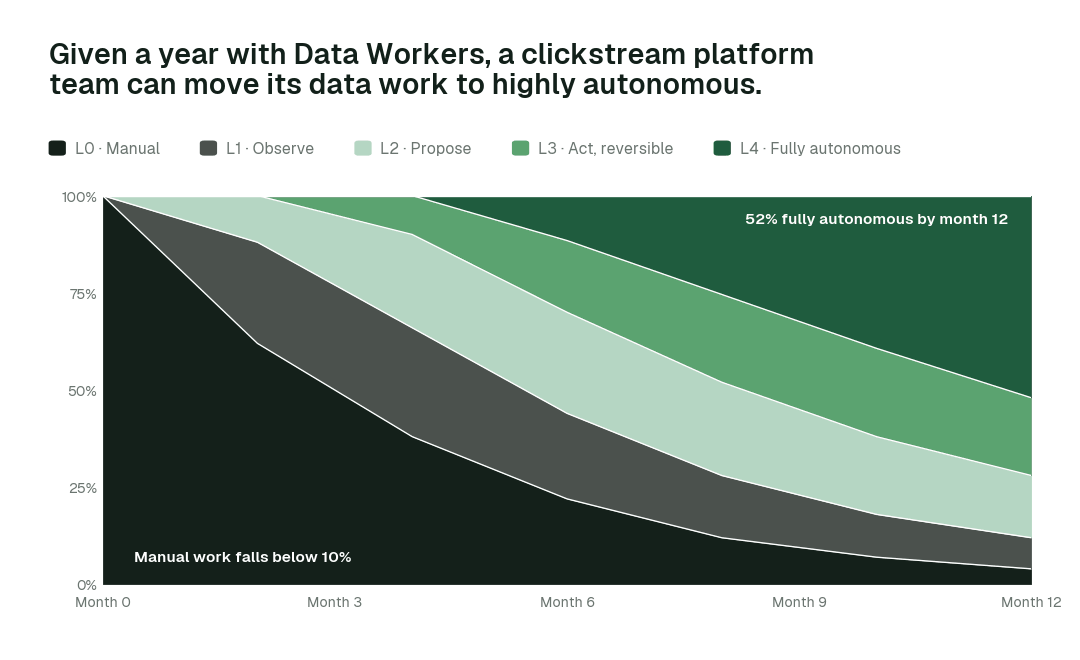
By month 12, more than 52% of agent actions run fully autonomously and manual work falls below 10%, while certified metric changes stay with a named approver.
FAQ
Does it replace Amplitude or Mixpanel? No; it keeps the events under them correct.
Can it retire events? After lineage proves no consumers, at the level you set.
Who approves metric changes? The metric owner, at L2.
Where do the agents run? In your infrastructure, with your credentials and model key. The hosted Conductor sees workflow metadata only.
Do we have to migrate anything? No. Your warehouse, dbt project, orchestrator, catalog and BI stay where they are.
Sources
- •Spotify Engineering, Data Platform Explained Part II: https://engineering.atspotify.com/2024/5/data-platform-explained-part-ii
- •Airbnb Engineering, Minerva: https://medium.com/airbnb-engineering/how-airbnb-achieved-metric-consistency-at-scale-f23cc53dea70
- •Data Workers pricing: https://dataworkers.io/pricing/
- •Data Workers open-source repository (tool registrations): https://github.com/DataWorkersProject/dataworkers-claw-community
- •Snowflake, managed MCP server and Cortex Agents GA release note (Nov 4, 2025): https://docs.snowflake.com/en/release-notes/2025/other/2025-11-04-cortex-agents-mcp
- •Databricks, Genie One launch (Jun 16, 2026): https://www.databricks.com/company/newsroom/press-releases/databricks-launches-genie-one-all-new-agentic-coworker-every-team